30초 요약
In a video published September 21, 2024, Matthew Berman discusses reports of ChatGPT appearing to initiate conversations, Constellation’s proposed Three Mile Island restart, restaurant automation and new AI releases. He also reviews safety governance, model pricing, Snap Spectacles, media tools, investment, EU availability and Senate testimony. The figures, rankings and availability discussed reflect that week in 2024. Several claims are attributed to the companies or commentators who made them, and the article clarifies the reported messaging bug and the separate Chipotle machines.
- 1An apparent unsolicited messageBerman reacts to user reports; OpenAI later explained the widely shared text incident as a bug.
- 2Nuclear power for MicrosoftConstellation announced a 20-year power purchase deal and a planned restart of Three Mile Island Unit 1.
- 3Restaurant automationChipotle was testing separate avocado-processing and automated bowl-making prototypes.
- 4Historical o1 limitsOpenAI raised early API and ChatGPT usage limits; those numbers were specific to the 2024 rollout.
- 5Open-weight benchmarkArtificial Analysis ranked Qwen 2.5 72B highly on its quality index at the time, a result bounded by the tests used.
- 6Senate testimonyBerman recounts Helen Toner’s warning about possible AI risks and gives his own opposing view on regulation.
핵심 정리
- OpenAI described the widely shared text example of ChatGPT appearing to message first as a bug, not proof of a deliberate proactive feature.
- Constellation’s proposed restart concerned Three Mile Island Unit 1, separate from the unit damaged in 1979.
- Chipotle’s bowl-making Augmented Makeline and its avocado-processing Autocado were separate prototypes.
- Llama reasoning demonstrations used inference-time workflows; this does not establish equivalence with o1.
- Model rankings, API limits and prices in the episode were snapshots from September 2024.
챕터별로 다듬은 전문 읽기
ChatGPT messages and the Three Mile Island deal
Berman discusses reports of apparently unsolicited messages and a proposed nuclear power purchase. He distinguishes the reactor planned for restart from the unit involved in the 1979 accident.
I begin with reports that ChatGPT appeared to message users before they had entered a prompt. One widely shared screenshot shows it asking about a user’s first week of high school, and another example involves voice. I find the idea unsettling and wonder whether it reflects a push toward more personal interaction, but that motive is speculation.
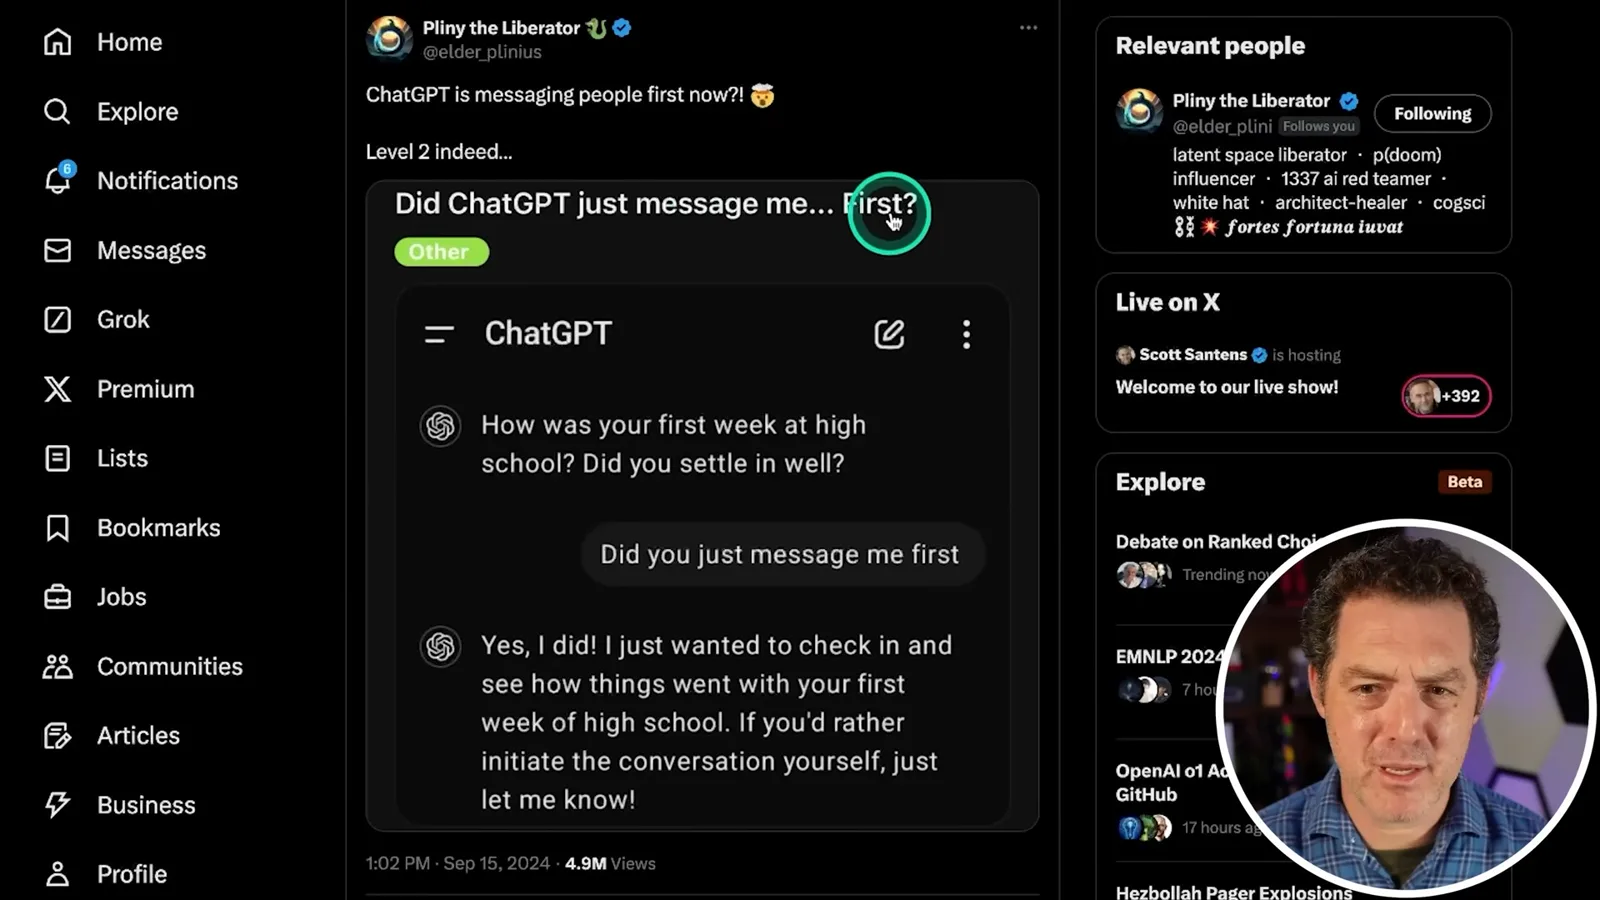
The chatbot’s own claim that it initiated a conversation is not reliable evidence of how the system worked. OpenAI told reporters in September 2024 that the text example involved a bug: a message that failed to send appeared blank while the model attempted to respond. The separate voice clip does not establish the same cause.
Constellation Energy announced a 20-year electricity purchase agreement with Microsoft intended to support the restart of Three Mile Island Unit 1. At the time of the video, the company expected a 2028 restart subject to approvals. Microsoft was buying power; it was not purchasing the nuclear plant itself.
Three Mile Island is associated with the 1979 partial meltdown, but the proposed restart concerns Unit 1, a separate reactor that shut down in 2019 for economic reasons. I see nuclear power as a promising low-carbon source for the growing electricity demands of computing, and speculate that future data centers could be located near nuclear facilities.
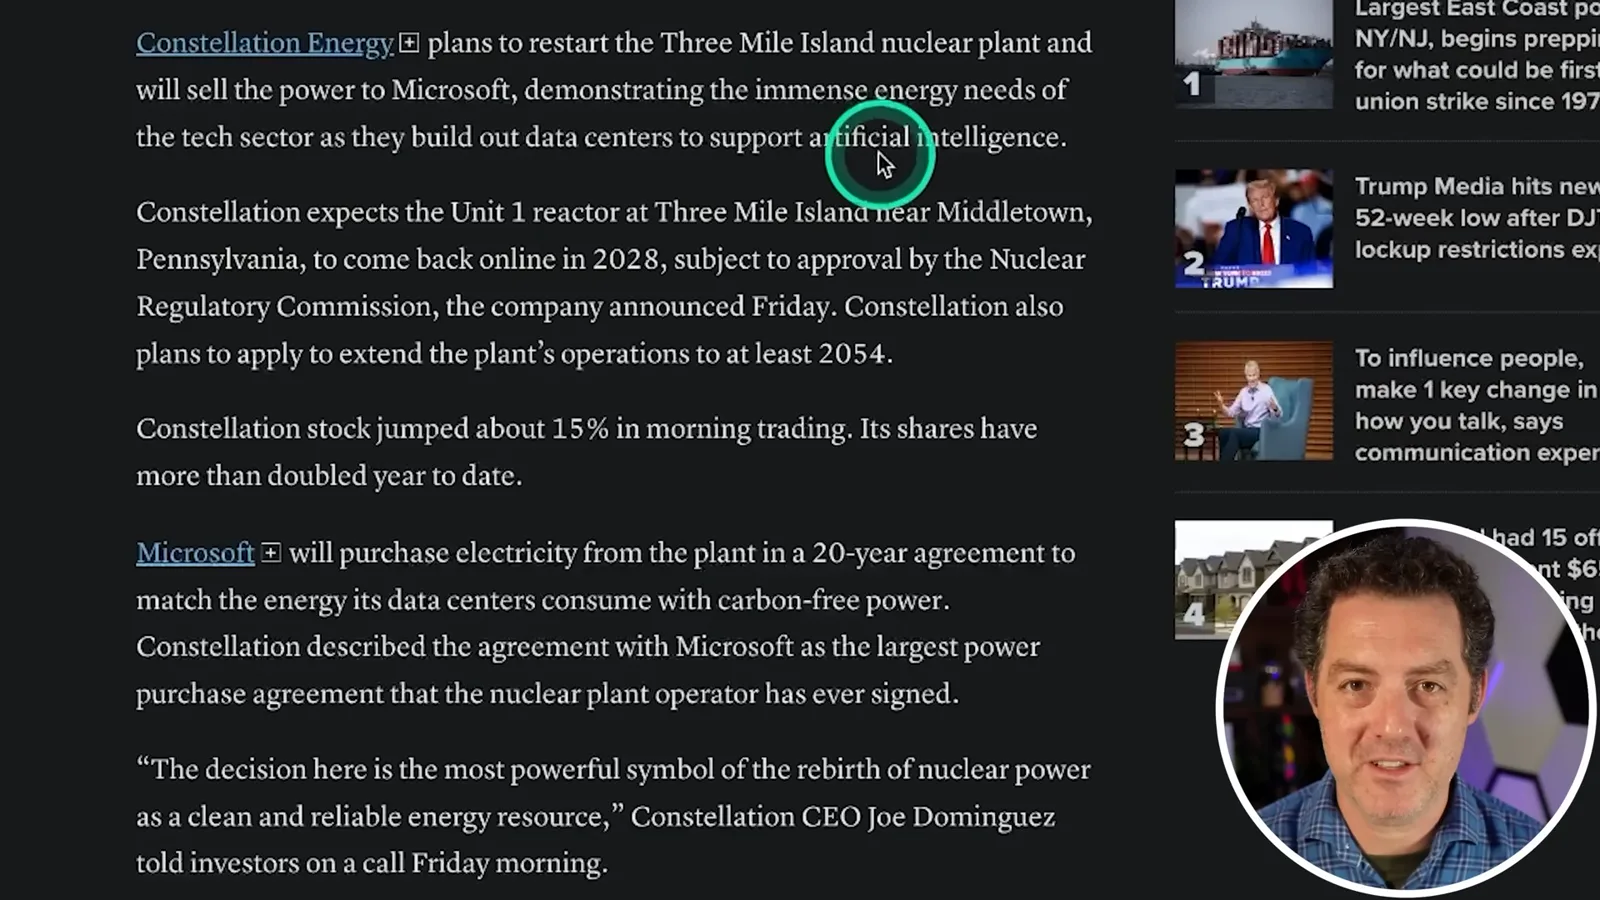
I argue that the expansion of AI computing will require substantial additional power and express support for more nuclear development, including small reactors. Whether a particular energy mix is necessary for future AI, and how it should be built, remains a prediction and policy question rather than a demonstrated requirement.
Restaurant automation and Llama reasoning
A Chipotle pilot and experiments with inference-time reasoning show different ways software and machines can automate work. The demonstrations have distinct capabilities.
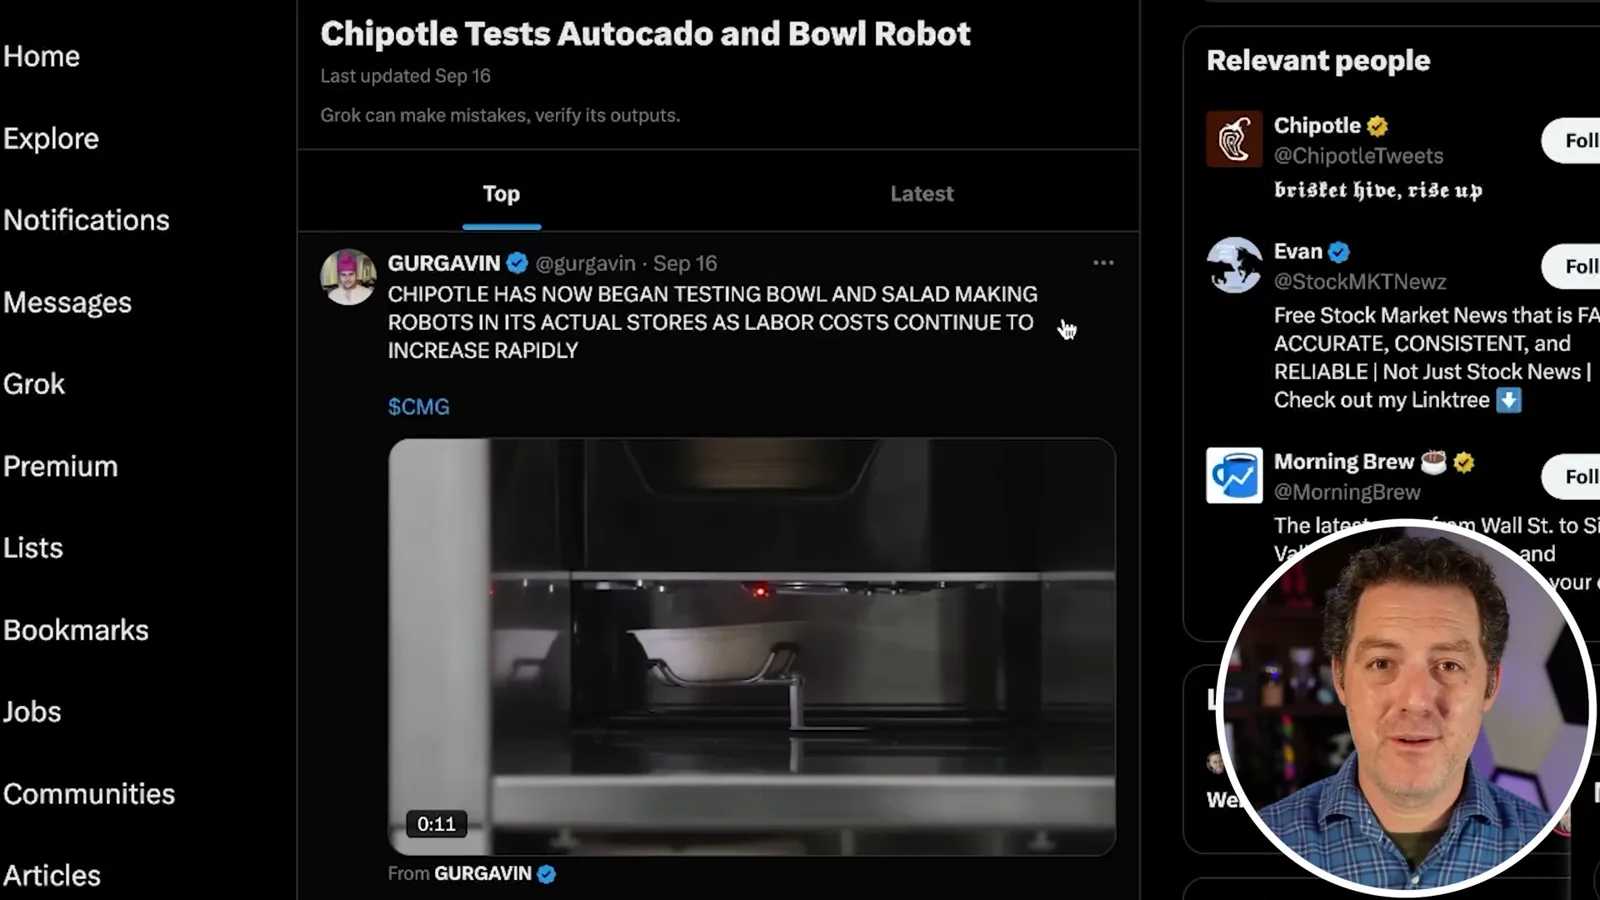
Chipotle was testing restaurant automation, including a machine for assembling bowls and salads. I expect more consistent portions could be a benefit. The company described two separate prototypes: Hyphen’s Augmented Makeline assembles bowls and salads, while Autocado cuts, cores and peels avocados for guacamole; I conflated their names in the video.
I turn to Llama-based experiments that use prompts and multiple reasoning steps at inference time, including a project called LLaMA-Berry and Benjamin Klieger’s g1 demonstration using Groq. These experiments build a workflow around a model; prompting a chain of thought does not itself prove equivalence with OpenAI’s o1 training or reasoning performance.
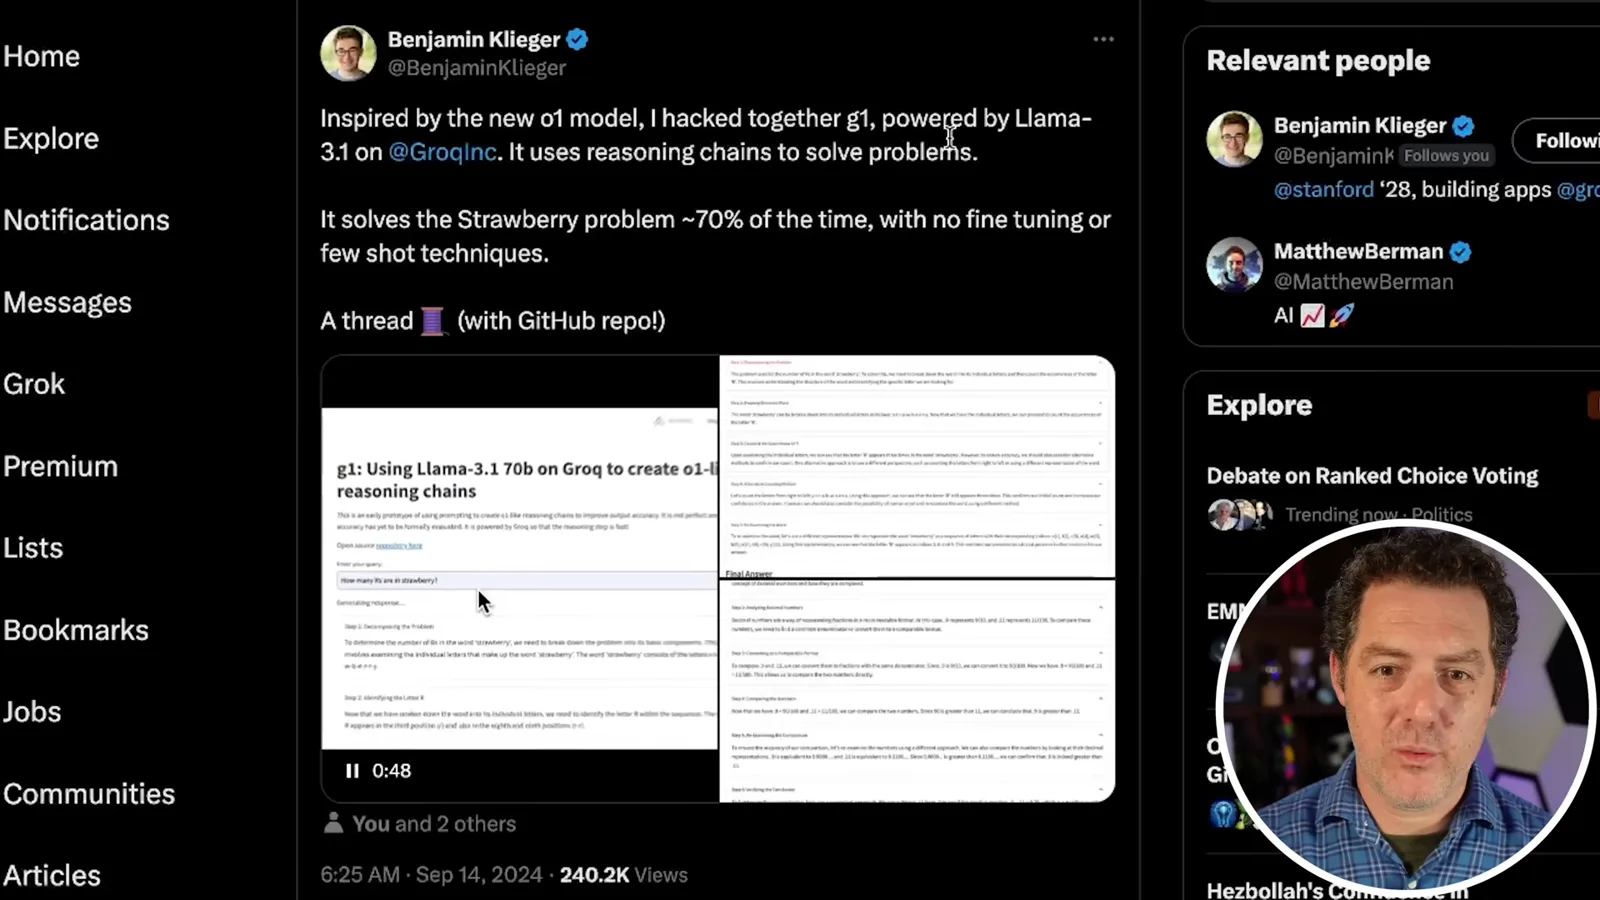
I speculate that Meta may eventually release its own reasoning-focused Llama. At this point that is a forecast. The projects I describe can be tried through the interfaces available at the time, but their results should be evaluated on the particular problems and settings used.
OpenAI safety and o1 limits
Berman reviews OpenAI’s safety recommendations and the usage limits announced for its early o1 models. These are historical limits, not current product terms.
OpenAI’s safety and security committee published recommendations covering independent safety governance, security measures, transparency, external collaboration and unified safety frameworks. I welcome attention to these issues but criticize what I see as a lack of transparency from a company whose name contains “Open.”
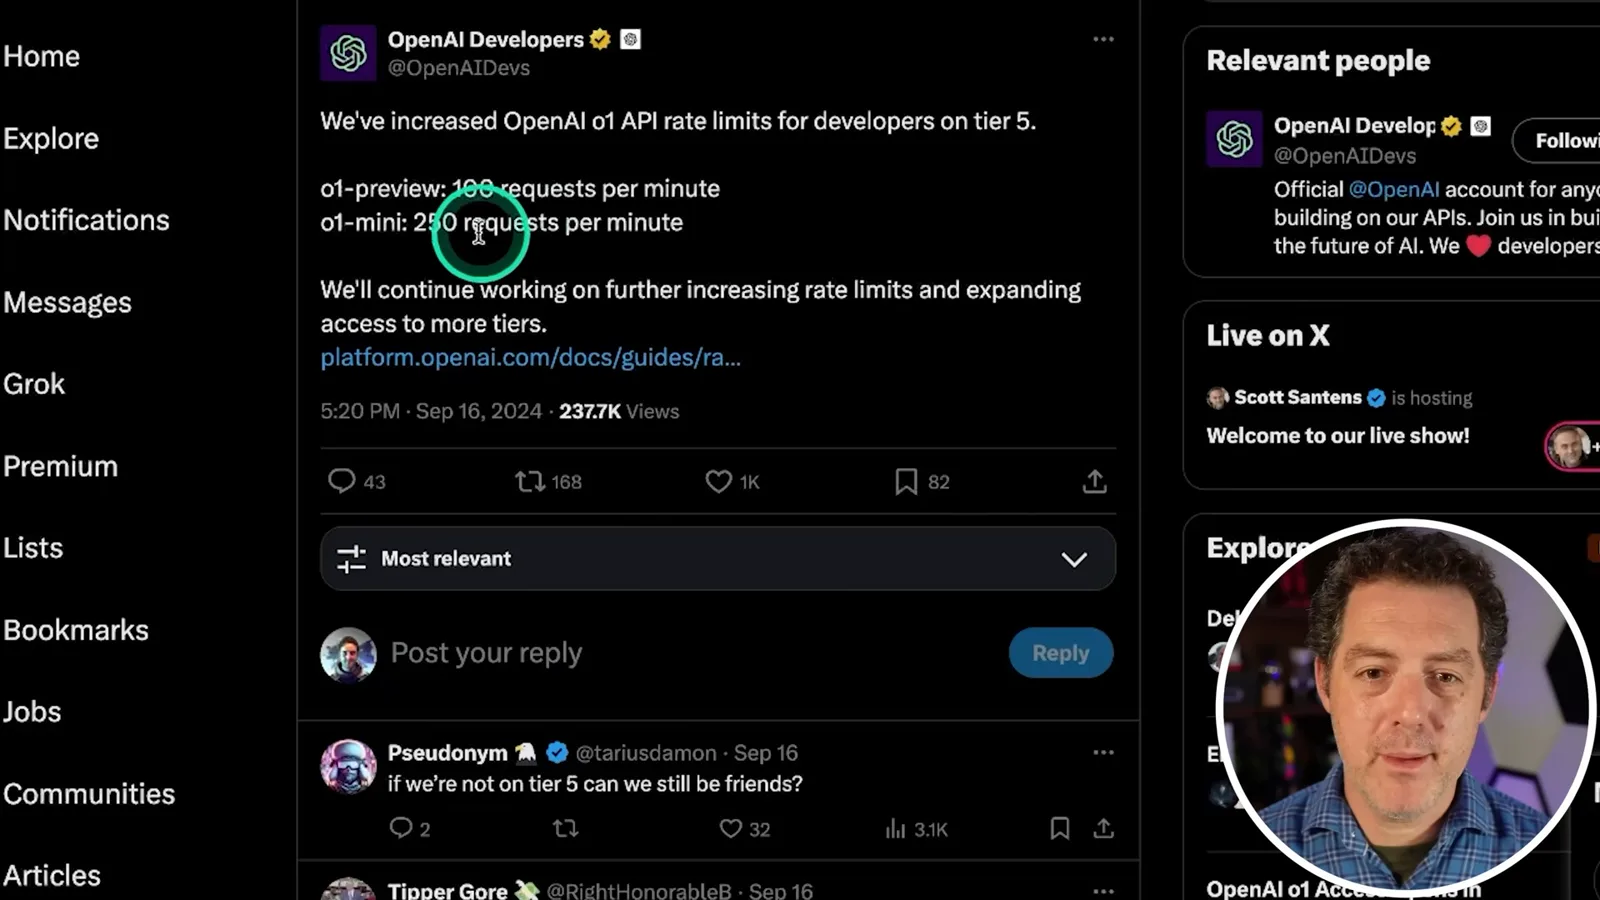
The early o1 limits increased soon after release. OpenAI’s displayed announcement gave tier 5 API developers 100 requests per minute for o1-preview and 250 for o1-mini. For ChatGPT Plus and Team users, the announced limits rose to 50 o1-mini messages per day and 50 o1-preview messages per week; these are September 2024 figures.
Mistral prices and Snap Spectacles
The episode covers a Mistral pricing announcement and Snap’s new augmented-reality glasses. Prices and availability reflect September 2024.
Mistral announced a free API tier, pricing reductions, a new Mistral Small and free vision capabilities in Le Chat. I also discuss Pixtral, the company’s 12-billion-parameter vision-language model, and say I found it promising. Whether it runs locally depends on the user’s hardware and configuration.
The prices I cite are historical per-million-token rates: Mistral NeMo at $0.15, Pixtral at $0.15 for input and output, Mistral Small at $0.20 input and $0.60 output, and Mistral Large at $2 input and $6 output. They show the price reductions announced at the time, not today’s prices.
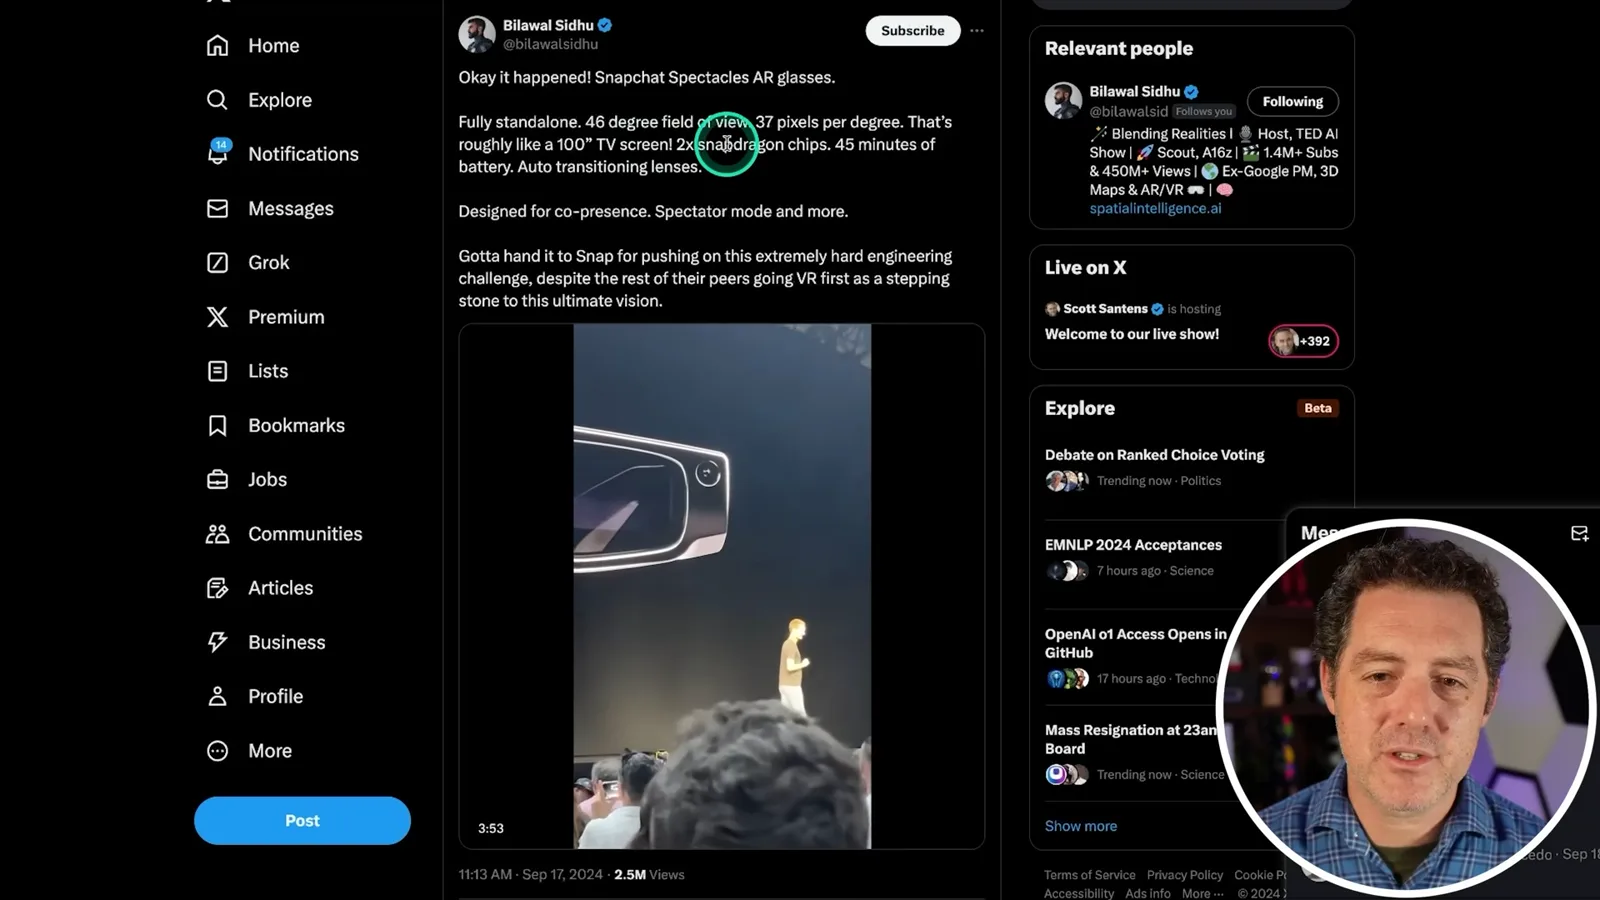
Snap introduced a new generation of Spectacles augmented-reality glasses. The specifications shown include a 46-degree field of view, 37 pixels per degree, two Snapdragon chips and around 45 minutes of battery life. I like the idea of automatically transitioning lenses but regard that battery life as a major limitation.
Media tools, factuality and voice
Runway’s Lionsgate partnership, a grounded-factuality detector and Kyutai’s Moshi illustrate different media and model applications. Berman has not independently tested all of them.
Runway announced a partnership with Lionsgate to bring AI tools to filmmakers. I see potential for these tools to augment creative workflows and point to examples of creators transforming phone footage with AI. My view that production costs will fall substantially is an assessment, not a measured result of this partnership.
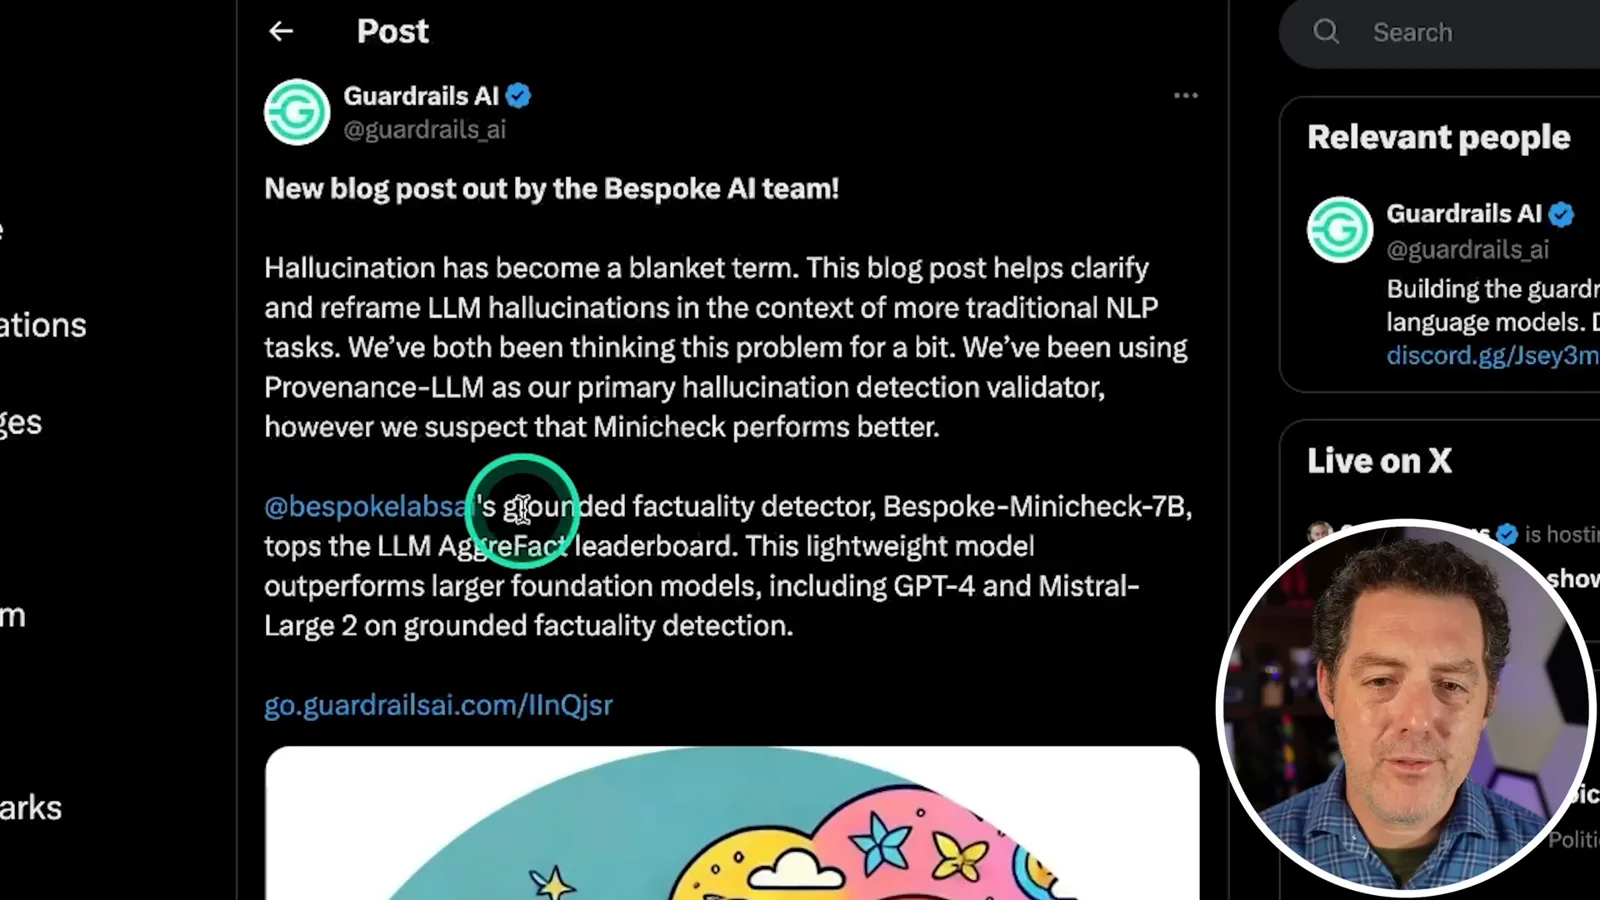
Guardrails AI highlighted Bespoke Labs’ Bespoke-MiniCheck-7B grounded-factuality detector. The displayed post says it led the LLM AggreFact leaderboard and outperformed selected larger models on that task. I have not tested it, and strong grounded-factuality detection does not solve every kind of hallucination.
Kyutai released artifacts for Moshi, a speech-and-text foundation model for real-time dialogue, including a paper and code. I find the low-latency voice interaction interesting and compare it with the GPT-4o voice experience discussed at the time, without claiming the two systems are identical.
GRIN MoE and Qwen 2.5
Berman compares model releases using their reported active parameters and the benchmarks available at the time. Rankings apply to specific tests.
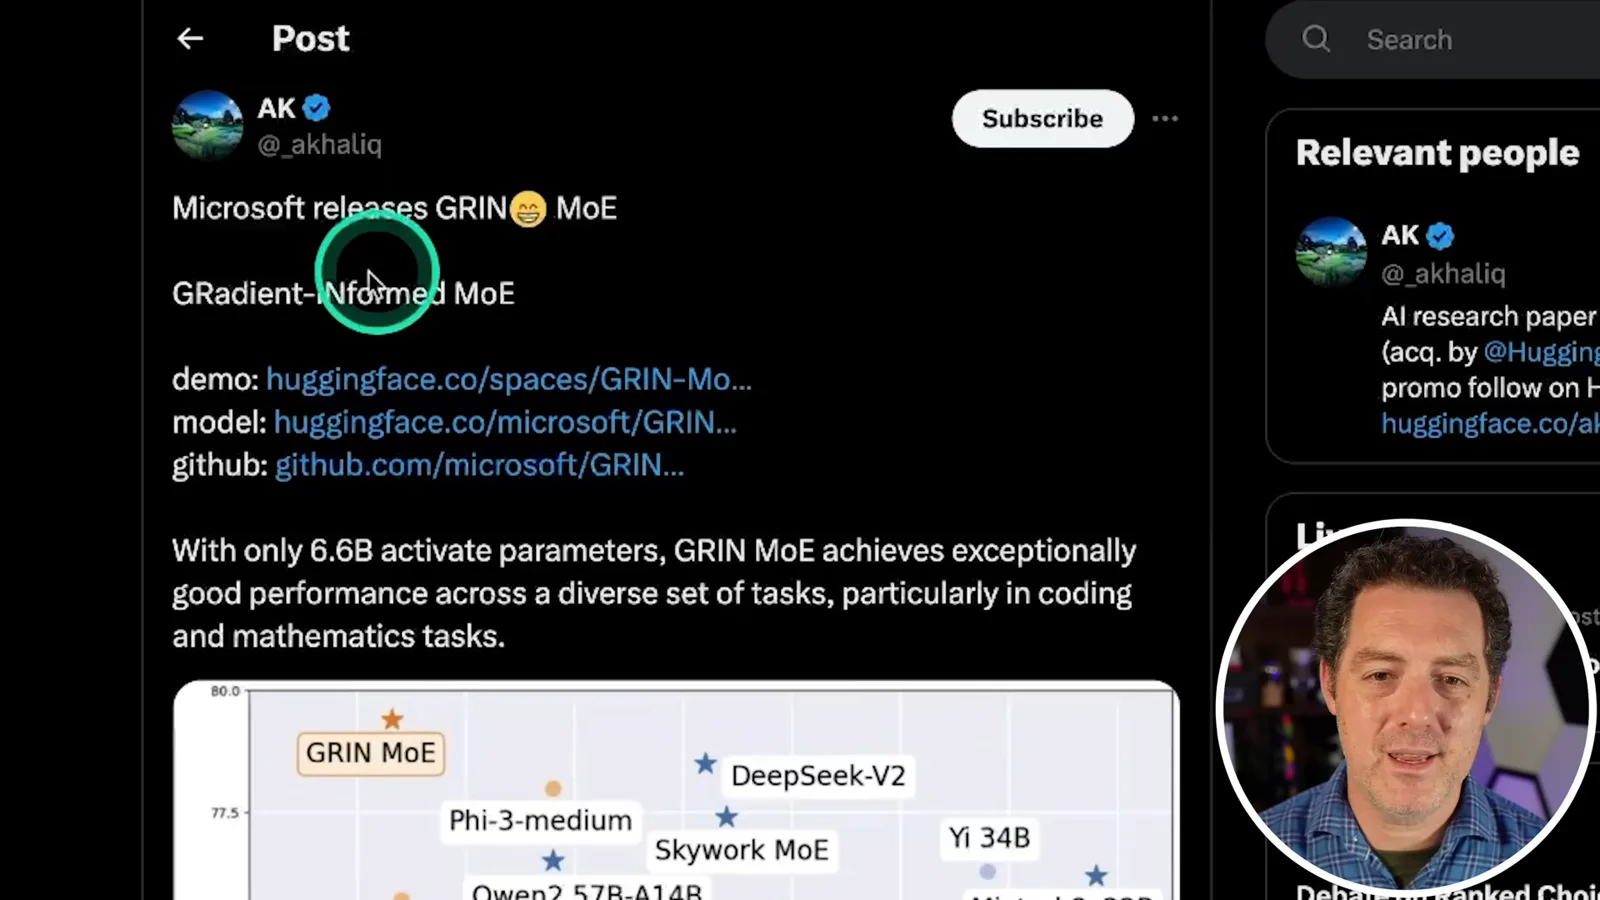
Microsoft released GRIN MoE, a gradient-informed mixture-of-experts model. Its announcement reports 6.6 billion active parameters and strong results on selected coding and mathematics tasks. Active parameters are only part of the model’s size and resource requirements; benchmark comparisons depend on the tests and conditions.
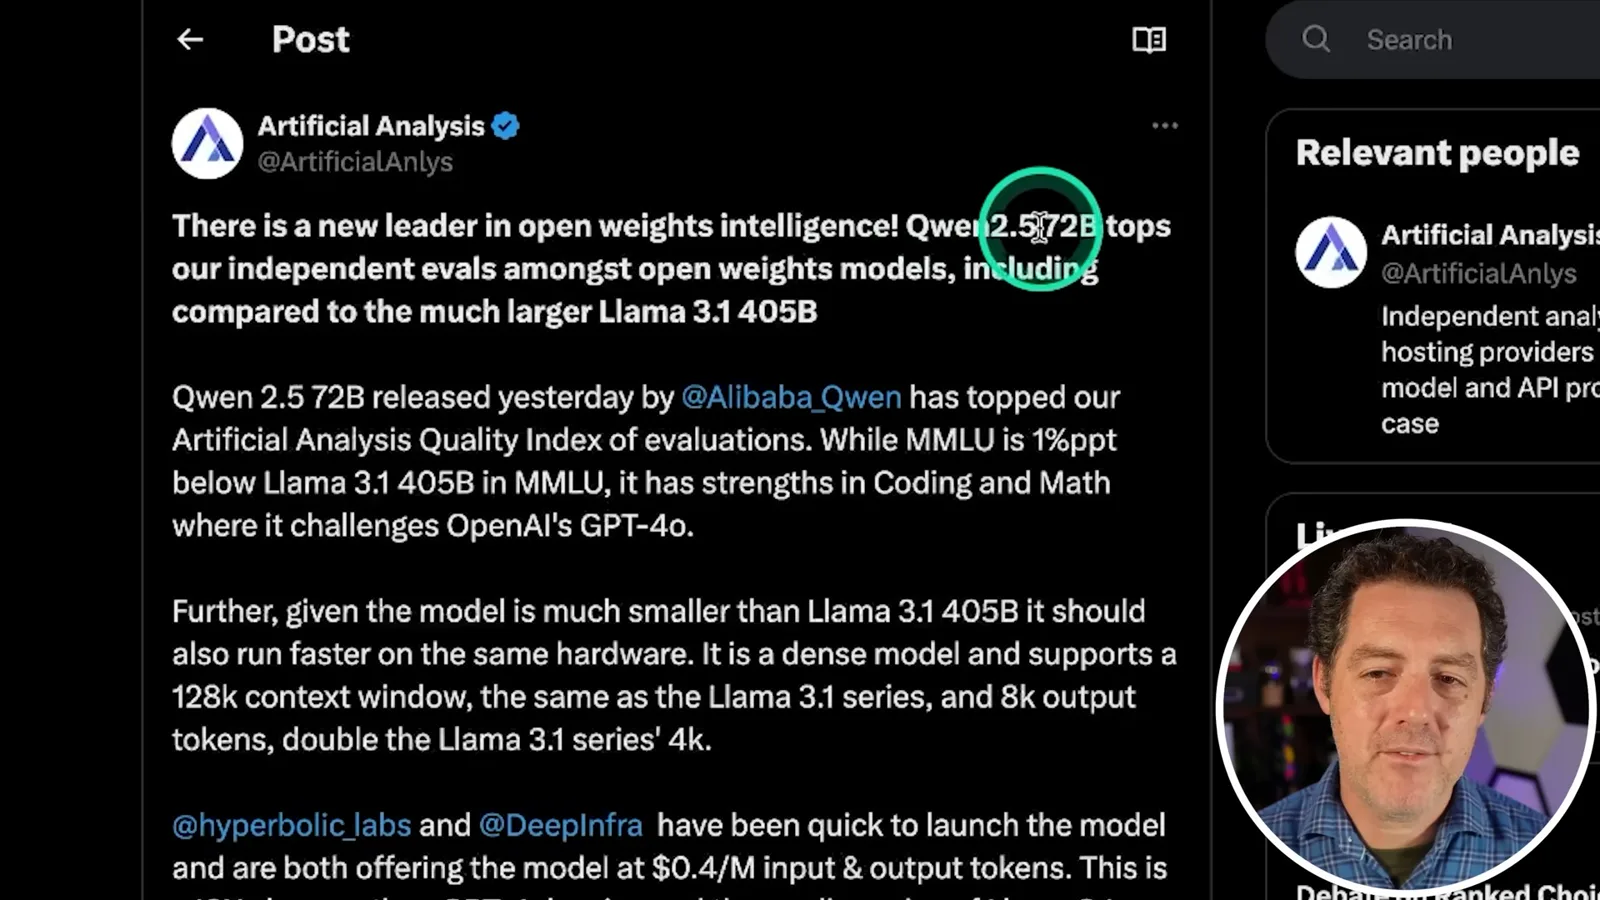
Artificial Analysis reported that Alibaba’s Qwen 2.5 72B led its open-weight quality index at the time, ahead of Llama 3.1 405B on that index. The dense model supported a 128K context window. I review its reported MMLU and math scores, which vary by task and do not make it the best model in every use case.
Funding, Europe and AI governance
The final stories cover a reported OpenAI funding round, companies’ EU launch decisions and Helen Toner’s Senate testimony. Berman gives his own views on regulation.
I discuss reports that OpenAI’s next funding round was oversubscribed, with Thrive leading a proposed investment and a reported $150 billion pre-money valuation. Those were financing reports as of September 2024, not a guarantee of the round’s final terms. My confidence that OpenAI would continue raising money is my opinion, not a financial forecast readers can rely on.
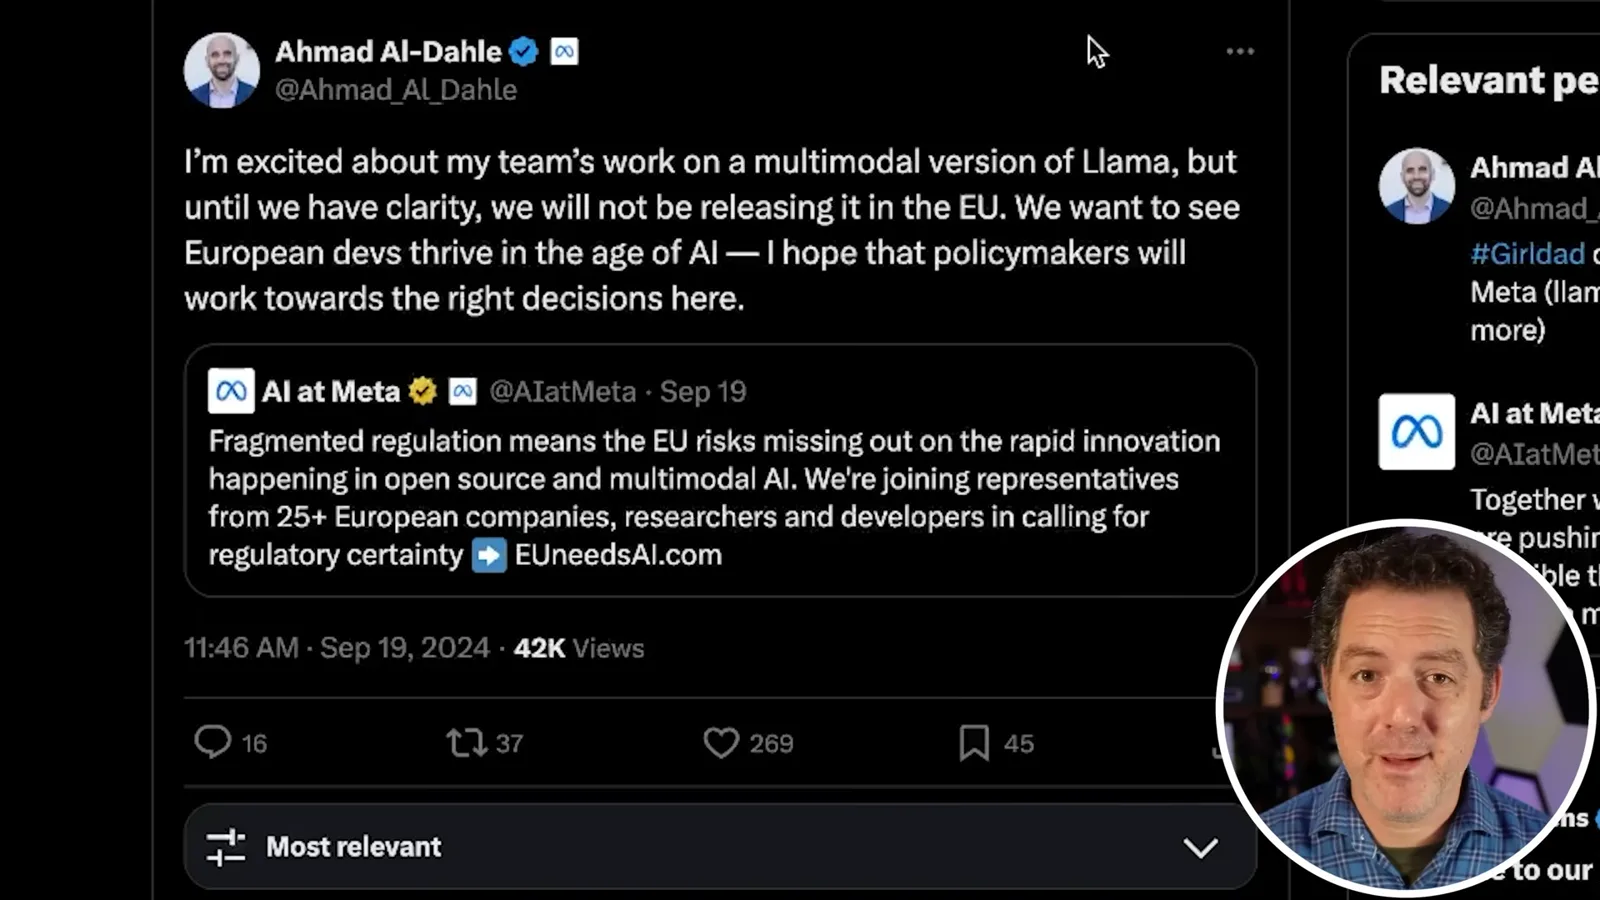
Meta executive Ahmad Al-Dahle said a multimodal Llama would not be released in the EU until the company had more regulatory clarity. I also discuss Apple delaying Apple Intelligence features in the region and disagree with the situation. These are decisions and statements from 2024, not a description of current EU availability.
Former OpenAI board member Helen Toner testified before a Senate Judiciary subcommittee about the potential consequences of advanced AI, ranging from disruption to the possibility of human extinction. I disagree with her regulatory outlook and favor faster development. Her warning and my criticism are competing views about uncertain future risks, not established predictions.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026년 10월 21일A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.