30초 요약
Berman reviews Meta’s Llama 3.2 announcement: 11B and 90B vision models and 1B and 3B text models. He explains the reported architecture and benchmarks and tests a hosted 1B preview; the video was made in partnership with Meta.
- 1Four model sizesTwo larger models support vision, while two smaller models are text-only.
- 2Reported benchmarksBerman reviews Meta’s comparisons with contemporary models.
- 3A hosted 1B testA story and Snake game are generated on Groq’s service.
- 4Vision architectureThe model uses an image encoder connected by cross-attention adapters.
핵심 정리
- Llama 3.2 introduced 11B and 90B image-capable models and smaller text-only models.
- The 1B and 3B versions target constrained and edge devices.
- Meta’s vision architecture connects an image encoder through cross-attention adapters.
- The brief Groq demo is a hosted test, not a measurement of local device speed.
- The benchmark figures shown are Meta-reported and specific to the evaluated tasks.
챕터별로 다듬은 전문 읽기
The Llama 3.2 family
Berman introduces the model sizes and their target environments.
At Meta Connect, Meta announced Llama 3.2 with new sizes and vision capabilities. Meta partnered with me on this video. I will review the announcement and show a brief test of the smallest model; I leave vision testing for a later video.
The 11B and 90B models add image understanding, while the 1B and 3B models are text-only and designed for more constrained devices. Meta presents the vision variants as compatible replacements for corresponding Llama 3.1 text models, subject to the actual deployment requirements.
I expect more AI computation to move onto phones, computers and other edge devices. Meta describes the smaller models as pretrained and instruction-tuned with a 128K context window, and lists optimization for Qualcomm and MediaTek processors.
Tools and reported benchmarks
He reviews Llama Stack and Meta’s benchmark tables.
Meta provides tooling for customization and local deployment, including torchtune and torchchat, along with access through its ecosystem. The Llama Stack is intended to simplify building applications across cloud, on-premises and device environments.
The stack’s announced interfaces cover inference, safety, memory, agent systems, evaluation and post-training among other functions. Meta lists several distribution and cloud partners, though availability and terms depend on the provider.
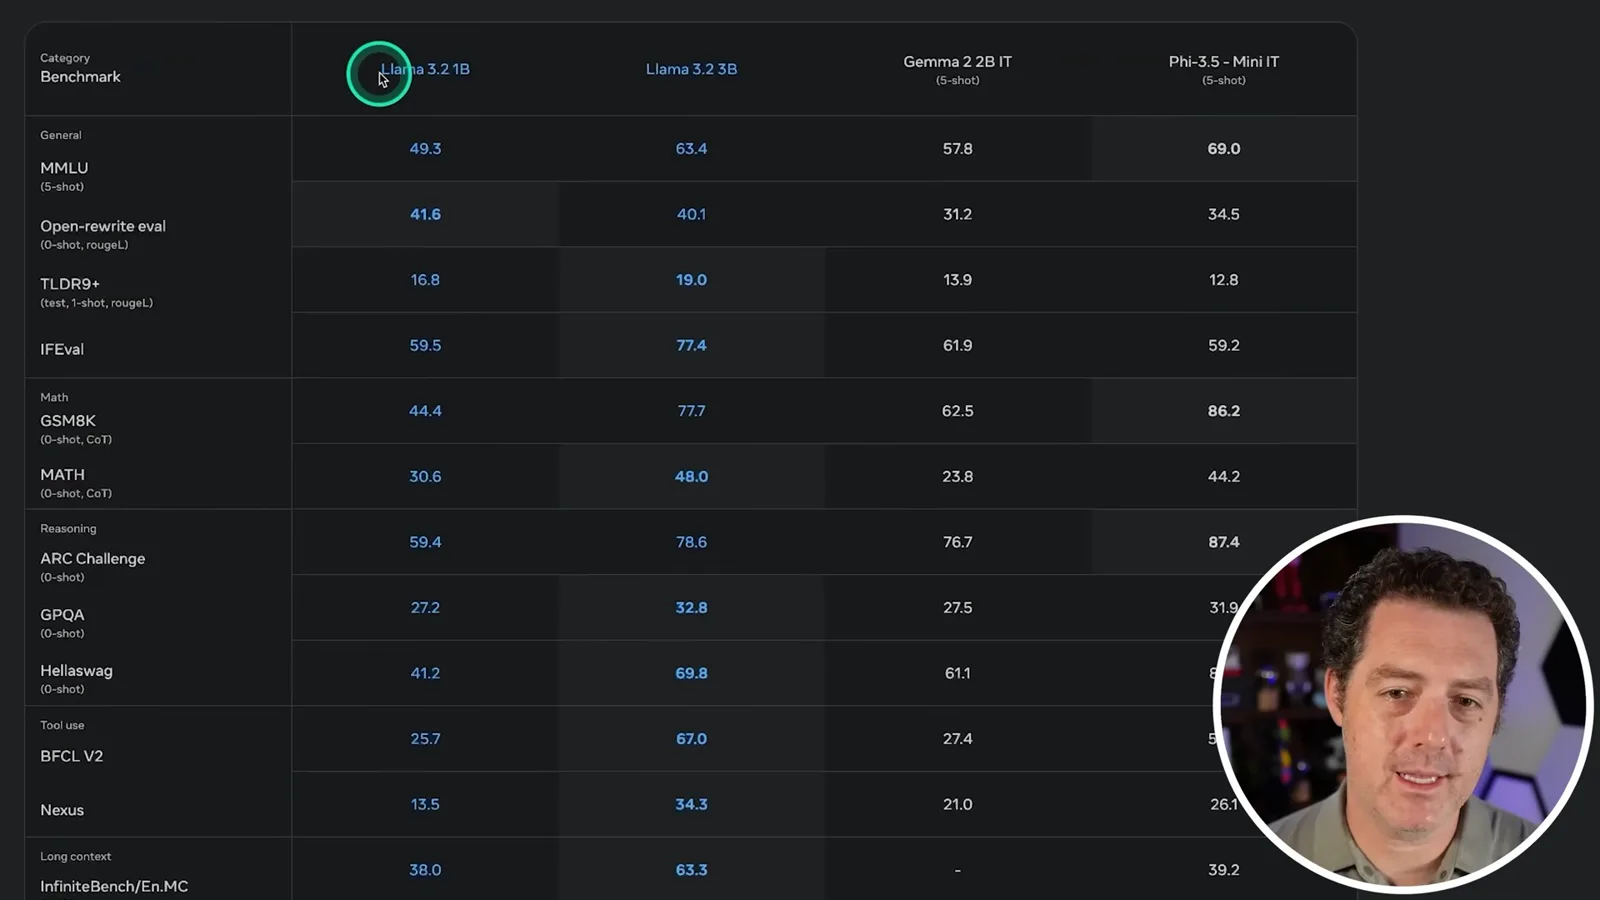
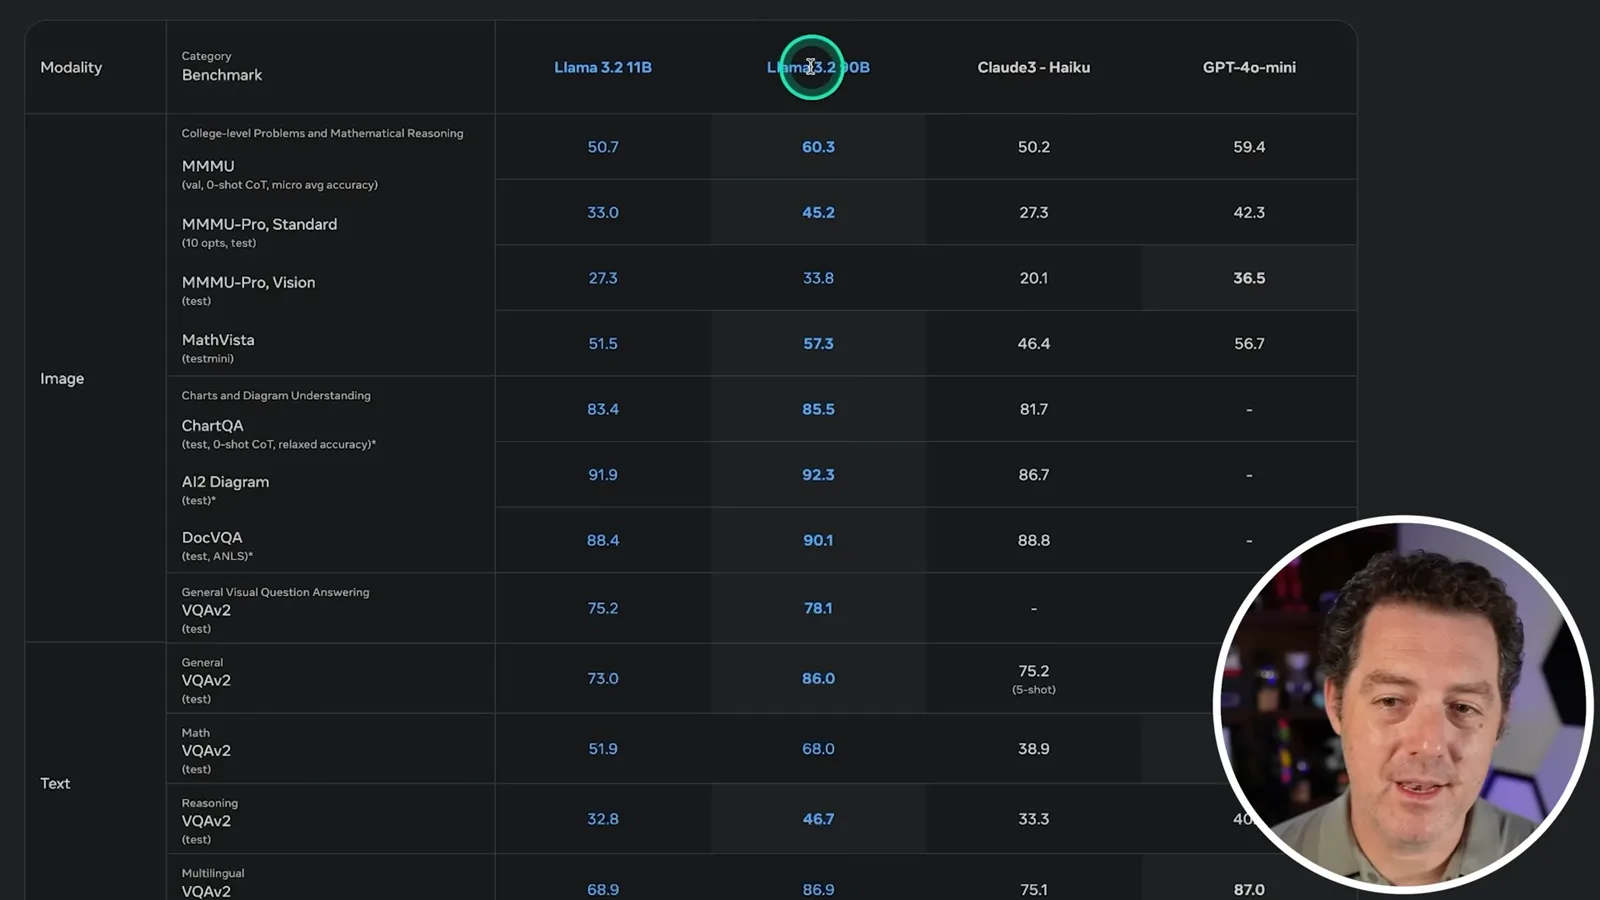
I review Meta’s benchmark tables comparing the 1B and 3B text models with small peers and the vision models with other models available at the time. The displayed scores are vendor-reported results on particular tests, not a guarantee of performance on every task.
A small-model test
He tries the hosted 1B preview and outlines vision use cases.
Using Groq’s hosted 1B preview, I ask for a story and then a Python Snake game. I observe more than 2,000 tokens per second and report that the game works on the first attempt; this is a single hosted demonstration, not an on-device speed measurement.
Meta describes the vision models as supporting image reasoning, including charts, document understanding, captions and visual grounding. For example, a user might ask which month had the best sales based on a graph. I plan to test those capabilities separately.
Training and architecture
He explains image adapters, post-training and distillation.
The announced architecture connects a pretrained image encoder to the language model through adapter weights and cross-attention layers. Meta says it trained these on image-text pairs, updating the image encoder while keeping the language-model parameters fixed during adapter training.
For post-training, Meta describes supervised fine-tuning, rejection sampling and direct preference optimization, plus synthetic data generated with Llama 3.1. It also uses pruning and distillation to create smaller models, with the larger Llama model acting as a teacher.
I welcome the release and plan separate follow-up tests of text and vision intelligence. This video is an announcement overview and one informal text test, so broader claims about quality need further evaluation.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026년 10월 23일Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026년 10월 22일Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026년 10월 21일A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.