30초 요약
Theo Browne describes three eras of agentic coding through Sonnet 3.5, Opus 4.5 and Mythos 5. In his view, the progression runs from reliable tool calls to longer tasks and then to orchestrating and verifying delegated work.
- 1Tool callsSonnet 3.5 was not the first model with tool calls, but Theo found them reliable enough for daily coding work.
- 2Long-running workTheo says Opus 4.5 could work for longer without losing track of its task.
- 3OrchestrationHe describes Mythos 5 as a jump toward delegating parts of a task to other models and verifying their work.
핵심 정리
- Theo associates Sonnet 3.5 with reliable tool calls for everyday coding.
- He sees Opus 4.5 as a step toward longer-running tasks.
- He associates Mythos 5 with breaking work up, delegating it and verifying the results.
챕터별로 다듬은 전문 읽기
Three eras of coding agents
Theo connects three model releases with tool calling, long-running work and orchestration. This is his framework for understanding their progress.
I think of these as eras. Sonnet 3.5 represents the tool-call era: it was not the first model able to call tools, but, in my experience, it was the first to do so consistently and reliably enough for everyday coding.
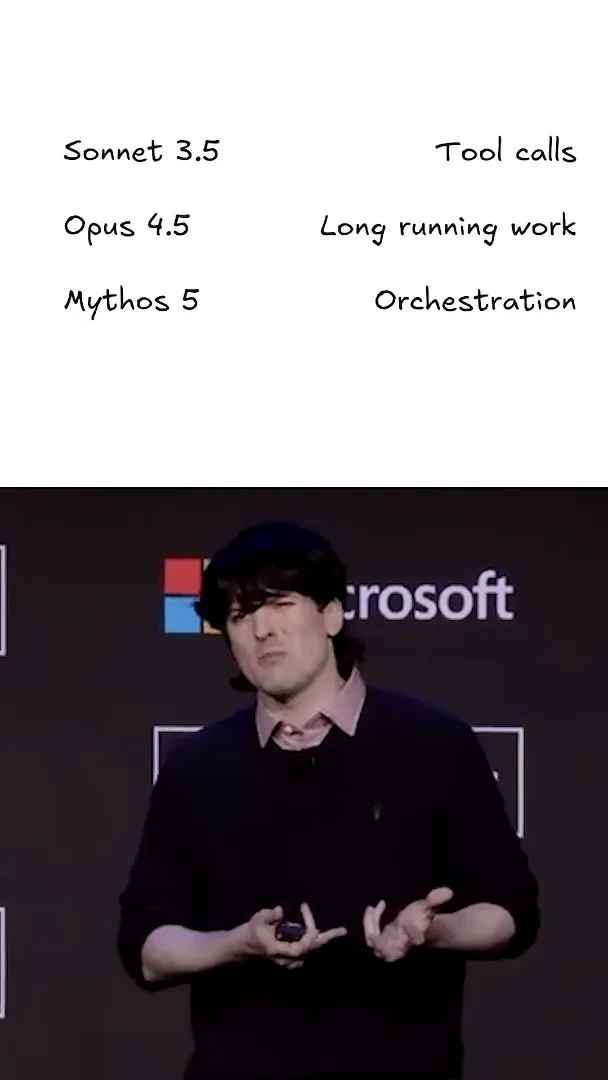
Then came Opus 4.5, which could work on much longer-running tasks without losing track of what it was doing.
Mythos 5 feels like another jump, this time to orchestration. In my experience it understands not only the codebase but how to use other models: it can split up work, spawn additional agents, and have the results verified afterward when asked.
같은 채널의 다른 글
 38:47EN
 Theo - t3․gg· 2026년 10월 28일Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026년 10월 27일Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026년 10월 26일Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026년 10월 23일Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026년 10월 22일Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026년 10월 20일Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.