30초 요약
Modal’s Jason Mancuso argues that teams with production agent harnesses and evaluations already have a starting point for reinforcement-learning environments. He describes an asynchronous training recipe that combines masked importance sampling, score centering and top-p mask replay to address differences between training and sampling. In Modal’s coding-agent experiment, compressed weight updates allowed rollout inference across multiple providers and GPU types; the company reports 15% lower rollout cost in that run, not a universal saving.
- 1Production traces can help build training tasksMancuso proposes mining failures and generating representative tasks around real agent usage.
- 2Asynchronous rollout generation trades idle compute for stalenessThe trainer may learn from data generated by an older model version, introducing policy mismatch.
- 3Three corrections target sampling and training mismatchThe recipe adds masked importance sampling, score centering and top-p mask replay to GRPO.
- 4Sparse weight updates enable geographically distributed inferenceMancuso reports compressing updates so samplers can run outside the main training cluster.
- 5A mixed-GPU run reported 15% lower rollout costThat result applies to Modal’s reported run and hardware mix; it is not a general cost guarantee.
핵심 정리
- Production agent harnesses, evaluations and representative tasks can help form an RL environment.
- Asynchronous rollouts improve hardware utilization but introduce stale-policy and system-level mismatches.
- Modal combines masked importance sampling, score centering and top-p mask replay to address those mismatches.
- Compressing sparse weight updates can separate rollout inference from the training cluster.
- Mixed GPU and precision rollout pools reduced cost in one reported run, with stability measured on the tested workload.
챕터별로 다듬은 전문 읽기
Why teams fine-tune agents
Mancuso discusses inference ownership, proprietary tasks and differentiation. He contrasts supervised traces with reinforcement learning.
Jason Mancuso of Modal argues that treating models only as interchangeable static backends can limit differentiation. Teams deploying agents must balance cost, reliability and the quality of the user experience.
He says some customers fine-tune open models to own inference and meet reliability objectives. Others work with proprietary data or specialized tasks that general models do not handle well enough out of the box.
Mancuso also sees interest in integrating more of the agent stack to compete on task quality per dollar, especially in coding. He expects interest in fine-tuning to spread as more sectors develop mature agent products.
He contrasts supervised fine-tuning on recorded traces with reinforcement learning in an environment. Agent sessions branch across many turns, so training only on recorded paths may leave a model unprepared for paths it encounters later.
RL can generate and evaluate new trajectories during training, giving the model a chance to explore more of the task space. Mancuso presents that exploration as one reason teams hope RL will generalize beyond recorded traces.
From production agents to RL environments
An agent harness, evaluations and representative tasks provide a foundation for training. He outlines the rollout and trainer loop.
He argues that a production harness and some form of evaluation or change measurement are a starting point for an RL environment. Representative tasks can be generated from production traces, including cases where the agent failed.
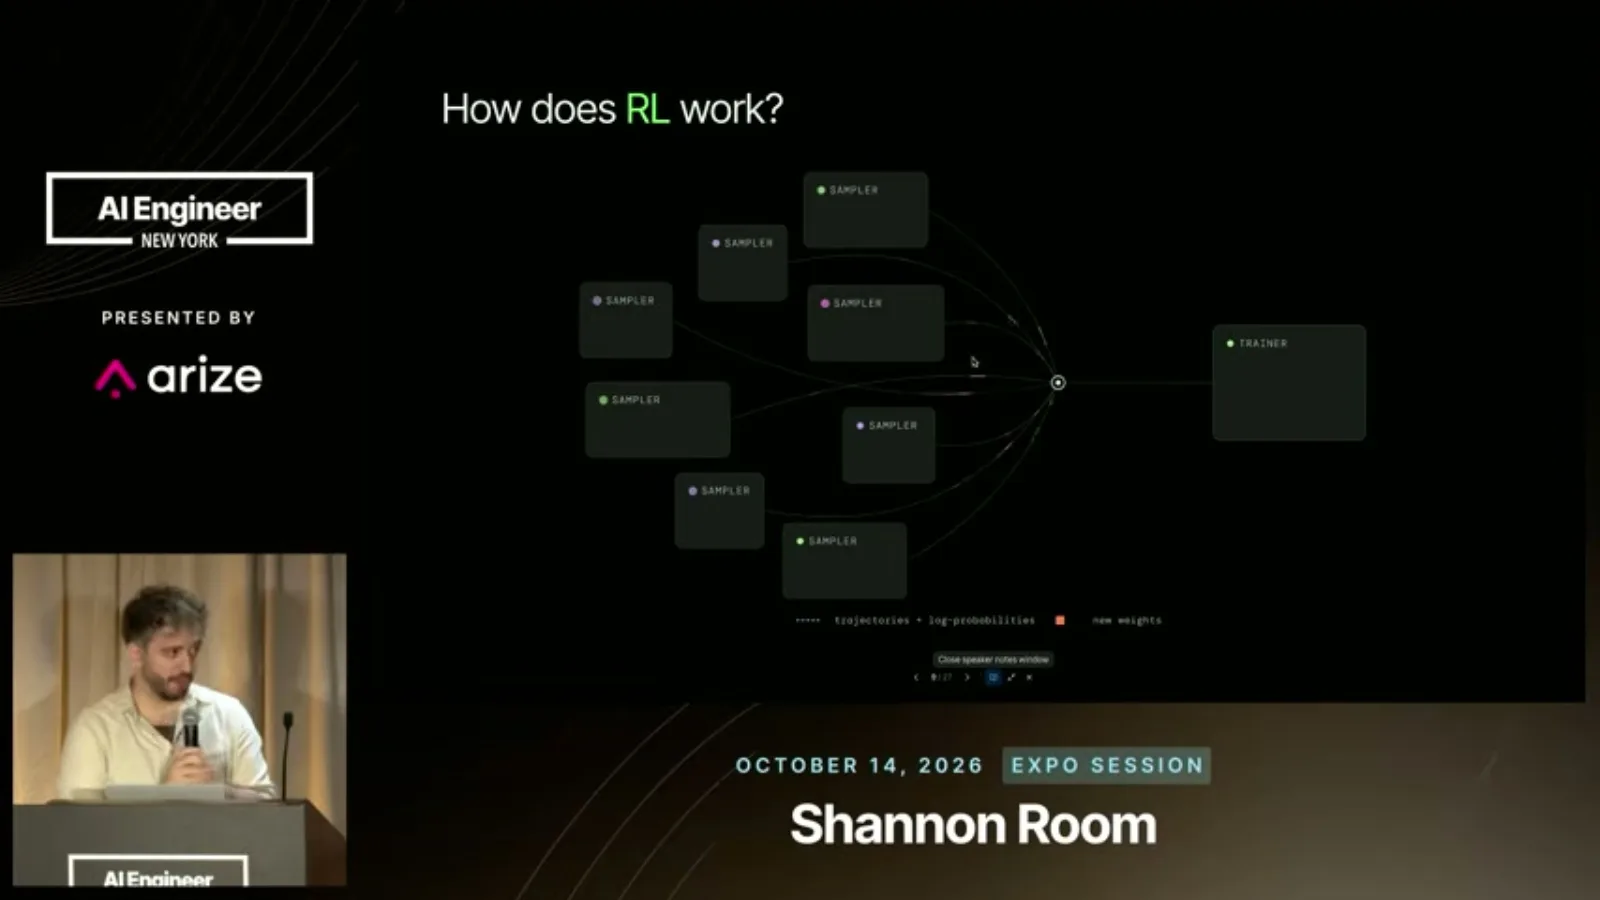
The training loop has two broad parts. Sampler GPUs run the model in the environment to generate rollouts; a trainer consumes those results, updates the model and sends new weights back to the samplers.
Stabilizing asynchronous training
Asynchronous execution improves utilization but introduces mismatch. Modal combines three corrections in its reported recipe.
A sequential loop keeps rollouts aligned with the latest model but can leave hardware idle. Running rollout generation and training asynchronously improves utilization, especially for long agent tasks.
The tradeoff is staleness: a rollout may come from an older model version while the trainer has already advanced. The resulting difference between sampling and training policies can make the update less stable.
Additional mismatch arises from systems details: inference and training stacks, numerical precision, routing and hardware may not behave identically. Mancuso says the method needs to correct important differences without overwhelming the training signal.
The recipe starts with GRPO and adds masked importance sampling. The method adjusts token-level weighting for differences between the sampling and training policies while masking extreme ratios that could dominate an update.
A second component, score centering, addresses drift that remains or is reintroduced by masking. Modal’s accompanying technical explanation describes subtracting an expected score term so that the retained training signal is less distorted.
The third component is top-p sampling with mask replay. Sampling restricts candidates to a set containing the chosen cumulative probability mass, and replaying that mask makes the trainer work with the same support.
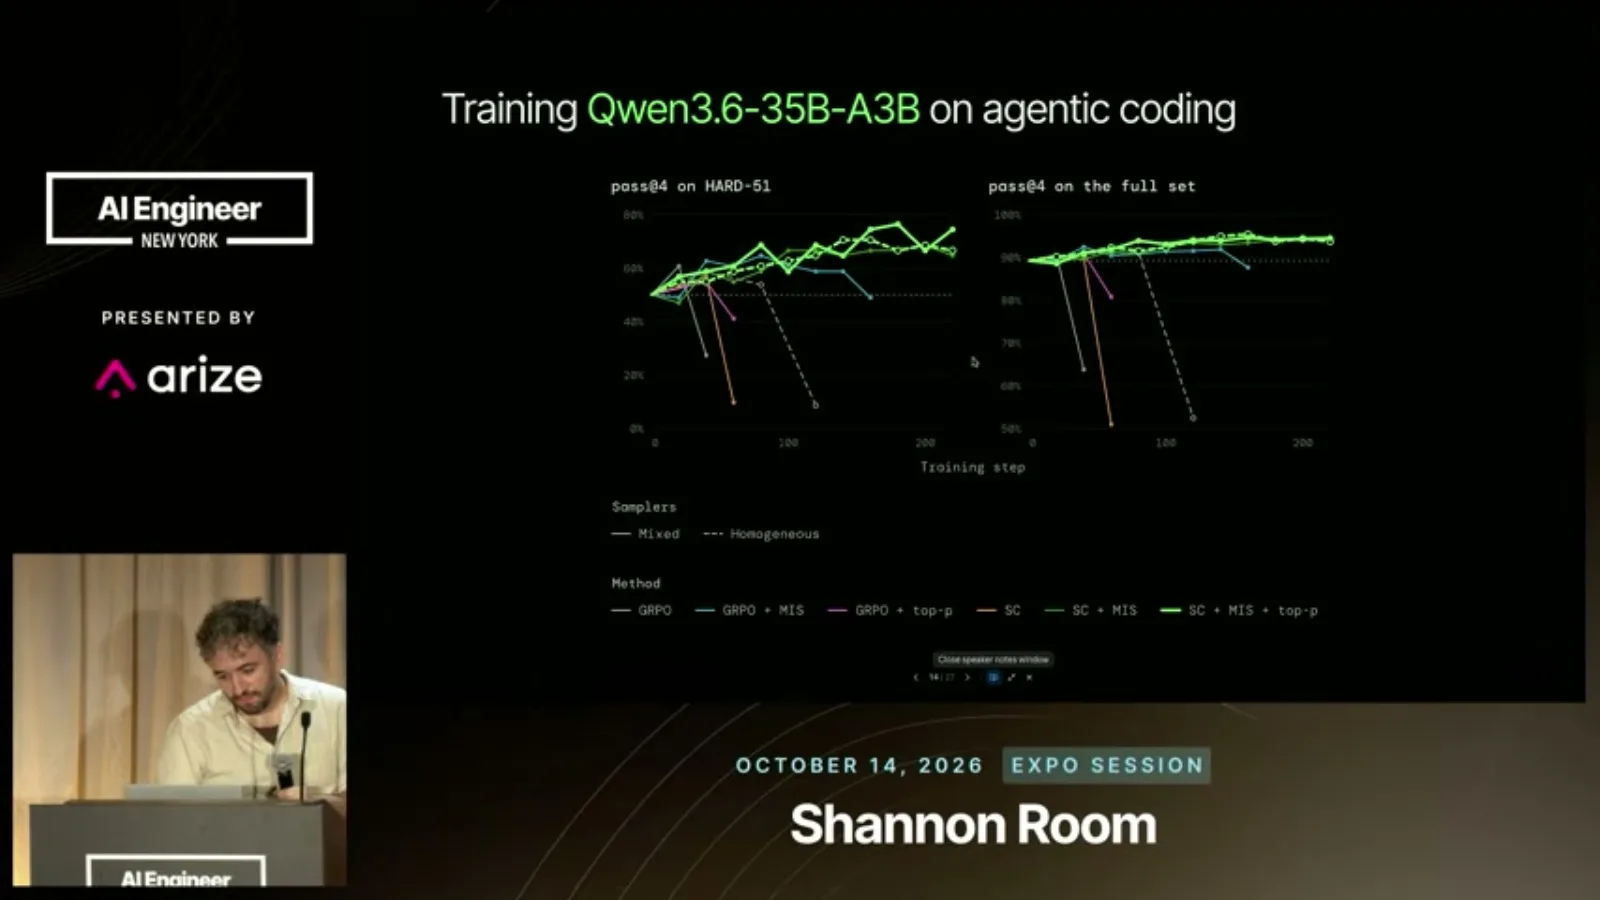
Mancuso shows an ablation using Qwen3.6-35B-A3B on agentic coding tasks. He reports that combining the corrections made the tested training run more stable than the alternatives shown.
Scaling across providers and GPU types
Fragmented GPU capacity motivates separate training and rollout fleets. Sparse updates and heterogeneous inference are tested on coding tasks.
He then explains why distributed RL matters to Modal. The company provides training, inference and sandbox environments, but aggregates GPU capacity across many providers and regions rather than a single uniform pool.
That aggregation offers flexibility but fragments available capacity. Mancuso says small clusters can be scheduled relatively quickly, while finding a contiguous block for a larger cluster can take much longer.
For agent RL, he estimates roughly two inference GPUs for every training GPU in the relevant workload. If all of them must sit in one cluster, much of the scarce contiguous capacity is occupied by rollout inference rather than training.
The proposed approach moves inference outside the main cluster. Mancuso says successive model-weight updates are sparse enough to compress substantially, reducing the amount of data sent from the trainer to rollout engines.
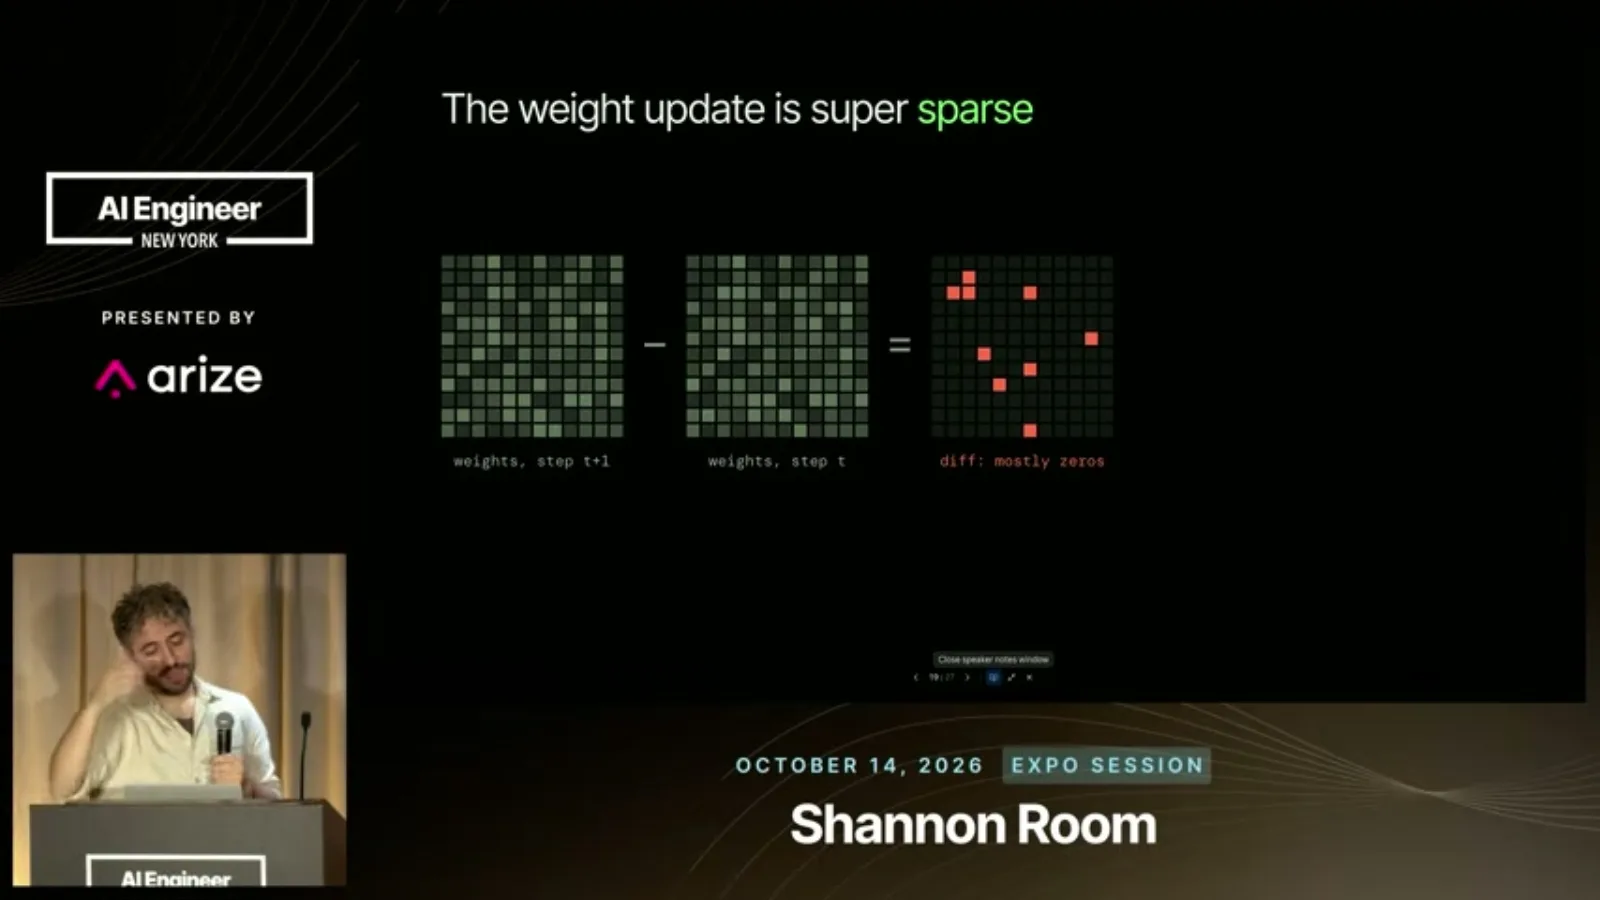
In the reported Qwen run, the training cluster operated in one location while inference GPUs ran across multiple cloud providers. Mancuso reports that sparse delta compression made this arrangement practical in their test.
The team also mixes GPU types and precision settings. A trainer on one accelerator and samplers on other accelerators can introduce numerical and kernel differences that would traditionally threaten stability.
Mancuso shows a mixed-hardware run and says the mismatch was several times larger than in a homogeneous setup, yet reward and gradient behavior remained comparably stable under the reported recipe.
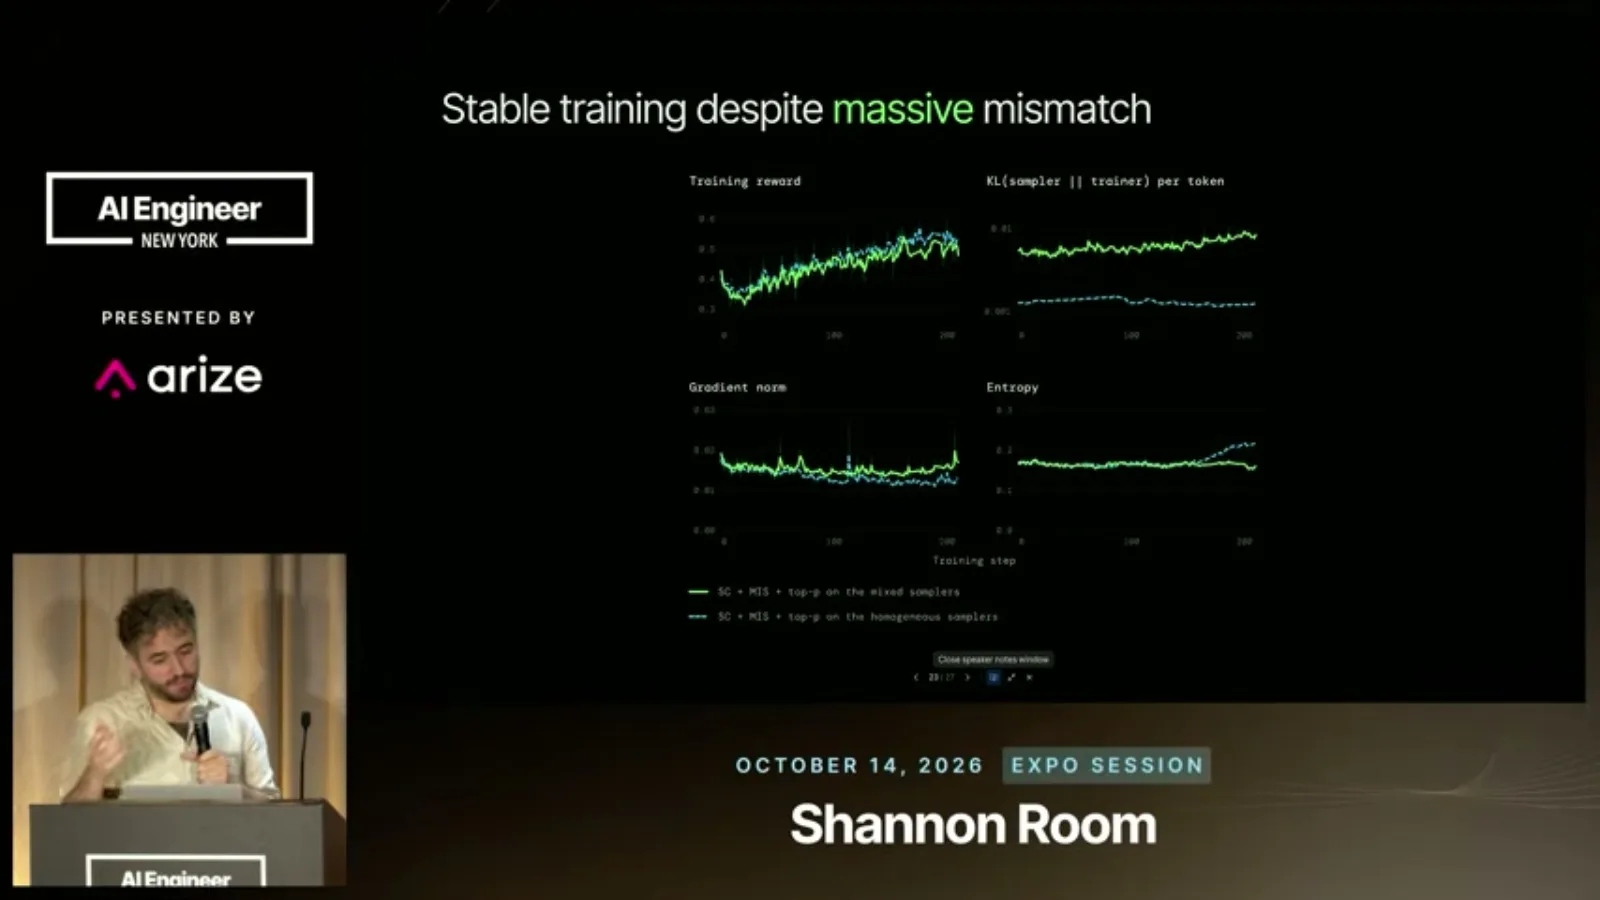
He reports that rollouts cost 15% less in this run because some inference used less expensive hardware. The number describes that particular workload and fleet; it does not establish a saving for every RL deployment.
The team also used different precisions, including BF16 and FP8 on H200 pools. Mancuso says the corrections allowed learning from those quantized rollouts in the tested setup, even with additional mismatch.
Cost and the case for owning the stack
Mancuso reports rollout savings in one mixed-GPU run and discusses the value of developing fine-tuning expertise.
He points to Modal’s technical write-up and says the implementation builds on Miles and SGLang. His broader recommendation is for teams to build competence beyond the agent harness, including evaluation, inference and training.
Mancuso closes by arguing that greater ownership of the stack can support differentiation in competitive agent markets. The reported techniques are evidence from a particular coding-agent setup, not a guarantee that all RL problems are solved.
같은 채널의 다른 글
 19:41EN
 AI Engineer· 2026년 11월 9일A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 22:01ENAI Engineer· 2026년 11월 9일Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· 2026년 11월 9일Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 15:25ENAI Engineer· 2026년 11월 9일Hassan and Omar El Mghari: When an AI financial forecast is right for the wrong reasonsHassan El Mghari, Omar El Mghari · Together AIA Costco membership-fee model passed basic checks and landed close to reported results, but an audit uncovered offsetting assumptions.
 14:38ENAI Engineer· 2026년 11월 9일Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· 2026년 11월 9일Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.