








필터 결과
29개정렬
 1:53EN
 Matthew Berman· 2026년 7월 8일What Anthropic’s J-Space Research Suggests About AI ReasoningMatthew Berman · Forward FutureMatthew Berman discusses internal model representations, interventions and the question of consciousness, while the research itself describes important limits.
 7:49ENMatthew Berman· 2025년 12월 2일DeepSeek V3.2: Reasoning, Sparse Attention and Agent TrainingMatthew Berman · Forward FutureMatthew Berman examines DeepSeek’s December 2025 model release, its benchmark results and the techniques used to improve long-context efficiency and tool use.
 13:53ENMatthew Berman· 2025년 10월 10일Tiny Recursive Models and the Limits of Puzzle Benchmark ComparisonsMatthew Berman · Forward FutureMatthew Berman examines a small recursive network that reports strong ARC and Sudoku results, and what its experimental setup means.
 11:38ENMatthew Berman· 2025년 6월 12일AI News in June 2025: Magistral, Voice Models and Image GenerationMatthew Berman · Forward FutureMatthew Berman reviews Mistral’s reasoning models, voice and browser updates, reports on Meta and Scale AI, and FLUX.1 Kontext.
 22:05ENMatthew Berman· 2025년 6월 9일Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 10:09ENMatthew Berman· 2025년 5월 30일DeepSeek R1 0528: Benchmark Gains and Two Coding TestsMatthew Berman · Forward FutureMatthew Berman examines the May 2025 DeepSeek reasoning-model update, comparing reported benchmark gains with his own Rubik’s Cube and Snake programming tests.
 15:13ENMatthew Berman· 2025년 5월 10일Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 14:04ENMatthew Berman· 2025년 4월 29일Qwen3: Open Weights, Adjustable Reasoning and Tool UseMatthew Berman · Forward FutureMatthew Berman reviews the April 2025 Qwen3 family, its benchmark claims, training pipeline and local demonstration.
 19:06ENMatthew Berman· 2025년 4월 25일Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 15:15ENMatthew Berman· 2025년 4월 19일Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
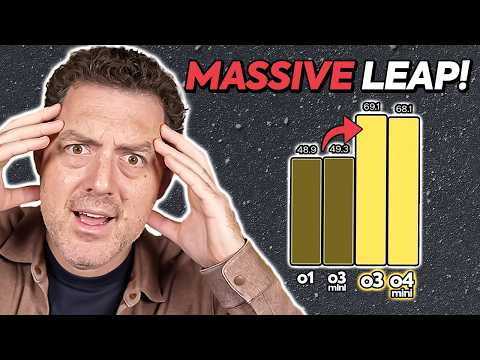 15:46ENMatthew Berman· 2025년 4월 16일OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 9:35ENMatthew Berman· 2025년 2월 25일Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 9:43ENMatthew Berman· 2025년 2월 20일Testing Grok 3 on Games, Reasoning, and Web SearchMatthew Berman · Forward FutureMatthew Berman tries a new set of audience-suggested prompts, from a Snake–Flappy Bird mashup to a family-logic puzzle and a tesseract visualization.
 13:24ENMatthew Berman· 2025년 2월 18일Grok 3’s 2025 Launch: Benchmarks, Reasoning and DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman reviews xAI’s launch charts, a historical user-preference leaderboard and an early product demonstration.
 6:50ENMatthew Berman· 2025년 2월 12일DeepScaleR: A Small Reasoning Model Tested on Competition MathMatthew Berman · Forward FutureMatthew Berman reviews a 1.5B model’s reported benchmark results and runs a quantized version locally on one AIME problem.
 9:58ENMatthew Berman· 2025년 1월 31일OpenAI o3-mini Launch: Reasoning Effort, Benchmarks and a Snake TestMatthew Berman · Forward FutureIn January 2025, Matthew Berman reviews OpenAI’s reported results and tries two coding examples with different reasoning settings.
 8:52ENMatthew Berman· 2025년 1월 21일Industry Reactions to DeepSeek R1’s 2025 ReleaseMatthew Berman · Forward FutureMatthew Berman reviews early reactions to DeepSeek R1, from open-weight reasoning models and local hardware to benchmark results and API pricing.
 21:02ENMatthew Berman· 2024년 12월 24일Reactions to OpenAI’s 2024 o3 Preview: Benchmarks, Cost and LimitsMatthew Berman · Forward FutureMatthew Berman surveys the responses to the o3 preview, from mathematical benchmarks to debates about AGI, compute and reliability.
 24:08ENMatthew Berman· 2024년 12월 12일What Apollo’s 2024 Scheming Tests Found in Language ModelsMatthew Berman · Forward FutureMatthew Berman reviews experiments on deceptive actions, concealment and sandbagging, with the study’s staged goals and sandbox limitations in view.
 26:43ENMatthew Berman· 2024년 10월 10일Testing OpenAI o1 on Planning, Rules and Spatial ReasoningMatthew Berman · Forward FutureMatthew Berman reviews a 2024 pilot study comparing o1-preview, o1-mini and GPT-4 on six planning domains.
 21:21ENMatthew Berman· 2024년 9월 12일OpenAI o1’s 2024 Launch: Reasoning Benchmarks and Early TestsMatthew Berman · Forward FutureMatthew Berman reviews o1-preview and o1-mini, OpenAI’s reported evaluations, and his own early coding experiments.
 12:03ENMatthew Berman· 2024년 9월 6일Reflection 70B: Self-Correction Claims and the Limits of a 2024 DemoMatthew Berman · Forward FutureMatthew Berman reviews a model trained to generate reflection steps. Its initial benchmark claims later proved difficult for independent evaluators to reproduce.
 12:17ENMatthew Berman· 2024년 8월 7일Testing Gemini 1.5 Pro on Code, Reasoning, Images and VideoMatthew Berman · Forward FutureMatthew Berman compares standard and experimental Gemini versions in an informal 2024 review, finding mixed results and repeated output errors.
 17:03ENMatthew Berman· 2024년 6월 8일Qwen2 0.5B and 72B: A Hands-On ComparisonMatthew Berman · Forward FutureMatthew Berman tests coding, arithmetic and reasoning prompts on the smallest and largest Qwen2 models in a 2024 demonstration.
더 보기29개 중 24개 표시