30 秒でわかる
In this July 17, 2026 short, Matthew Berman says Kimi K3 signals that Chinese open-weight models are catching up with leading proprietary models. He cites its front-end coding leaderboard placement and says he is eager to try it. Moonshot released the full weights on July 27, after the video.
- 1A competitive open-weight modelBerman sees Kimi K3 as evidence that Chinese models are catching up to proprietary frontier models.
- 2Scale and contextMoonshot lists 2.8 trillion parameters and a one-million-token context window.
- 3A specific coding leaderboardThe video places K3 ahead of Claude Fable 5 and GPT-5.6 Sol in Arena’s front-end coding ranking; this is not a claim of overall superiority.
- 4Weights followed laterK3 was available through Moonshot services at launch. Full model weights were released on July 27, after this video.
ポイント
- Moonshot describes Kimi K3 as a 2.8-trillion-parameter model with a one-million-token context window.
- The video shows Kimi K3 above Claude Fable 5 and GPT-5.6 Sol on a front-end coding ranking, not on every task.
- The full model weights were released on July 27, 2026, after the July 17 video.
チャプターごとに整えた全文を読む
Kimi K3 and the front-end coding result
Berman cites the model’s scale, context window and Arena front-end coding position. He expresses enthusiasm for an open-weight frontier model; the full weights followed later.
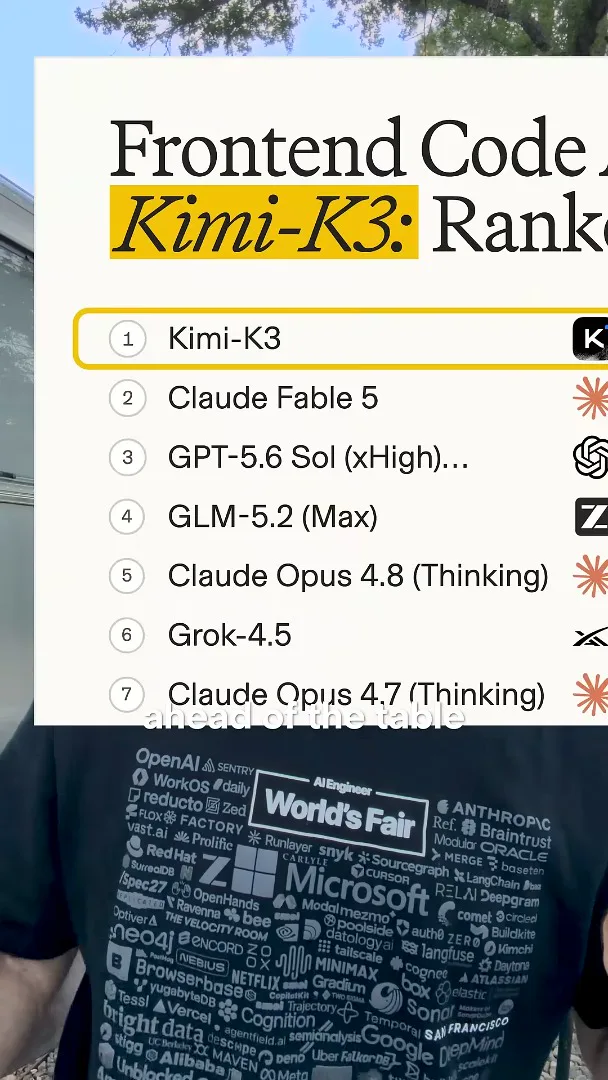
Chinese open-weight models may have caught up, at least on this test. Moonshot AI’s Kimi K3 has 2.8 trillion parameters and a one-million-token context window, according to the company’s [launch announcement](https://www.kimi.com/en/blog/kimi-k3). The video’s Arena front-end coding ranking puts Kimi K3 first, ahead of Claude Fable 5 and GPT-5.6 Sol.
I see Kimi K3 as a frontier-class model and can’t wait to use it. That leaderboard covers front-end coding, not all model capabilities: Moonshot itself says K3’s overall performance still trails Fable 5 and GPT-5.6 Sol in its evaluation suite. At the time of this July 17, 2026 video, Moonshot offered hosted access and promised open weights; it [released the full weights on July 27](https://www.kimi.com/news/kimi-k3-open-source).
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.