30 秒でわかる
In this February 2025 video, Matthew Berman reviews a Stanford preprint on multi-agent reinforcement learning for a simplified social-deduction game. Researchers use the simulated imposter identity to train listening and reward messages that improve teammates’ beliefs, then compare the resulting agents with baseline models. The video includes a VITURE sponsorship. The reported win-rate gains apply to the researchers’ simulated settings; they do not establish reliable lie detection or interrogation of people.
- 1A simulated hidden-role gameCrewmates communicate and vote while an imposter tries to remain hidden in a custom grid environment.
- 2Why final reward is sparseAn individual can vote correctly and still lose, making a final outcome a weak signal for each conversational contribution.
- 3Listening and speakingThe method combines imposter prediction with a reward for changes in teammates’ belief about the known hidden role.
- 4A bounded experimental resultThe full method achieved approximately twice the RL-only win rate in the paper’s base environment.
- 5No real-world lie-detection claimThe simulation does not establish reliable interrogation or truth detection involving people.
ポイント
- The study uses a custom 2D hidden-role environment inspired by Among Us, rather than testing the commercial game.
- A final win or loss is a sparse and noisy signal for judging individual messages.
- A listening loss predicts the known imposter, while a speaking reward tracks how messages change teammates’ belief in that identity.
- The full method doubled the RL-only baseline win rate in the reported base environment, not in every setting.
- No human gameplay demonstrations were required for this game-specific training, but the base language model had prior language pretraining.
- The study does not validate a real-world lie detector or prove human-like theory of mind.
チャプターごとに整えた全文を読む
The hidden-role communication problem
Berman introduces the Stanford research and explains the simulated social-deduction setting. Final game outcomes provide only sparse feedback on individual messages.
Stanford researchers Bidipta Sarkar, Warren Xia, C. Karen Liu and Dorsa Sadigh studied how language-model agents can communicate in a social-deduction game. In this February 2025 video I explain their preprint and why I find its reward design interesting. The experiment uses a simplified game inspired by Among Us; it does not demonstrate reliable lie detection or interrogation of real people.
In the game's hidden-role setup, most players are crewmates and an informed minority are imposters. Crewmates try to complete tasks and identify imposters, while imposters try to eliminate them without being voted out. After a body is reported, players discuss their observations and vote. The paper implements its own 2D grid and discussion environment rather than demonstrating agents controlling the commercial game itself.
A witness can say they saw one player eliminate another, but other players must judge the statement in the context of their partial observations. An imposter can mislead or shift blame. The problem is cooperative and adversarial at the same time: a crewmate's words should help teammates identify the hidden role while the opponent tries to derail them.
The paper examines multi-agent reinforcement learning, where agents learn through interactions and rewards. A final win or loss alone is a sparse signal for each statement: a player can vote correctly and still lose, or vote incorrectly and still win if teammates make the right choice. That makes it hard to tell which communication helped.
Listening, speaking and reward
The researchers use the known game state to train imposter prediction and reward useful changes in teammate beliefs. The game-specific training does not need human demonstrations.
The authors add two signals grounded in the simulated environment's known imposter identity. For listening, they train a crewmate to predict the true imposter from its observations and the discussion. This is an auxiliary prediction loss, rather than merely another end-of-game reward.
For speaking, the method rewards a message according to how it changes other living crewmates' belief in the true imposter. The environment supplies the ground truth during training; an individual player does not automatically know it during the game. Rewarding the belief shift encourages useful communication, although influence on a model's belief is not a general test of whether a real person's statement is true.
The researchers observe behaviors such as direct accusations and references to evidence, and use iterated self-play against earlier opponent policies. They report that this training does not require human gameplay demonstrations. The base language model was nevertheless pretrained on human language data, so the work should not be described as learning language without human data.
VITURE sponsored a separate segment of this video promoting its XR glasses. The research discussion that follows is about agent communication in the simulated game, not an evaluation of the sponsored hardware.
The authors' key observation is that win/loss feedback may not assign credit to a useful contribution in a conversation. A denser signal based on changes in teammates' belief is available because the environment records the hidden role. I am interested in whether similarly grounded intermediate signals could be designed for other tasks, but that requires a reliable source of ground truth.
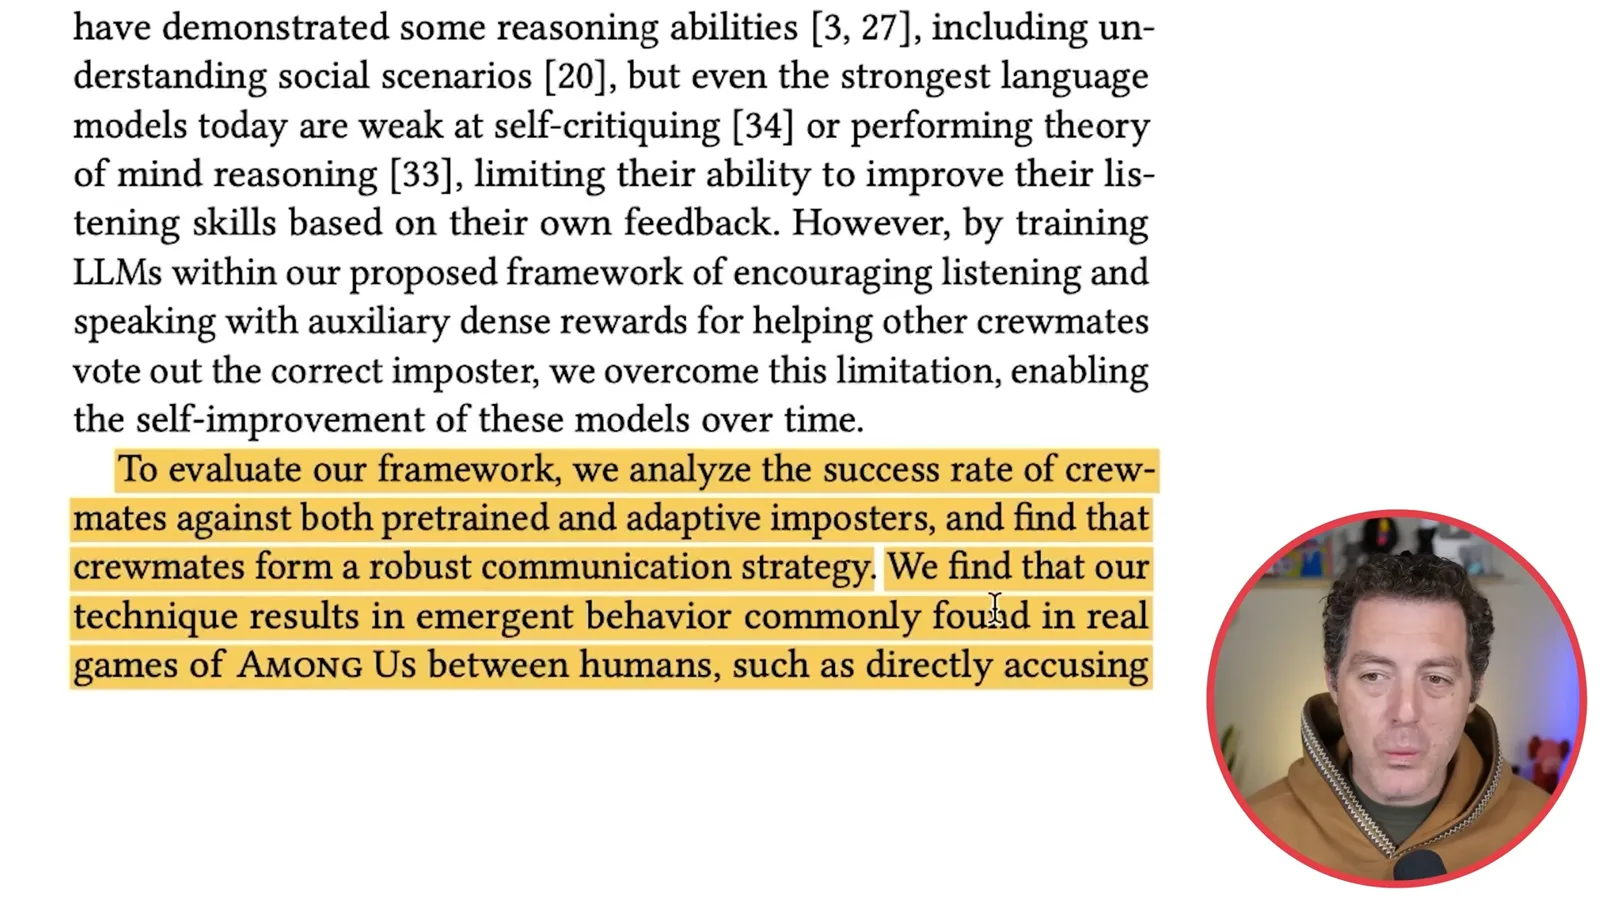
Related communication and self-play
Berman compares the setting with reference games and describes iterated self-play. These analogies do not establish human-like reasoning or general transfer.
The paper contrasts its setting with a reference game, where a speaker knows which item must be identified and describes it to a listener. In social deduction, crewmates have only partial information and all need to both speak and listen. I mention theory of mind as a way humans interpret others' beliefs; the game results do not prove the agents possess human-like mental-state understanding.
A correct individual vote can still accompany a team loss, and an incorrect one can be outweighed by teammates' votes. The researchers therefore use the known role during training to make the listener's imposter prediction and the speaker's effect on others more informative than final outcome alone.
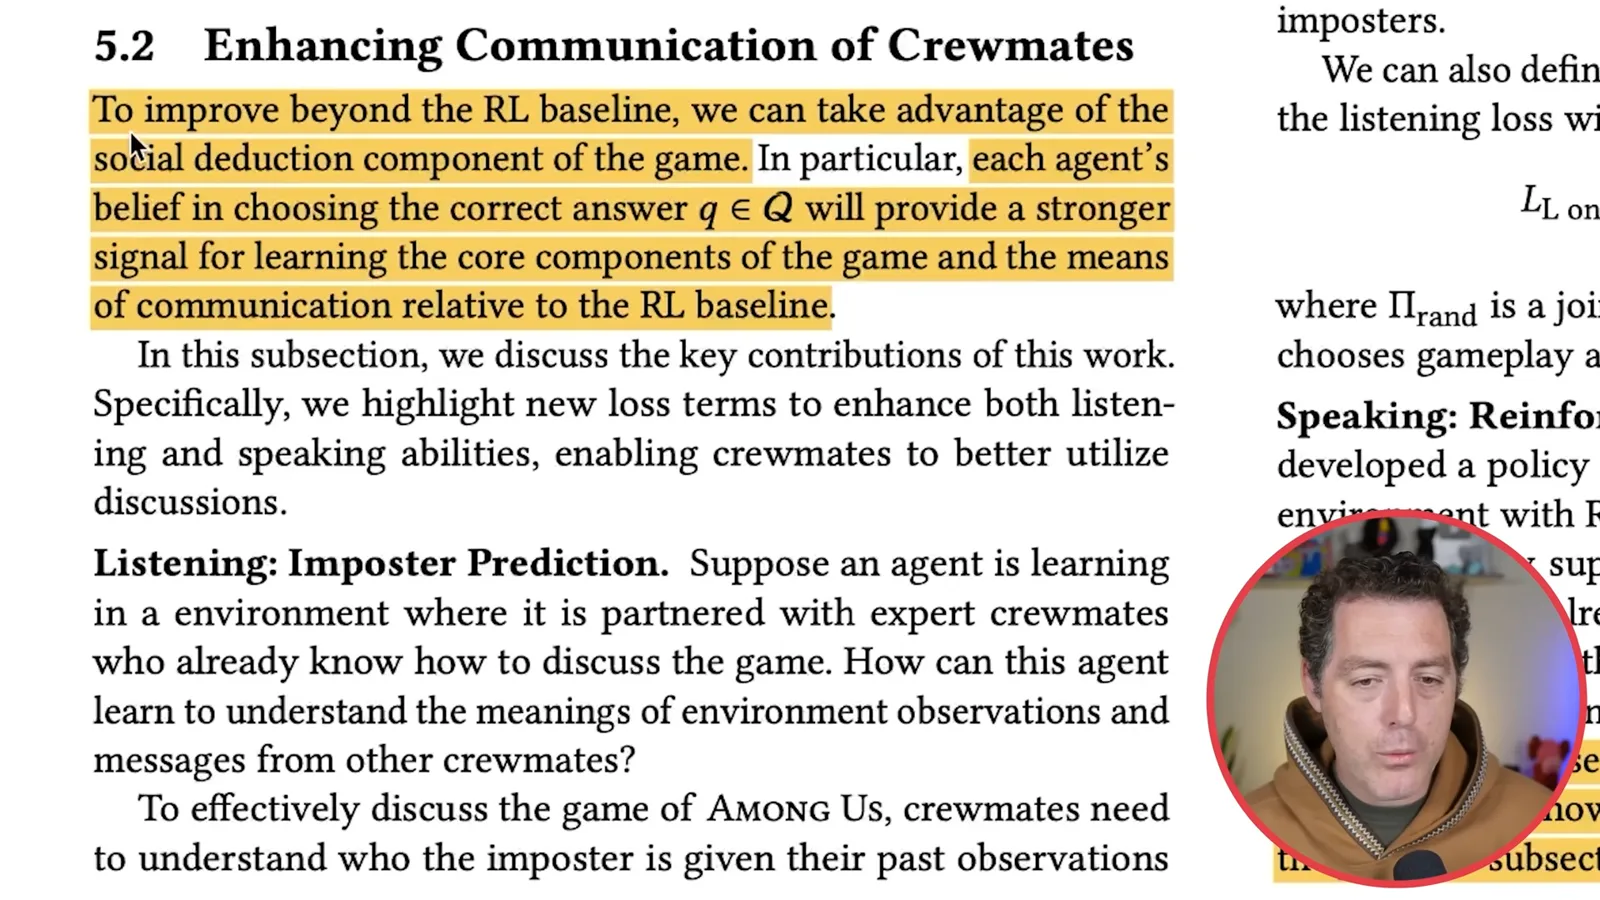
I am excited by the fact that the game-specific training does not require annotated human demonstrations. It would be too broad to conclude that reinforcement learning is the only method needed for every task: tasks without obvious ground truth require different reward design, and story quality can be assessed through human feedback or other imperfect signals.
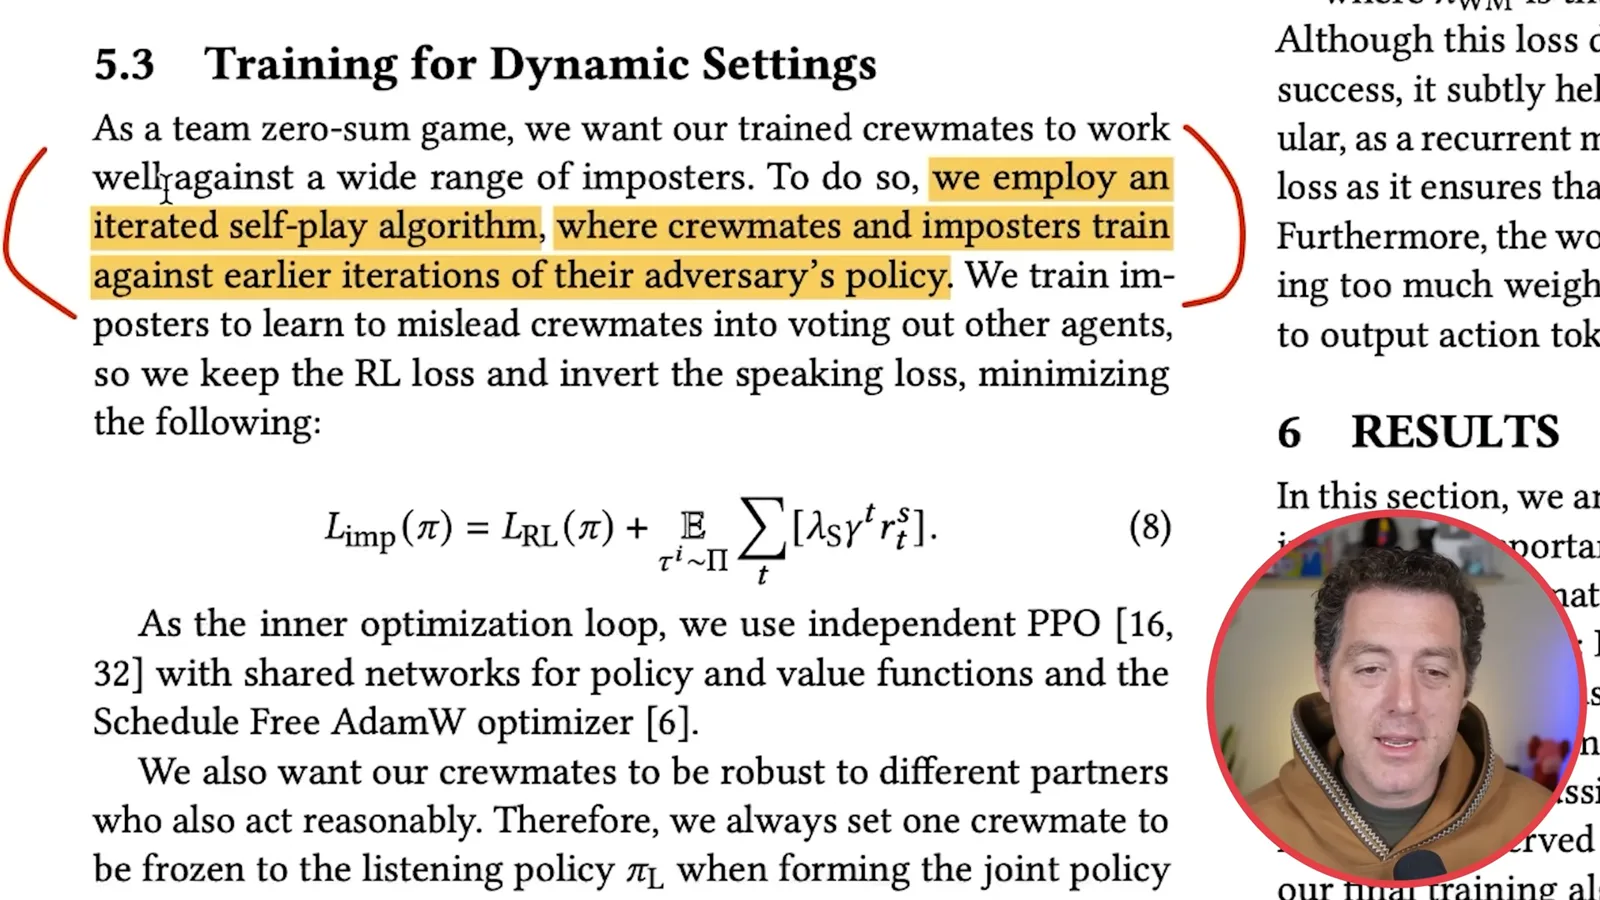
The paper trains agents against prior iterations of opposing policies. This iterated self-play can create changing challenges as both sides improve, although it is not identical in every detail to the procedures used in AlphaGo or other language-model projects. The analogy illustrates an approach, not a universal recipe or cost claim.
Results and limits
The paper compares model and training variants in several simulated settings. Berman’s proposed real-world applications go beyond what the study validates.
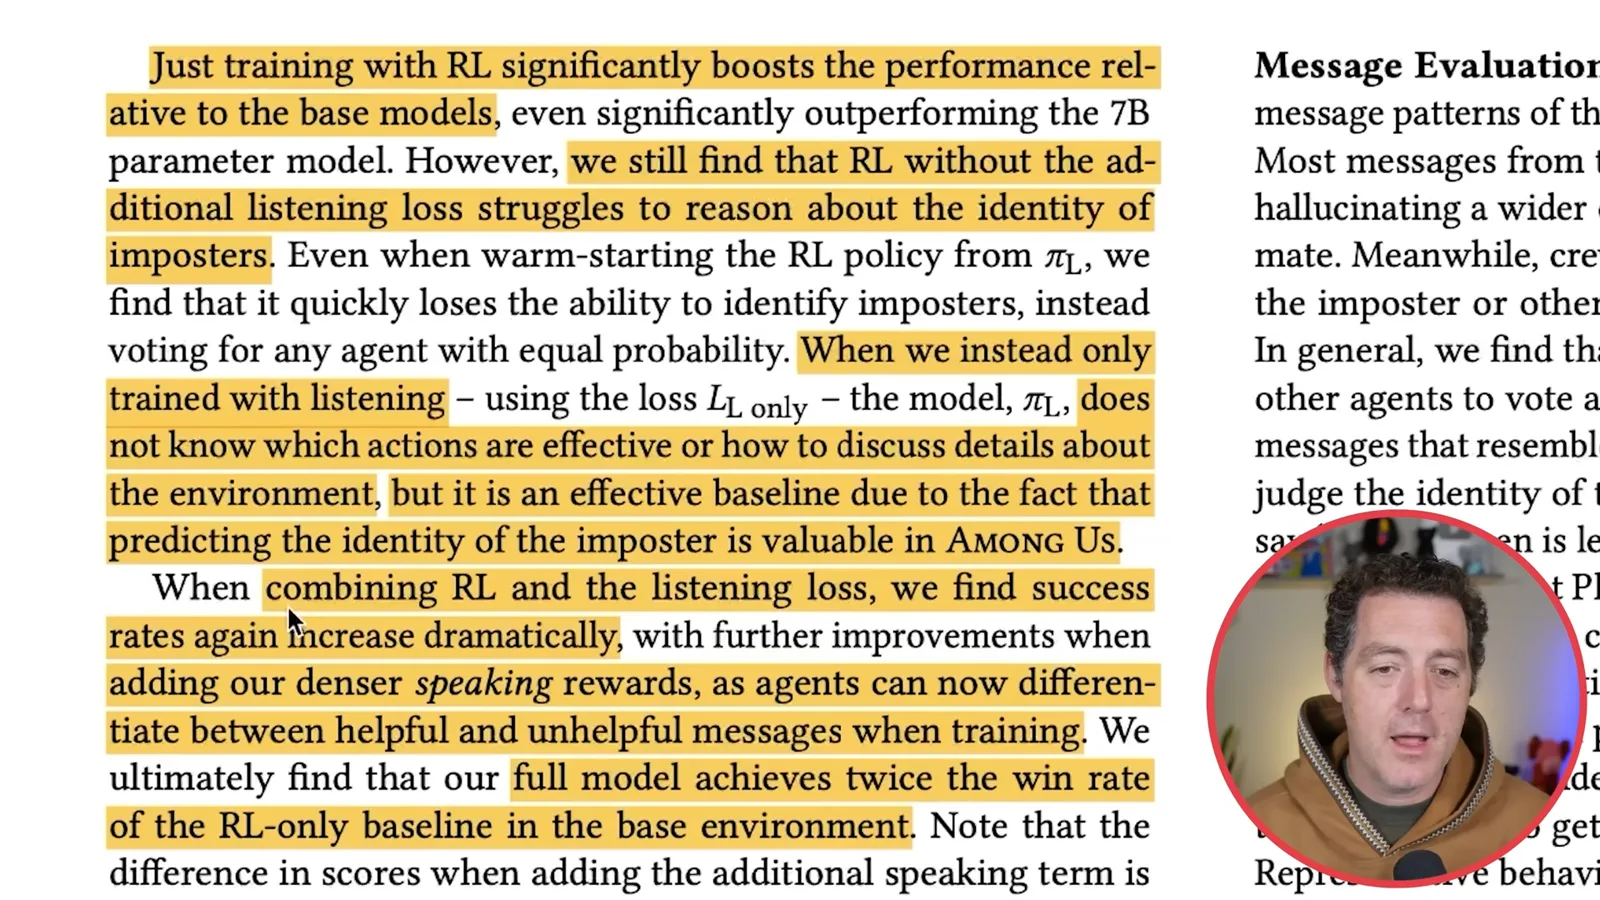
The results compare different grid shapes, task counts and numbers of players, alongside base models and several training variants. In the base environment, the full method achieved about twice the win rate of the reinforcement-learning-only baseline; the authors also compared against a larger 7B-parameter base model. The ratios are specific to their experiment, opponents and evaluation conditions.
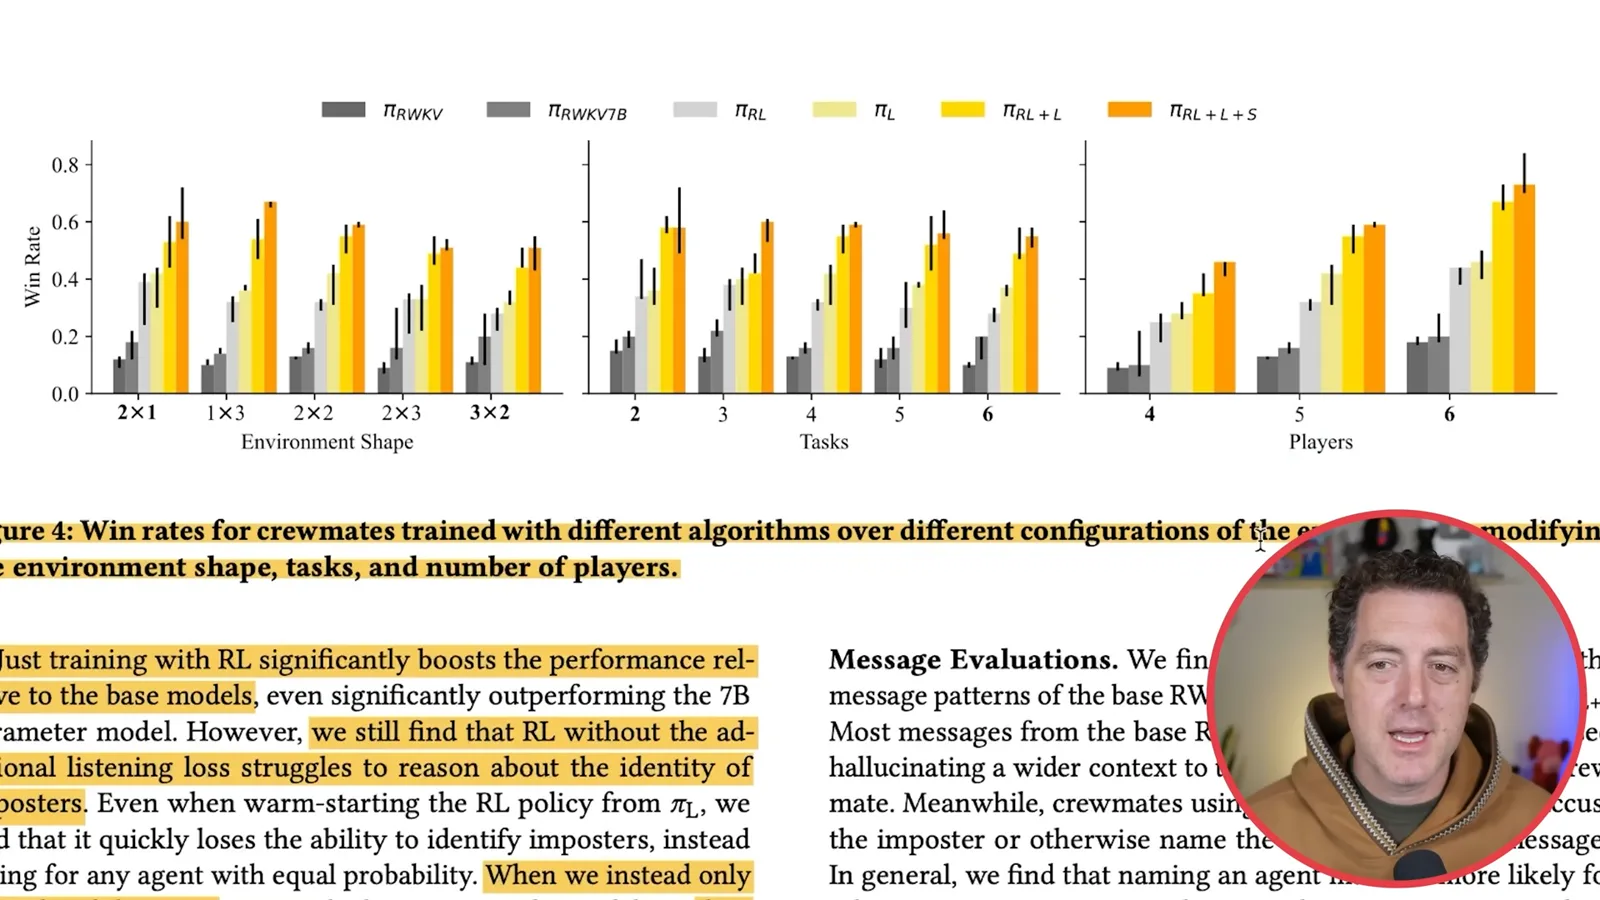
The paper uses a 1.5B-parameter RWKV base for the main experiments. Standard RL improves over the base model but struggles to identify the imposter without the listening loss; listening-only training helps identification but does not learn the full set of useful actions. Combining RL and listening improves the results, with a further relatively small gain from the speaking reward in the reported comparison.
The authors test different layouts and adversarially trained imposters, reporting that the trained crewmates remain effective within their simulated settings. Their self-play results show convergence over a few iterations for the reported runs. This is evidence about those game conditions, not proof of robustness to all adversaries or general human interaction.
My takeaway is that identifying a task-specific, verifiable reward can make reinforcement learning more informative than a single win/loss signal. I speculate about applications to interrogation and detecting lies, but this paper does not validate a real-world lie detector, assess human subjects or justify using such a system for high-stakes judgments. Broader transfer, safety and reliability would require separate evidence.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.