30 秒でわかる
In this May 2023 video, Matthew Berman reviews Voyager, a Minecraft research agent built by a team including NVIDIA and university researchers. He explains its automatic curriculum, skill library and feedback loop, then discusses comparisons with adapted baselines and limitations. The system queries GPT-4 without fine-tuning its weights; its performance figures belong to the study’s specific experiments.
- 1Three parts of VoyagerThe system combines an automatic curriculum, a reusable code library and iterative feedback. Its learning resides in the surrounding agent system, not GPT-4 weight updates.
- 2Choosing the next taskThe curriculum uses inventory, environment and prior successes and failures to propose challenges suited to the agent’s progress.
- 3Storing executable skillsSkill descriptions are embedded for retrieval, with associated code reused and composed for later tasks.
- 4Evaluation resultsThe authors report 63 unique items in 160 prompting iterations and 2.3× longer traversal than their adapted baselines. These are study-specific results.
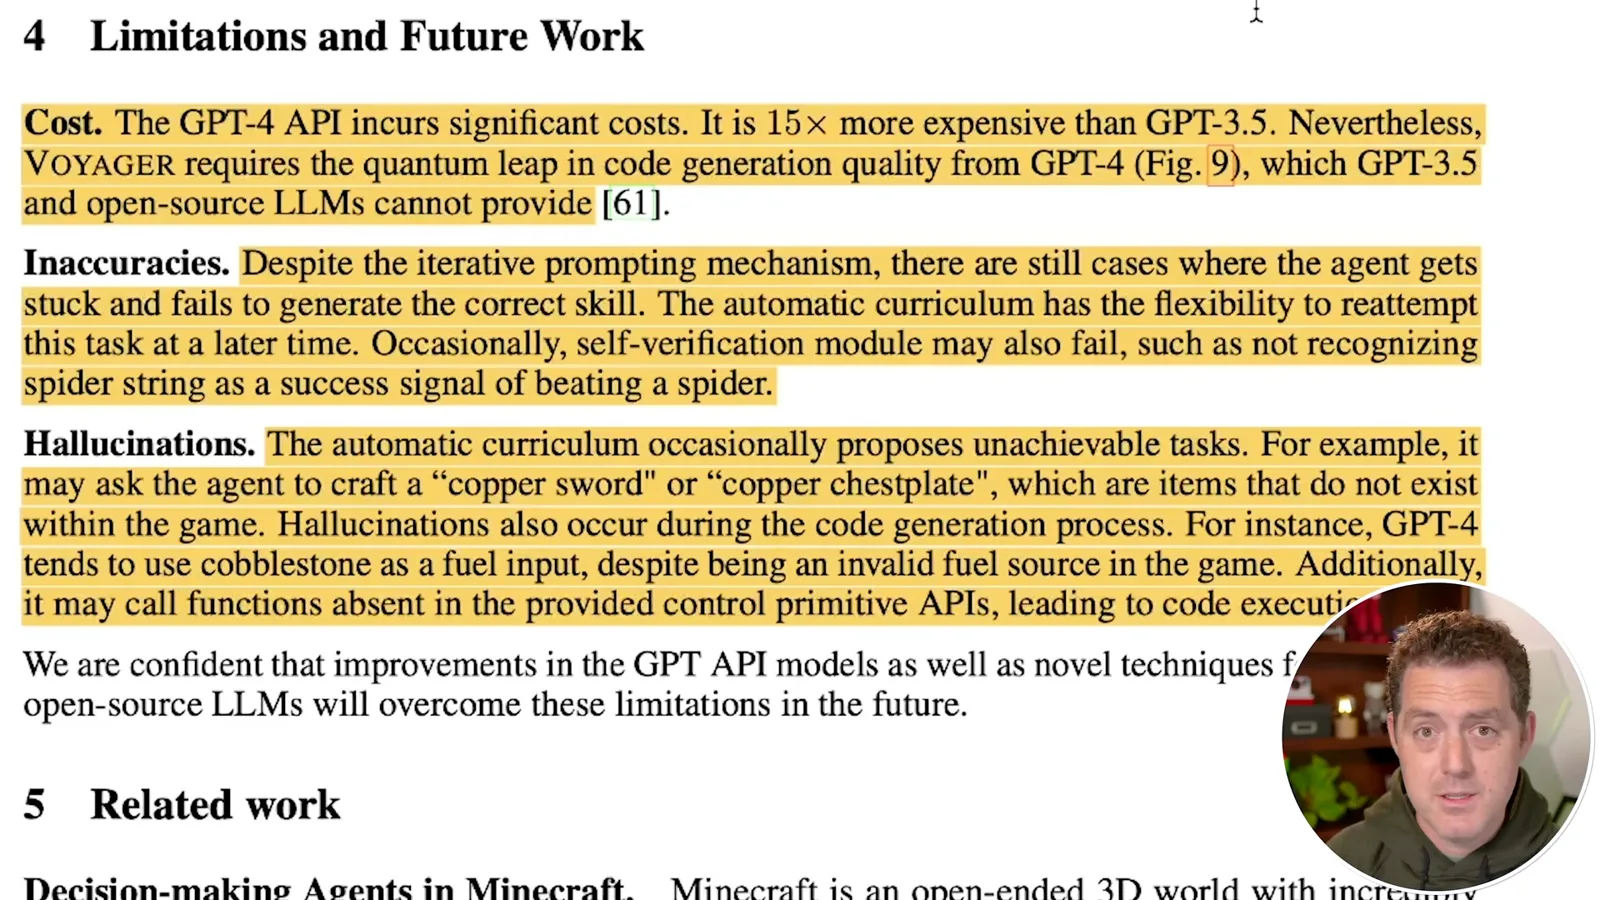
- 5Cost and reliabilityThe paper reports expensive API calls, failed skills and hallucinated items or functions; self-verification can also fail.
ポイント
- Voyager proposes tasks, generates code and accumulates reusable skills without fine-tuning GPT-4.
- The curriculum considers the agent’s state and history, while a skill library retrieves relevant executable programs.
- Environment feedback, execution errors and model-based self-verification inform iterative retries, but the verifier can be wrong.
- The reported exploration and tech-tree gains compare specific adapted baselines in a small Minecraft study, with speed measured in prompting iterations.
- API cost, incorrect skills and hallucinated game objects or functions remain limitations.
チャプターごとに整えた全文を読む
Voyager and its automatic curriculum
Berman introduces the Minecraft agent and its three components. He discusses the curriculum and distinguishes MineDojo’s dataset from unverified claims about GPT-4 training data.
The 2023 Voyager paper explores how a GPT-4-powered agent can pursue tasks, gather resources and build skills in Minecraft. The researchers include contributors from NVIDIA, Caltech, UT Austin, Stanford and ASU. I examine the system, its experimental comparisons and the limitations that remain.
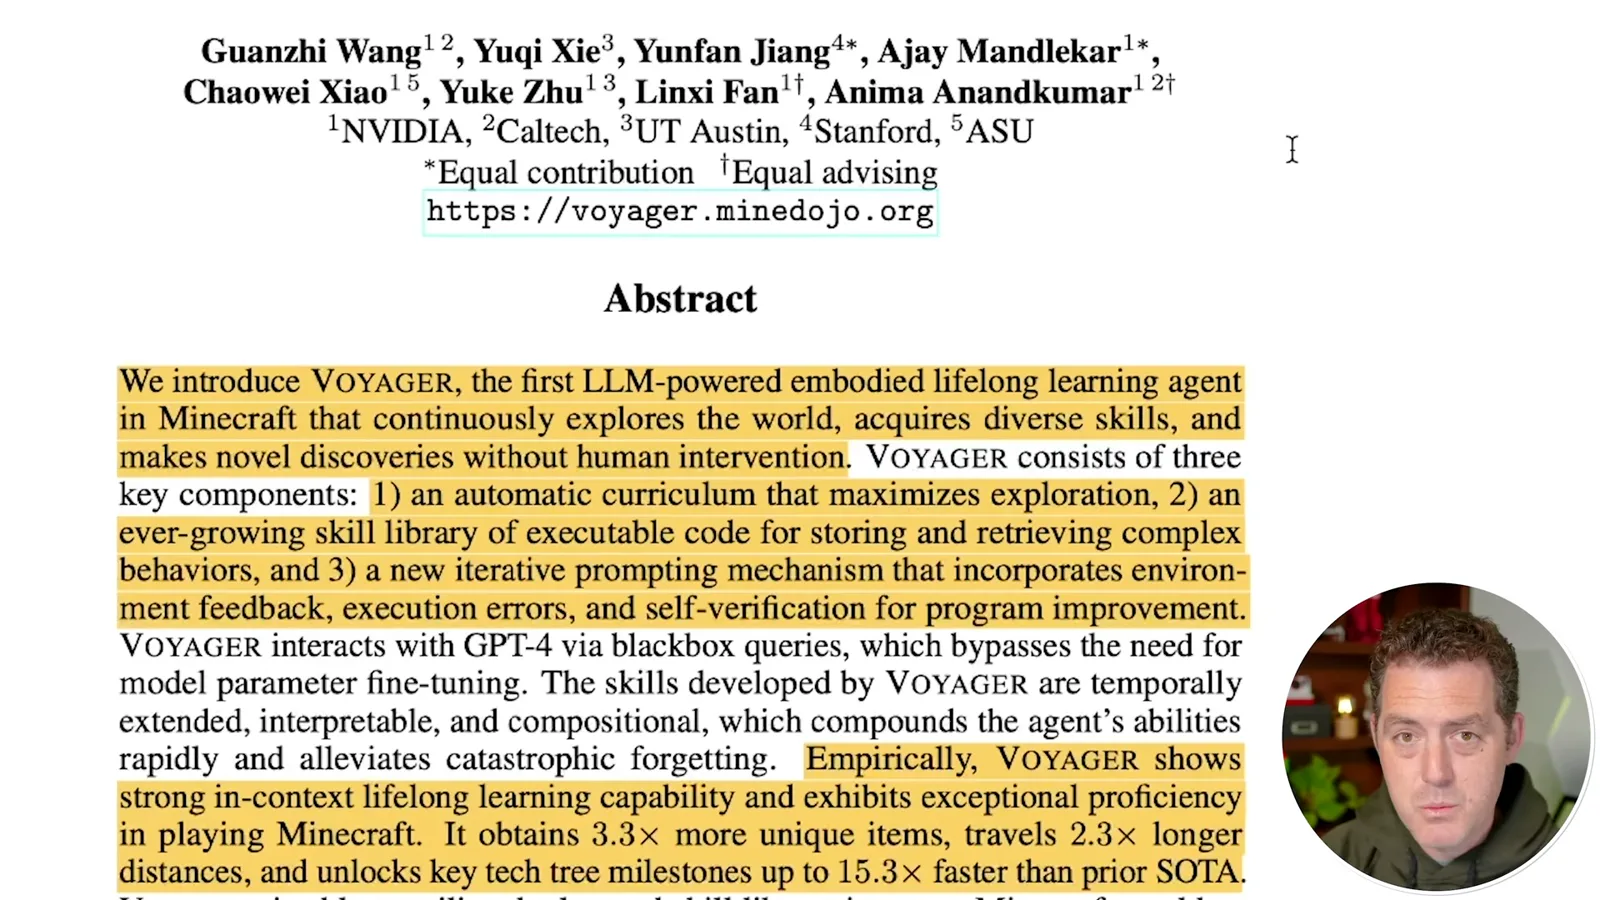
Voyager combines an automatic curriculum, a growing library of executable skills and iterative prompting. The agent can propose and carry out tasks without a person selecting each next step during a run, but its environment, prompts, APIs and system design are provided by researchers. It queries GPT-4 as a black box rather than updating the model’s weights.
I point to the earlier MineDojo project’s collection of Minecraft videos, wiki pages and Reddit discussions as an illustration of the game’s available knowledge. Those dataset counts do not establish that GPT-4 was trained on that specific collection. Voyager uses pretrained model knowledge and, as the paper describes, wiki-based context for some questions.
The curriculum uses the agent’s current state and exploration progress to propose tasks that are diverse but not too difficult for its current resources. The prompt includes inventory, equipment, nearby entities, health, hunger, position and previously completed or failed tasks. GPT-3.5 helps generate questions answered with a wiki knowledge base to add context.
A reusable skill library and feedback
The system indexes code by skill description and improves attempts with environment feedback, execution errors and self-verification. GPT-4 is queried without fine-tuning.
The skill library keeps successful behaviors as executable programs. A description is embedded for retrieval, and the corresponding code can be reused when the agent faces a related task. By combining previously stored programs, Voyager can build more complicated behaviors rather than starting every action from scratch.
The third component is an iterative prompting loop. GPT-4 generates code to use the game’s control APIs; the system executes it and returns environmental feedback, program errors and a separate GPT-4 self-verification judgment. The verifier can decide that the task failed and offer a critique, but model-based verification is not infallible.
A failure might report that the agent lacks ingredients for a recipe, prompting a revised plan to gather them. The paper gives the system up to four rounds of code generation for a task; if it remains stuck, the curriculum can propose another one. This process improves the program and stored skill library, not GPT-4’s parameters.
Experiments and limitations
Berman reviews the study’s adapted baselines, exploration and tech-tree results. He closes with the costs, failures and hallucinations reported by the authors.
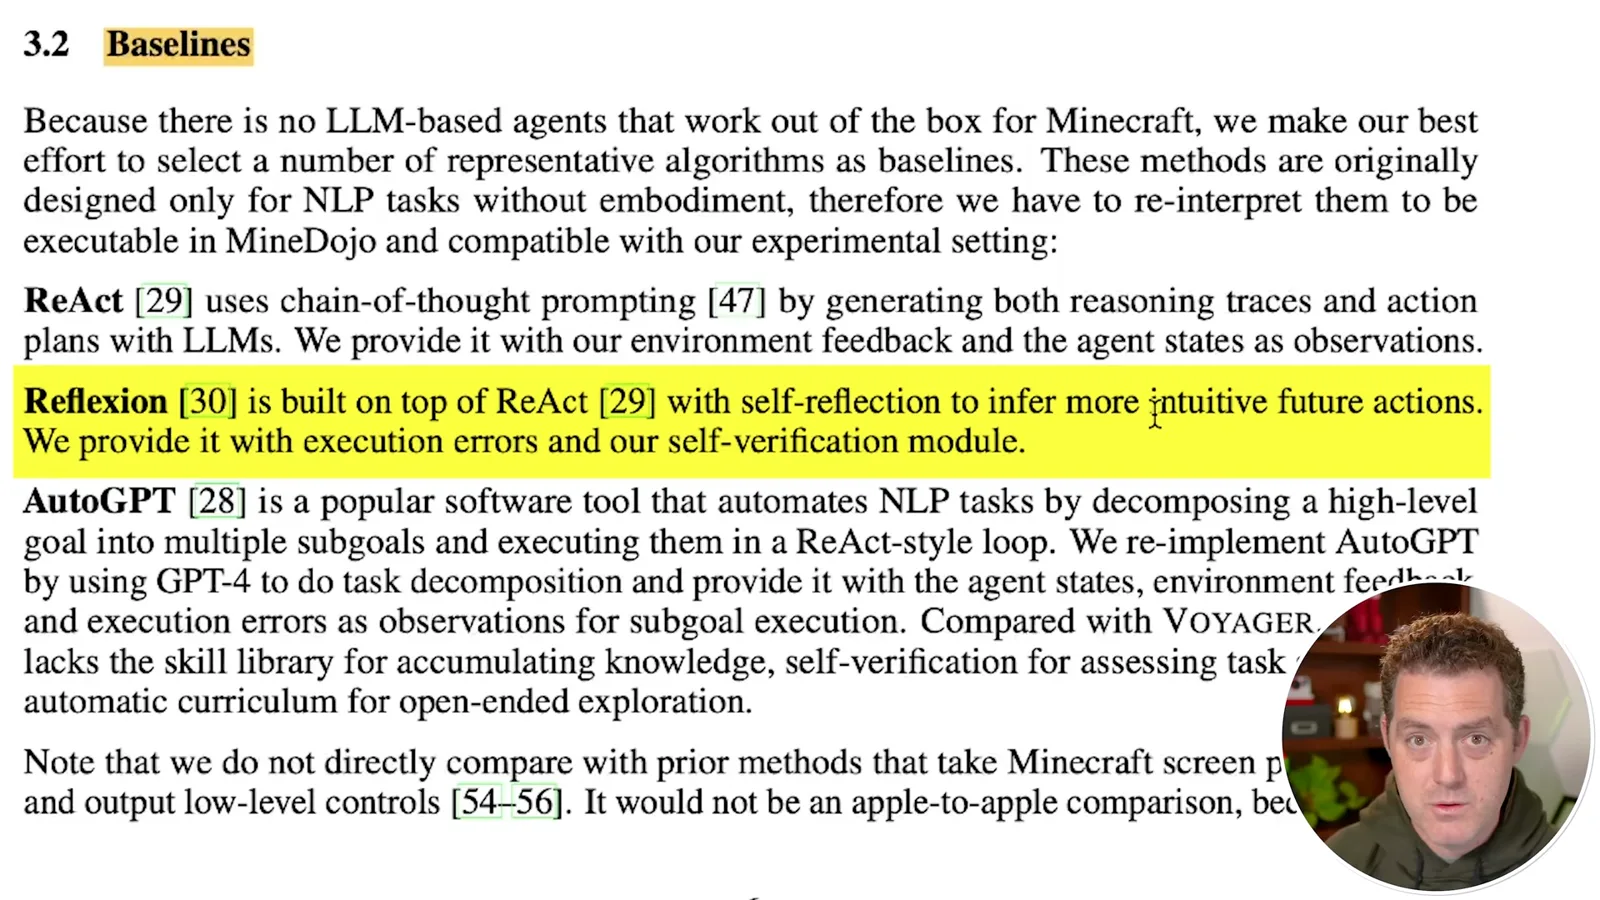
The researchers compare Voyager with adaptations of ReAct, Reflexion and AutoGPT for the Minecraft setting. These baselines were reinterpreted to work with the environment, so the findings concern the particular implementations and experimental setup rather than every possible version of those approaches.
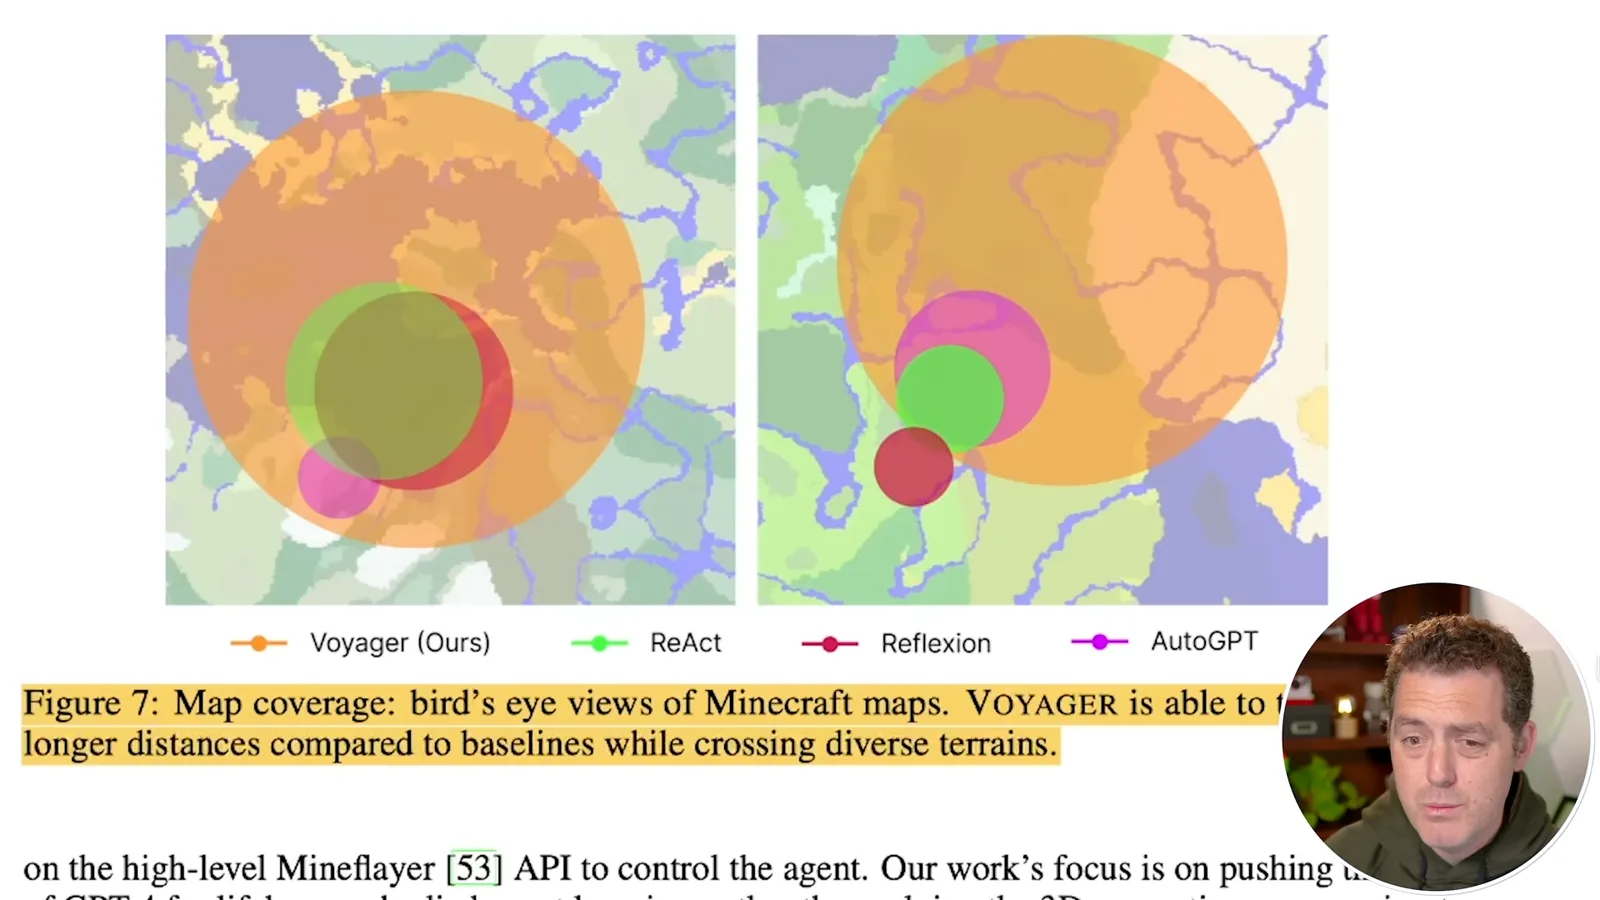
In the reported trials, Voyager traveled 2.3 times farther than the compared baselines and discovered 63 distinct items within 160 prompting iterations, about 3.3 times as many as the counterparts. The map figure shows that the baseline agents remained closer to their starting areas in the depicted runs.
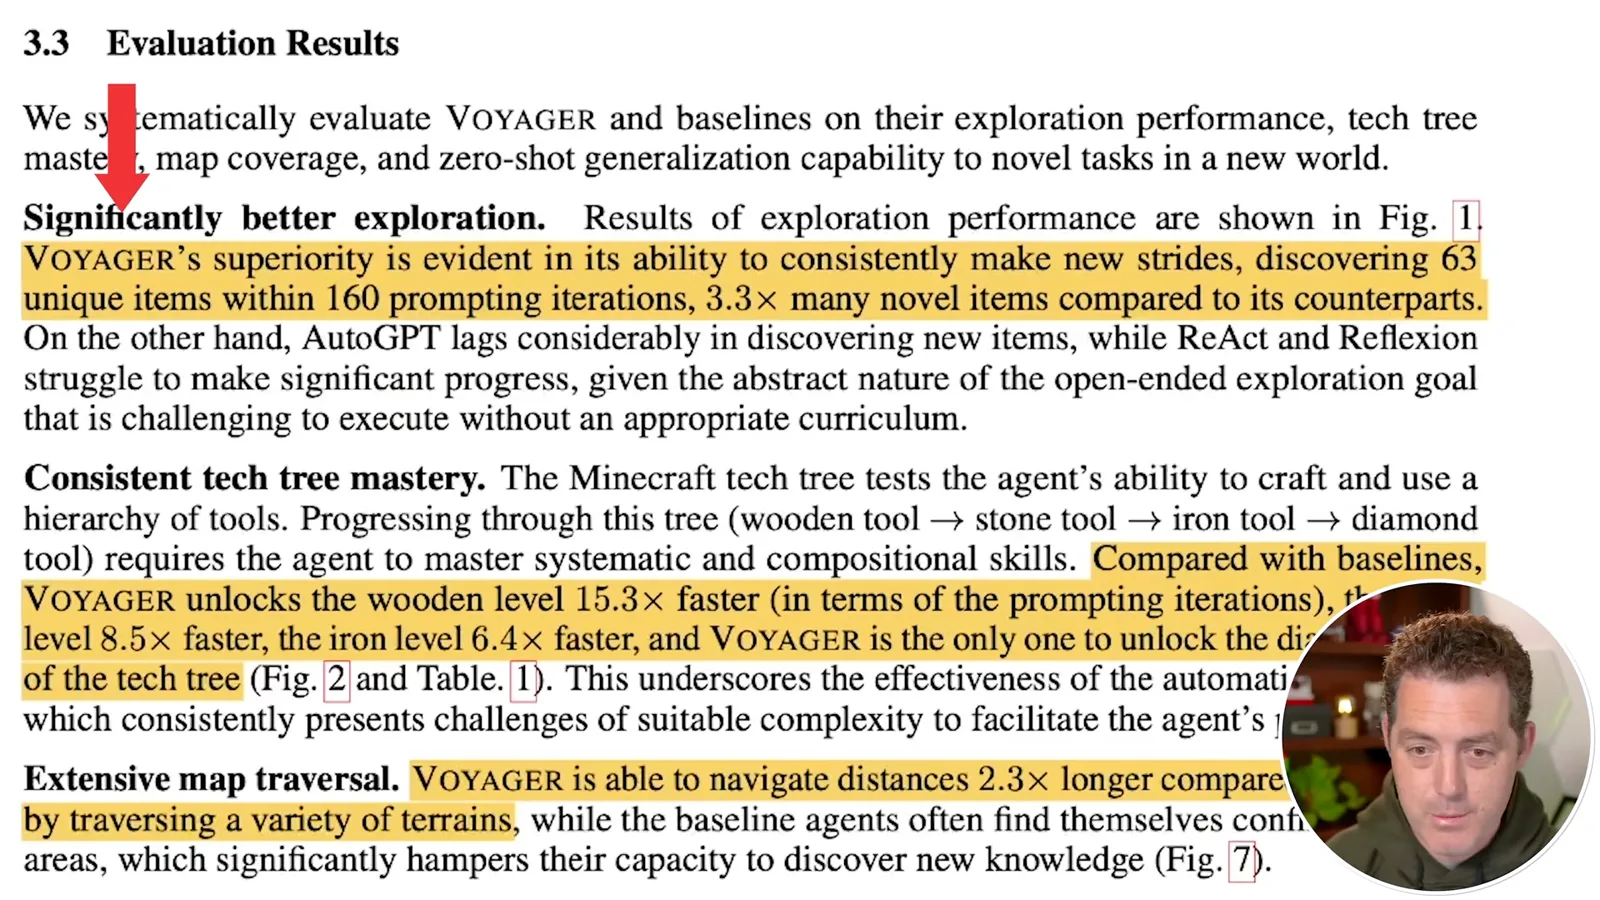
The paper reports wooden, stone and iron tool milestones reached 15.3, 8.5 and 6.4 times faster respectively in terms of prompting iterations, not necessarily elapsed time. Voyager alone reached the diamond level among the tested methods. The study reports three runs for the tech-tree table, so the ratios are specific to this evaluation.
The authors also evaluate transfer to unseen tasks in a newly initialized world after clearing the agent’s inventory: the saved library helped Voyager solve the tested tasks. This is evidence of transfer in that experiment, not proof of general competence across games or arbitrary tasks.
The limitations matter. GPT-4 API calls carried substantial costs at the time, and the agent could still get stuck or fail to produce a correct skill. Its self-verifier could also make mistakes, so an automatic pass is not equivalent to a guarantee of success.
Hallucinated tasks and code are another problem: the curriculum might ask for a nonexistent copper sword or chestplate, and generated programs can call unavailable functions. The authors made code and prompts available, but running the research system requires its dependencies and model access. I am excited by the possibility of autonomous characters in games, while this is a research demonstration rather than a finished game feature.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.