30 秒でわかる
Matthew Berman presents AnythingLLM and its Community Hub in a November 2024 NVIDIA partnership. He describes running local models and agents on RTX-equipped PCs and sharing prompts, slash commands and agent skills. Local inference can limit data sent to a model provider, but external services and agent skills may still transmit information or execute code.
- 1Local agents on RTXBerman describes AnythingLLM running locally on compatible NVIDIA RTX PCs; performance depends on hardware, model and setup.
- 2Community HubThe hub offers shared system prompts, slash commands and agent skills for a range of workflows.
- 3Integrations and privacyExamples include email, calendars, smart homes and APIs; external integrations may send data beyond the local device.
ポイント
- AnythingLLM supports local model and agent workflows, with RTX acceleration available on compatible NVIDIA hardware.
- The Community Hub shares system prompts, slash commands and agent skills for different tasks.
- Local execution alone does not guarantee privacy when an agent uses cloud services, external APIs or downloaded skills.
- The short is an NVIDIA partnership; the claim that RTX is fastest is promotional rather than a comparative benchmark.
チャプターごとに整えた全文を読む
Local agents and the Community Hub
Berman introduces AnythingLLM, RTX acceleration and shared agent tools. He discloses the NVIDIA partnership and describes possible integrations.
NVIDIA partnered with me on this video about AnythingLLM and local AI agents on RTX-equipped PCs. AnythingLLM is an open-source application for working with models and agents locally. I say the agents run fastest on RTX, but that is a promotional performance claim rather than a controlled comparison across hardware and workloads ([NVIDIA](https://blogs.nvidia.com/blog/ai-decoded-agents-anythingllm-rtx-ai/)).
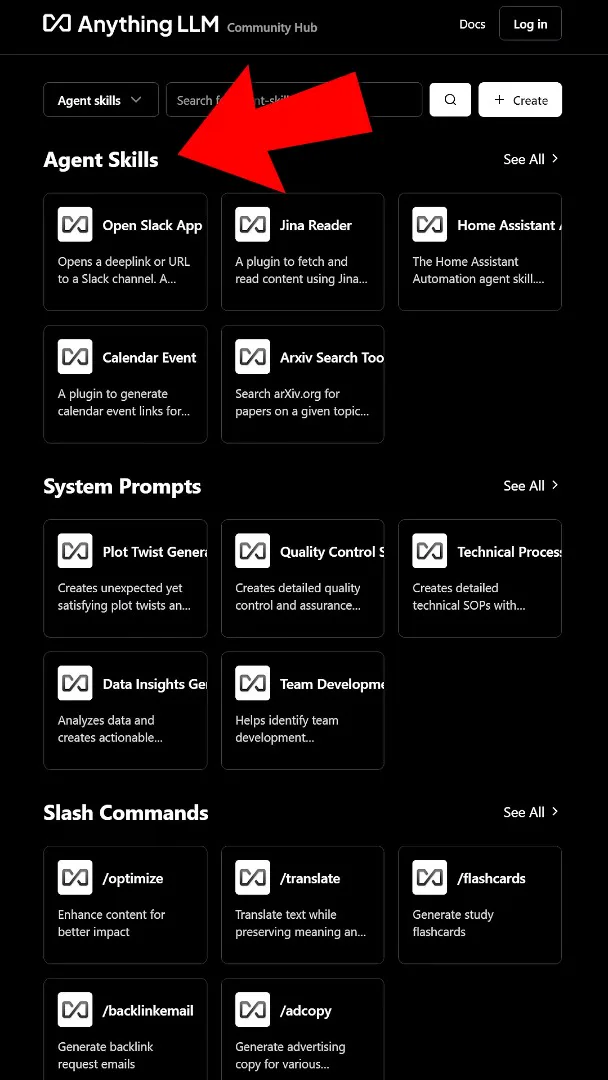
AnythingLLM’s Community Hub lets users share system prompts, explore slash commands and exchange agent skills. Examples I mention include Outlook email, calendar and smart-home assistants, plus integrations with custom APIs and services. Availability and capabilities depend on the specific skill and configuration.
I suggest that running locally protects privacy. Local model inference can reduce the information sent to an external model provider, but privacy is not automatic: email, web and API integrations can transmit data, and custom skills can execute code. AnythingLLM’s [documentation](https://docs.anythingllm.com/agent/custom/introduction) recommends trusting and testing skills before use. I thank NVIDIA for the partnership and point viewers to its AI Decoded article.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.