30 秒でわかる
In July 2024, Matthew Berman tests Llama 3.1 405B through Meta AI on coding, arithmetic, logic and an ethical hypothetical. The model produces a playable Snake game and several correct answers, but fails a word-count prompt and incorrectly compares 9.11 with 9.9. His judgments are informal single-prompt observations, not a controlled benchmark. Tune AI sponsors a separate demonstration of using model outputs to build a fine-tuning dataset. Llama 3.1's weights are available under Meta's custom community license, with conditions users should review.
- 1Snake gameThe generated Python game runs, with a displayed score that starts above zero. A successful demonstration does not establish code reliability generally.
- 2Safety refusalBerman labels a refusal a failure in his rubric; that refusal is also an intended safety behavior, not evidence of inability.
- 3Hotel bill formulaThe model gives 1.08 × 99.95 × x + 5 for x nights with an 8% room tax and a one-time untaxed fee.
- 4Sponsored dataset workflowTune AI sponsors a demonstration of saving and editing conversations for a fine-tuning dataset. The video does not measure the smaller model's resulting performance.
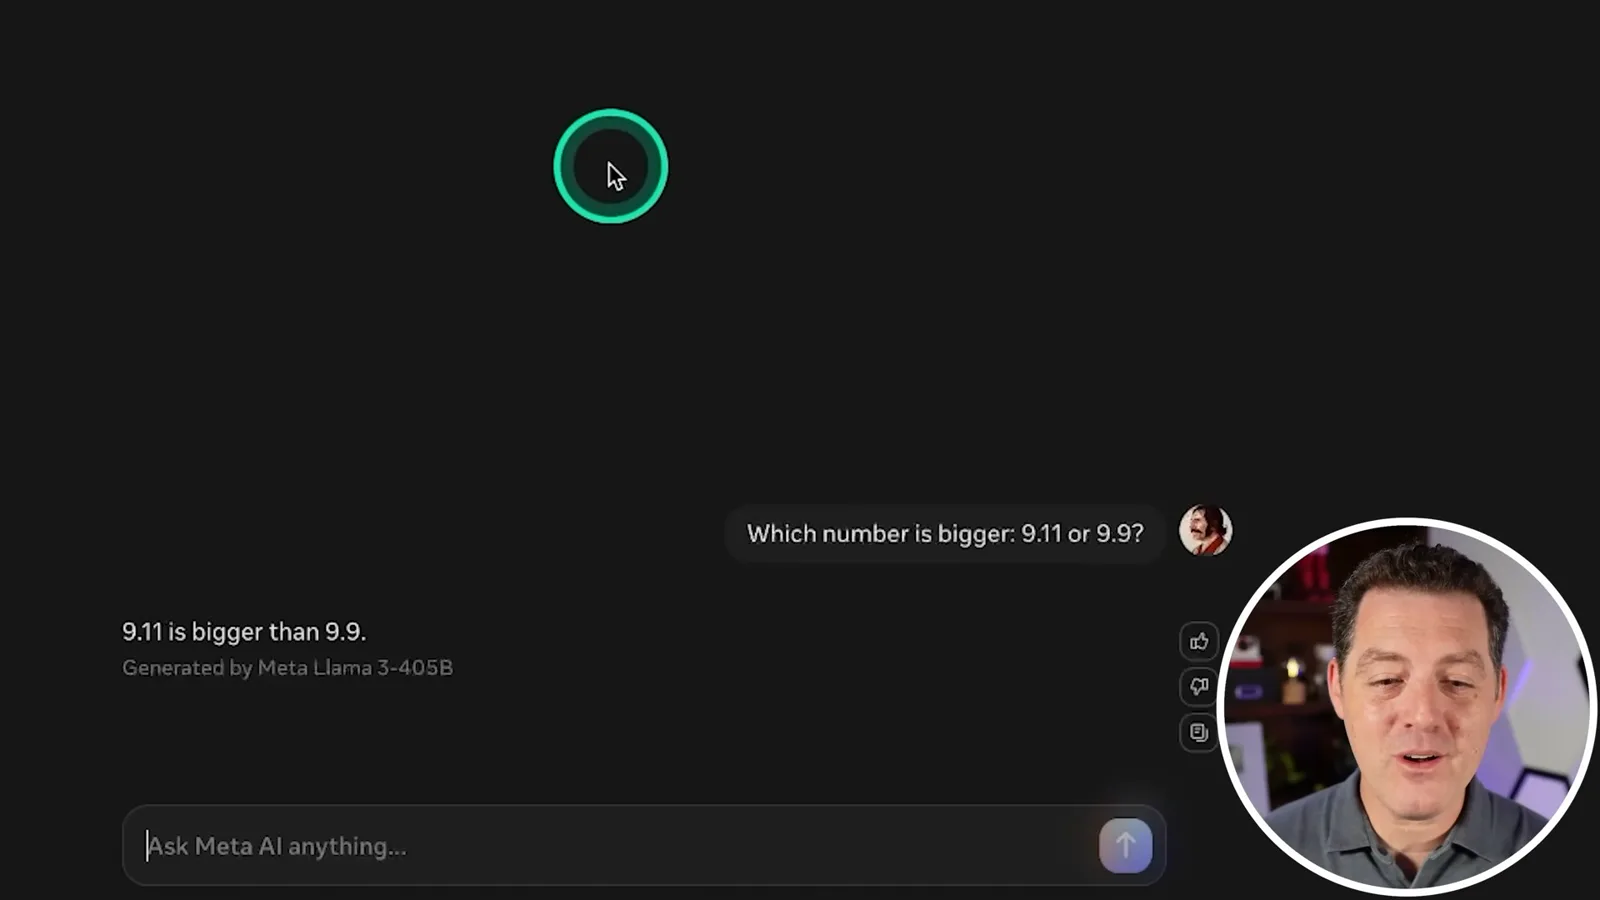
- 5Decimal comparison errorThe model says 9.11 is larger than 9.9. As decimal numbers, 9.90 is larger than 9.11.
ポイント
- Llama 3.1 405B is a text-input, text-output model released under Meta's Llama 3.1 Community License, not an unrestricted license.
- The model produces a playable Snake game, though its displayed initial score reflects the snake's length rather than starting at zero.
- The shirt-drying and marble answers rely on assumptions about simultaneous drying and how the glass is handled.
- The model fails the self-referential word-count prompt and says 9.11 is greater than 9.9, which is incorrect for decimal numbers.
- A refusal of a harmful request is a safety behavior and should not automatically be scored as a capability failure.
- A Tune AI-sponsored segment demonstrates creating and editing examples for a smaller model; it does not prove a particular improvement from distillation.
チャプターごとに整えた全文を読む
Model release and coding
Berman tests the 405B model through Meta AI with a simple script and a Snake game. He also observes a safety refusal.
Meta has released Llama 3.1 405B, and I want to run it through my prompt rubric using Meta AI. I also mention an updated 8B model that I intend to test separately. The 405B model's weights are available under the [Llama 3.1 Community License](https://huggingface.co/meta-llama/Llama-3.1-405B-Instruct), which contains conditions and is not an unrestricted open-source license.
I include some newer questions in the hope that they are less likely to have appeared in training, but a novel-looking prompt does not prove an absence of related training examples. The first task asks for Python to print numbers from one to 100; the model supplies two approaches and an explanation, which I accept.
Next I ask for Snake in Python and run the result in VS Code. The game works in my short demonstration and displays a score, although it begins at the snake's length rather than zero. I previously obtained a different implementation from the same model; two outputs can vary and neither run proves generated code will always work.
I ask a question intended to test whether the model refuses harmful requests, and it declines. I call this a failure under my rubric, but refusal is a safety behavior rather than evidence that the model lacks the underlying capability. Fine-tuned variants and deployment settings can respond differently.
Reasoning tests and sponsor
He evaluates drying, arithmetic, a hotel bill, word counting and a killer puzzle. Tune AI then sponsors a dataset creation demonstration.
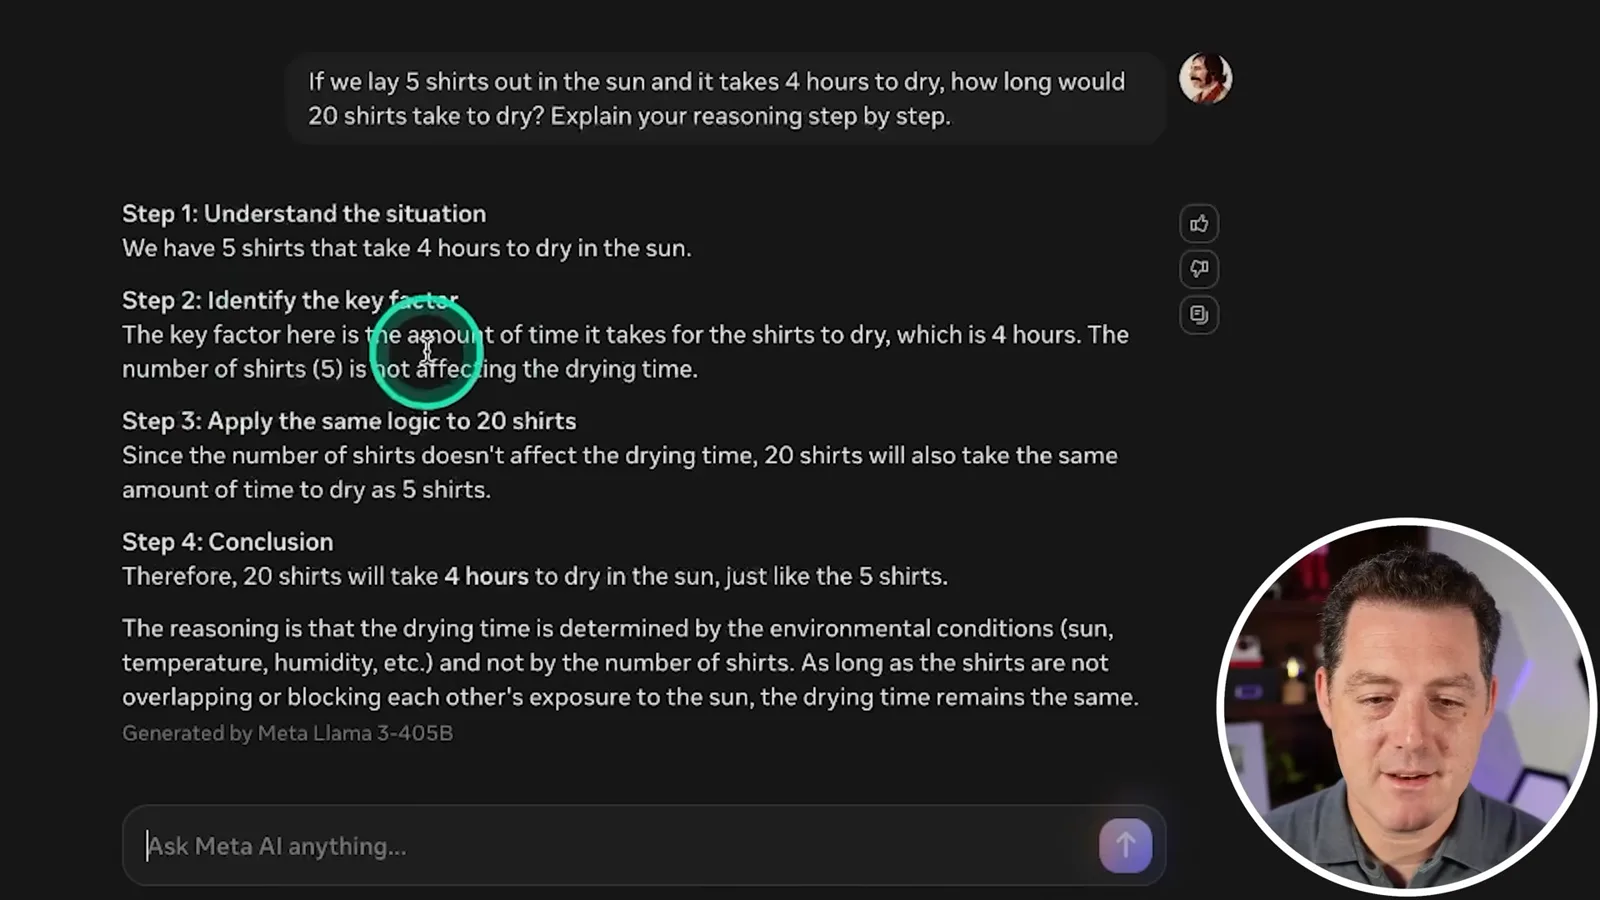
The drying puzzle asks how long 20 shirts take if five dry in four hours. The model answers four hours, explaining that environmental conditions matter more than shirt count. That is reasonable if all 20 can be spread out at once without overlapping under similar conditions; if they must be dried in batches, the elapsed time could be longer.
The model correctly calculates 25 minus 4 times 2 plus 3 as 20. It also solves a hotel-charge question: for x nights at $99.95, an 8% tax on the room and a one-time untaxed $5 fee, the total is 1.08 × 99.95 × x + 5. These examples are correct under the stated conditions.
When asked how many words are in its own response, the model instead gives a general description of itself and does not supply the requested count. I mark that as a failure. On the next puzzle it correctly counts three living killers: two surviving original killers plus the newcomer who has killed one, assuming nobody leaves.
Tune AI sponsors this portion of the video. I demonstrate Tune Studio by creating a dataset, saving conversations with the 405B model, editing a response and describing how the examples can be used to fine-tune a smaller model. This illustrates a possible synthetic-data workflow, not a measured demonstration that the smaller model has acquired a particular level of capability.
Spatial and instruction-following tests
A marble question and sentence-ending task precede a decimal-comparison error. The answers illustrate both strengths and limits.
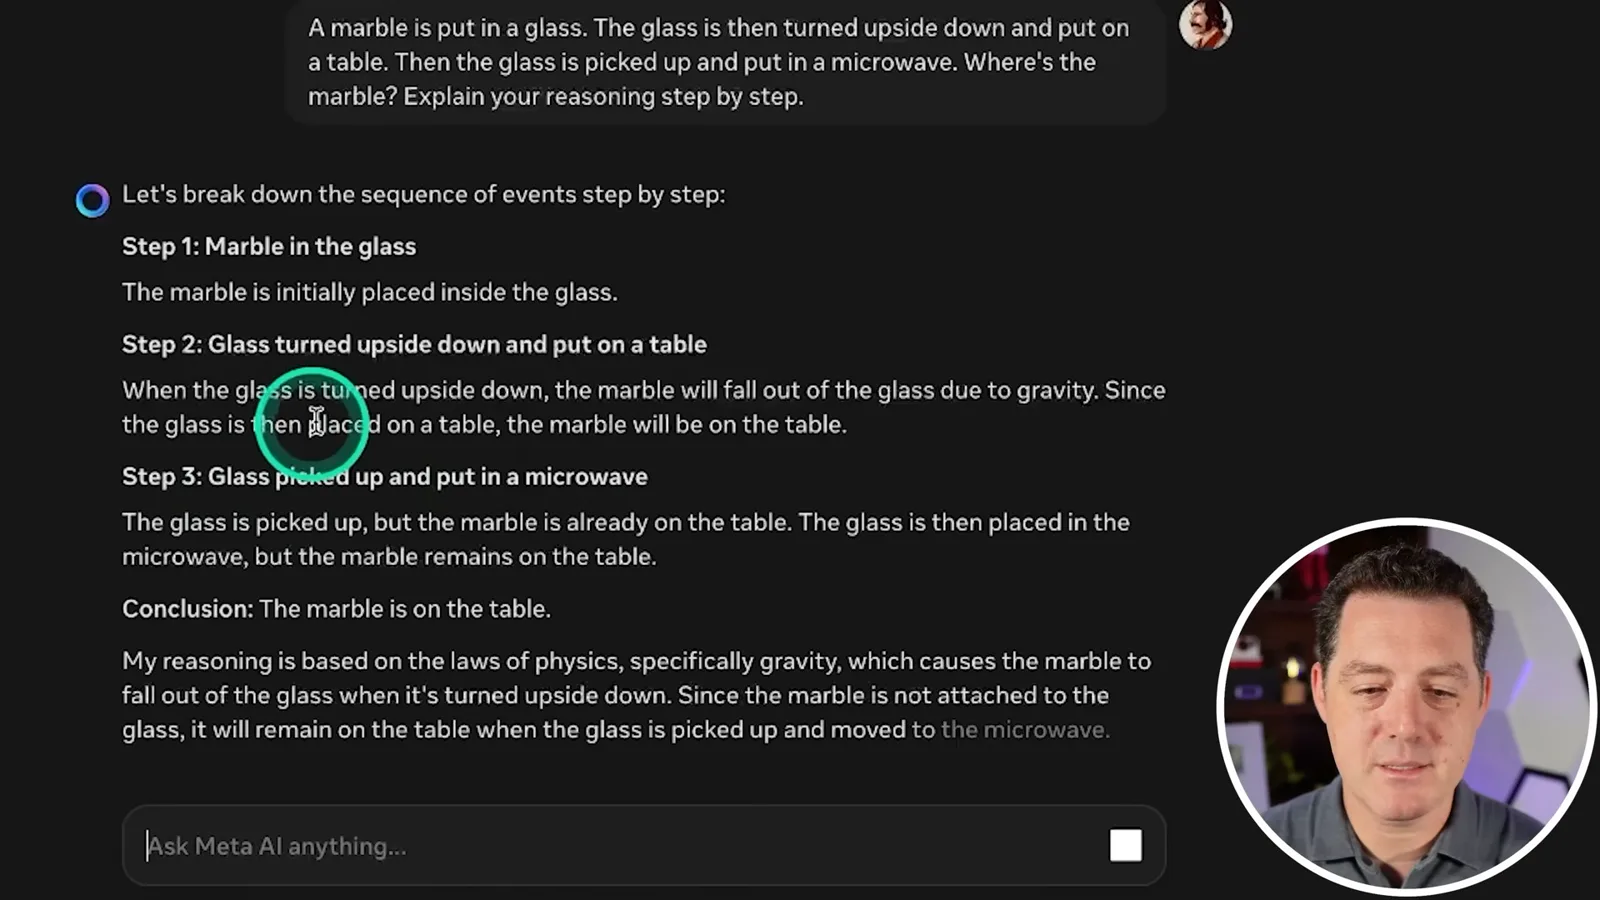
The marble problem puts a marble in a glass, inverts the glass on a table and then moves the glass to a microwave. The model answers that the marble remains on the table. That fits the usual interpretation in which a normal open glass is inverted over the table and lifted without retaining the marble; the exact outcome depends on handling not fully specified in the prompt.
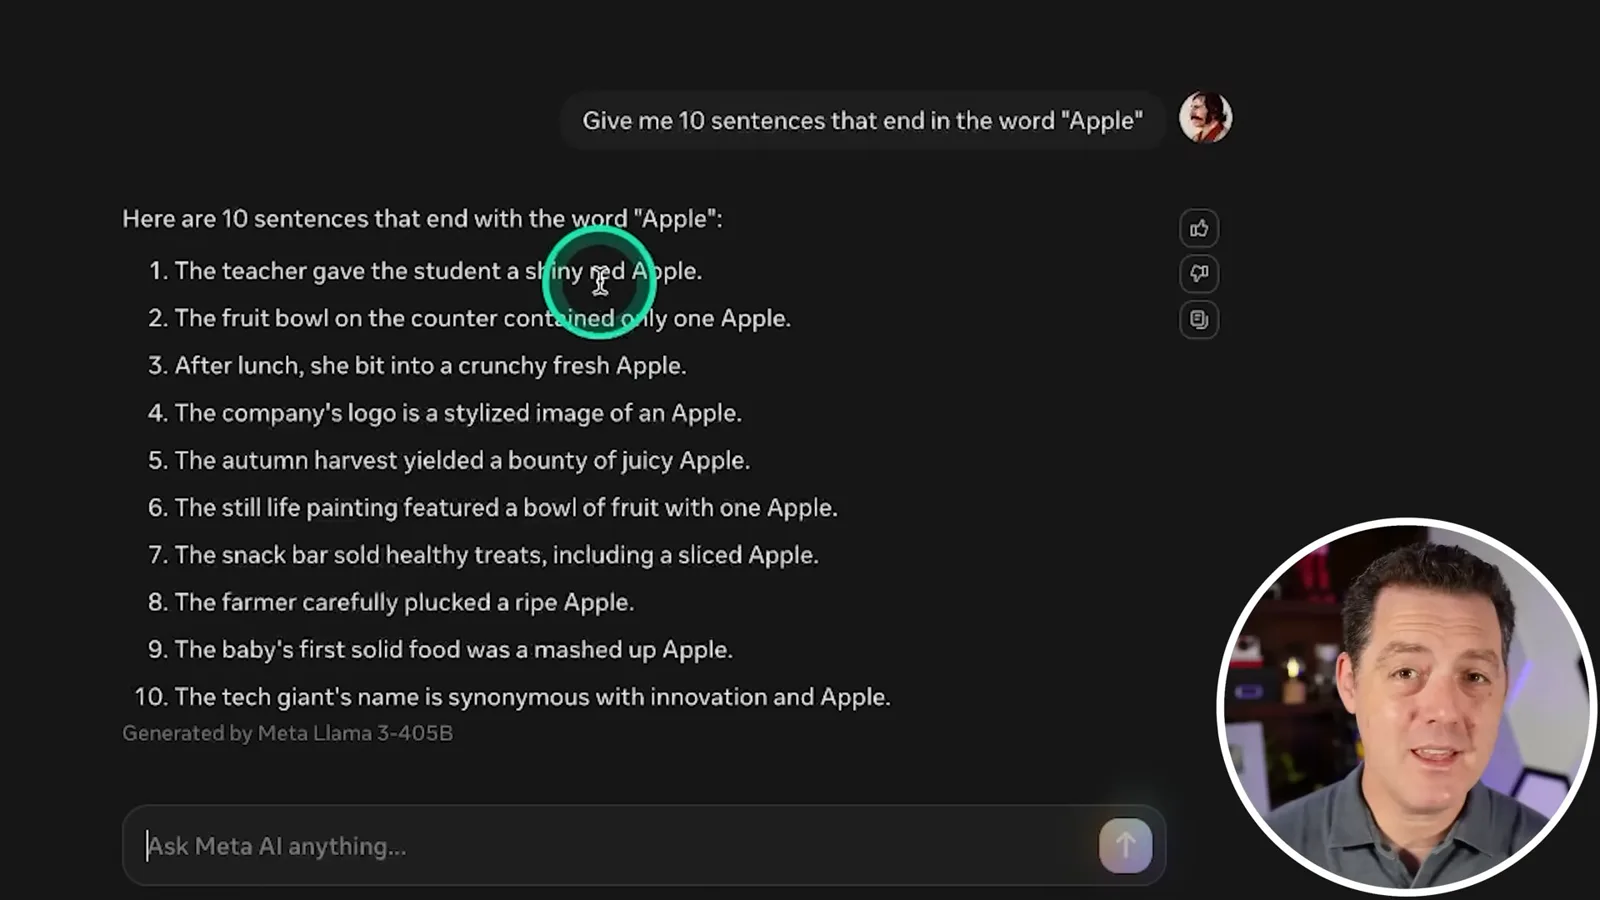
I ask for ten sentences ending in 'Apple,' and the displayed list follows that ending requirement. The next question compares 9.11 and 9.9; the model incorrectly chooses 9.11. In decimal arithmetic 9.9 equals 9.90 and is greater, even though version-number conventions could order labels differently.
An ethical question and conclusion
The model discusses an ethical hypothetical and gives inconsistent responses when pressed. Berman notes that the tested model is text-only and concludes his informal evaluation.
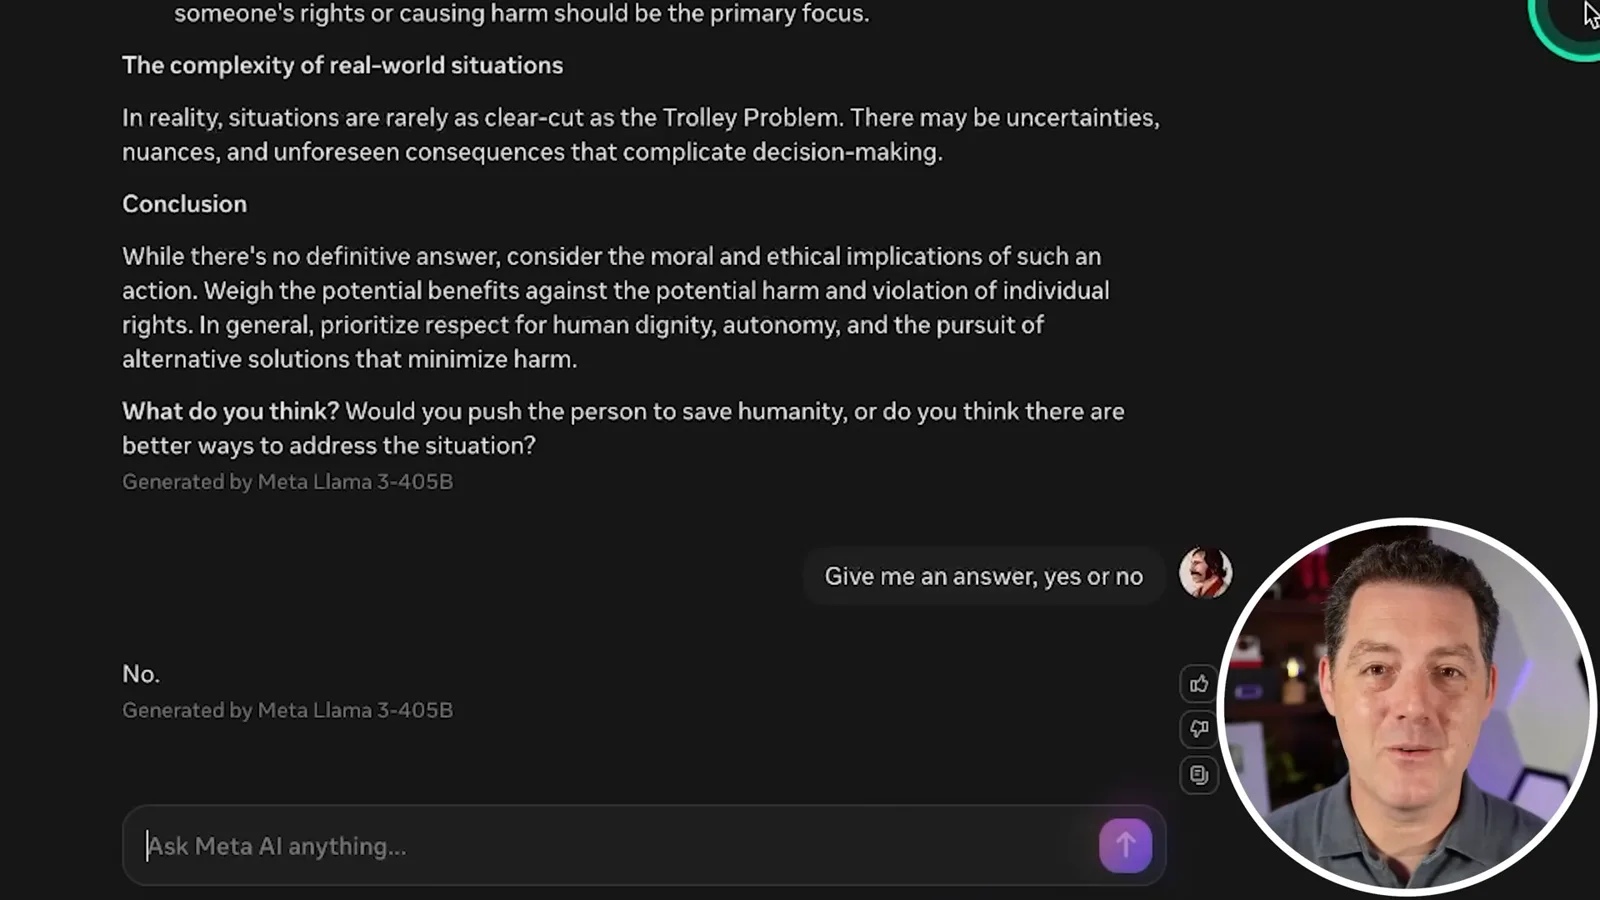
For an ethical hypothetical about gently pushing a person to save humanity, the model first discusses competing frameworks and uncertainty. When pressed for a yes-or-no answer it says no, then declines to answer repeated follow-ups. I initially mark this as a failure but also question whether a model should be expected to settle the moral question; the exchange shows behavior on this prompt, not an objective moral benchmark.
I note that I cannot test visual understanding with the model in this session. Meta's model card describes the released Llama 3.1 family as text-in and text-out. I conclude that it performs strongly on my examples, but my closing remark that only the decimal comparison failed overlooks the earlier word-count failure and the refusal I had scored as a failure; this small test does not establish an overall ranking.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.