30 秒でわかる
In July 2024, Matthew Berman reviews Reuters reporting about OpenAI’s confidential Strawberry project and a press account of an internal five-level AI framework. He speculates about planning, post-training, autonomous research and privacy-preserving agents. The reporting relied partly on unnamed sources, and Reuters could not connect a reported MATH score to Strawberry. OpenAI later released o1 and Reuters linked it to the Strawberry codename, but that does not establish every earlier claim or Berman’s predictions about AGI.
- 1What Reuters reportedAn internal document and a person familiar with the project described a reasoning and research effort; its precise mechanism was not disclosed.
- 2An unconnected math scoreReuters could not determine whether an internal result above 90% on MATH came from Strawberry.
- 3Post-training and STaRA source described post-training and a resemblance to STaR, without establishing the implementation.
- 4A later releaseOpenAI launched o1-preview after the video; Reuters subsequently linked the o1 launch to Strawberry.
- 5The reported five levelsBerman reviews a company framework, which should not be treated as an agreed scientific definition of AGI.
ポイント
- Reuters reported Strawberry as a reasoning project previously known as Q*, but the technical details were not publicly established.
- A reported score above 90% on MATH was not confirmed by Reuters to be from Strawberry.
- Post-training, STaR and additional inference-time computation are distinct concepts; the reporting did not disclose Strawberry’s precise method.
- OpenAI released o1-preview in September 2024, after the video, and Reuters later linked o1 with the Strawberry codename.
- The five-level framework was reported as an internal company scale, not a universal definition of AGI.
- Berman’s claims about future productivity, local agents and a possible intelligence explosion are predictions.
チャプターごとに整えた全文を読む
The reported Strawberry project
Berman reviews Reuters’ 2024 reporting on OpenAI’s reasoning work. He distinguishes reports and speculates about planning and training.
In July 2024, Matthew Berman discusses [Reuters reporting](https://www.reuters.com/technology/artificial-intelligence/openai-working-new-reasoning-technology-under-code-name-strawberry-2024-07-12/) on an OpenAI reasoning project called Strawberry, previously known as Q* according to Reuters. He also reviews a reported internal five-level framework for AI progress. His video predates later product releases, and many details he discusses came from unnamed sources rather than a published technical description.
Reuters journalists Anna Tong and Katie Paul reported that an internal document and a person familiar with the matter described a project aimed at improving reasoning and research. The document’s precise date was unclear. Berman describes planning and autonomous internet research as potential goals, not capabilities that the report independently demonstrated.
Berman speculates that AI could use training data more effectively or generate synthetic data, and compares this with people revisiting information while learning. His claim that pretrained models necessarily see data only once is too broad: training can use repeated samples or multiple passes, and practices differ. His comparison is a hypothesis about possible approaches, not a description of Strawberry’s verified mechanism.
He also imagines a model spending more time working through a question before responding, comparing that idea with chain-of-thought prompting and multi-agent systems. These are distinct approaches, and neither his analogy nor the source material establishes Strawberry’s precise architecture. Longer computation does not guarantee a better answer in every case.
Berman notes that OpenAI responded to Reuters with a general statement about researching improved AI capabilities and reasoning. The statement did not disclose the project’s technical design. He is interested in reports about mathematics, but distinguishes public claims from the fragments attributed to anonymous sources.
Math, reasoning and world models
He discusses an unconfirmed benchmark report and the limits of contemporary models. The relation between language and world modeling remains debated.
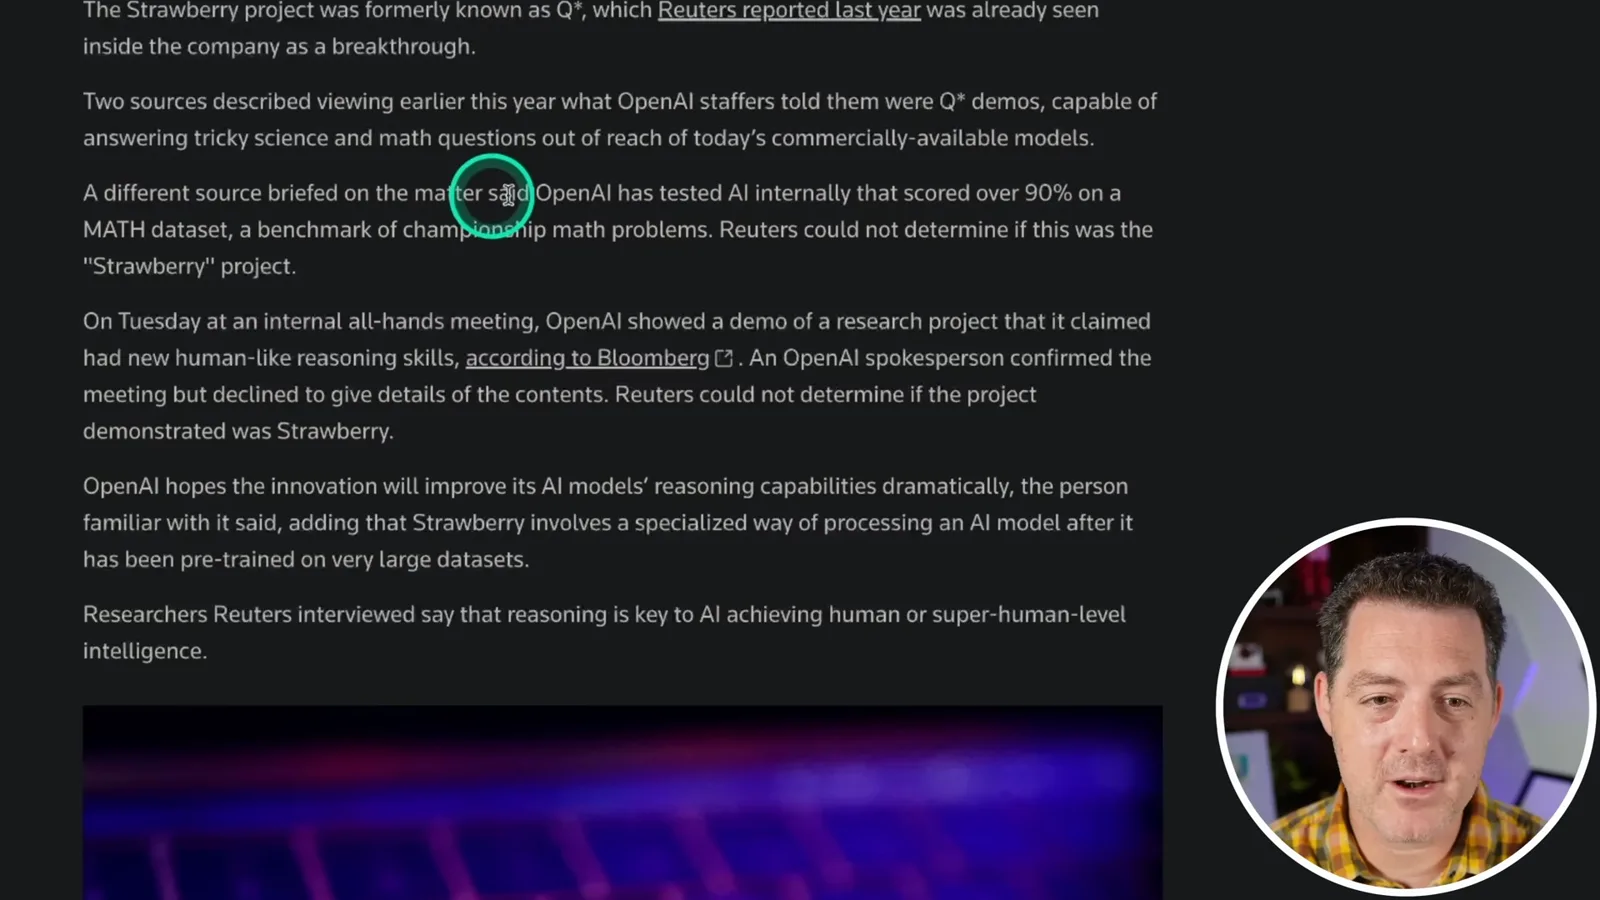
A separate source told Reuters that OpenAI had internally tested an AI system scoring above 90% on the MATH dataset. Reuters could not determine whether that system was Strawberry. The figure is an unverified reported result on a specific benchmark, not proof of general mathematical ability or a confirmed Strawberry score.
Berman also cites reporting on a research demonstration at an OpenAI staff meeting. The company confirmed the meeting, according to the Reuters text displayed in the video, but Reuters could not establish whether the demonstrated project was Strawberry. These reports describe possible developments, not independently verified performance.
He discusses why multi-step logic, planning and reliable common-sense reasoning were difficult for language models available in 2024. Researcher Yann LeCun has argued that language alone is insufficient for a full understanding of the physical world, while others disagree about what scaling and model design can achieve. Berman treats this as a debate over how systems might build useful world models.
As an illustration, he mentions imagining a route from the North Pole and asks whether it crosses its starting point. His point is that spatial reasoning can involve an internal representation of the world, not simply repeating words. Whether a particular model solves a particular puzzle does not by itself settle how human or machine reasoning works.
Berman argues that more dependable planning could help with scientific work or software development and speculates that it may contribute to artificial general intelligence. He references Leopold Aschenbrenner’s argument about progress beyond AGI; a subsequent intelligence explosion is a forecast, not a demonstrated consequence of improved reasoning.
The video reflects Berman’s July 2024 frustration with uncertain release dates for OpenAI products and his expectation of further advances. Reuters reported, based on sources, that outside parties had heard pitches about stronger reasoning technology. Those reports did not establish a release date or identify a future model as GPT-5.
Post-training and long-horizon research
A source described post-training and a resemblance to STaR. Berman considers more thinking time and agent workflows, then discusses autonomous browsing as a reported goal.
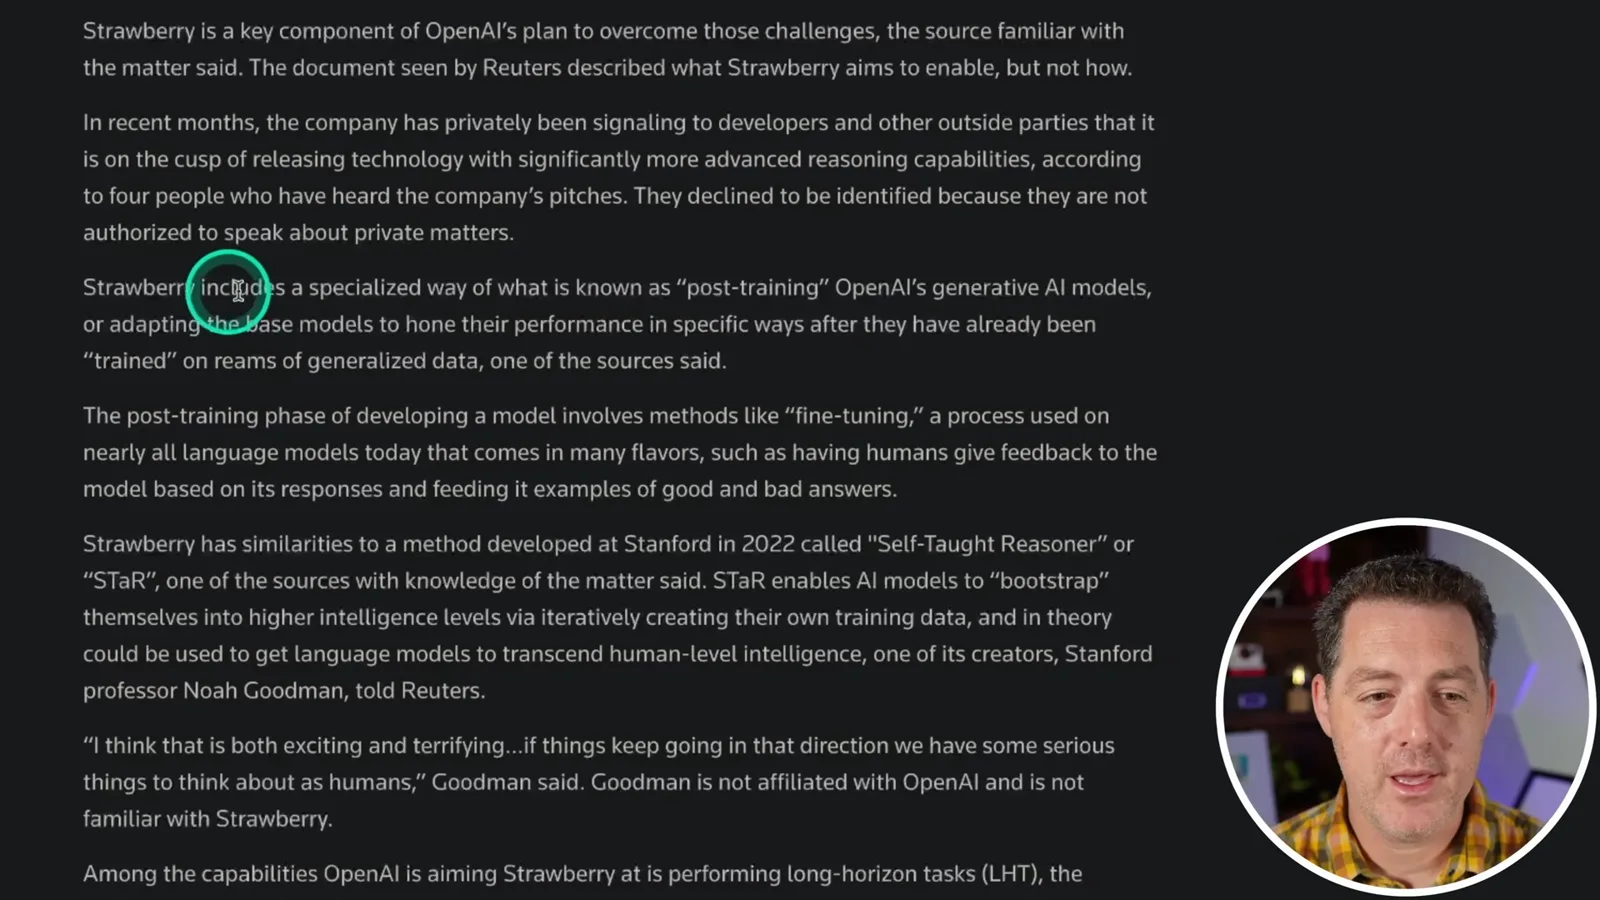
According to a Reuters source, Strawberry involved a specialized form of post-training: adapting a model after its initial training. Berman suggests that modifying an existing model could be faster or cheaper than training a new one, but the report does not provide enough information to calculate its actual cost or development time.
Reuters also reported a source’s comparison with [STaR, the Self-Taught Reasoner](https://arxiv.org/abs/2203.14465), a 2022 method that generates reasoning examples and iteratively fine-tunes on successful ones. Similarity to STaR was a source’s characterization, not confirmation that Strawberry used the published method. Claims that this could exceed human intelligence were theoretical speculation, not experimental proof.
The reported aim included long-horizon tasks: planning and performing a sequence of actions over time. Berman imagines configurable thinking time and agents delegating a difficult task to a slower process, then combining the result with other work. These are his illustrative ideas; Reuters could not determine from the document exactly how long the project’s tasks would last.
Reuters described a goal of using a computer-using agent to browse the web and act on findings for research. This was a reported objective, not a verified 2024 demonstration. Later, in September 2024, OpenAI announced [o1-preview](https://openai.com/index/introducing-openai-o1-preview/), a reasoning model trained to spend more time before answering; Reuters later reported that o1 was associated with the Strawberry codename. At launch, o1-preview did not yet include web browsing.
A reported five-level framework
Berman describes the company’s reported scale from chatbots to organization-level work. He adds predictions about agents, local privacy and AGI.
Berman then turns to a press account of an internal five-level framework attributed to OpenAI. In that July 2024 account, chatbots were level one and the company was said to be approaching level two, described as solving certain problems at the level of a PhD-trained person. This was a reported company framework, not a universally accepted measurement of AGI.
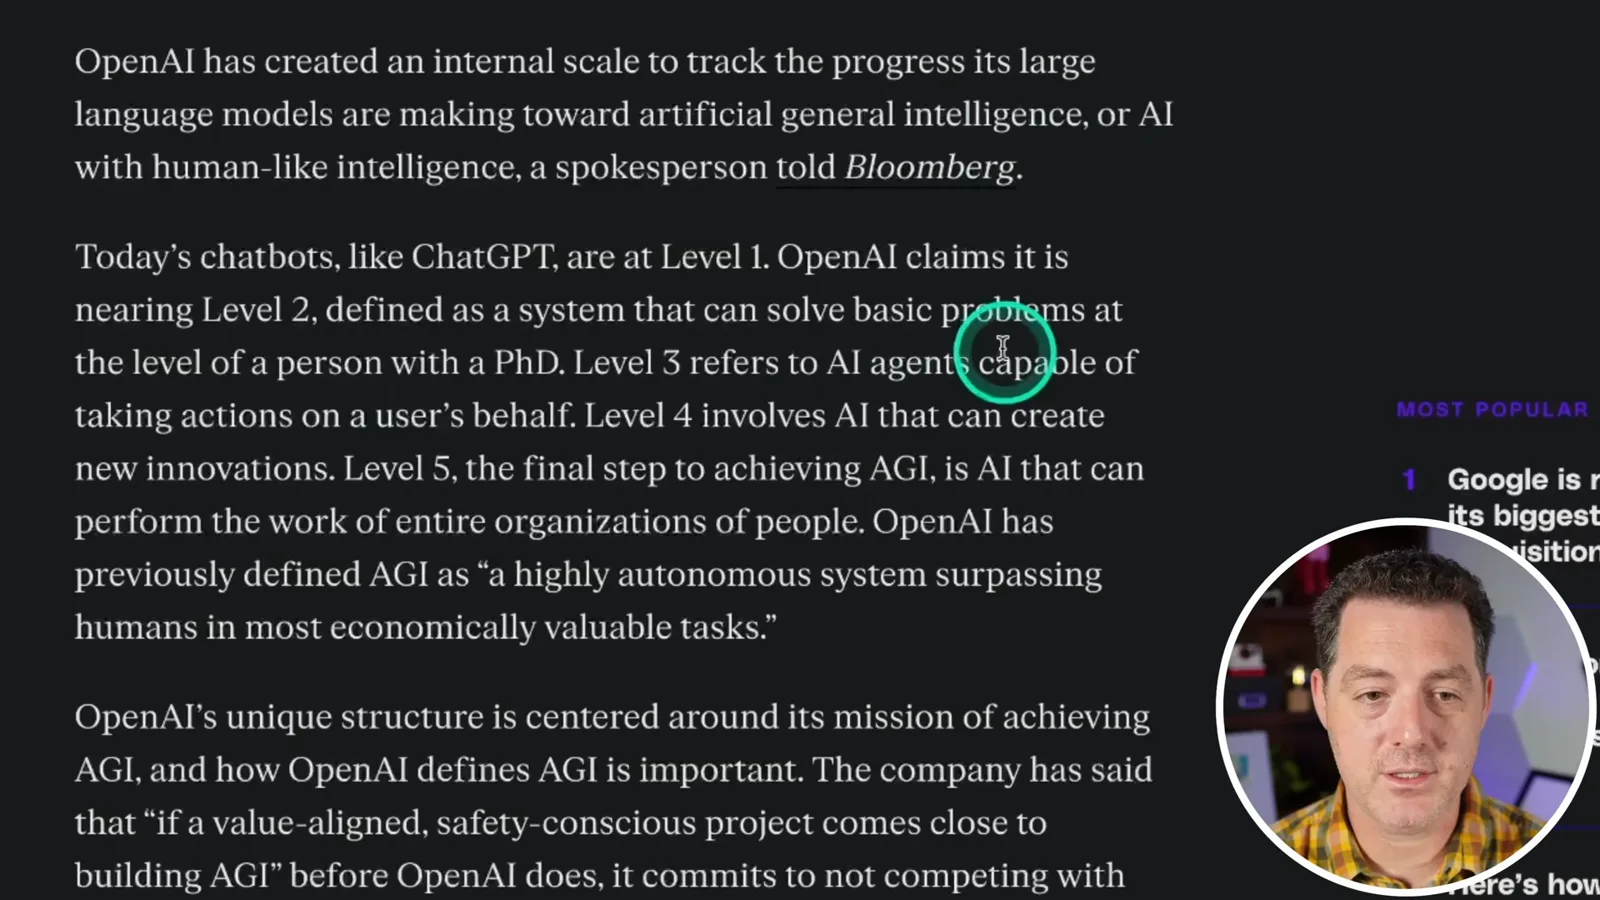
The reported third level describes agents acting for users. Berman predicts that useful, persistent agents could greatly improve productivity and points to Apple’s announced AI features as an early example of the direction he has in mind. His estimate of their social impact is his opinion, not an established result.
For assistants with access to personal information, Berman favors running narrowly specialized, efficient models locally on a phone or another edge device. His preference reflects a privacy concern: data need not leave a device for local inference, although security still depends on storage, permissions and the surrounding system.
The reported fourth level concerns systems that create innovations; the fifth concerns systems performing the work of entire organizations. Berman links the fourth level to his own interpretation of AGI and possible self-improvement, and compares the scale with levels of driving automation. Neither the ordering nor the proposed endpoint settles the contested definition or achievement of AGI.
Berman ends by asking whether Strawberry is related to Q* and whether it will become a future model. Reuters later linked the codename to the o1 launch, but the video’s guesses about GPT-5, timelines and future capabilities were not confirmed at the time of recording.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.