30 秒でわかる
An accounting agent can get most checks right and still fail a task a bookkeeper needs to trust. Ramp’s Ryan Stevens says his team spent four to six months building synthetic businesses and repeatable end-to-end evaluations before launch. It measures both partial accuracy and whether an entire task succeeds, then uses failures to compare models, remove unhelpful skills and test memory across periods. Scheduled regression runs continue after launch; in one illustrated memory test, accuracy rose from 56% to 61.5%.
- 1Understand the job before deciding what to measureRamp worked with bookkeepers and accounting firms to define end-to-end tasks such as reconciliation.
- 2Synthetic businesses make agent tests repeatableThe team built complete sample books, bills and business records so each run begins from a known state.
- 3Partial accuracy can hide an entirely failed taskStevens compares criterion-level accuracy with pass@k, which requires at least one fully correct attempt.
- 4Reasoning was the largest failure category in Ramp’s accounting testsThe team says agents often gathered the required information but reasoned about it incorrectly.
- 5Measure each skill’s contribution before keeping itAblation helped identify skills for deletion or compression; Stevens notes uncertainty about the signs on his displayed chart.
- 6Test memory by carrying it into the next periodThe agent retains customer rules but must work with fresh records. The illustrated accuracy rose from 56% to 61.5%.
- 7Schedule regression runs rather than relying only on release-time checksRamp tags cases, runs them periodically and has an agent flag possible regressions for investigation.
ポイント
- Define the job and success criteria with practitioners before designing agent evaluations.
- Create realistic, replayable environments when representative user data is unavailable.
- Track full-task success alongside partial accuracy when a single mistake can undermine trust.
- Ablate individual skills and test memory across changing periods rather than assuming either helps.
- Run recurring regression checks and investigate failures, accounting for nondeterministic results.
チャプターごとに整えた全文を読む
Turn bookkeeping into measurable tasks
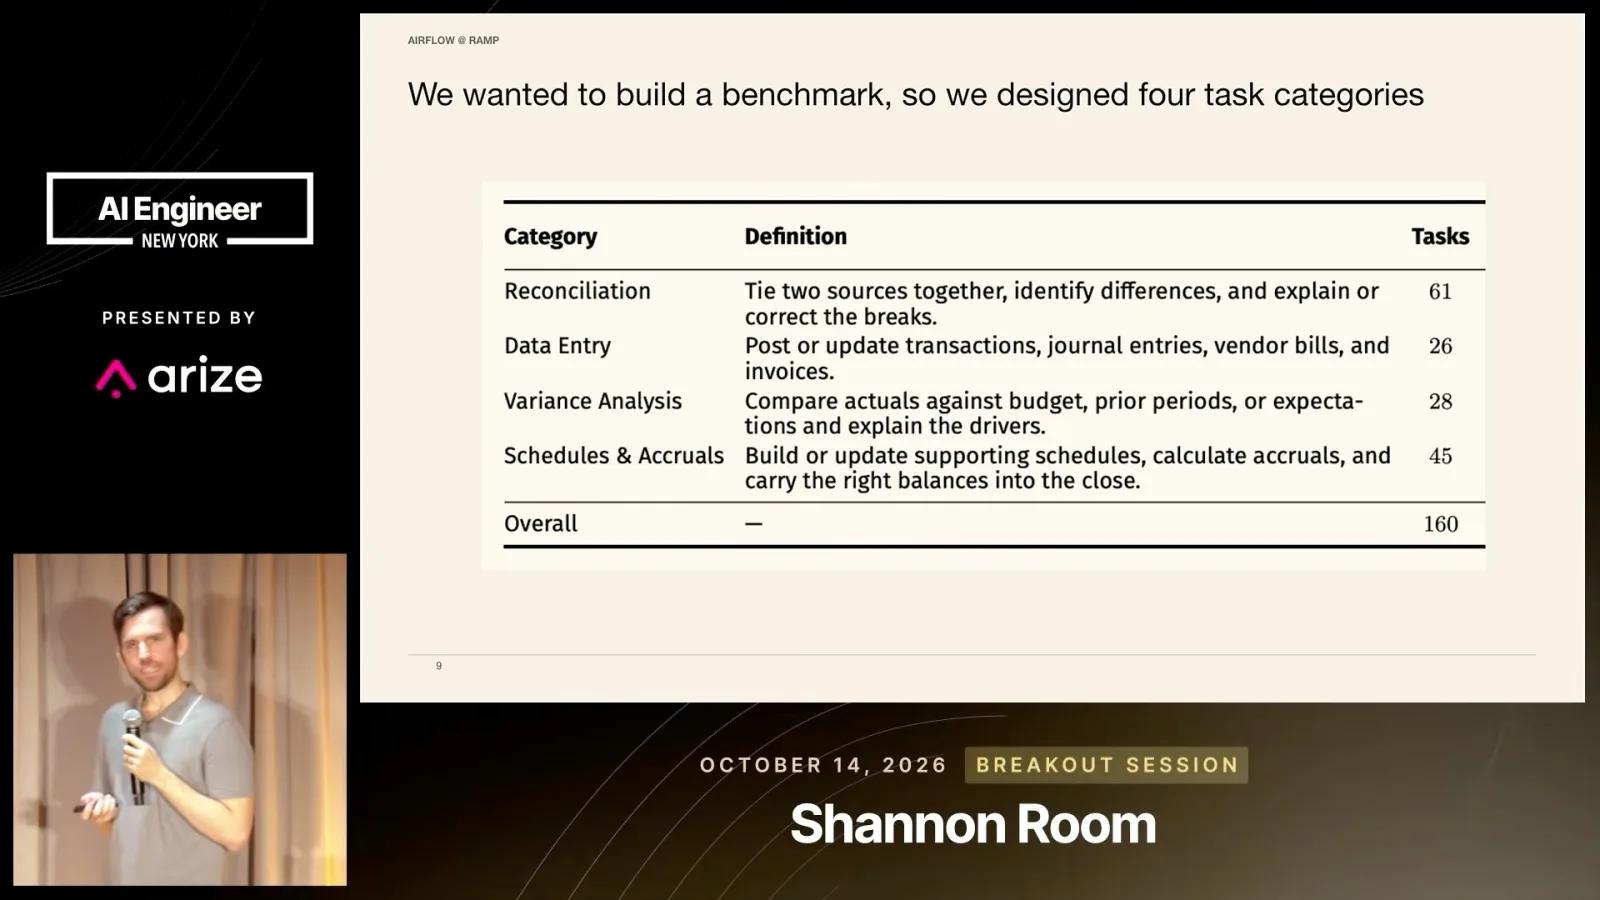
Stevens starts with practitioners’ workflows and defines what success means. Reconciliation and three other task categories form the benchmark.
Ryan Stevens leads applied sciences at Ramp and introduces Stack, an AI bookkeeping agent. He focuses on evaluating whether an agent can complete a real job, not just whether its individual components look promising.
Before building an agent, Stevens says, break the job into tasks and define success with the people who do it. His team met bookkeepers and accounting firms to understand their full workflows.
For reconciliation, an accountant compares a ledger in an enterprise resource planning system with the system containing bills, identifies differences and resolves them. The benchmark also covers data entry, variance analysis, schedules and accruals.
Build replayable businesses and score the result
Synthetic records create a consistent offline test. Partial accuracy and pass@k capture different aspects of performance.
When there are not enough users to supply representative data, Stevens recommends simulation. Ramp worked with Mercor to create synthetic businesses and their accounting environments for offline evaluation.
One simulated business sells through several channels. The team created its accounting system, customer and vendor lists, bills and other documents so agents could perform realistic tasks against a consistent starting state.
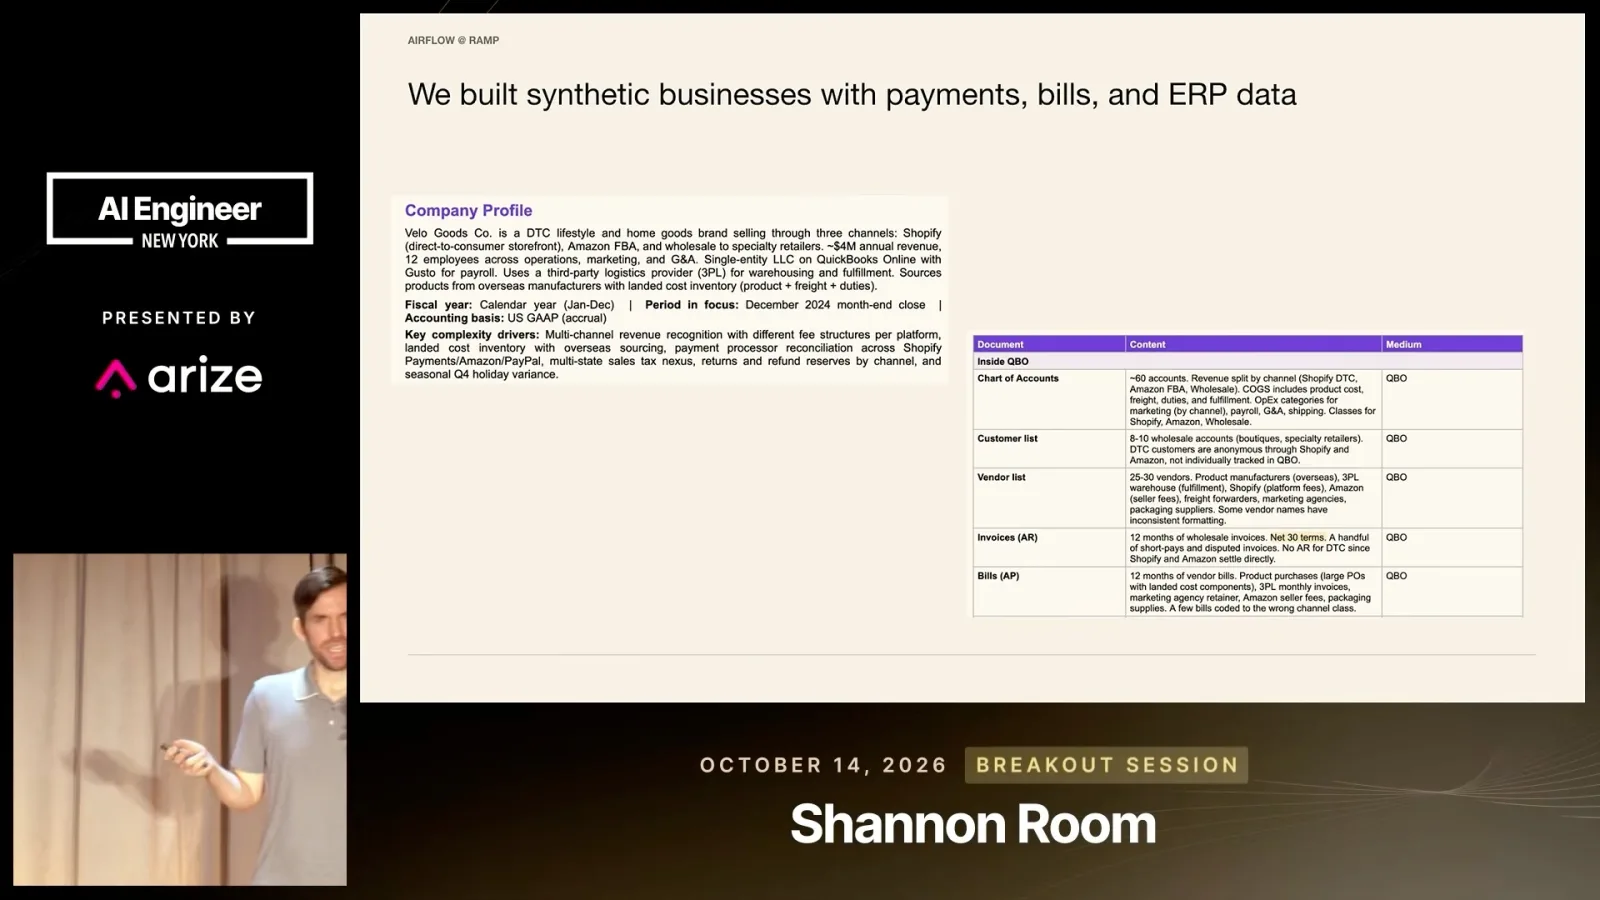
Stevens describes the process as backtesting: rerun an agent against the same task and data, then compare results over time. Unlike a code repository with version history, production systems require deliberate snapshots to make past states replayable.
Each test combines a task with a simulated business environment, which the team calls a world. The agent runs and the team grades the final output against typically 10 to 20 criteria per task.
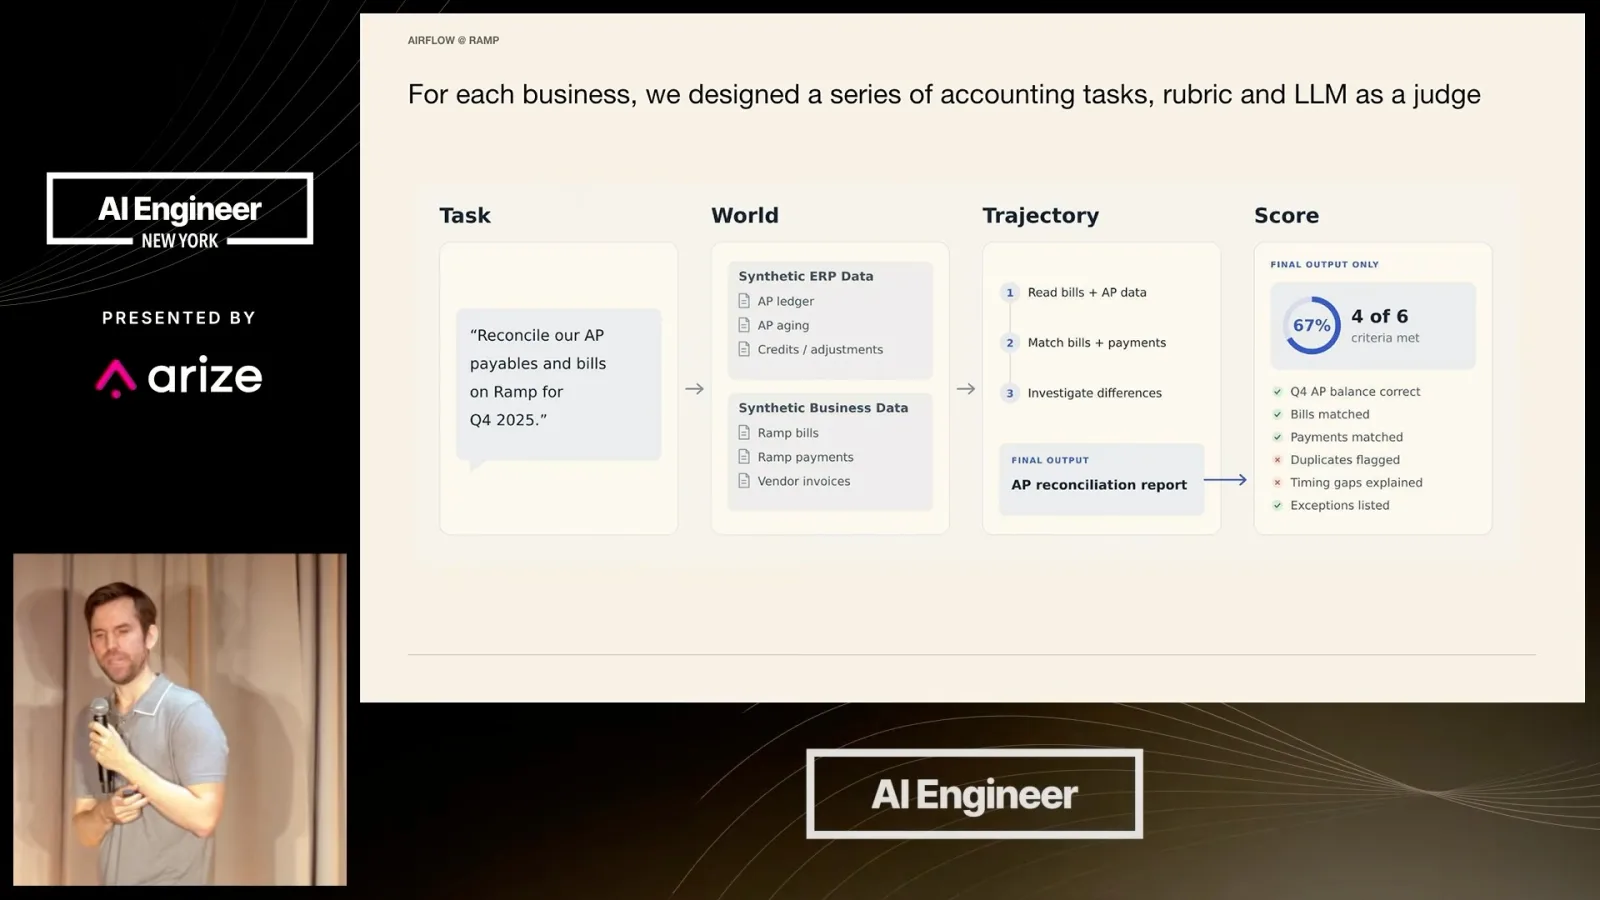
Initially, Ramp did not score whether the agent chose the correct tools or the most efficient trajectory. Stevens says the team first prioritized correctness, cost and speed, though other applications may need to evaluate intermediate steps.
He says building the evaluations took four to six months before launch. In domains not already optimized by frontier model providers, creating useful test environments can itself require substantial work.
Stevens contrasts partial-credit accuracy with pass@k. If four of six criteria are correct, the example receives 67% accuracy; pass@k asks whether any of k attempts satisfies every criterion.
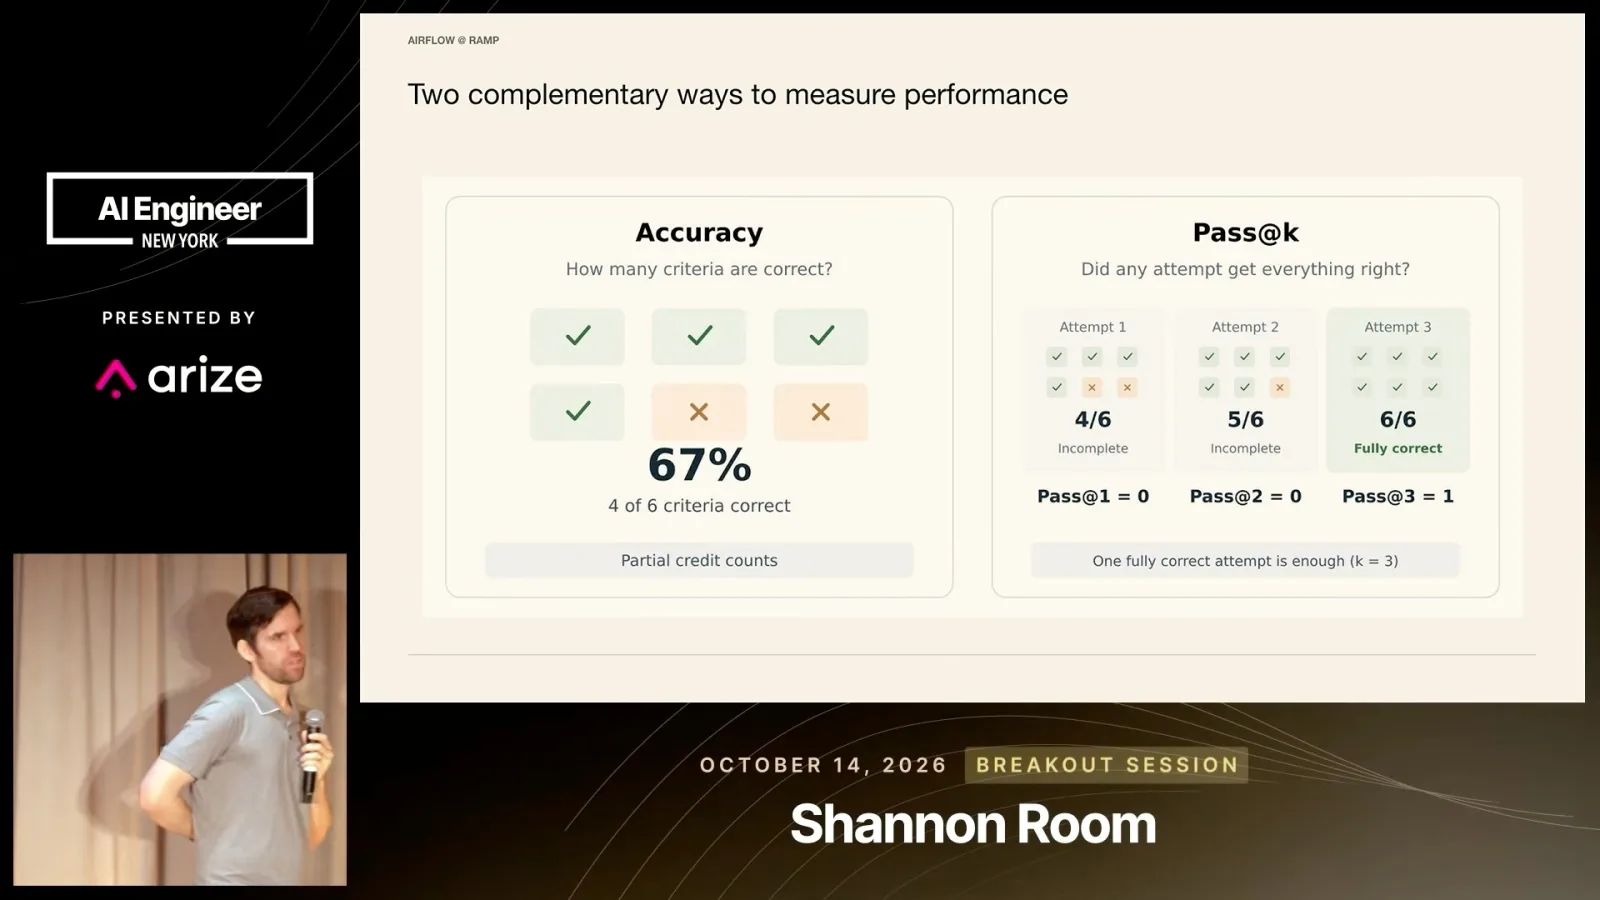
In his three-attempt illustration, the first two runs are incomplete and the third satisfies all six criteria. The example has pass@1 and pass@2 of zero and pass@3 of one. He says all-or-nothing measures can matter when accounting errors undermine trust.
Use failures to improve the agent
The team compares models, classifies failures and tests which skills or memories improve results. Some automated tuning attempts did not help.
The benchmark helped the team compare models. Stevens reports high partial accuracy but much lower pass@1 in the results he shows, leaving room for improvements in the surrounding agent system.
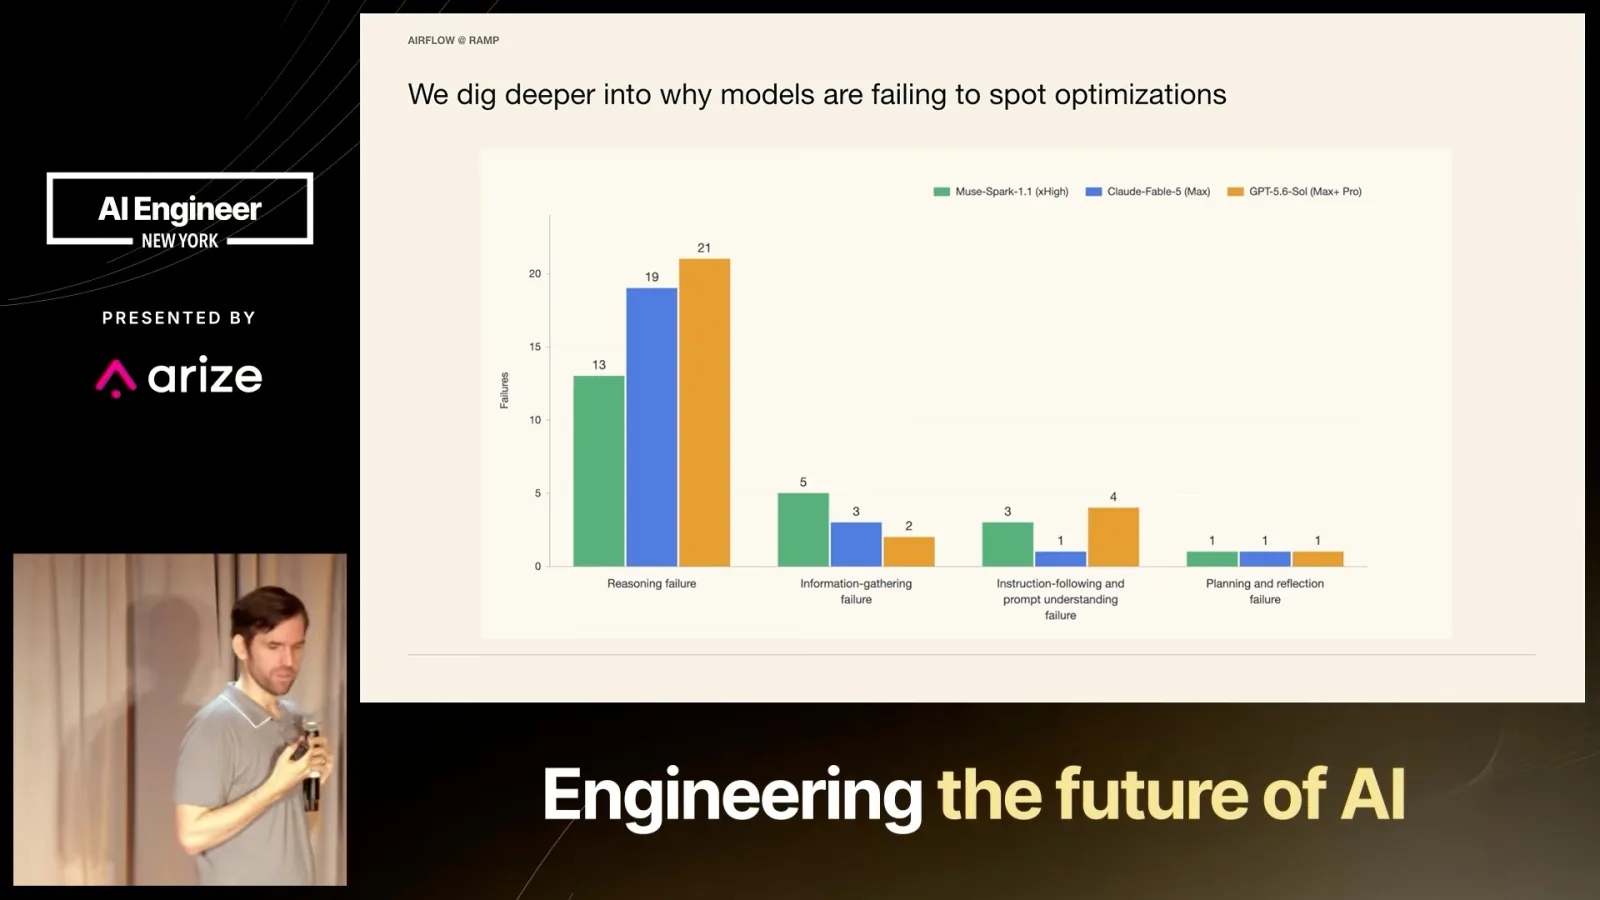
The team categorized failures as reasoning, information gathering, instruction following and other problems. In its accounting tasks, Stevens says reasoning failures were the largest category: the agent often had the information but did not use it correctly.
He also highlights failed experiments. In this setting, automated prompt or skill tuning did not work for the team; Stevens cautions that its lack of success may be specific to their agent and should temper assumptions about automatic research.
One useful experiment was skill ablation: compare performance with and without individual skills, analogous to testing the contribution of features in machine learning. The results identify candidates to remove or compress and can reduce context usage.
Stevens cautions that he may have reversed the sign interpretation on the displayed ablation chart. His practical conclusion is to measure each skill’s effect rather than assume that adding instructions always helps.
The team also tested memory using what it calls roll-forward worlds. An agent performs a task in one period, writes a compressed memory, and then handles a similar task for the same business in the next period.
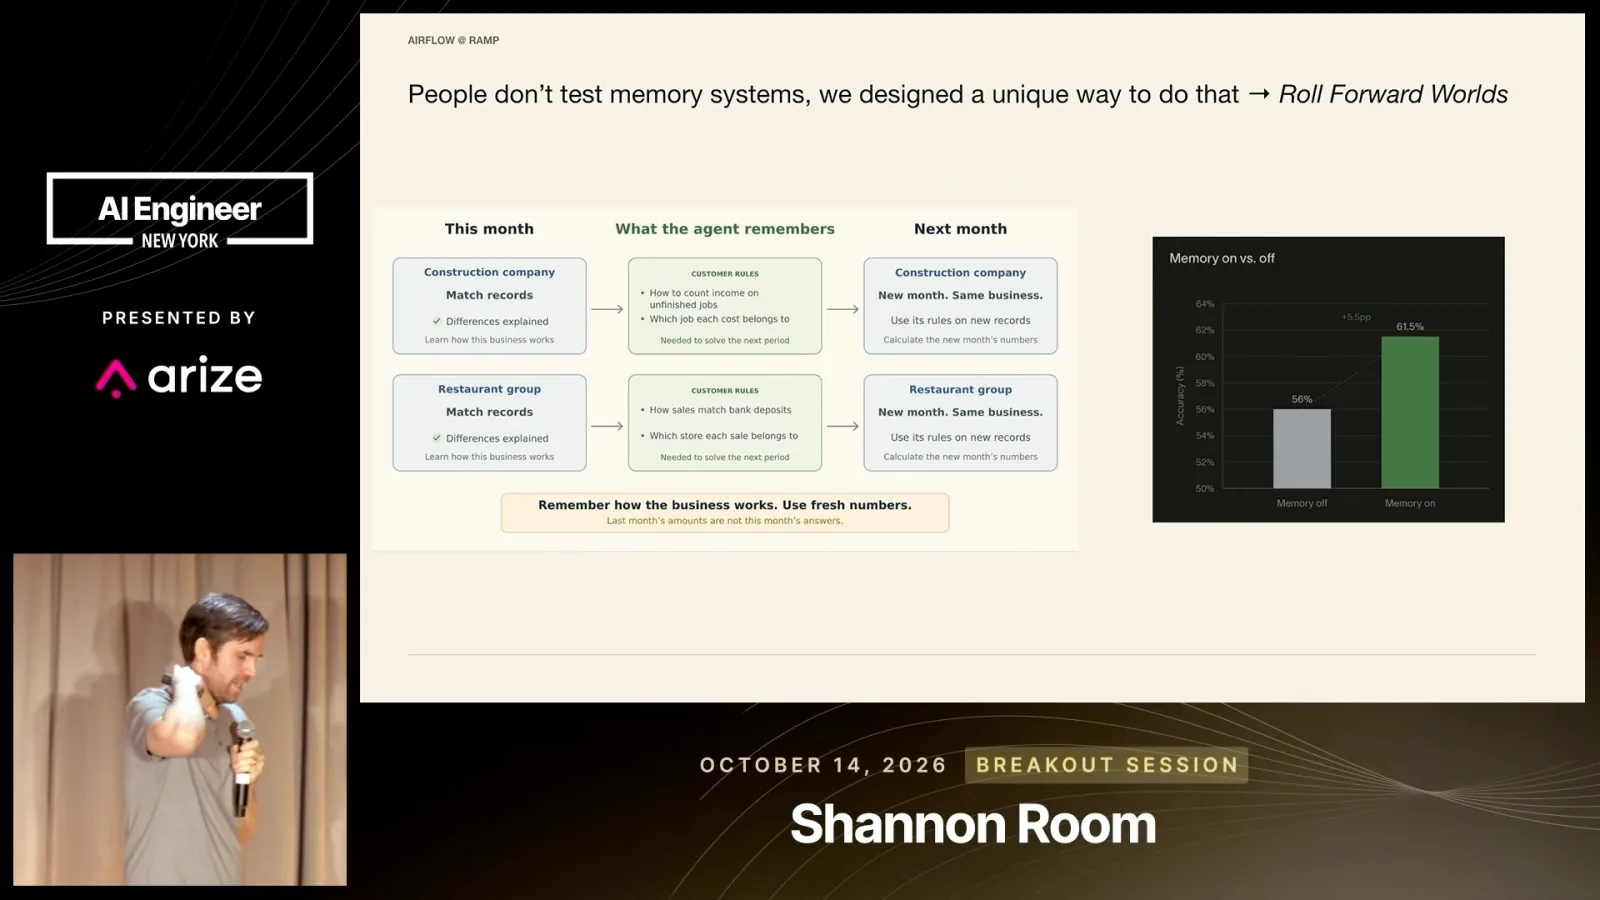
For reconciliation, that memory might retain implicit customer-specific rules while the numerical records change. The next run can receive the memory directly or search for it. Stevens says the prompts used to write memories strongly affected their usefulness.
In the illustrated evaluation, memory raised accuracy from 56% to 61.5%; Stevens describes memory tuning as one of the larger gains the team found. The purpose is to retain how the business works rather than reuse last month’s numbers as answers.
Keep checking after launch
Scheduled regression evaluations compare tagged cases over time and surface possible failures for investigation.
Finally, Ramp runs recurring regression evaluations. Stevens is cautious about using nondeterministic agent evaluations as a hard continuous-integration gate; instead, the internal platform schedules tagged cases and compares results with prior performance.
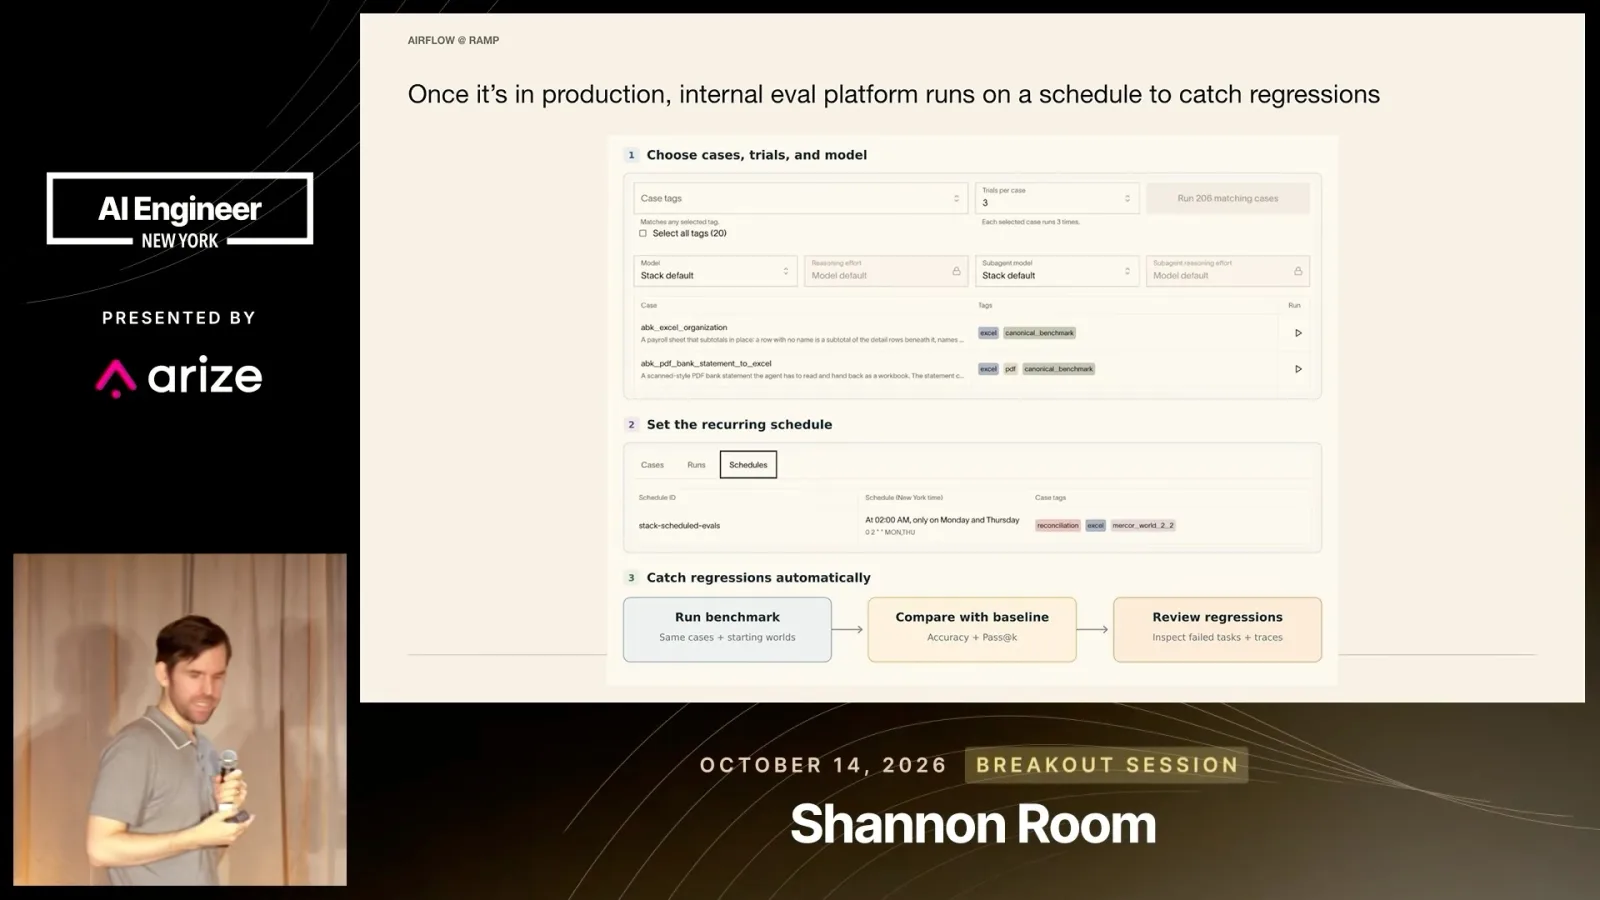
A background agent examines failures and possible regressions and sends a message for someone to investigate. Stevens closes by recommending realistic environments, clear task definitions and evaluation workflows that continue after launch.
同じチャンネルの記事
 19:41EN
 AI Engineer· 2026年11月9日A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 22:01ENAI Engineer· 2026年11月9日Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· 2026年11月9日Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 15:25ENAI Engineer· 2026年11月9日Hassan and Omar El Mghari: When an AI financial forecast is right for the wrong reasonsHassan El Mghari, Omar El Mghari · Together AIA Costco membership-fee model passed basic checks and landed close to reported results, but an audit uncovered offsetting assumptions.
 14:38ENAI Engineer· 2026年11月9日Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· 2026年11月9日Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.