30 秒でわかる
Matthew Berman explains Apple's 2024 account of its on-device and server foundation models and argues that personal context and task execution could make Apple Intelligence useful. He reviews training, privacy claims, optimization and evaluation charts. The article corrects a spoken latency figure and distinguishes Apple's reported results and future product plans from independently established performance.
- 1Two foundation modelsApple describes an on-device language model and a larger server model, alongside other models for coding and images.
- 2Training and privacyThe company describes AXLearn, licensed and public data, filtering and its policy on private user data.
- 3Optimizing inferenceApple discusses low-bit palettization, LoRA and cache optimizations; its latency figure is 0.6 milliseconds per prompt token, not the six spoken in the video.
- 4Human evaluationThe comparison charts measure selected prompts and criteria; results depend on the tested models and evaluation.
ポイント
- Apple described an approximately 3-billion-parameter on-device model and a larger model for Private Cloud Compute.
- Apple says it trains on licensed and public web data, rather than users' private personal data or interactions.
- Low-bit compression, grouped-query attention and adapters are among the techniques described for efficient and specialized inference.
- Apple's source reports about 0.6 milliseconds per prompt token and 30 output tokens per second on iPhone 15 Pro in its stated test; the first figure is not total latency.
- The displayed human evaluations compare specific models and sampled prompts, not universal performance across all tasks.
チャプターごとに整えた全文を読む
Personal intelligence and models
Berman explains Apple's on-device and server approach. He argues that personal context and actions may be more useful than general knowledge for daily tasks.
Apple has published details about Apple Intelligence, and I want to clear up a misconception: it is not simply sending everything to OpenAI. Apple describes its own models, including an approximately 3-billion-parameter on-device model and a larger server model for Private Cloud Compute.
Apple describes a personal intelligence system integrated into its operating systems. I think its differentiator is access to personal context on the user's device and its ability to help with everyday tasks. I contrast that with general questions about the world, though Apple's foundation models are not limited to only one narrowly defined task.
I'm optimistic about the possibility of Siri taking useful actions across apps. I might ask a general model a few questions a day, but an assistant that actually helps with daily work could be useful much more often. That is my expectation, not evidence that all the showcased actions are already available.
Apple says it has tuned models for writing, notification summaries, images and in-app actions. Notification summaries sound overdue to me; the cross-app actions are the part I find most important. I also expect Apple to take a conservative approach to generated images and safety because it is protective of its brand.
The on-device language model has about three billion parameters. Apple also describes a larger server model running on Apple silicon in Private Cloud Compute. Its model family includes a coding model and an image diffusion model, for which it said it would share more detail later.
Principles and training
He reviews Apple's stated safety and privacy principles and its training pipeline. The discussion covers data, infrastructure and post-training.
Apple lists responsible AI principles: build tools for specific user needs, represent users authentically, design carefully to reduce misuse and protect privacy. I favor an architecture that can select specialized, efficient models for particular tasks, although that is my preference rather than a proven general superiority over larger models.
Apple says it works to avoid stereotypes and bias, evaluates potential misuse and uses on-device processing and Private Cloud Compute for privacy. It says users' private personal data and interactions are not used to train its foundation models. These are Apple's stated design and training policies.
The development pipeline includes data preparation, pre-training, post-training and optimization. Apple uses AXLearn, its open-source framework built on JAX and XLA, and describes training across TPUs and cloud or on-premises GPUs with several forms of parallelism.
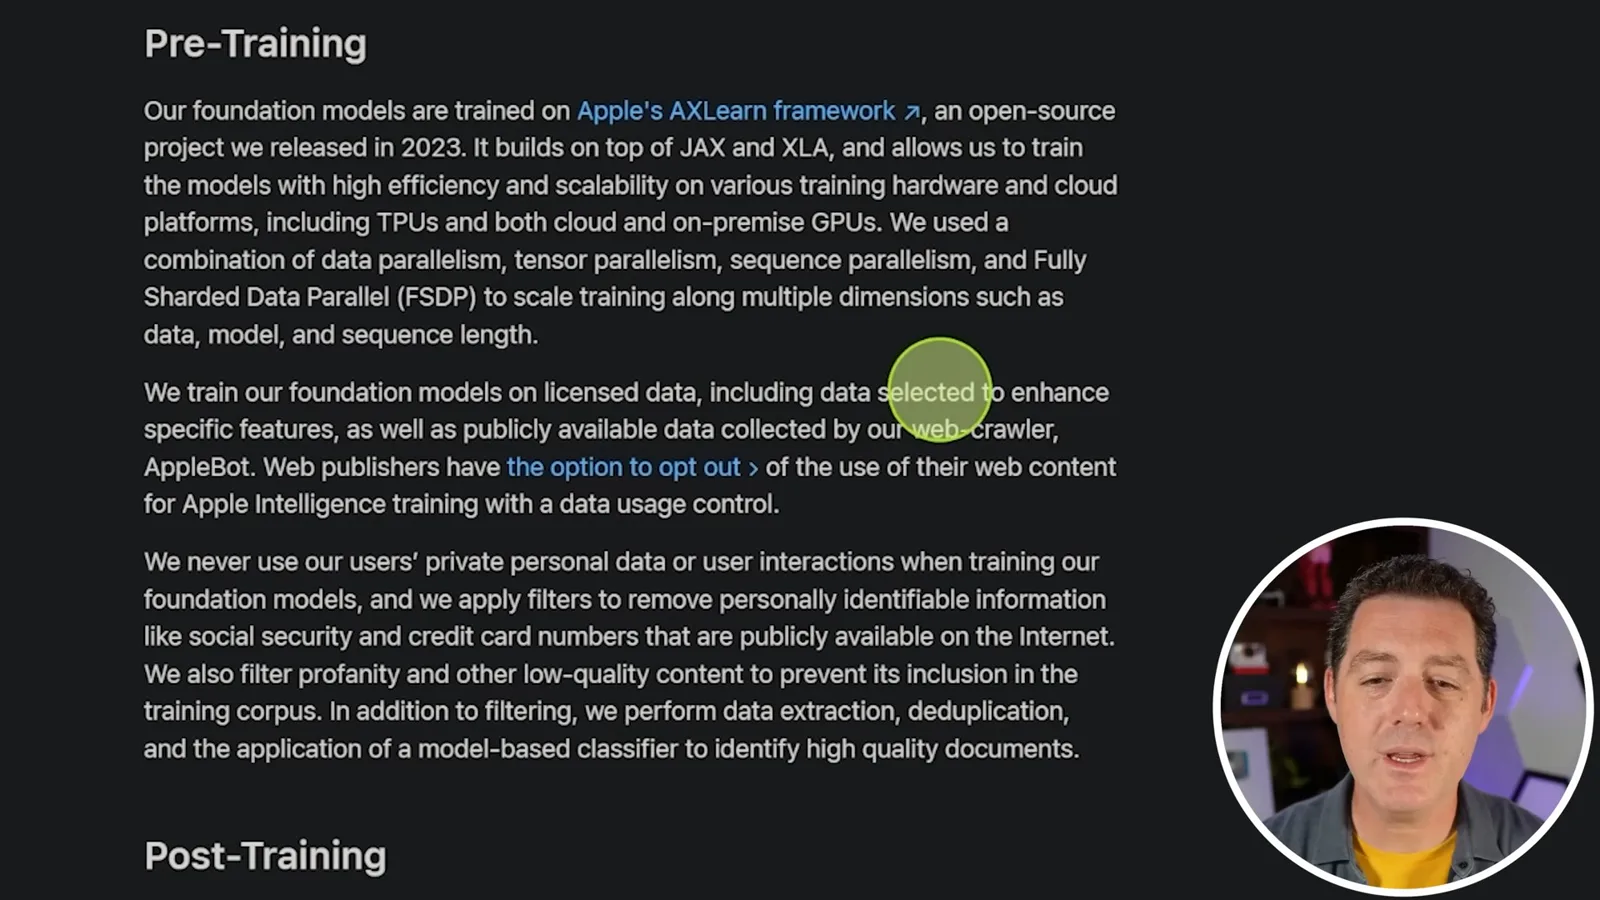
For pre-training, Apple says it uses licensed material and public data collected by Applebot; publishers can opt out of the latter use. It says it filters personal identifiers and low-quality material, deduplicates data and uses a classifier to identify high-quality documents. I speculate that publishers may trust Apple more than some competitors; that is my opinion.
For post-training Apple describes using both human-annotated and synthetic data, with filtering and curation. It names rejection sampling fine-tuning with a teacher committee and a reinforcement-learning-from-human-feedback method. I do not claim to understand all the details of those algorithms.
Optimization and adaptation
Apple describes efficient inference, compression and task adapters. Its source's per-prompt-token latency differs from Berman's spoken number.
Apple emphasizes inference speed and efficiency on devices and in its private cloud. Running more work locally could reduce server demand and limit the need to send certain data off-device, although actual costs and privacy properties depend on the whole system.
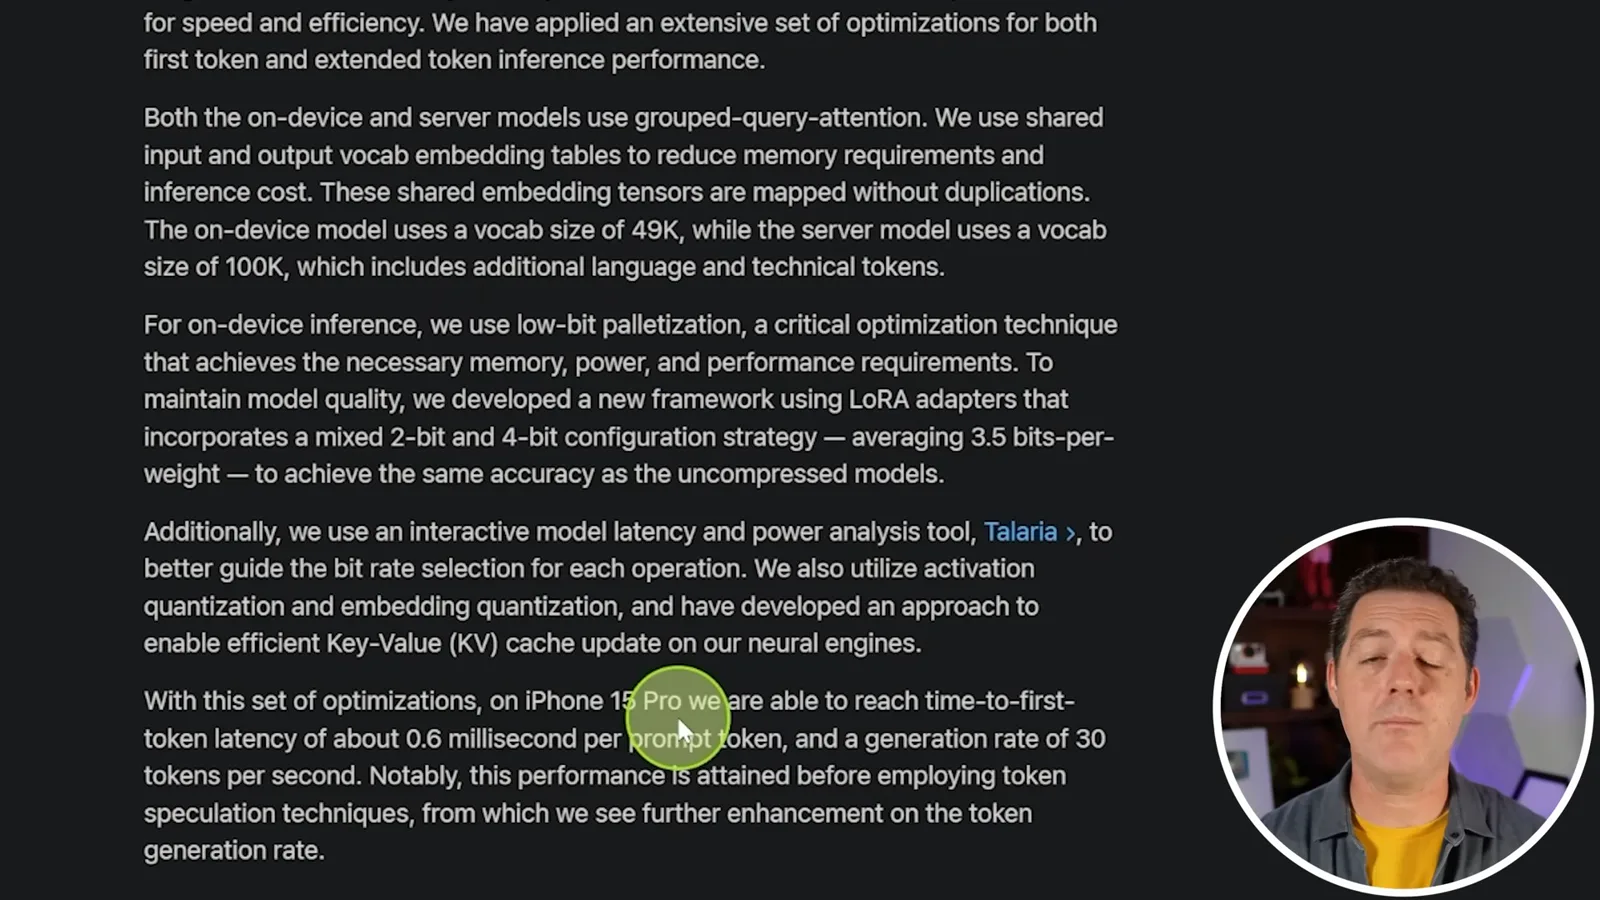
Both models use grouped-query attention and shared input/output embedding tables to reduce memory and inference costs. Apple reports a 49,000-token vocabulary for the on-device model and 100,000 for the server model. My question about whether it uses Nomic's embeddings is speculation; the cited description does not establish that.
The on-device model uses low-bit palettization and LoRA-based techniques, with a mixed two- and four-bit configuration averaging 3.5 bits per weight. Apple describes maintaining quality under its evaluation; that does not prove identical performance on every possible task.
Apple also uses its Talaria latency and power analysis tool, activation and embedding quantization and an efficient key-value cache update. It reports roughly 0.6 milliseconds per prompt token for time-to-first-token processing and 30 generated tokens per second on iPhone 15 Pro before token speculation. I say six milliseconds in the video, but the displayed source says 0.6; the per-input-token figure is not the total time to the first token.
For adaptation, Apple uses small adapter modules in layers of the pre-trained model. Training the adapters leaves the base model parameters unchanged while specializing behavior for tasks. I compare the idea to a mixture of experts, but adapters alone do not establish that this is a mixture-of-experts architecture.
Evaluations and outlook
Berman examines Apple's human preference, safety and writing charts. He closes with his expectations for local models.
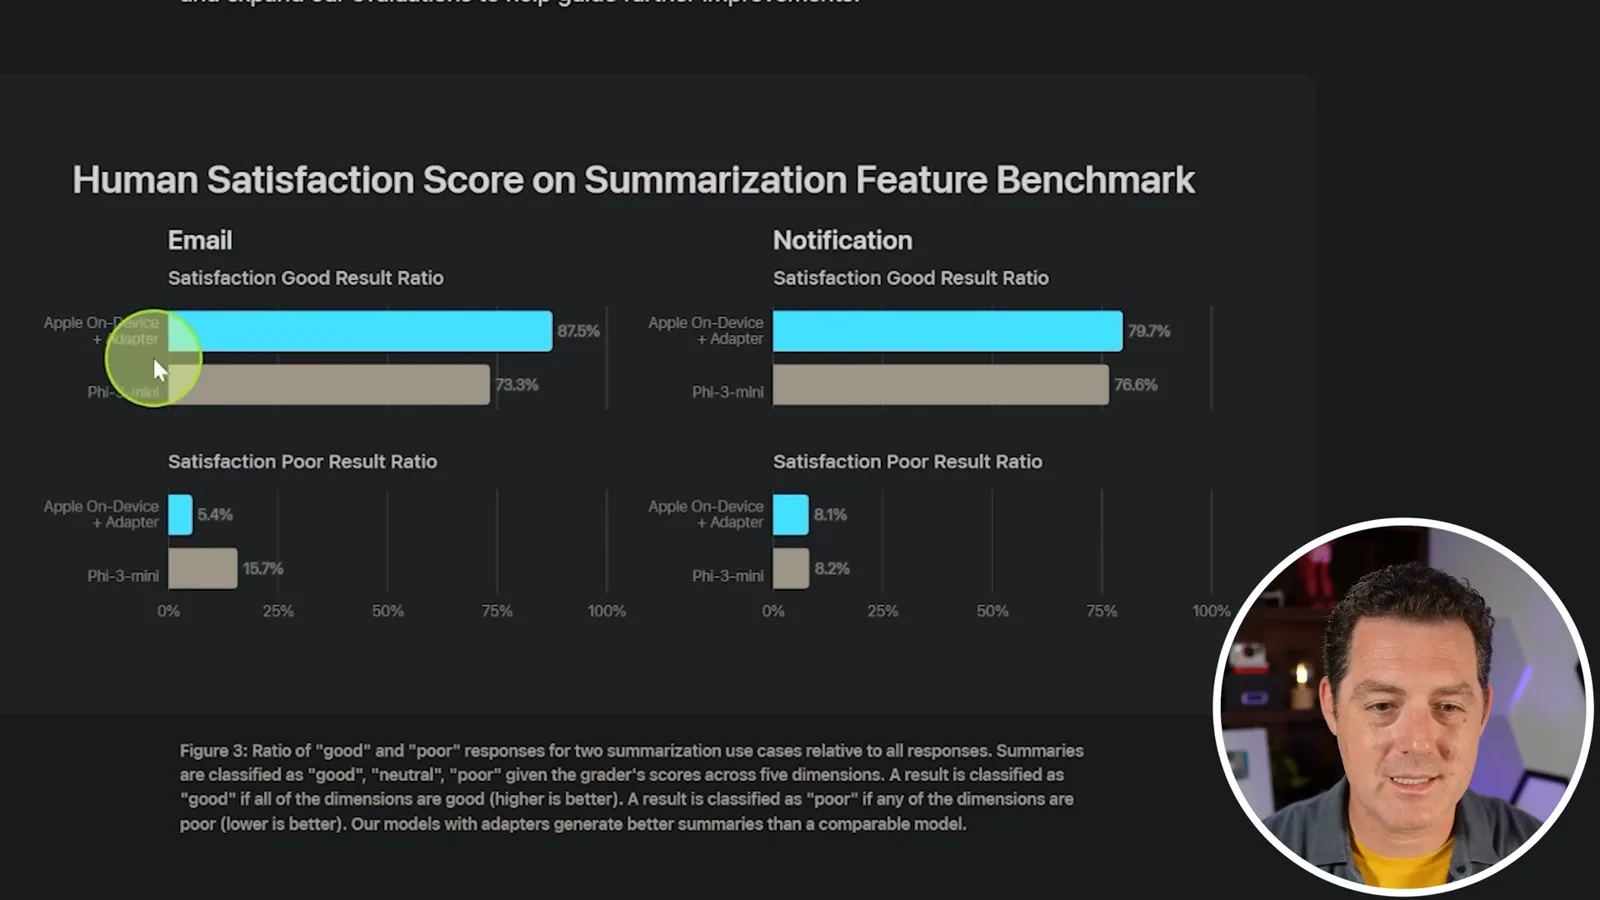
Apple emphasizes human evaluation for user-facing tasks. Its email-summary chart shows 87.5% good results for the on-device model with an adapter versus 73.3% for Phi-3-mini on its sampled evaluation. The notification comparison is closer; these figures are limited to Apple's selected cases and grading procedure.
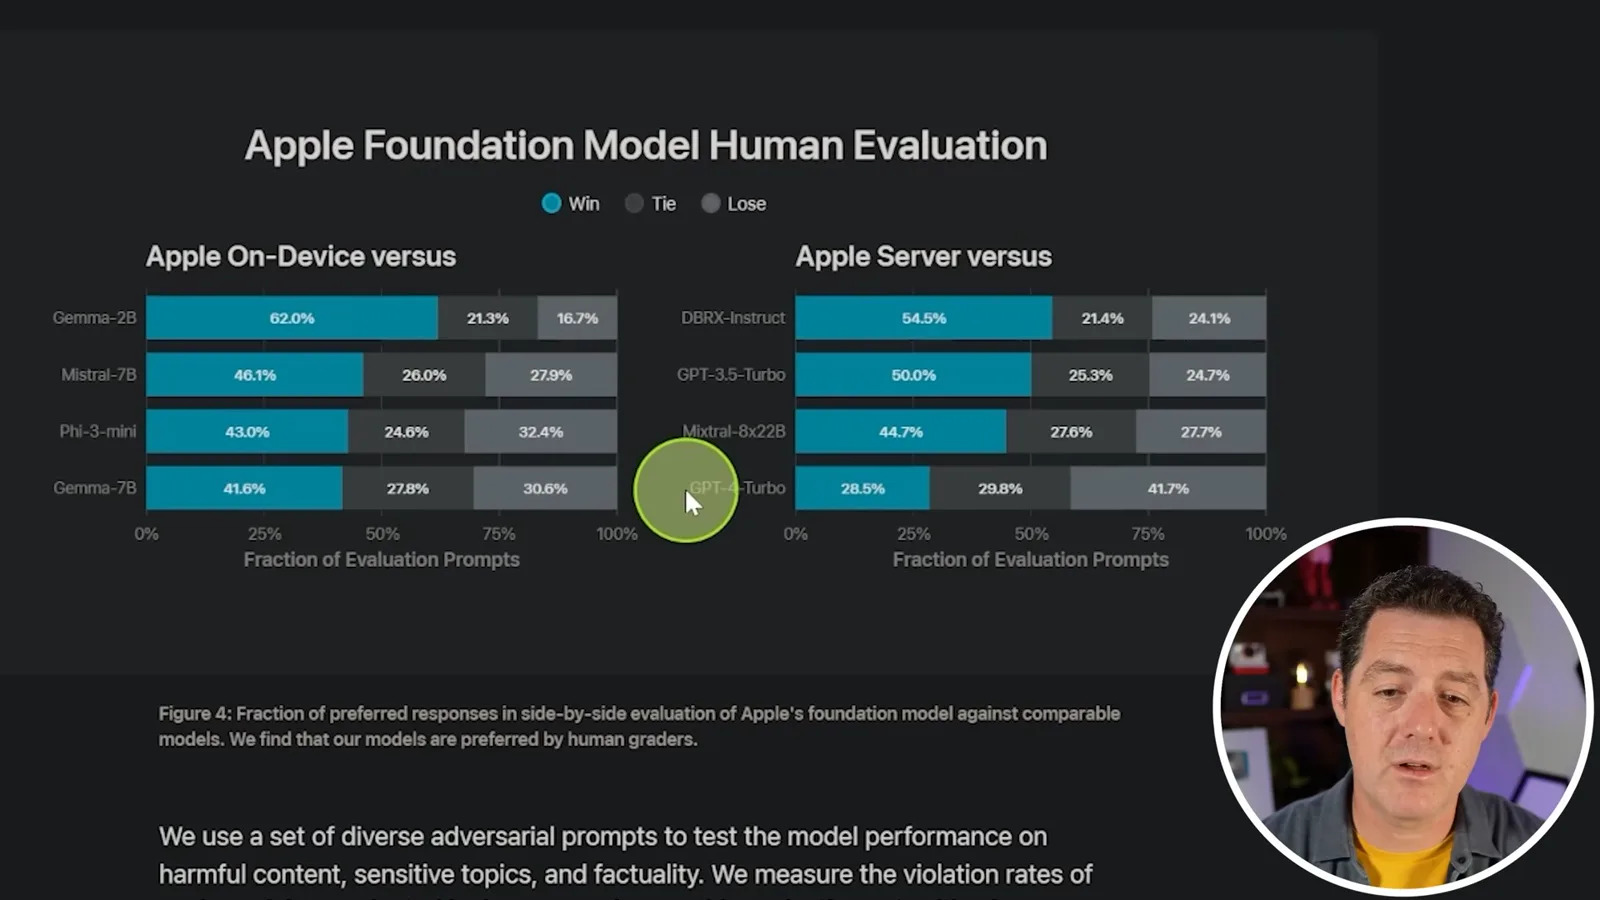
For broader capabilities Apple compares models on prompts such as writing, extraction, coding and reasoning. Its human preference chart reports wins, ties and losses against selected alternatives: the on-device model is preferred to Gemma 2B on 62% of sampled prompts, while its server model loses more often than it wins against GPT-4 Turbo in that chart.
Apple also reports results for harmfulness, safety prompts, instruction following and writing. I describe some safeguards as censorship, but a harmfulness score measures the specific evaluation and is not itself a complete measure of a model's usefulness or refusal behavior. Results can vary with the prompts and scoring.
I'm excited to try the technology, though it was not yet available to me in the iOS 18 version I had installed at the time. My preferred direction is a small local model adapted to everyday tasks and connected to tools that can act on my behalf.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.