30 秒でわかる
In September 2026, Matthew Berman calls GPT-6 Astra his favorite model and illustrates game generation, browser research and writing. He introduces the clip as four things to try but describes three in the available video. The examples are demonstrations and subjective impressions, not a controlled comparison of model quality.
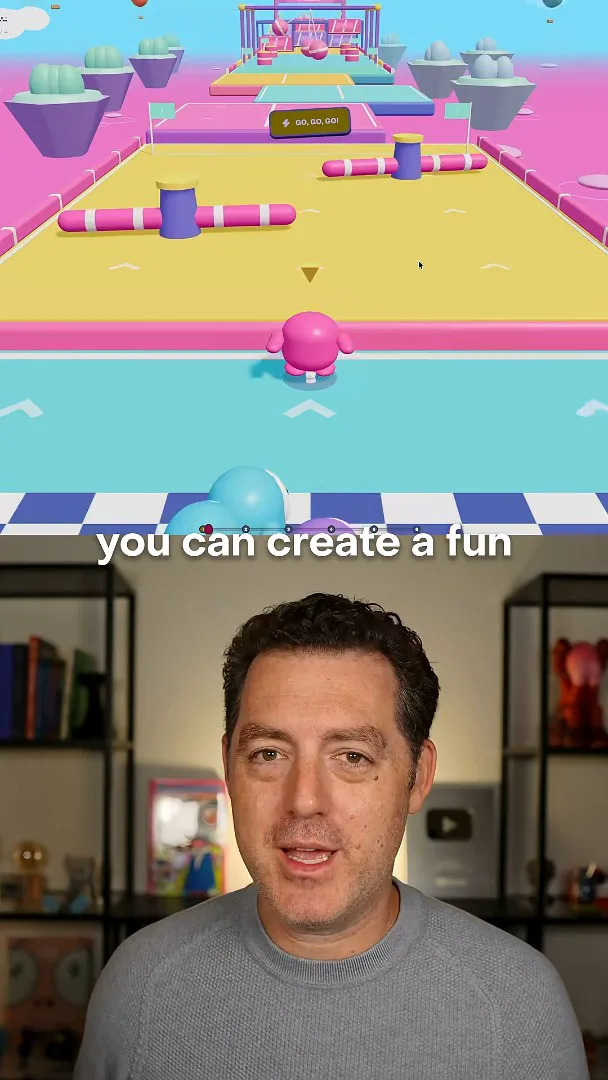
- 1A game from a promptBerman shows a Fall Guys-style game and says a single prompt produced it.
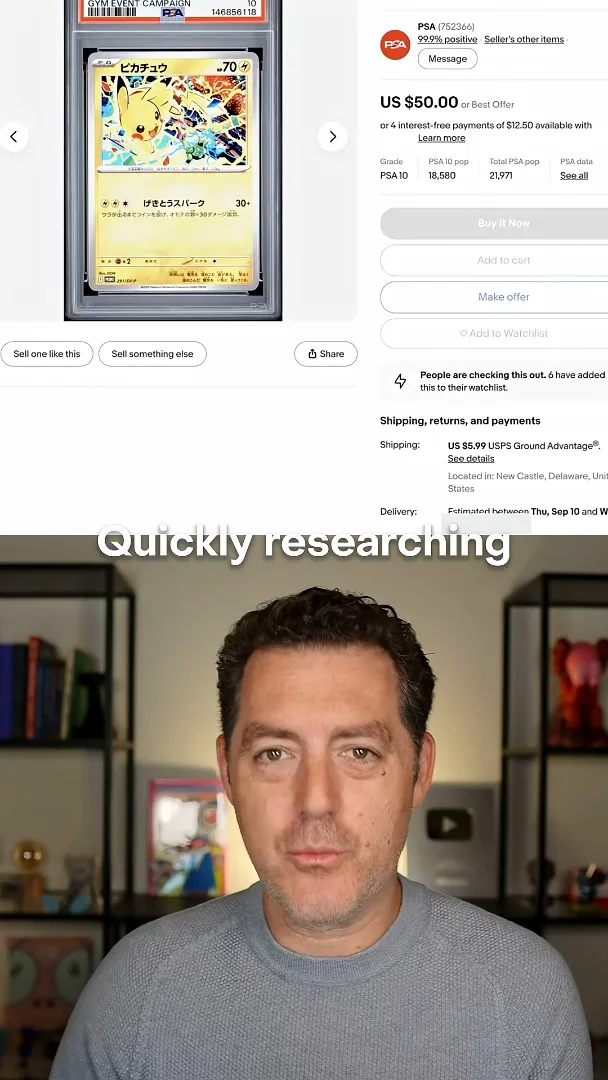
- 2Browser researchHe shows browser use to research and compare Pokémon cards.
- 3Writing styleBerman says he prefers the model’s writing to other models, while acknowledging that it still has recognizable AI characteristics.
ポイント
- Berman shows a playable game resembling Fall Guys and says it was created from one prompt.
- His browser-control example compares Pokémon card listings; the clip does not establish that all details were verified.
- He prefers the model’s writing style, a subjective judgment rather than a benchmark result.
- The video promises four examples but presents three in the available footage.
チャプターごとに整えた全文を読む
Game generation and browsing
Berman introduces the model, shows a game example and describes a browser-research task. These brief demonstrations do not establish general reliability.
I consider GPT-6 Astra the best model I have used and introduce a list of things to try. Although I promise four, the available video describes three examples: creating a game, using browser control and writing. My overall ranking is a personal impression rather than a controlled comparison.
First, I show a playable game resembling Fall Guys and say it was created with a single prompt. The clip illustrates one outcome, but does not show a full evaluation of its quality, completeness or reliability across other game requests.
Next, I show browser control being used to research and compare rare Pokémon cards. The clip demonstrates the workflow at a high level; it does not independently verify the listings or establish that every comparison is correct.
Writing impressions
He gives a subjective comparison of writing style and asks viewers to try the model. The clip presents three examples despite its introduction promising four.
Finally, I say I prefer the model’s writing to that of other models because it has less of the style I associate with AI-generated text. I acknowledge that some remains. That is a subjective judgment about the examples I have seen, not an objective benchmark.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.