30 秒でわかる
An OpenAI engineering acceleration agent ran for six weeks monitoring and fixing flaky CI tests, its operator says. After four days he delegated individual investigations to subagents while the main thread organized incoming failures; he reports 213 fixes merged and more than 600 coordination messages. The speakers explain the tests, project rules, remote environments and spending limits they use to make long-running work manageable.
- 1A short instruction started a six-week CI maintenance runThe operator defined the repository, communication rules and use of CI resources.
- 2Delegating investigations kept new failures movingThe main thread coordinated while subagents worked on individual failures.
- 3A GPU test required days of investigation and researcher inputThe agent correlated logs, reproduced an intermittent failure and contacted the responsible team.
- 4The operator estimated the run at $32 per hourHe says a later model reduced the estimate to $16 per hour; review and CI resources are separate factors.
ポイント
- Give a recurring agent a clear outcome, testable feedback and escalation rules.
- Delegate independent investigations when one difficult issue blocks new work.
- Keep compact notes so interrupted long-running work can resume.
- Set a spending or CI concurrency limit and account for review and infrastructure costs.
チャプターごとに整えた全文を読む
Building 3D scenes over several days
The speakers describe a car model and a racetrack render that resumed after interruptions.
Two OpenAI engineers describe long-running coding agents: one works on engineering acceleration and the other on developer experience. They begin with experiments building interactive 3D scenes.
The developer experience engineer asked Codex and Astra to build an explorable Ferrari model and website from seven reference photographs. He worked with it over several days and says it also produced clay and wireframe views.
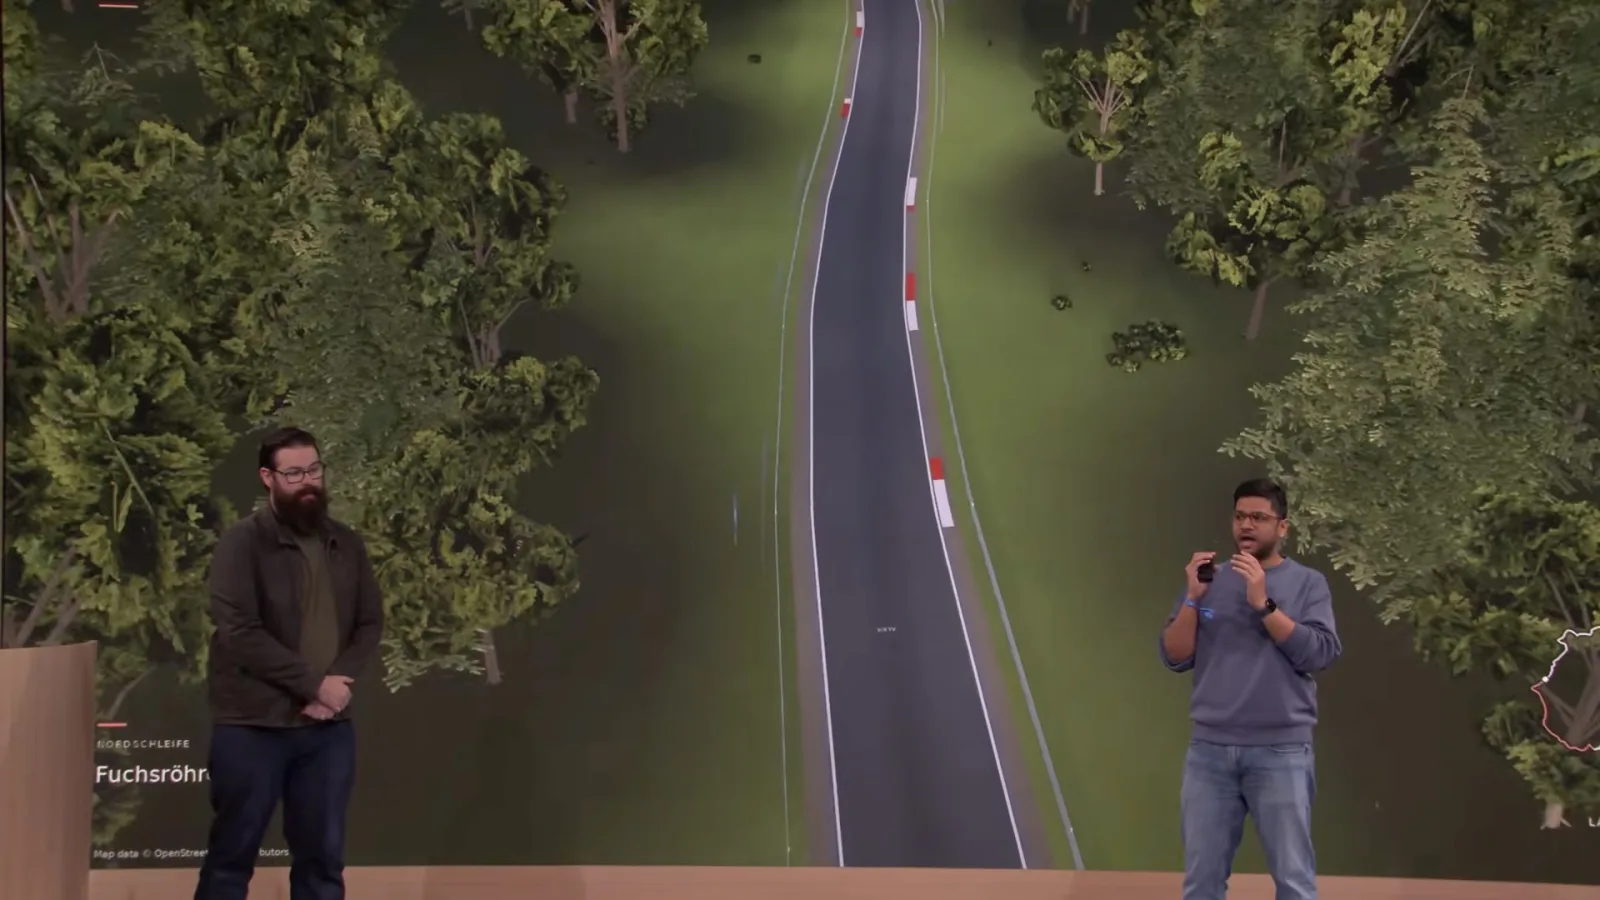
He then asked for a fly-through of the Nürburgring. He says Codex researched the 21-kilometer circuit, used subagents to check geometry and plan rendering, and resumed from saved frames after memory and overheating interruptions.
The engineering acceleration speaker contrasts this with earlier detailed execution plans. With newer models, he says, he is more comfortable specifying the outcome, tradeoffs and success checks while letting the agent choose the steps.
Running CI maintenance for six weeks
An agent monitored flaky tests and delegated investigations. Its operator reports the resulting fixes and coordination.
His team maintains continuous integration, which automatically runs tests on changes. Flaky tests can fail once and pass later, making their causes costly to diagnose while new failures continue to arrive.
He assigned an agent to monitor and fix those failures. He says it ran for six weeks until colleagues started similar agents, beginning from a roughly 200-word prompt specifying the repository, communication and CI-resource rules.
Initially a single thread investigated and fixed issues, but difficult bugs blocked attention to new ones. Four days in, he told it to delegate individual investigations while the main thread collected failures, organized work and communicated.
He reports more than 100 pull requests per week, over 1,000 commits, more than 600 Slack messages and 213 of the agent’s fixes merged over the run. In other cases it recognized a colleague already had a similar fix and prioritized that work.
The run made just under half a million tool calls and used over 5,800 subagent sessions, he says. More than 67,000 calls were waits, reflecting the time needed for tests and CI jobs.
Investigating a difficult GPU test
The agent correlated intermittent failures and collaborated with researchers.
One difficult example involved intermittent floating-point errors in a GPU test. A subagent correlated logs, isolated a particular node and learned to run repeated tests there over several days.
The agent contacted the responsible researchers to ask whether the cause could be an undocumented optimization or faulty hardware. When uncertain about deleting a failing test, it sometimes asked another agent to challenge the proposed change before human review.
Set up long-running work
The speakers describe objectives, tests, logs, remote environments, plugins and parallel chats.
The developer experience speaker recommends one thread per outcome, with a concrete objective and tests that let the agent check its work. He suggests recording project rules and limits in AGENTS.md.
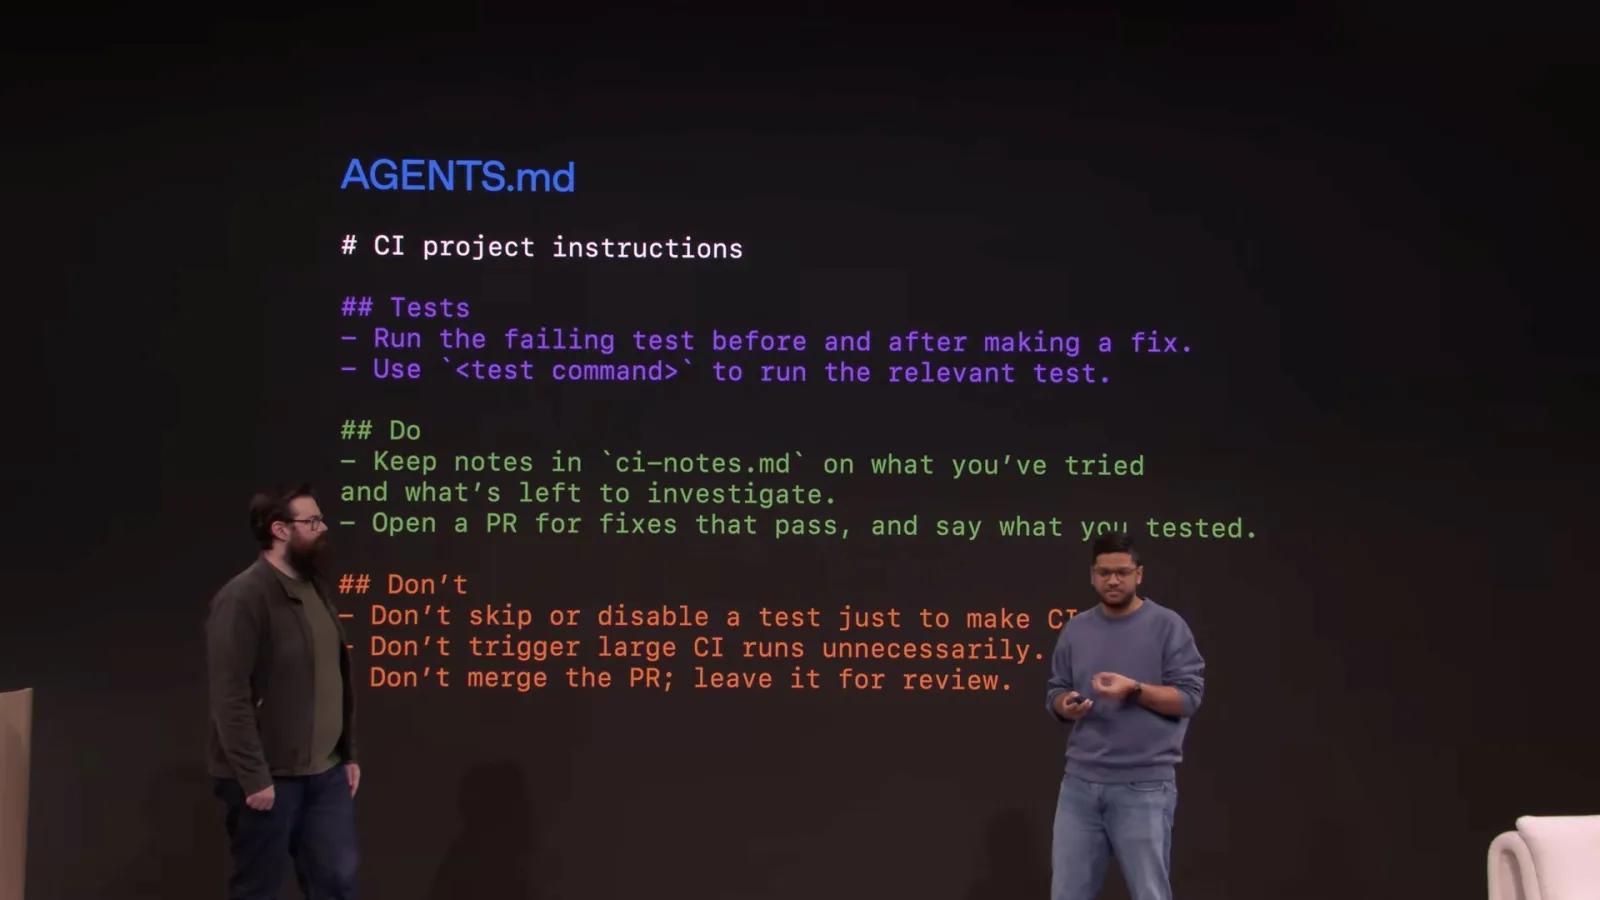
A compact work log can record what was tried and what remains, making it easier to resume after an interruption. Context compaction carries relevant information through a long conversation.
Remote environments let work continue without a laptop running continuously. The speakers describe connecting a remote machine or using Codex Cloud, where an environment can be resumed later.
Plugins can give an agent relevant context from sources such as GitHub or Linear, including existing issues, pull requests and discussions. This helps it avoid working without knowledge of related activity.
A large job can be split into child chats for independent parts, such as a 3D model and its website. Separate worktrees give parallel work separate checkouts; the user can open and steer each chat.
The speakers describe a side thread for questions and a higher-reasoning mode with subagents for hard problems. They distinguish independent work suited to parallel chats from a single difficult investigation.
Follow up, budget and escalate
Scheduled follow-ups handle external waits. The operator discusses estimated costs and boundaries.
When work depends on an external event such as a review, a scheduled heartbeat can revisit the same thread and act on new feedback. A separate scheduled task can instead create recurring summaries.
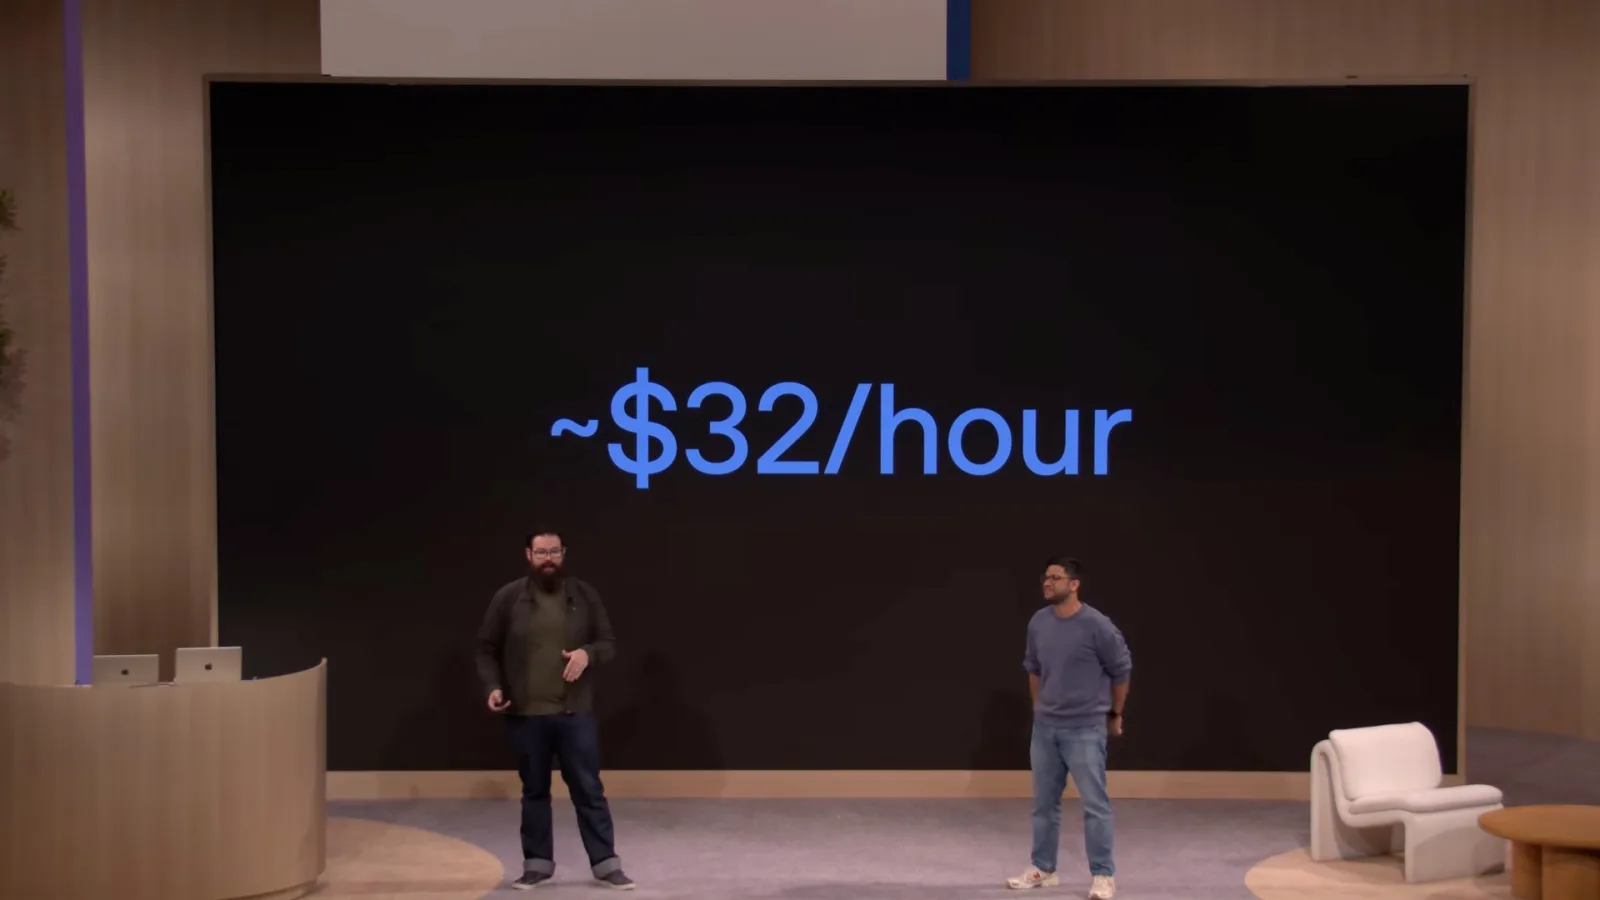
The engineering acceleration speaker estimates the original six-week run at about $32 per hour based on pricing, and says a later model would reduce the estimate to $16. He notes that review and CI resources are additional factors.
To begin, he suggests selecting recurring work, giving the agent tests and a completion criterion, defining when to escalate, and setting a spending or CI concurrency limit.
同じチャンネルの記事
 27:44EN
 OpenAI· 2026年11月11日Plugin extensions bring interactive tools into ChatGPTCorey, Max Neuber · OpenAIOpenAI describes discovery, sidebar and file entry points, event-driven automation and revised submissions.
 24:01ENOpenAI· 2026年11月11日When agent work needs loops, subagents and a shared logRaj, Eric · OpenAIOpenAI’s Raj and Eric explain persistence, when to delegate and how they coordinate longer work.
 22:37ENOpenAI· 2026年11月11日How GPT Live keeps speaking while an agent worksAlex, Erika · OpenAIOpenAI demonstrates simultaneous voice, background delegation and three ways to return updates.
 21:10ENOpenAI· 2026年11月11日How OpenAI turned security findings into verified fixesIan, Kyle · OpenAIOpenAI engineers describe the scan, deduplication and patch verification loop behind Codex Security.
 19:44ENOpenAI· 2026年11月11日What a managed agent harness has to do to keep workingCharlie, Steve · OpenAIOpenAI engineers explain remote sandboxes, long-running state and a human-approved flight rebooking demo.
 20:48ENOpenAI· 2026年11月11日Sites adds personalized connectors and agent-friendly web appsKatia, John · OpenAIOpenAI demonstrates scheduled updates, per-user plugins and WebMCP in two Sites applications.