30 秒でわかる
Samaya AI’s Ashwin Paranjape proposes earnings prediction as a more interpretable test of financial agents than predicting stock prices. His team reports that leading models, given a research harness and point-in-time data, outperformed a bias-corrected analyst-consensus baseline on some metrics across more than 450 earnings releases. The study also found large differences when recent data was withheld. The experiment evaluates reported company metrics, not trading returns or proof that a model can reliably pick stocks.
- 1Earnings offer an observable forecasting taskReported revenue, margins and earnings can be compared with forecasts and analyst consensus.
- 2The harness restricts data to the prediction dateA time gate covers company documents and data; timestamped news substitutes for unrestricted web search.
- 3Some models beat bias-corrected consensus on measured metricsSamaya reports results across more than 450 earnings releases, but the task does not measure trading profit.
- 4Stale information substantially weakens performanceIn one comparison, using data from 11 weeks before earnings reduced performance by roughly 12–15 points.
- 5The strongest model was less dependent on consensus accessIn the reported experiment GPT-6 Astra had no significant difference with or without analyst consensus.
ポイント
- Earnings provide reported outcomes and analyst estimates that make forecasts easier to score than noisy stock prices.
- A point-in-time data gate is intended to prevent the agent from seeing information released after the prediction date.
- Samaya compares forecasts with both raw and bias-corrected consensus across several metrics.
- Leading models performed better on some measured tasks; performance varies by metric and model.
- Recent data and expert guidance improved results in the reported experiments.
チャプターごとに整えた全文を読む
Why predict earnings instead of stocks?
Paranjape describes the difficulty of attributing stock-price movements. Earnings provide quantitative outcomes and an expert baseline.
Ashwin Paranjape introduces his work at Samaya AI, from retrieval and long-context systems to a financial-agent harness and benchmark. He asks whether agents that perform increasingly complex technical tasks can improve financial forecasting.
A colleague with investment experience cautioned against starting with stock-price predictions: prices are noisy, drivers are hard to isolate and an apparently correct prediction may be based on flawed reasoning.
The team chose quarterly earnings instead. Companies report revenue, margins, operating income and earnings per share, while analyst estimates are pooled into consensus; results above or below that consensus are described as beats or misses.
Paranjape sees three advantages for evaluation: a quantitative outcome, a human expert baseline and management commentary that may help explain surprises. He asks whether an agent can make a useful forecast before the release.
A point-in-time research environment
Samaya adapts its production harness to prevent access to future data. The agent researches and forecasts before results are released.
The team built an environment around a research harness. An agent receives a task and historical information, researches the company and produces a forecast that can later be compared with the reported result.
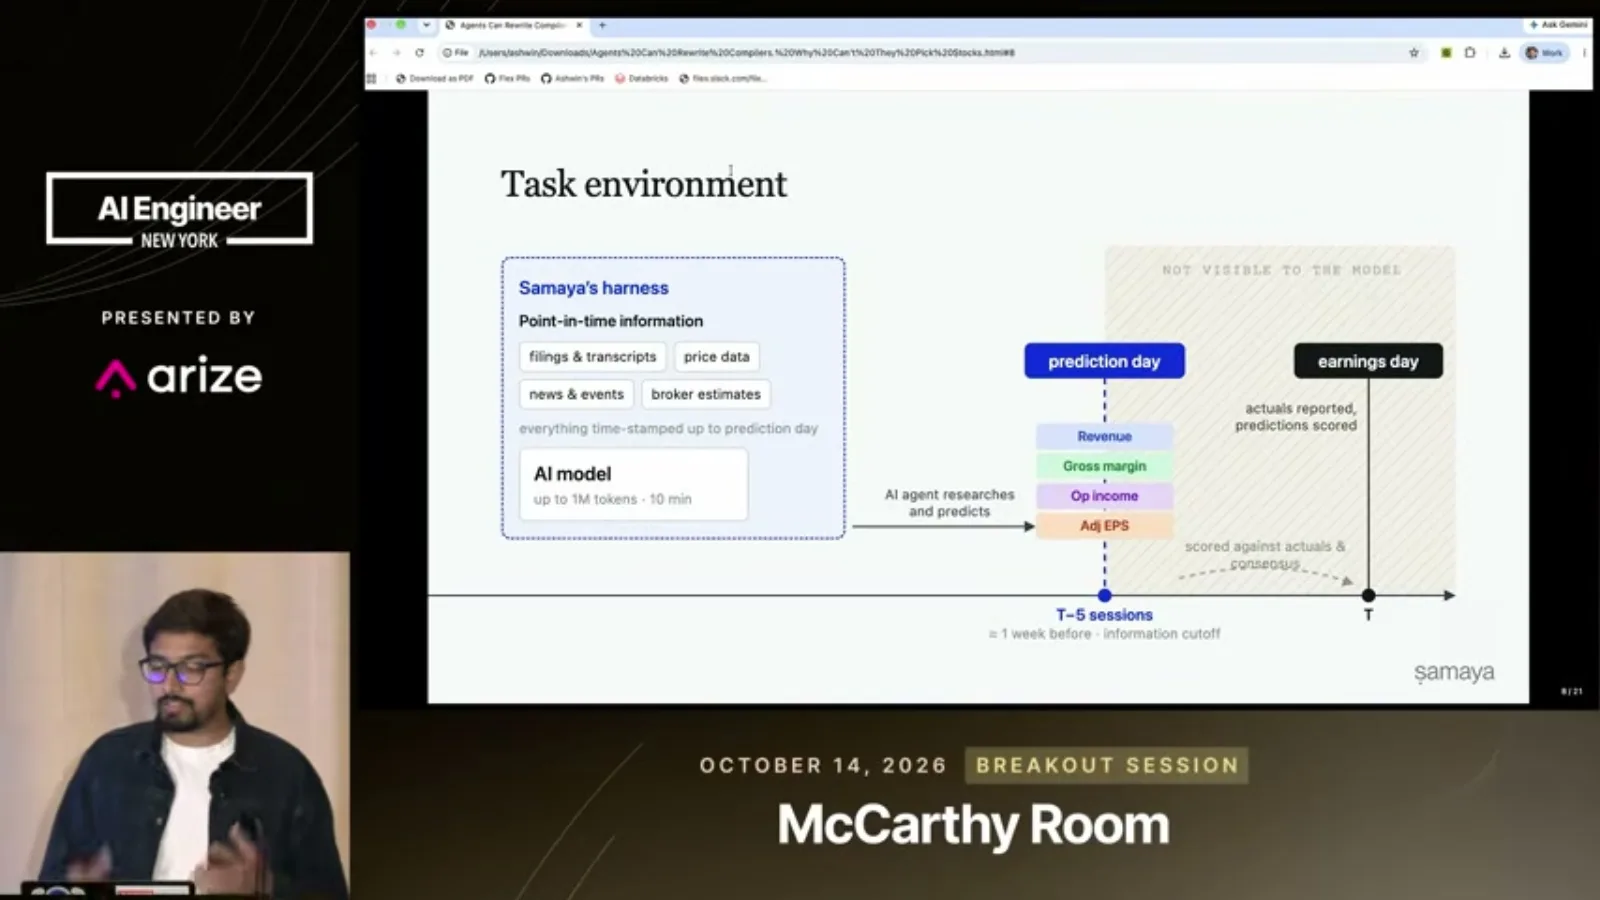
A point-in-time gate limits retrieved information to the selected prediction date, such as five trading sessions before earnings. Samaya modified document retrieval and structured-data tools to support that cutoff.
Unrestricted web search is difficult to constrain retrospectively, so the team instead used additional timestamped news feeds. The harness also provides expert guidance on using context and approaching the prediction.
Results and examples
The team compares seven models with raw and bias-corrected consensus using prediction error, direction and correlation. Examples illustrate successful and missed calls.
Paranjape reports results for more than 450 earnings releases and seven frontier models. The period begins after the newest tested model’s knowledge cutoff, an attempt to reduce the risk that reported outcomes were already in its training data.
The first metric is prediction error normalized by each company’s historical volatility. The comparison includes raw analyst consensus and a bias-corrected consensus intended to account for the tendency of many reported results to exceed estimates.
In the revenue comparison, Paranjape says GPT-6 Astra significantly outperformed even the bias-corrected baseline. Results vary across revenue, gross margin, operating income and adjusted earnings per share; not every difference is statistically significant.
The team also measures hit rate: whether a forecast correctly calls a result above or below consensus. For below-consensus outcomes, it compares models with a baseline based on the company’s majority outcome in the previous eight quarters.
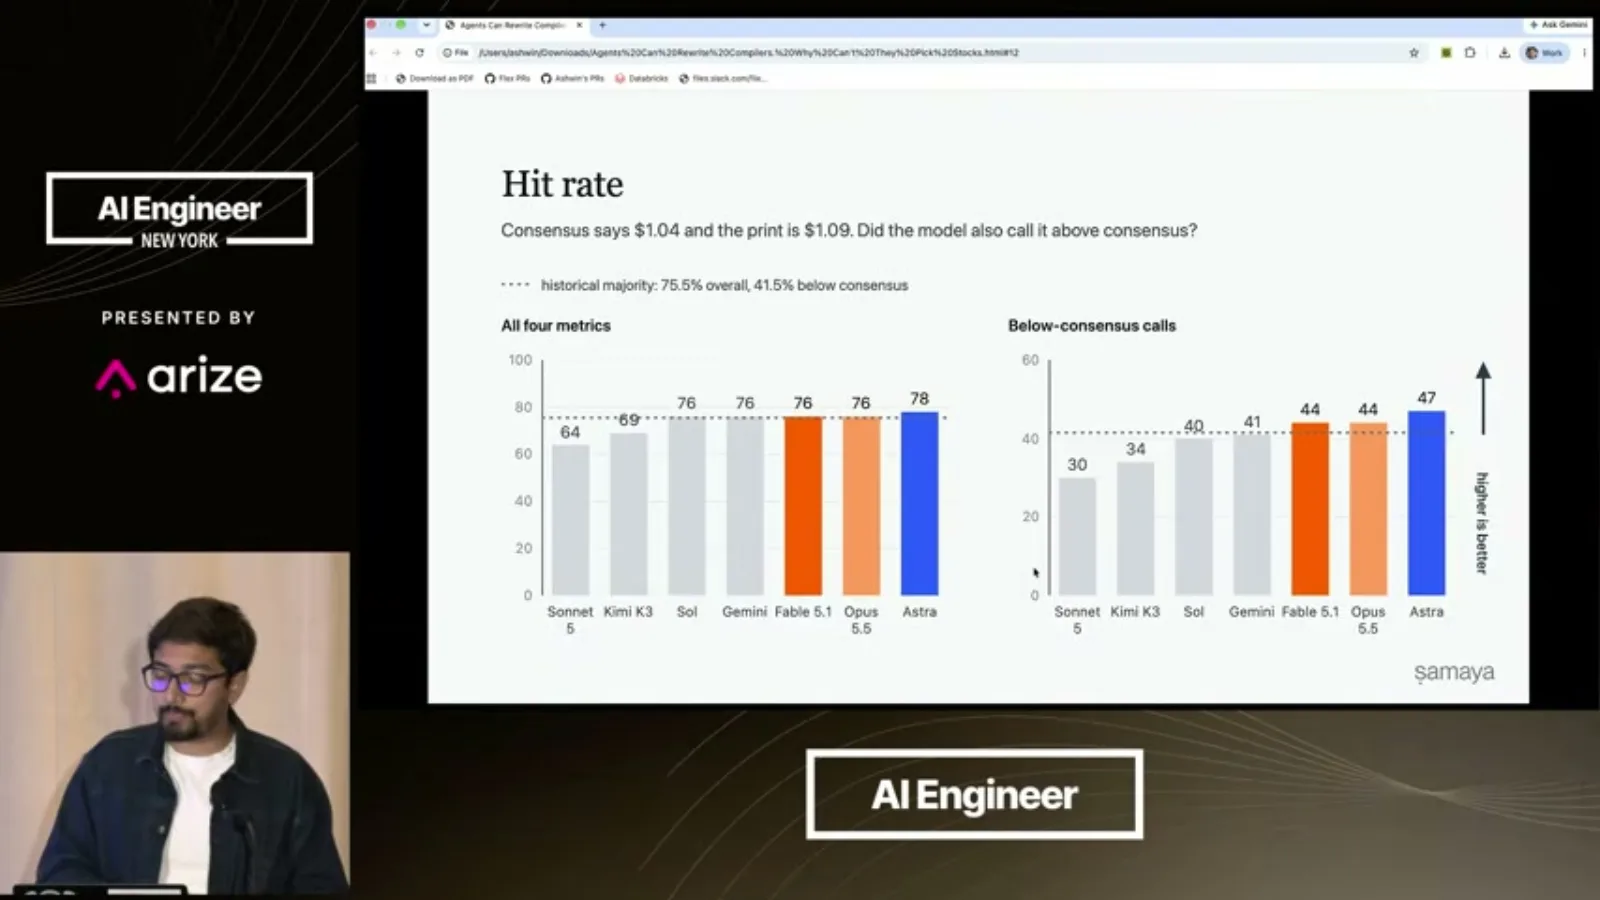
A third metric, surprise correlation, measures whether predicted surprises line up with actual surprises in direction and magnitude. Paranjape says the leading models outperform the baseline on that measure, while their differences from one another are not statistically significant.
For an example of a good forecast, he describes a semiconductor supplier to data centers. The agent found timely information from a smaller supplier, incorporated it into an income-statement forecast and moved above consensus toward the eventual result.
A missed example concerns Ross Stores. The agent found information about a peer’s tariff refund but did not incorporate it into the gross-margin forecast; its estimate remained near consensus while the reported result was much higher.
Paranjape says the models’ strongest departures above or below consensus were particularly interesting when actual surprises were large. The examples illustrate possible reasoning patterns, but a few cases alone do not establish a trading strategy.
Data freshness and guidance
Experiments compare current versus stale data, expert guidance and access to consensus. Paranjape outlines possible research directions.
The team next tests data freshness. A model using only its stored parametric knowledge performs poorly on the task, despite pretraining that may have included earlier documents.
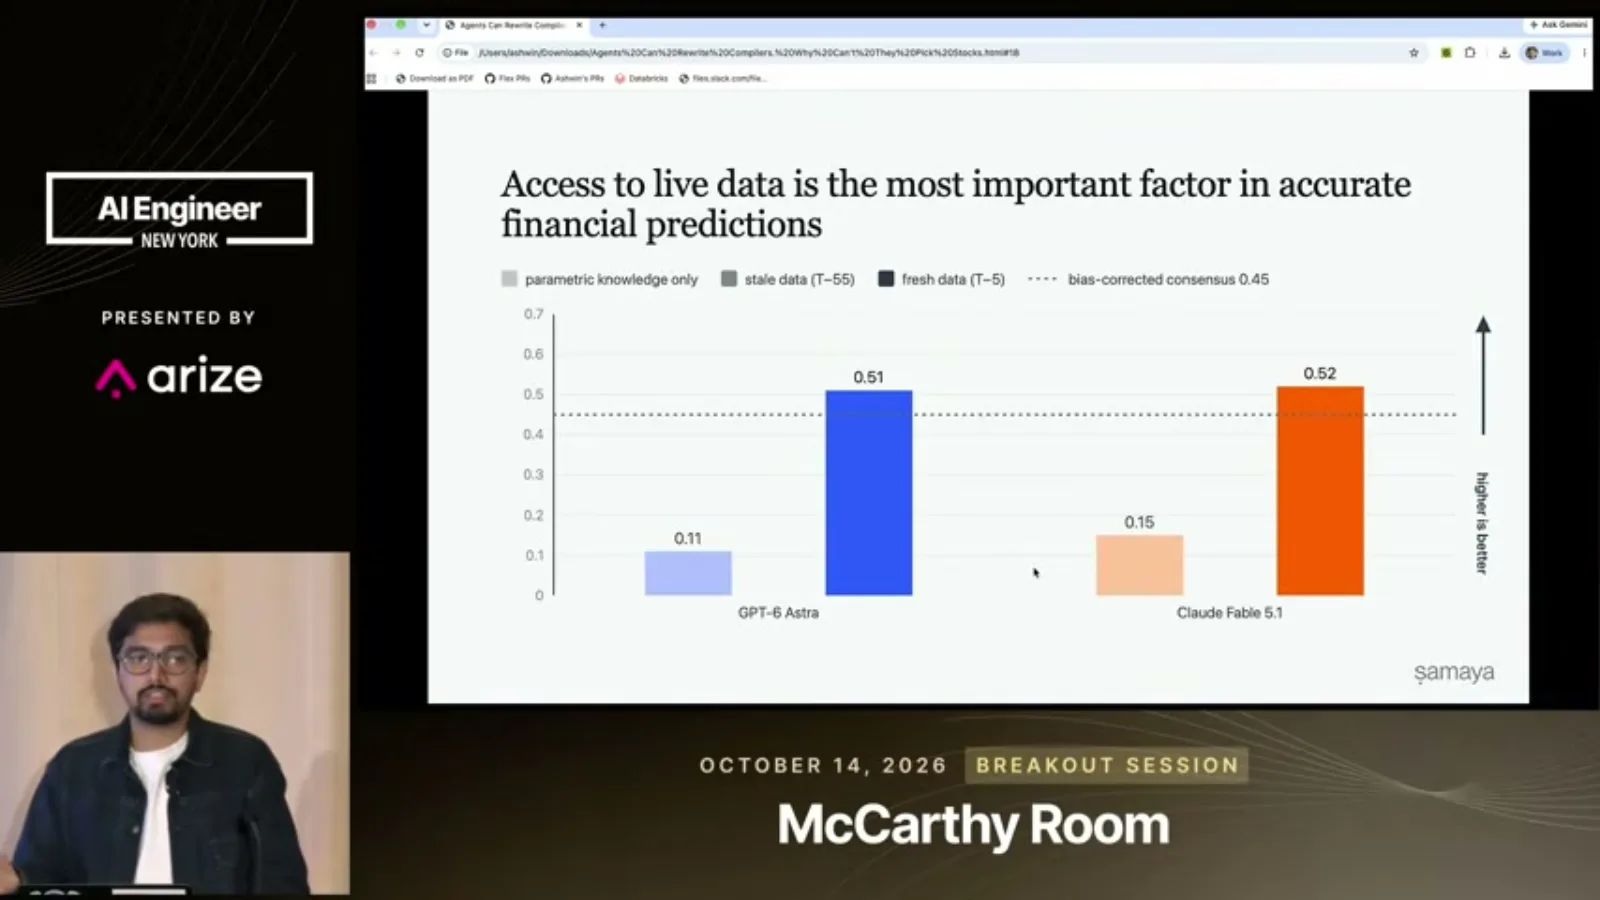
Using data from about 11 weeks before the release, rather than the latest available information, reduces performance by roughly 12 to 15 points in the comparison he describes. He compares the size of that gap with the gap between two model generations.
Expert guidance led agents to spend more time and tokens on research. Paranjape reports a statistically significant improvement in prediction error for GPT-6 Astra under the guided setup.
The team also withheld analyst consensus, including redacting mentions from retrieved sources. The best model’s result did not differ significantly with and without consensus; Paranjape suggests it may reconstruct aspects of that view from other information.
Samaya is testing the forecasting capability with customers and studying whether internal data can help. Future research includes examining model reasoning, combining it with human analysis and learning from prior mistakes.
Paranjape points to the company’s public research and FrontierFinance benchmark for further details. The reported study predicts company earnings metrics; it does not establish that the agent can reliably pick stocks or earn risk-adjusted trading returns.
同じチャンネルの記事
 19:41EN
 AI Engineer· 2026年11月9日A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 22:01ENAI Engineer· 2026年11月9日Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· 2026年11月9日Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 15:25ENAI Engineer· 2026年11月9日Hassan and Omar El Mghari: When an AI financial forecast is right for the wrong reasonsHassan El Mghari, Omar El Mghari · Together AIA Costco membership-fee model passed basic checks and landed close to reported results, but an audit uncovered offsetting assumptions.
 14:38ENAI Engineer· 2026年11月9日Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· 2026年11月9日Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.