30 秒でわかる
In this November 2024 video sponsored by Dell and NVIDIA, Matthew Berman compares three coding models using LM Studio on a workstation with two RTX A6000 GPUs. Qwen produces his preferred Snake game and the highest displayed generation speed, while all three struggle with Tetris, a difficult regular-expression challenge, and a prime generator’s time limit. All pass the letter-shift and sorted-array median tests after the adjustments shown; this small, uneven test does not establish a universal ranking.
- 1Three locally run modelsBerman compares DeepSeek-Coder-V2 Lite, Yi-Coder 9B Chat, and Qwen2.5-Coder 7B using LM Studio.
- 2Snake favors QwenThe Qwen-generated version works best in the presenter’s trial, including an observed self-collision game-over.
- 3Tetris remains difficultThe attempts either need manual repair, freeze, or still fail after a requested fix.
- 4A simple challenge passesAll three pass the letter-shift challenge after the displayed naming adjustments.
- 5Harder challenges expose limitsNone passes the regex task completely, and the prime generators time out under the test constraints.
- 6Median challengeAll three pass the final sorted-array median test, with the DeepSeek attempt corrected for the expected interface.
ポイント
- The three models are DeepSeek-Coder-V2 Lite, Yi-Coder 9B Chat, and Qwen2.5-Coder 7B; their architectures and total parameter counts differ.
- Qwen’s generated Snake game works best in this demonstration, while no model produces a satisfactory Tetris game in the attempts shown.
- All three pass the letter-shift challenge and the final median challenge after the presenter’s necessary interface adjustments.
- The hard regex attempts fail some tests, and the prime generators time out under the challenge’s limits.
- Reported generation speeds are observations on the sponsor-provided workstation and cannot be generalized to other hardware or settings.
- The video is sponsored by Dell and NVIDIA, and its small set of prompts is not a controlled coding benchmark.
チャプターごとに整えた全文を読む
Models and sponsored hardware
Berman introduces the three coding models and his Dell workstation with two NVIDIA GPUs. He uses LM Studio for local inference.
I am comparing three models for local coding: DeepSeek-Coder-V2 Lite, Yi-Coder 9B Chat, and Qwen2.5-Coder 7B. I will try game generation and programming challenges. This video is sponsored by Dell and NVIDIA, which supplied the workstation; the comparison is an informal set of examples from November 2024, not a comprehensive benchmark.
The Dell Precision 5860 has two RTX A6000 GPUs with 48 GB of VRAM each, and I load all three models in LM Studio. Their architectures are not identical: [DeepSeek-Coder-V2 Lite](https://huggingface.co/deepseek-ai/DeepSeek-Coder-V2-Instruct) is a 16B-parameter mixture-of-experts model with about 2.4B active parameters, while the other names describe 9B and 7B models. Capacity and speed depend on quantization, hardware, and software configuration; two GPUs do not automatically behave as one pooled memory device in every setup.
Snake and Tetris
The models generate Python games, with Qwen producing the most successful Snake attempt. None completes Tetris satisfactorily in the demonstrated runs.
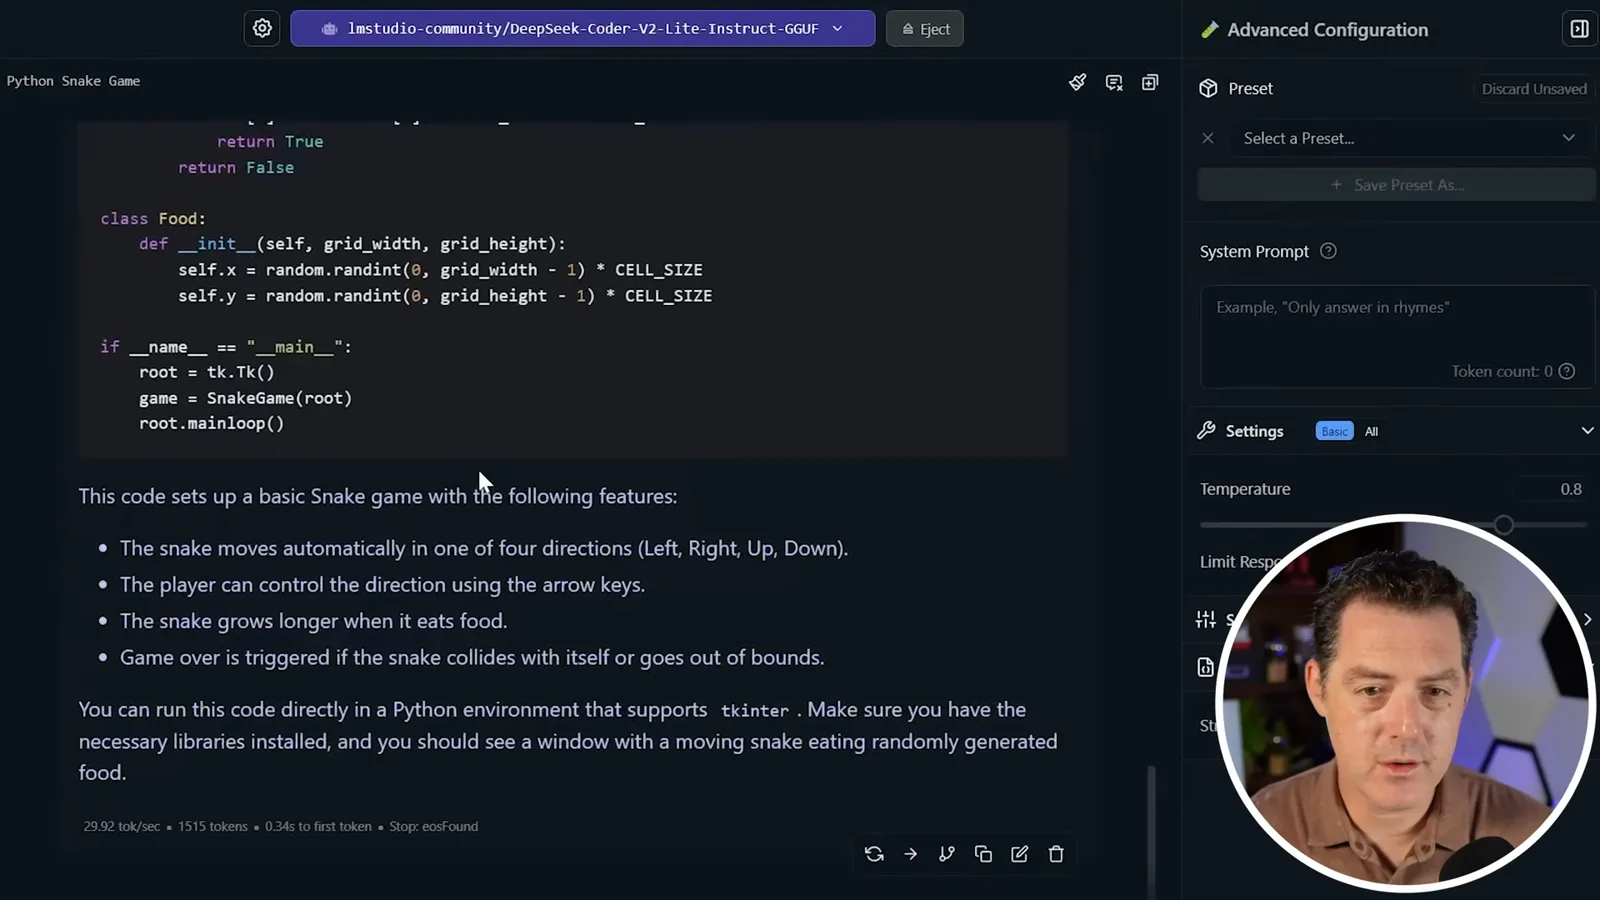
Local inference can work without an internet connection once the models and necessary software are available. I start by asking DeepSeek to write Snake in Python. It generates a tkinter version at roughly 30 tokens per second on this machine. The game opens, but it does not behave as I expect, so loading alone is not a complete success.
Yi-Coder generates its Snake game with the turtle library at roughly 50 tokens per second. The game works better in my trial, although the pixels do not line up cleanly and I do not find a way to lose. These displayed speeds describe particular generations on this workstation, not a controlled throughput study.
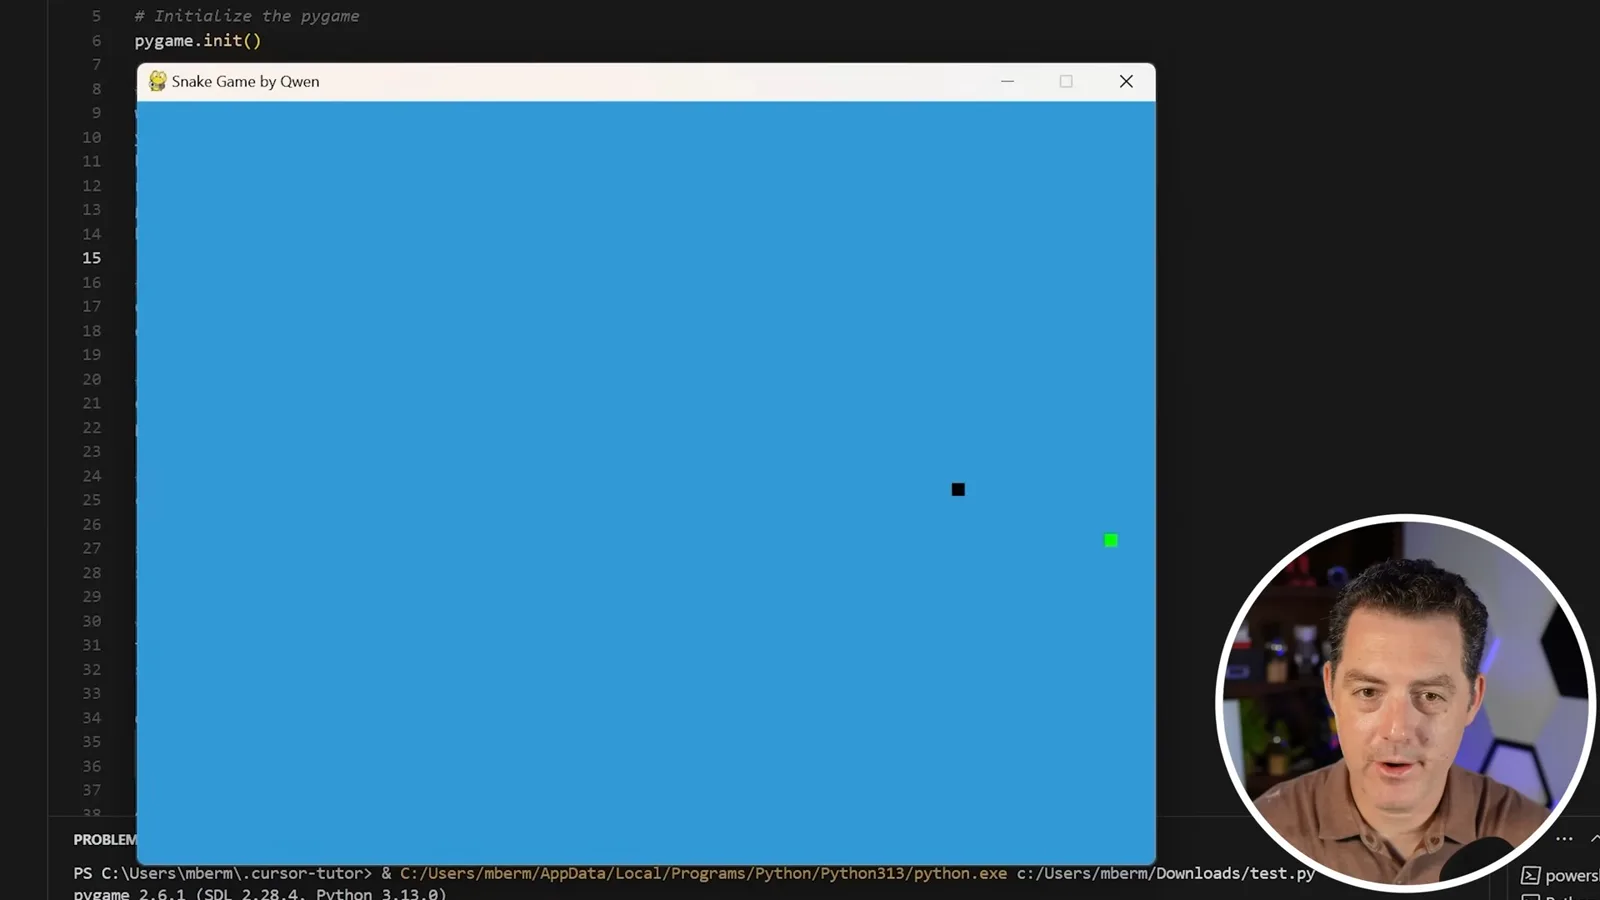
Qwen2.5-Coder uses Pygame and generates at nearly 70 tokens per second in this run. After addressing a missing Pygame module, I run the game: the visuals line up, and colliding with the snake’s own body ends the game. I judge this the strongest Snake attempt of the three.
Next I ask each model for Tetris. DeepSeek’s code uses Pygame without importing it, so I add the import manually; the game starts but is laggy and appears to provide only one piece. Yi-Coder’s attempt does not work and freezes. These tests include human intervention and do not use identical repair steps for all models.
Qwen’s Tetris code also errors. I feed the error back to the model, replace the suggested main function, and try again, but it still fails. None of the three produces a satisfactory Tetris game in the attempts shown, although this is not evidence that they cannot solve the task under different prompts or iterations.
CodeWars challenges
All three pass a simple letter-shift task. A difficult regex problem and an efficient prime generator expose failures and timeouts.
I move to Codewars and request a function that advances every letter ten places through the alphabet, wrapping around after z. DeepSeek initially uses a different function name; after I rename it to the expected interface, its solution passes. Yi-Coder passes as well, and Qwen passes after I adjust its function name.
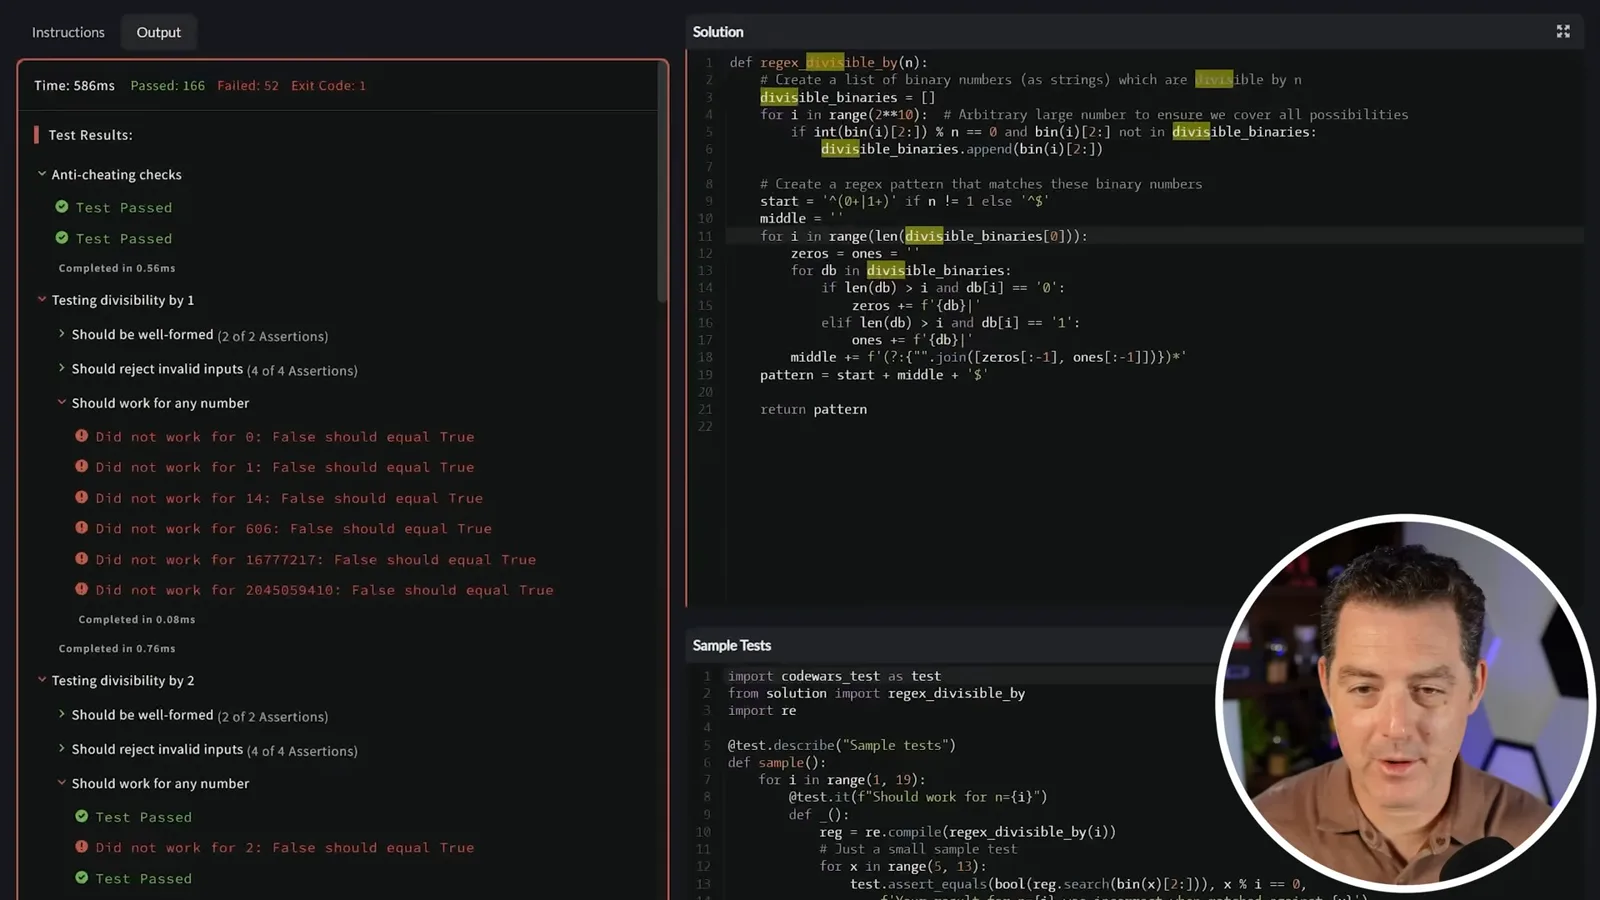
For a much harder Codewars task, I ask for a regular expression that matches binary numbers divisible by a given number. DeepSeek first encounters restrictions on libraries, so I request a version without them; the revised submission passes 166 tests and fails 52. I give Yi-Coder more explicit instructions about the method name and libraries; it still fails tests, as does Qwen. Because the prompts and revisions differ, the displayed counts are not a controlled head-to-head score.
The next challenge asks for an endless prime-number generator fast enough to produce a million primes in a few seconds. DeepSeek passes some checks but times out; Yi-Coder and Qwen also fail to finish within the shown test limit. I wonder aloud whether the requirement is possible in Python, but these three attempts do not establish that it is impossible.
Median of two sorted arrays
All three models pass the final median test in the shown attempts. Berman favors Qwen for the observed speed and Snake result.
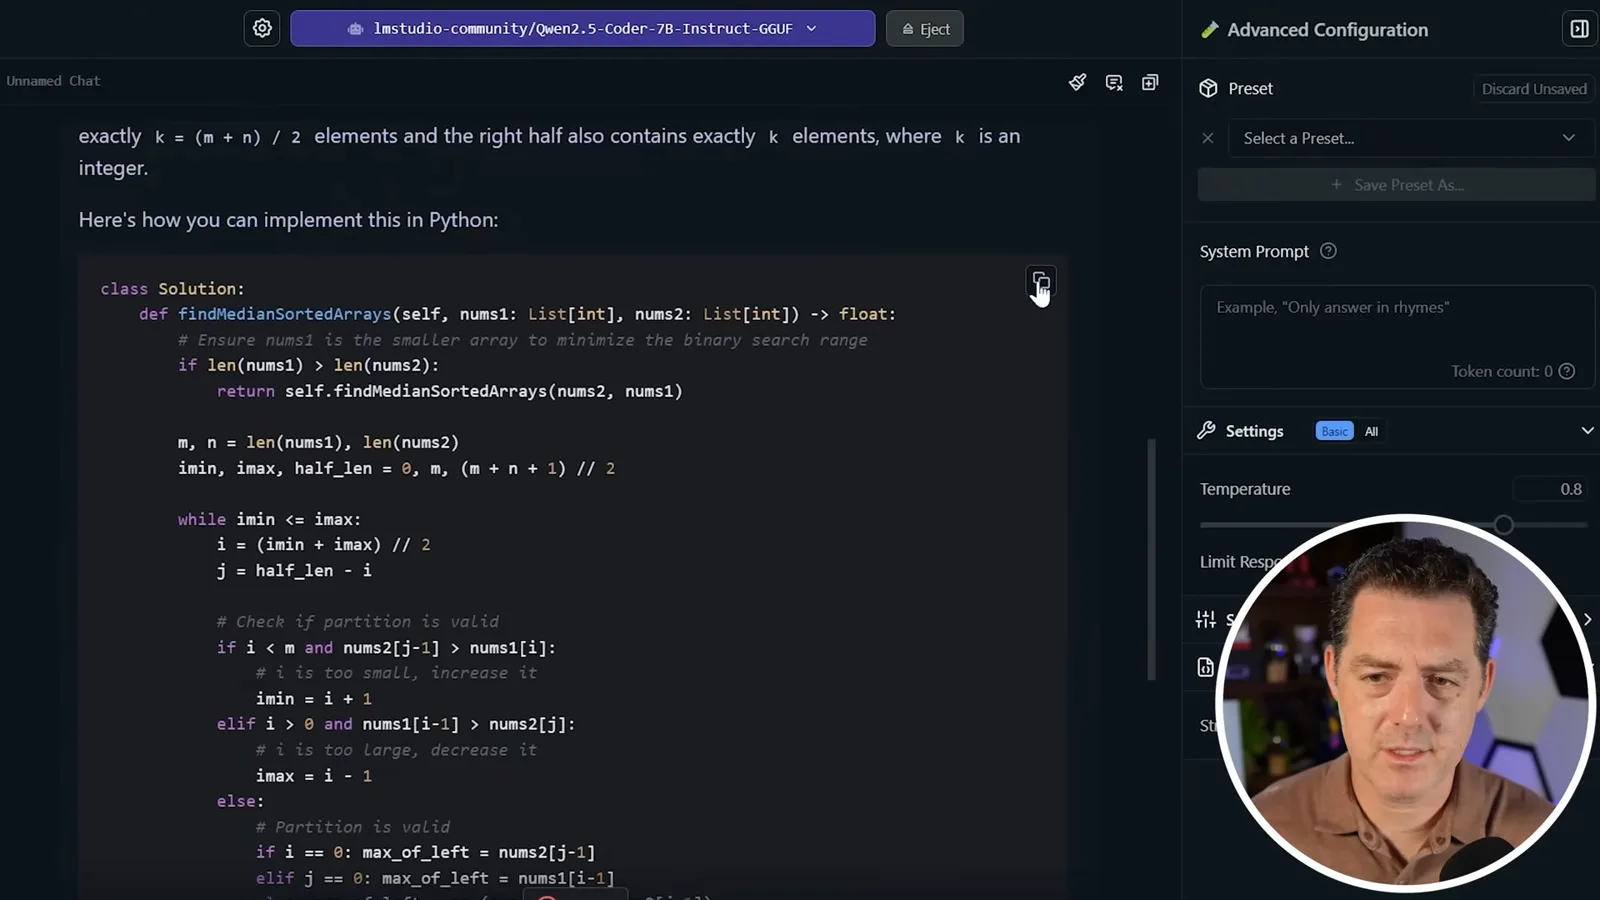
Finally I ask for the median of two sorted arrays with the stated logarithmic complexity requirement. My first DeepSeek run has an argument error because I did not specify the expected method structure, so I clarify it and rerun; it passes. Yi-Coder and Qwen also pass the displayed tests. Passing a test suite is evidence for those cases, though the clip does not independently prove complexity for every input.
For this set of tests, I prefer Qwen2.5-Coder 7B because it was fastest in the displayed runs and produced the best Snake game. I ask viewers what more useful coding tests they would suggest. That is a practical preference based on a few examples and this hardware, not proof that one model is best for all developers or workloads.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.