30 秒でわかる
In July 2026, Matthew Berman argues that a low token price does not automatically mean a low cost per task. He illustrates a mixed-model coding workflow and offers predictions about open and closed model economics; the budget figures are hypothetical and the displayed benchmark chart measures average cost per task.
- 1Average benchmark task costThe chart shows approximately $0.95, $1.04 and $2.75 for three displayed configurations; it does not say cost per successful task.
- 2Cross-model reviewA sponsor’s study reports better bug recall across models in its sample; it does not guarantee defect-free code.
- 3Plan, implement, reviewBerman suggests assigning a strong model to planning, a cheaper one to implementation and another strong model to review.
- 4Hypothetical budgetThe illustrative mixed-model total is $25.55 under specified assumptions; quality and rework were not measured.
- 5Open-model competitionBerman predicts competitive hosting of downloadable models could reduce prices, a scenario rather than a guaranteed result.
ポイント
- Token prices alone do not determine the cost or quality of a completed task.
- The displayed benchmark chart reports weighted average cost per task, not necessarily per successful task.
- A three-stage coding workflow can use different models for planning, execution and review, but needs evaluation on real work.
- The displayed $25.55 mixed-model total is a hypothetical estimate, not proof of equal quality or realized savings.
- Latency, retries, caching, context transfer and human review affect total workflow cost.
- Berman’s forecasts about open-model competition are opinions about future market dynamics.
チャプターごとに整えた全文を読む
Tokens and price
Berman explains tokenization and compares historical input and output prices. He argues that total task cost matters more than a price per token alone.
In this July 2026 video, Matthew Berman argues that effective AI use requires more than comparing the price of a million tokens. Different models can use different numbers of tokens, take different amounts of time and achieve different results on a task. He proposes choosing models for each stage of a workflow instead of using the same model everywhere.
A token is a unit a model processes, not necessarily a whole word. Berman shows a tokenizer where a simple sentence splits roughly into words, while “programmatic” splits into smaller pieces. Autoregressive language models generate sequences by predicting successive tokens; tokenization depends on the model and text.
Berman compares the prices visible in the video: GPT-5.6 Sol at $5 per million input tokens and $30 per million output tokens, versus his quoted Kimi K3 prices of $3 and $15. Those are historical examples, not a current price quote; rates can differ by provider, context length, caching and service tier.
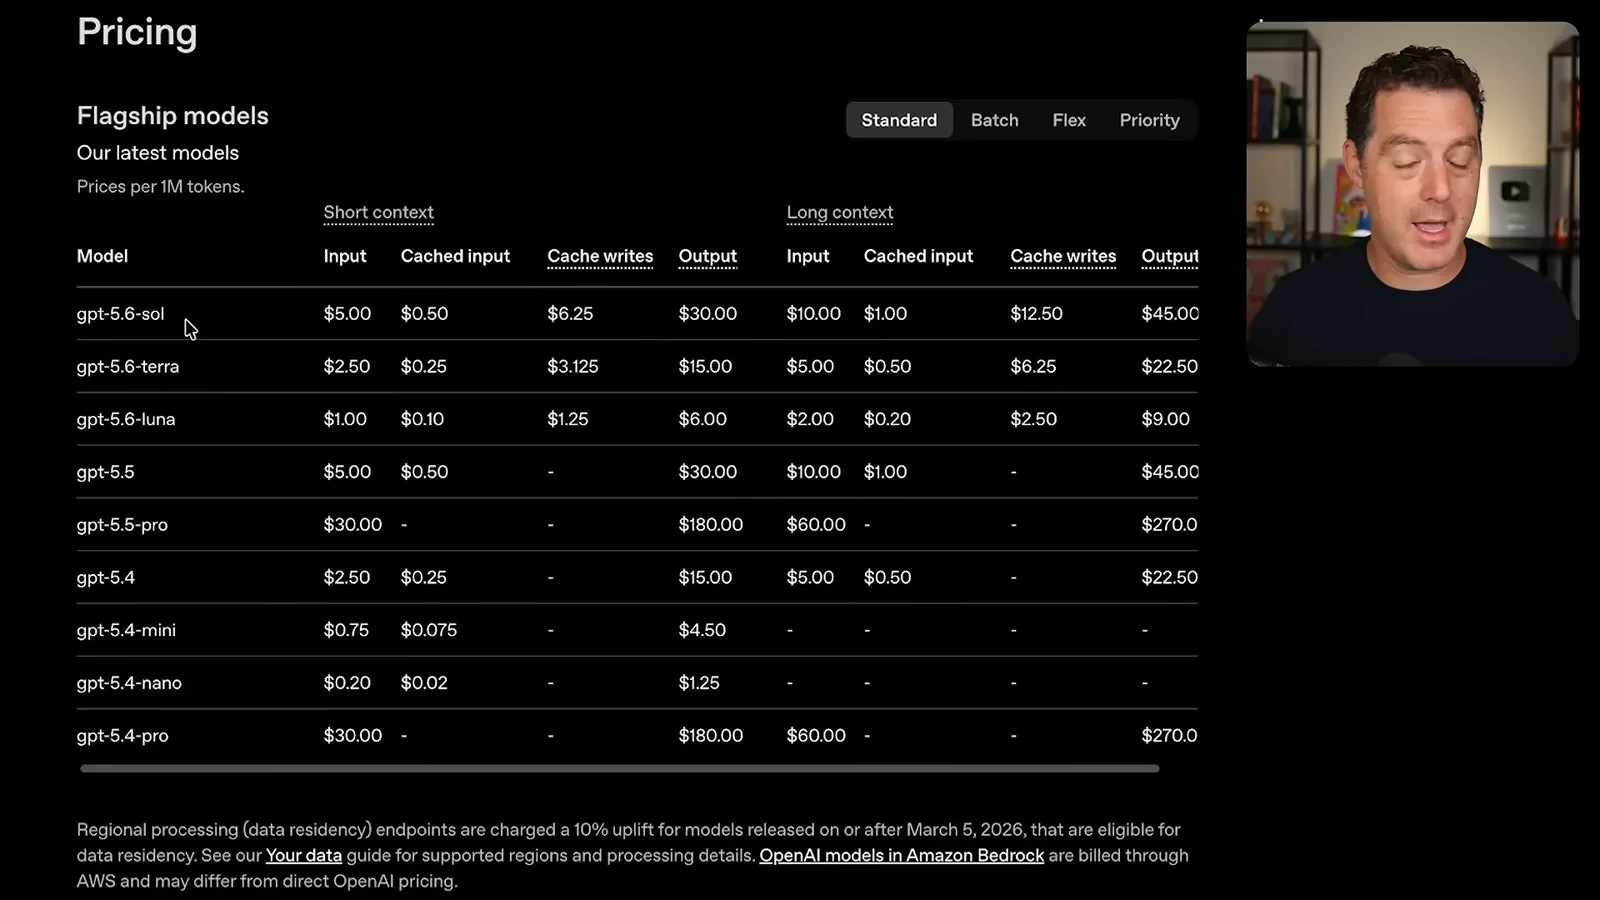
Benchmark costs and model differences
An Artificial Analysis chart shows average costs per benchmark task. Berman discusses model-specific strengths and a sponsor’s cross-model review comparison.
Benchmark scores can look competitive even when token prices differ. Berman’s point is to consider the total cost of a useful outcome, including how much each model generates. Similar scores on selected tests do not guarantee equal reliability or quality for a particular application.
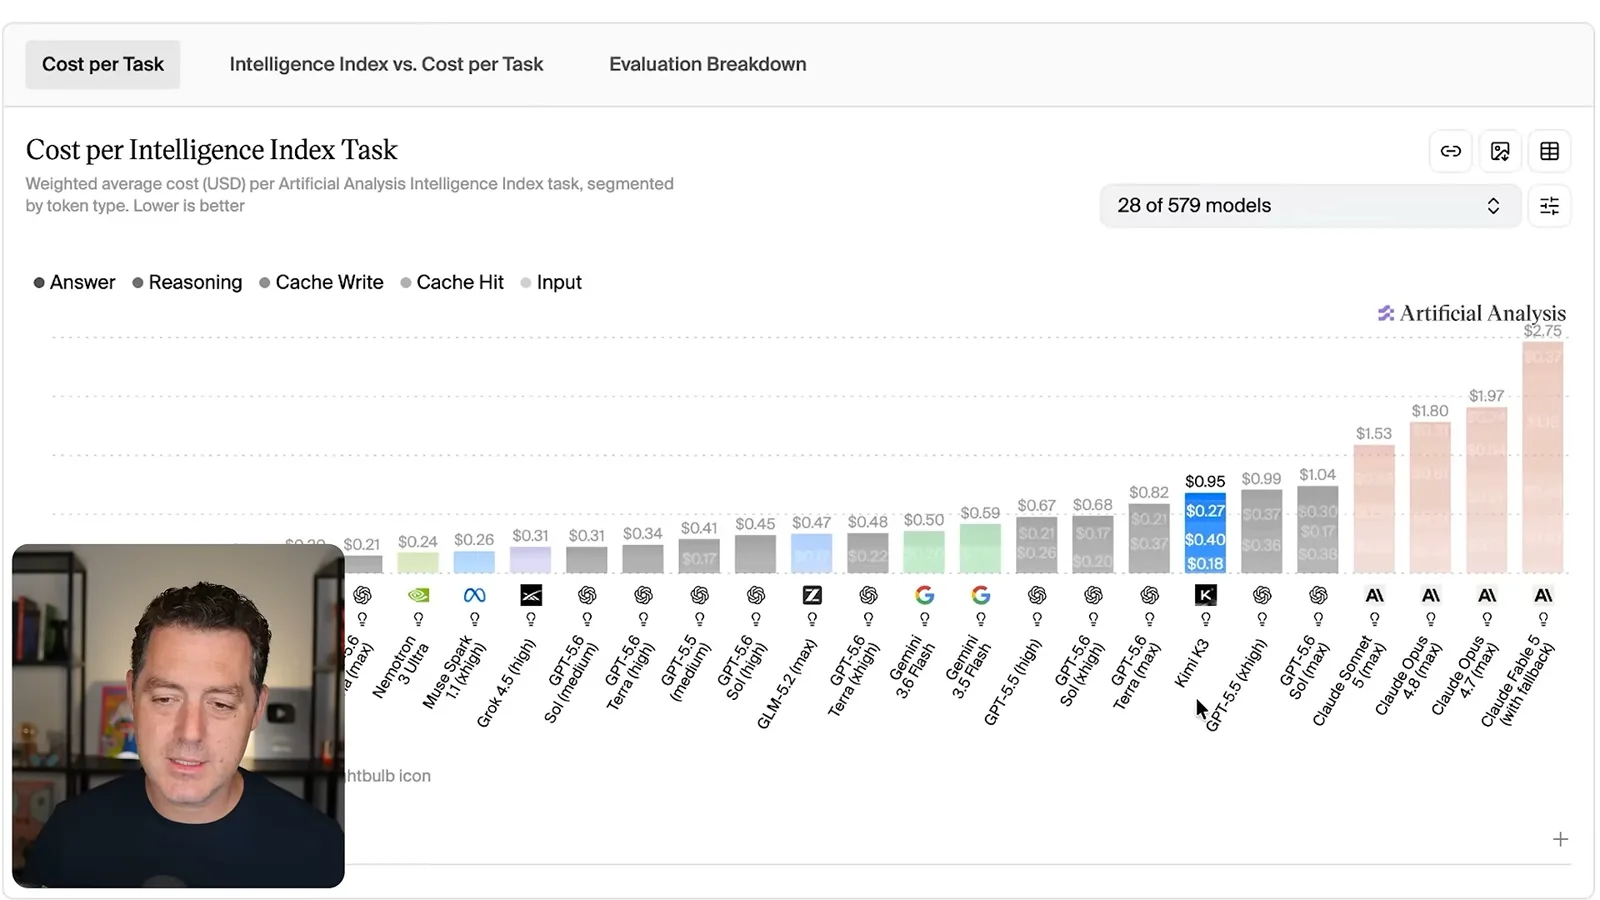
The Artificial Analysis chart shown in the video labels its metric the weighted average cost per Intelligence Index task: about $0.95 for Kimi K3, $1.04 for GPT-5.6 Sol and $2.75 for Claude Fable 5 in the displayed configurations. These are costs per benchmark task, not necessarily costs per successfully solved task. The comparison is tied to that benchmark, model settings and pricing.
Berman interprets the similar task costs as an example of a cheaper token price being offset by greater token use. He illustrates it with one million output tokens at $30 versus two million at $15 per million, both costing $30. This is illustrative arithmetic, not a demonstrated universal two-to-one token ratio across tasks or a complete calculation of input, caching and retry costs.
He calls this “intelligence density” and offers his opinion that OpenAI’s models lead on it in his experience. That is his interpretation, not a standardized property of individual tokens. Measuring quality, success rate, total spending and latency on the actual workload provides a more useful comparison.
Berman argues that models have different strengths and suggests using one to review code produced by another. In a sponsored section, he cites Greptile’s comparison of Claude Opus 4.7 and GPT-5.5: in its displayed sample, each reviewer found a greater share of high-severity bugs in the other model’s pull requests than in its own. The vendor’s finding is limited to its study and does not guarantee independent review will catch every defect.
A three-model coding workflow
Berman proposes planning, execution and review with different models. His budget is a hypothetical based on assumed token counts, not a controlled quality test.
Speed matters too: a lower API bill can come at the cost of a longer wait. Berman uses a hypothetical 30-minute versus one-hour task to illustrate why a team should weigh latency and human time as well as model charges. Actual completion time depends on the provider, throughput, workload and retries.
For difficult coding tasks, Berman describes three stages: use a strong model to plan, a cheaper fast model to implement, and a different strong model to review. In his example Claude Fable produces a specification after examining the codebase, a cheaper model such as Grok 4.5 or Cursor Composer executes it, and GPT-5.6 reviews the result against the specification.
His rationale is that planning requires broad context and judgment, while implementation may generate a large volume of expensive output tokens. A reviewer then reads substantial material but produces a relatively short assessment. This is a useful division of labor to test; the assumption that implementation is always easy or needs only the plan will not hold for every codebase.
Berman presents a hypothetical budget: one million input and 100,000 output tokens for planning, 100,000 input and one million output for execution, then one million input and 100,000 output for review. His displayed estimates are $81 using Fable throughout, $46.50 using GPT-5.6 throughout and $25.55 using a mixture. These numbers depend on the assumed token volumes and rates, and they do not demonstrate equal quality, account for iteration or establish real savings for an untested project.
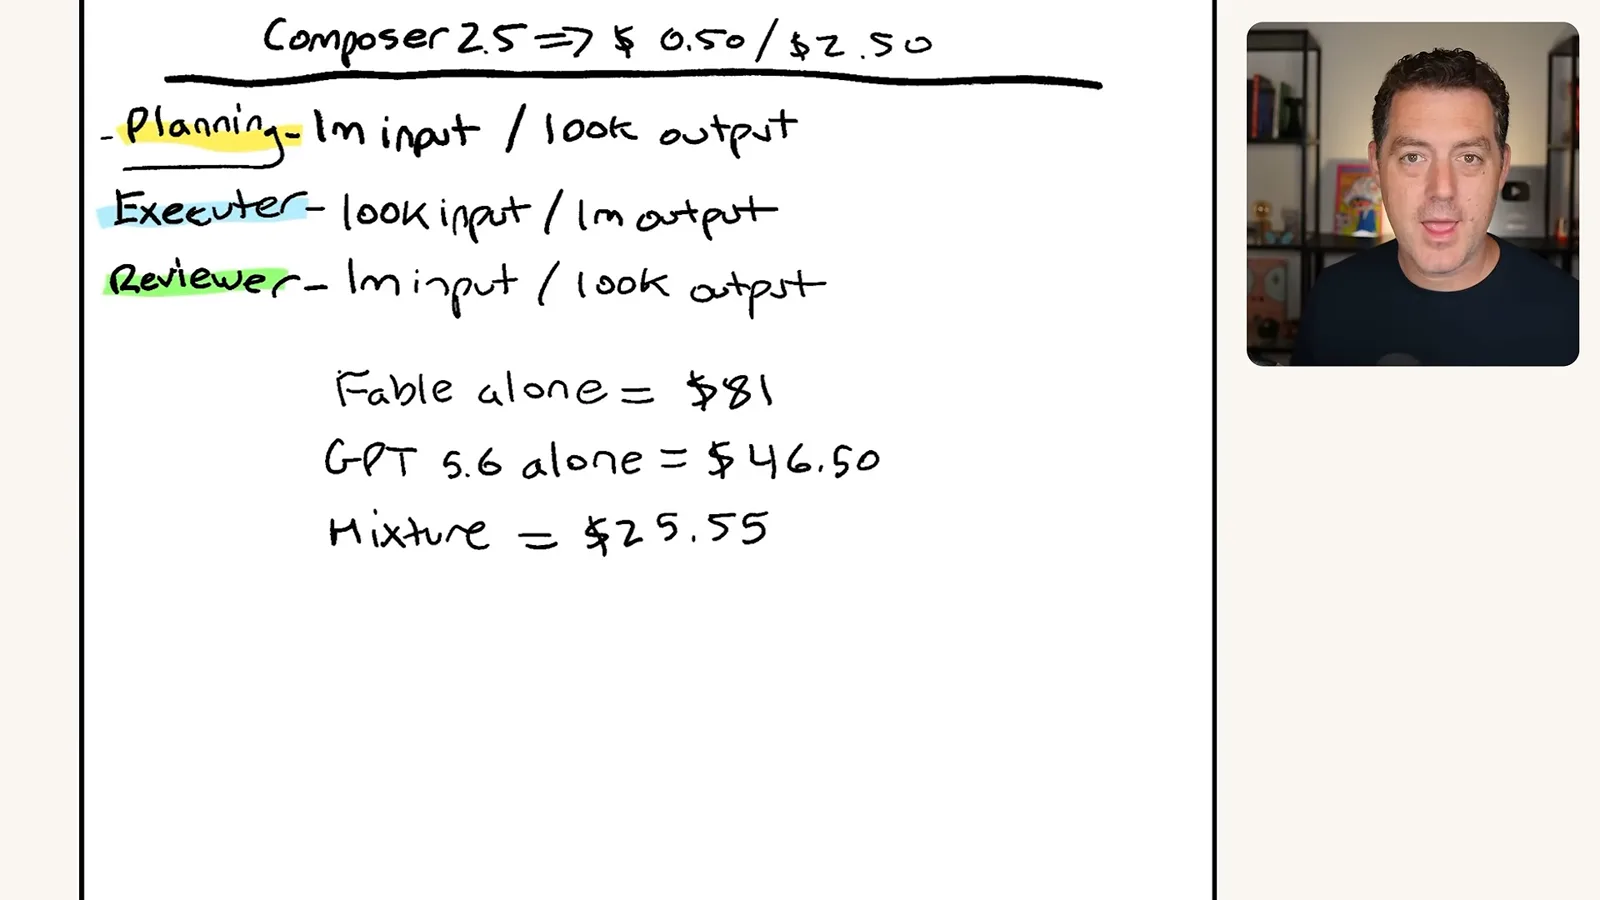
He also expects a faster execution model to reduce elapsed time. That can happen, but splitting work between models adds handoffs and may increase context transfer, review or rework. Teams need to compare complete workflows using tests and outcome quality, not only the hypothetical bill.
Open and closed model economics
Berman offers predictions about competition, hosting costs and value across the AI stack. These are future market scenarios rather than established outcomes.
Berman then discusses the economics of open and closed models. He argues that downloadable, openly available models can be hosted and optimized by competing providers, potentially putting downward pressure on inference prices. He contrasts that with proprietary frontier models available from their owners or partners, and characterizes OpenAI and Anthropic as the leading providers in his account.
He predicts that as open-model serving becomes more competitive, revenue and profit opportunities will shift toward chips, cloud infrastructure and applications. He also expects lower prices to encourage more usage. These are market hypotheses, not guaranteed outcomes: margins, demand, licenses, infrastructure costs and the competitive landscape can all change.
Berman concludes that model pricing and openness matter across the AI stack. His proposed practical step is to assess total task economics and combine models where their strengths fit the workflow. The examples are a snapshot of his July 2026 view and should be checked against current rates and real-world results before making a buying decision.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.