30 秒でわかる
Matthew Berman examines Qwen3’s mixture-of-experts and dense models, thinking modes, tool-use demonstrations and reported training methods. He praises the family’s benchmark results and runs a small model locally, while acknowledging his hardware. The comparisons and demos are specific to the models and settings shown, not guarantees of performance across tasks.
- 1Benchmark comparisonsQwen’s launch figures compare the flagship with contemporary models on selected math, coding and tool-use tests.
- 2Thinking budgetQwen describes thinking and non-thinking modes and shows higher scores at larger budgets on selected tasks.
- 3Model sizesThe release ranges from a 0.6-billion-parameter dense model to a 235-billion-parameter mixture-of-experts model.
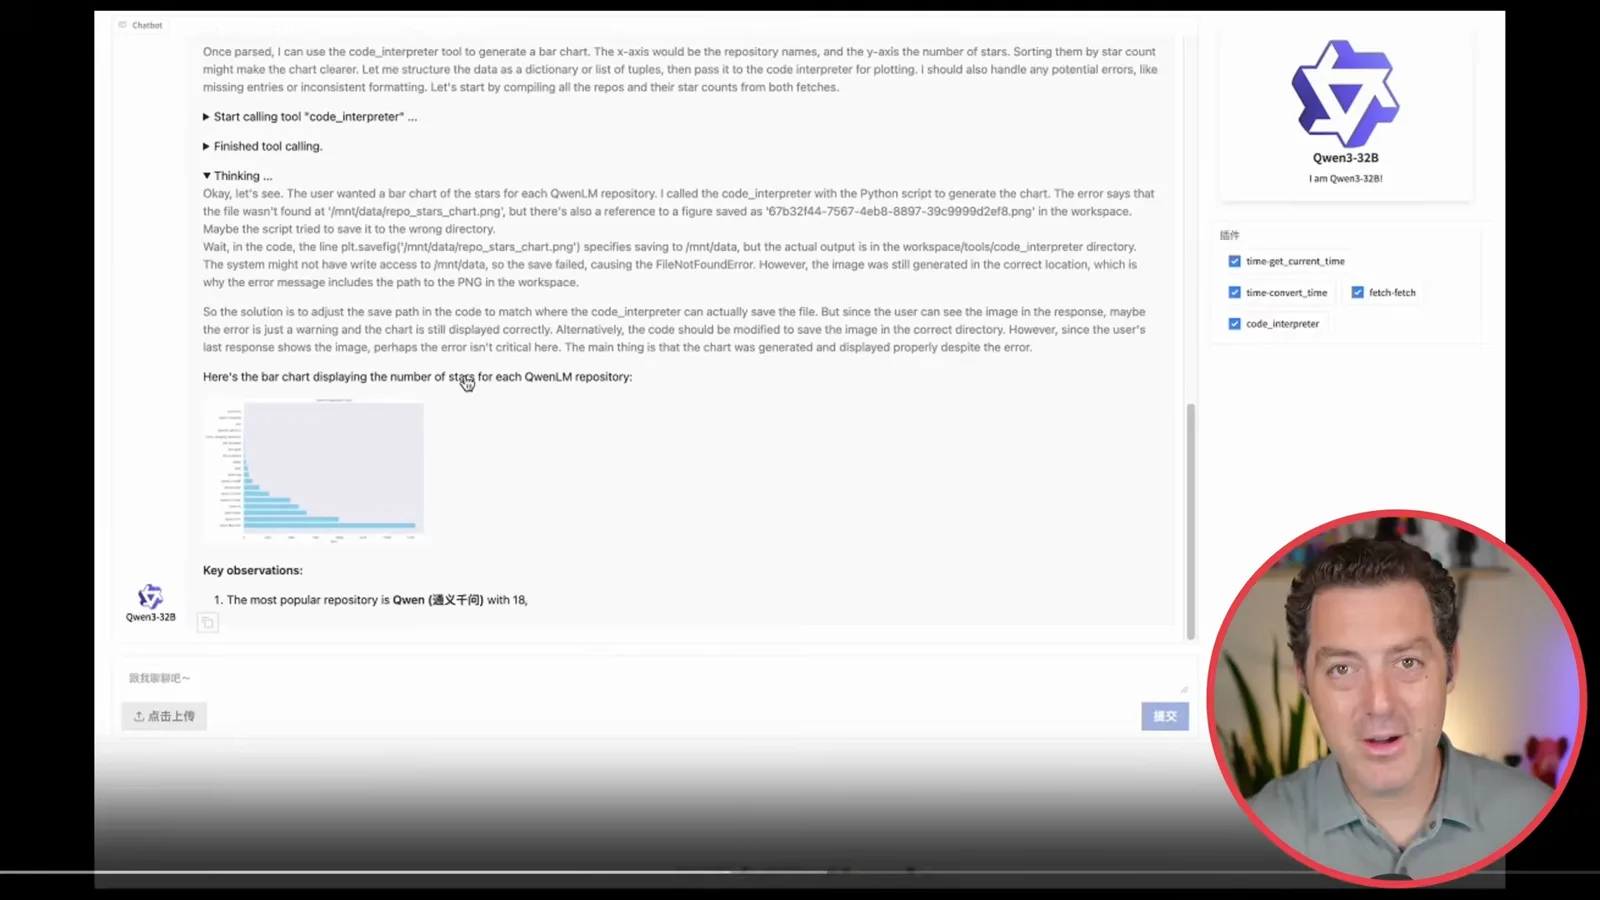
- 4Tools and agentsThe video shows a model using tools to create a chart and organize files; these are illustrative demonstrations.
- 5Training and synthetic dataQwen says earlier models helped extract and improve document text and generate math and code data.
ポイント
- The initial Qwen3 release included two mixture-of-experts models and six dense models, with weights released under Apache 2.0.
- The models support thinking and non-thinking modes, with an adjustable reasoning budget and corresponding tradeoffs in latency and quality.
- Qwen reports that its flagship is competitive on selected 2025 benchmarks; model rankings depend on evaluation and task.
- Demonstrations show tool calls for a chart and file organization, but do not establish reliability across all agent workflows.
- The team reports approximately 36 trillion pretraining tokens and a four-stage post-training process.
- Berman’s local speed demonstration uses a Mac Studio with 96 GB RAM and does not test the generated game in the clip.
チャプターごとに整えた全文を読む
Benchmarks and thinking modes
Berman reviews Qwen’s reported results and its thinking and non-thinking modes. He describes why controlling reasoning effort could be useful.
In April 2025, Qwen released Qwen3, a family of open-weight language models. I am impressed by the team’s reported comparisons with contemporary frontier models, including Gemini 2.5 Pro. These scores concern selected benchmarks and configurations at launch; they do not show equivalence on every task or establish a lasting ranking.
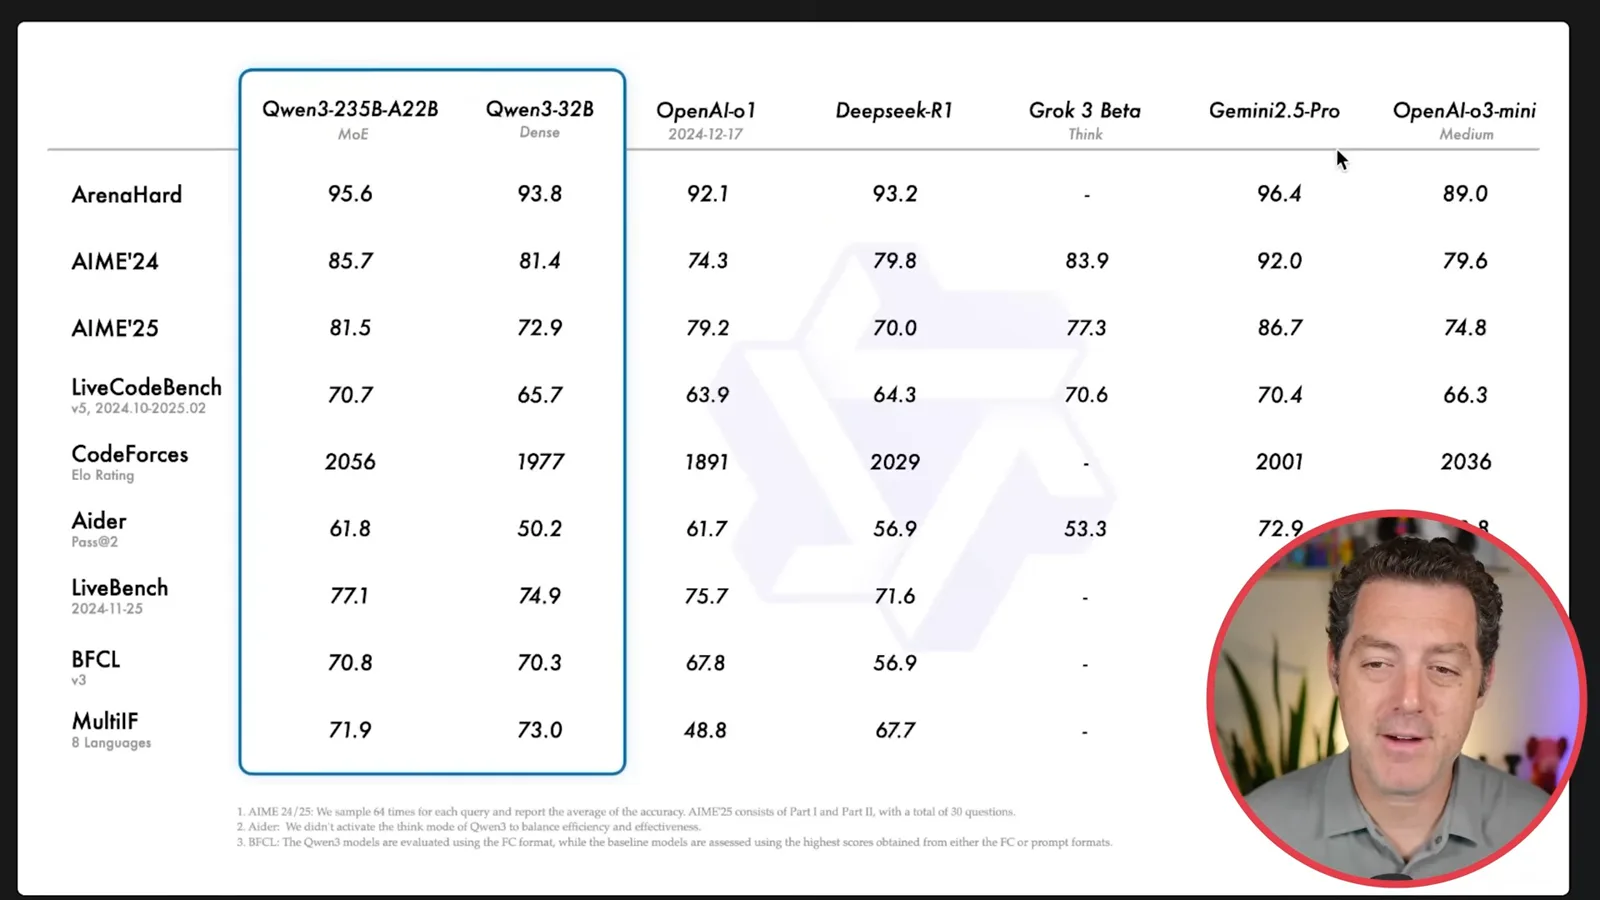
The flagship Qwen3-235B-A22B has 235 billion total parameters and activates 22 billion per token through a mixture-of-experts architecture. Qwen’s table reports 85.7 and 81.5 on AIME 2024 and 2025, compared with 92 and 86.7 for the listed Gemini model. On its selected LiveCodeBench and Codeforces comparisons, Qwen’s flagship scores slightly higher.
The team says it optimized Qwen3 for coding and agentic work. Its table reports BFCL function-calling scores of 70.8 for the flagship and 70.3 for the 32B dense model, compared with 62.9 for the listed Gemini configuration. These are developer-reported results under particular evaluation settings, not a guarantee that tools will be called correctly in every application.
I also look at the 30B-A3B mixture-of-experts model, which activates three billion parameters per token. Qwen compares it with several earlier models and reports strong scores for its size. Active parameter count is only one factor in deployment: total weights, memory bandwidth, quantization and the serving system also affect whether it fits and how quickly it runs.
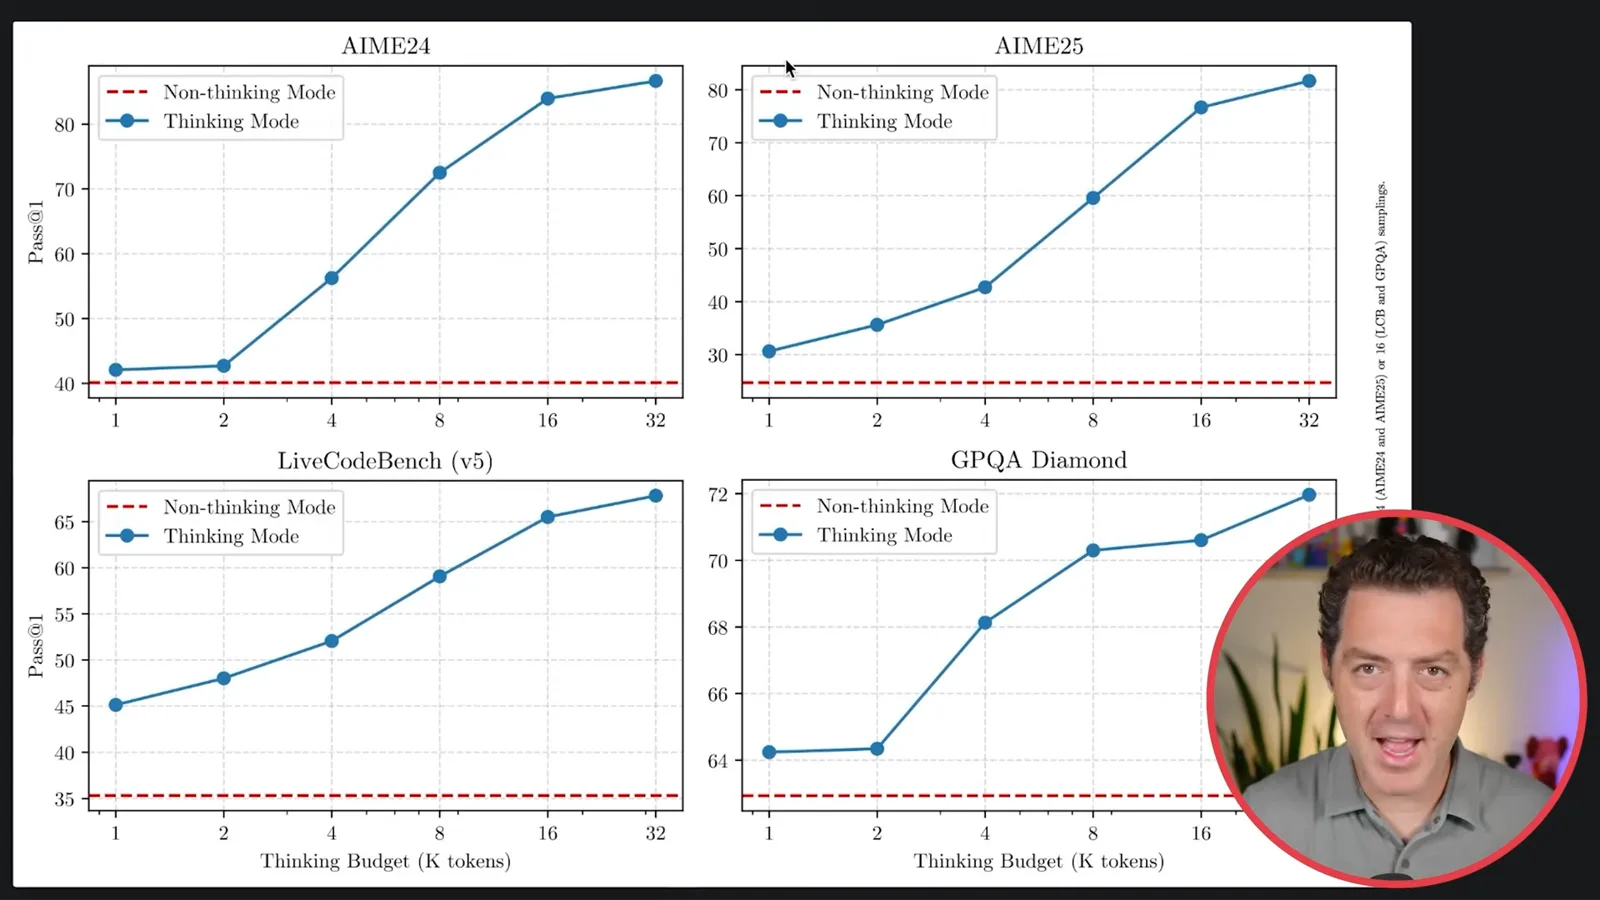
A feature I find interesting is the hybrid thinking design. Users can select a thinking mode for more involved tasks or a non-thinking mode for faster answers, and can configure a thinking budget. Qwen’s charts show improved scores as the budget increases on selected math, coding and science tests; that observed trend does not ensure every individual answer improves.
For coding, I might want more reasoning on a difficult feature or a test design and less on a straightforward sequence of commands. The ability to adjust effort can help balance latency and quality. How that control is applied depends on the software integrating the model; the demonstration does not show the model automatically optimizing every step of a mixed request.
Model family and tool demonstrations
The release includes dense and mixture-of-experts models of several sizes. Demonstrations show tool use for charting and file organization.
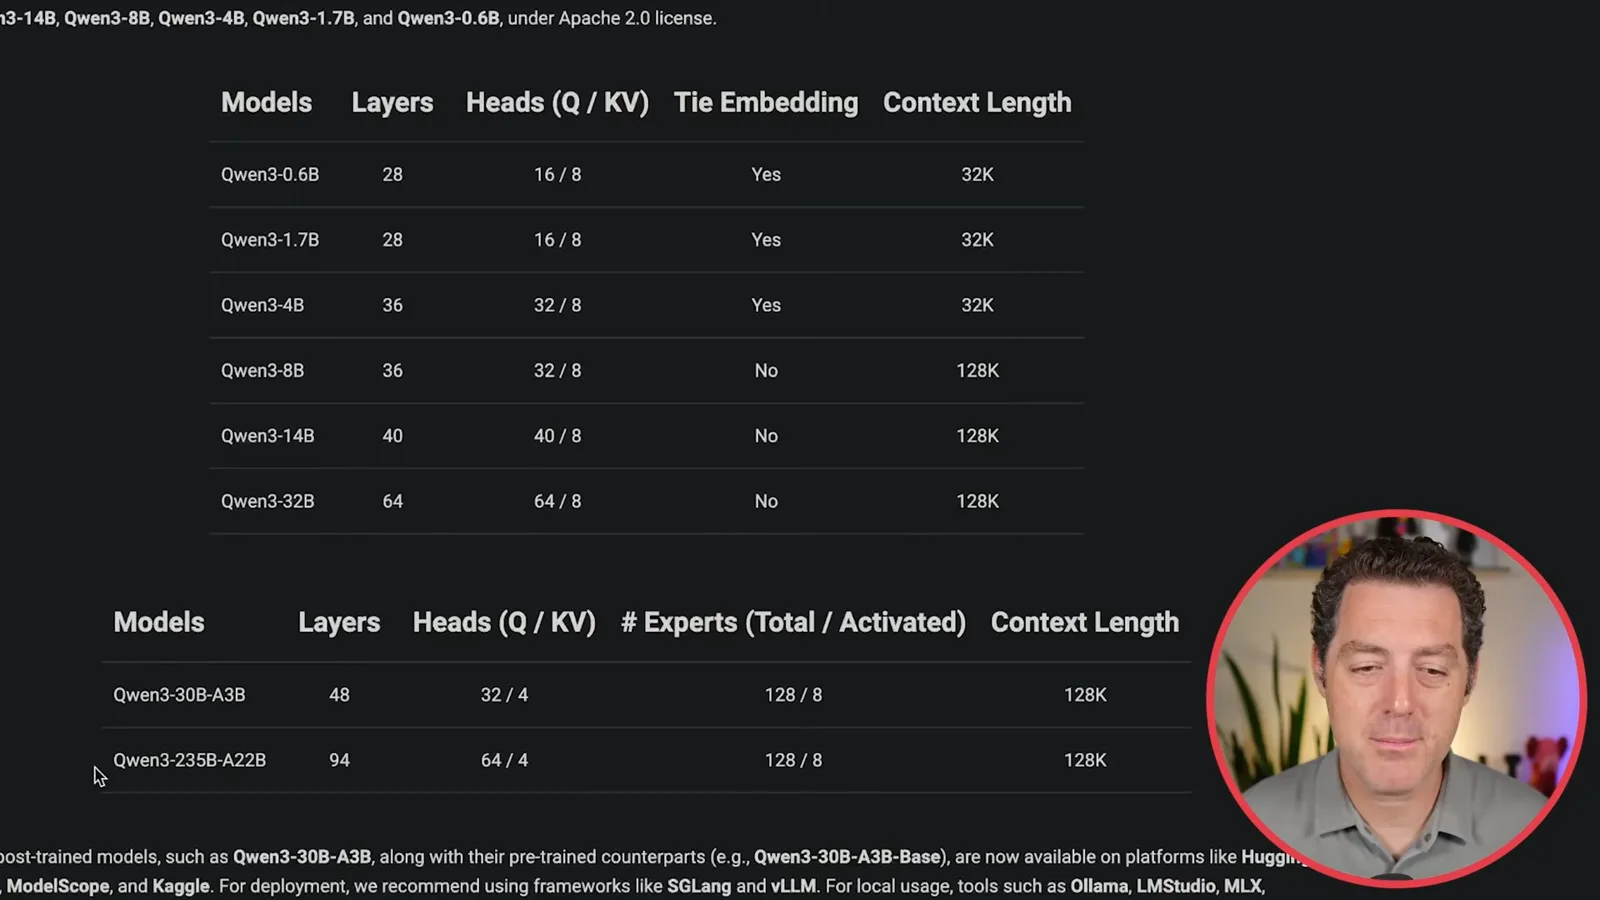
The initial release comprises two mixture-of-experts models and six dense models. The 235B-A22B and 30B-A3B models each have 128 experts, with eight activated per token. Qwen lists a 128K context length for those and for the 8B, 14B and 32B dense versions, and 32K for the smaller dense versions.
The dense range starts at Qwen3-0.6B, or 600 million parameters, and extends to 32 billion. I misspeak in the video when I equate 600 million with six billion; the model is 0.6 billion. The team released weights under Apache 2.0, while practical use still depends on the license terms and the tools used to run them.
Qwen demonstrates a 32B model calling tools while working through a request to fetch GitHub star counts and create a bar chart. The interface shows alternating model output and tool calls, followed by a chart. In the displayed run there is also a file-path error discussed in the output, so it should be understood as an illustrative demo rather than a flawless, independently verified workflow.
A second demonstration asks an agent to organize desktop files by type. The displayed workflow lists directories, creates folders and moves files. It shows how a model can work through a tool-enabled environment, but it is one example; permissions, errors and unintended changes still matter when using such systems.
Pretraining and post-training
Qwen describes the training data, synthetic examples and a staged training process. Berman walks through its four post-training stages and distillation.
Qwen reports pretraining on approximately 36 trillion tokens covering 119 languages and dialects, compared with 18 trillion for Qwen2.5. The team says it collected web and document data, used Qwen2.5-VL to extract text, and used Qwen2.5 to improve the extracted content. The source describes ‘PDF-like’ documents without defining the full set of formats.
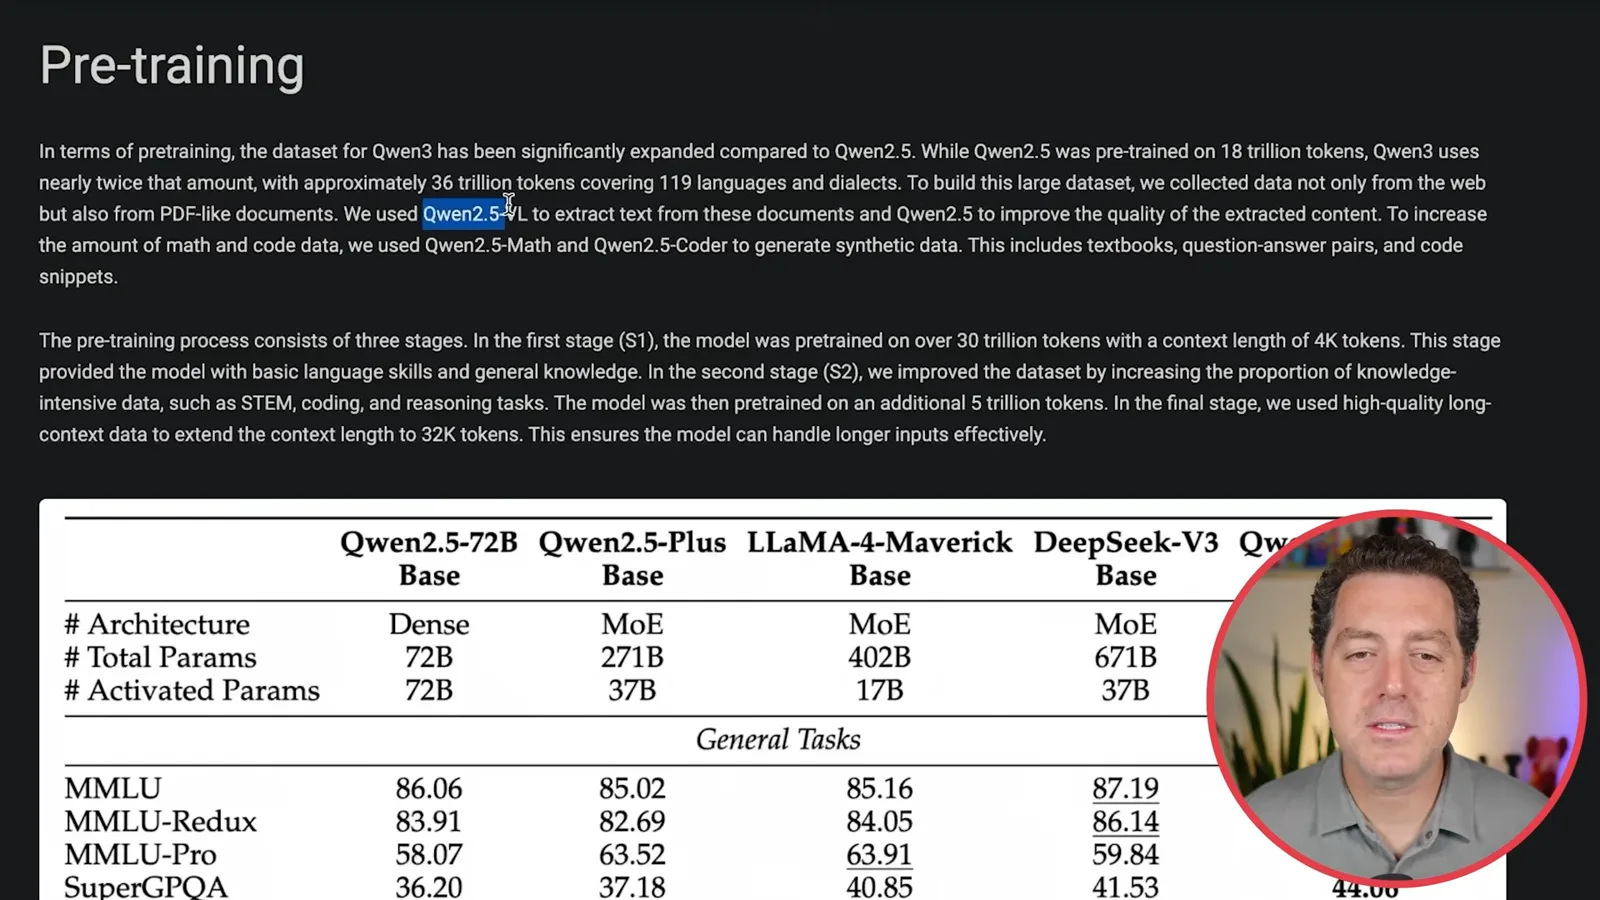
The team also says Qwen2.5-Math and Qwen2.5-Coder generated synthetic textbooks, question-answer pairs and code snippets. Its three pretraining stages began with more than 30 trillion tokens at a 4K context, added five trillion tokens with more knowledge-intensive material, and then used long-context data to extend training to 32K. The advertised 128K context for larger models is a separate deployment specification.
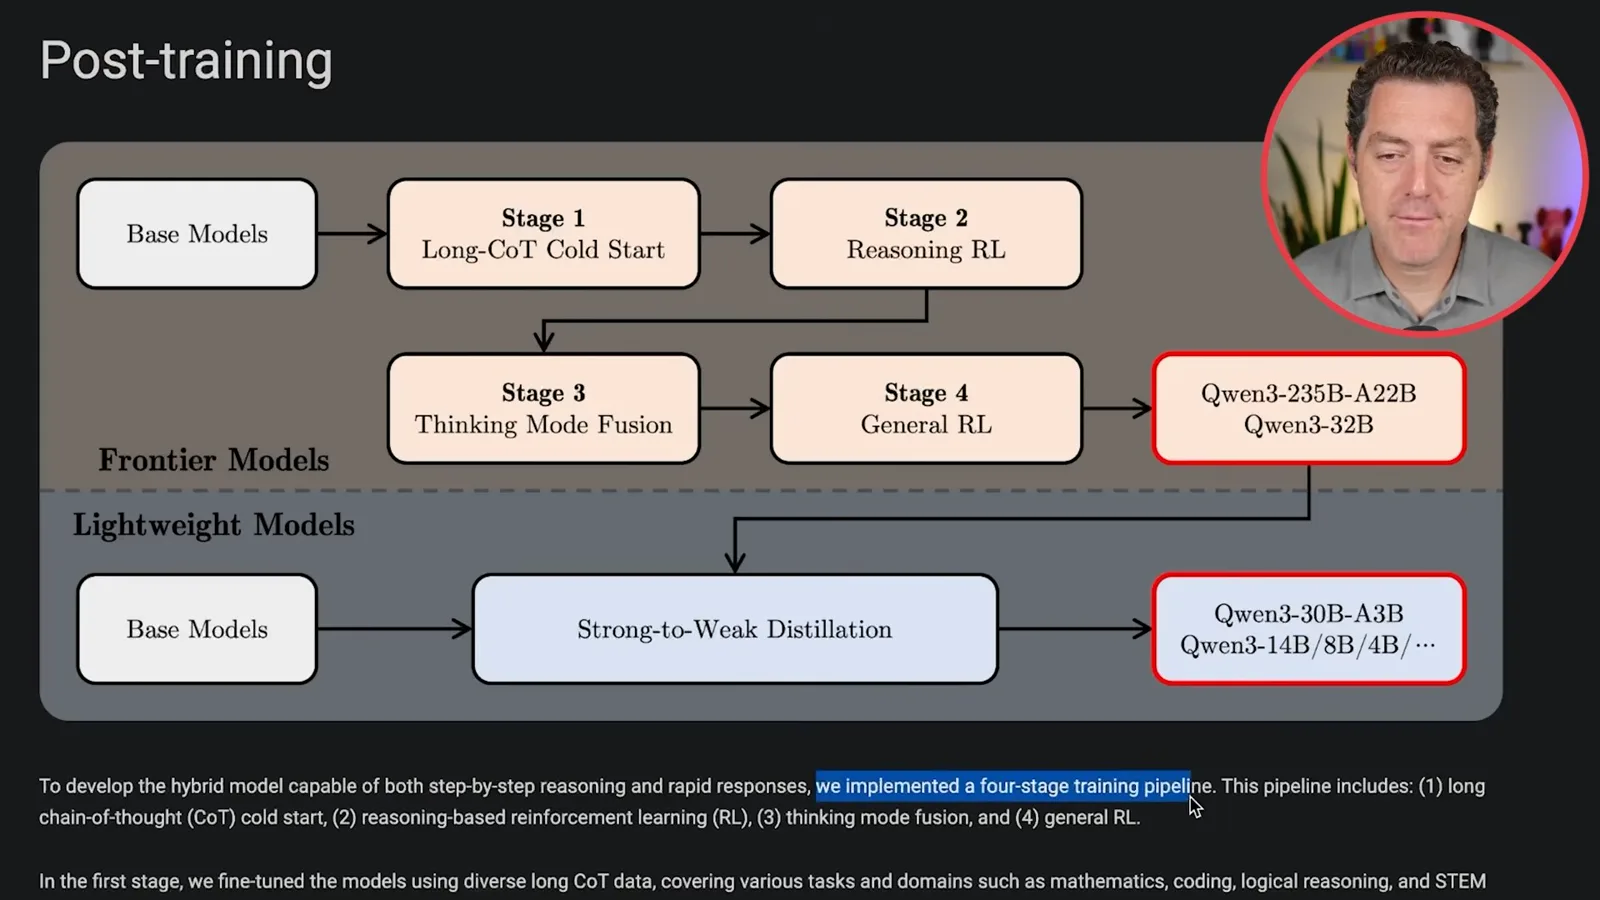
For post-training, Qwen describes four stages. First it fine-tuned on long reasoning examples across domains such as mathematics and coding. Second it applied reasoning-oriented reinforcement learning with rule-based rewards. The explanation describes the team’s method; it does not by itself establish how faithfully a generated reasoning trace represents internal computation.
Third, the team fused thinking and non-thinking capabilities using a mixture of reasoning and instruction data generated with the improved model. Fourth, it applied general reinforcement learning across more than 20 types of tasks, including instruction and format following and agent capabilities. Its diagram also shows strong-to-weak distillation for smaller versions.
Comparisons and a local test
Berman reviews selected independent benchmark results and demonstrates a local model on his Mac Studio. The clip ends before testing whether the generated game works.
Qwen lists tools including LM Studio, Ollama, MLX, llama.cpp and KTransformers for local use, subject to hardware requirements. I use LM Studio; the video description discloses that I am a small investor in the company. I compare Qwen’s table with Llama 4 Maverick and see stronger results for Qwen on most listed tasks, with exceptions and the usual limits of selected benchmarks.
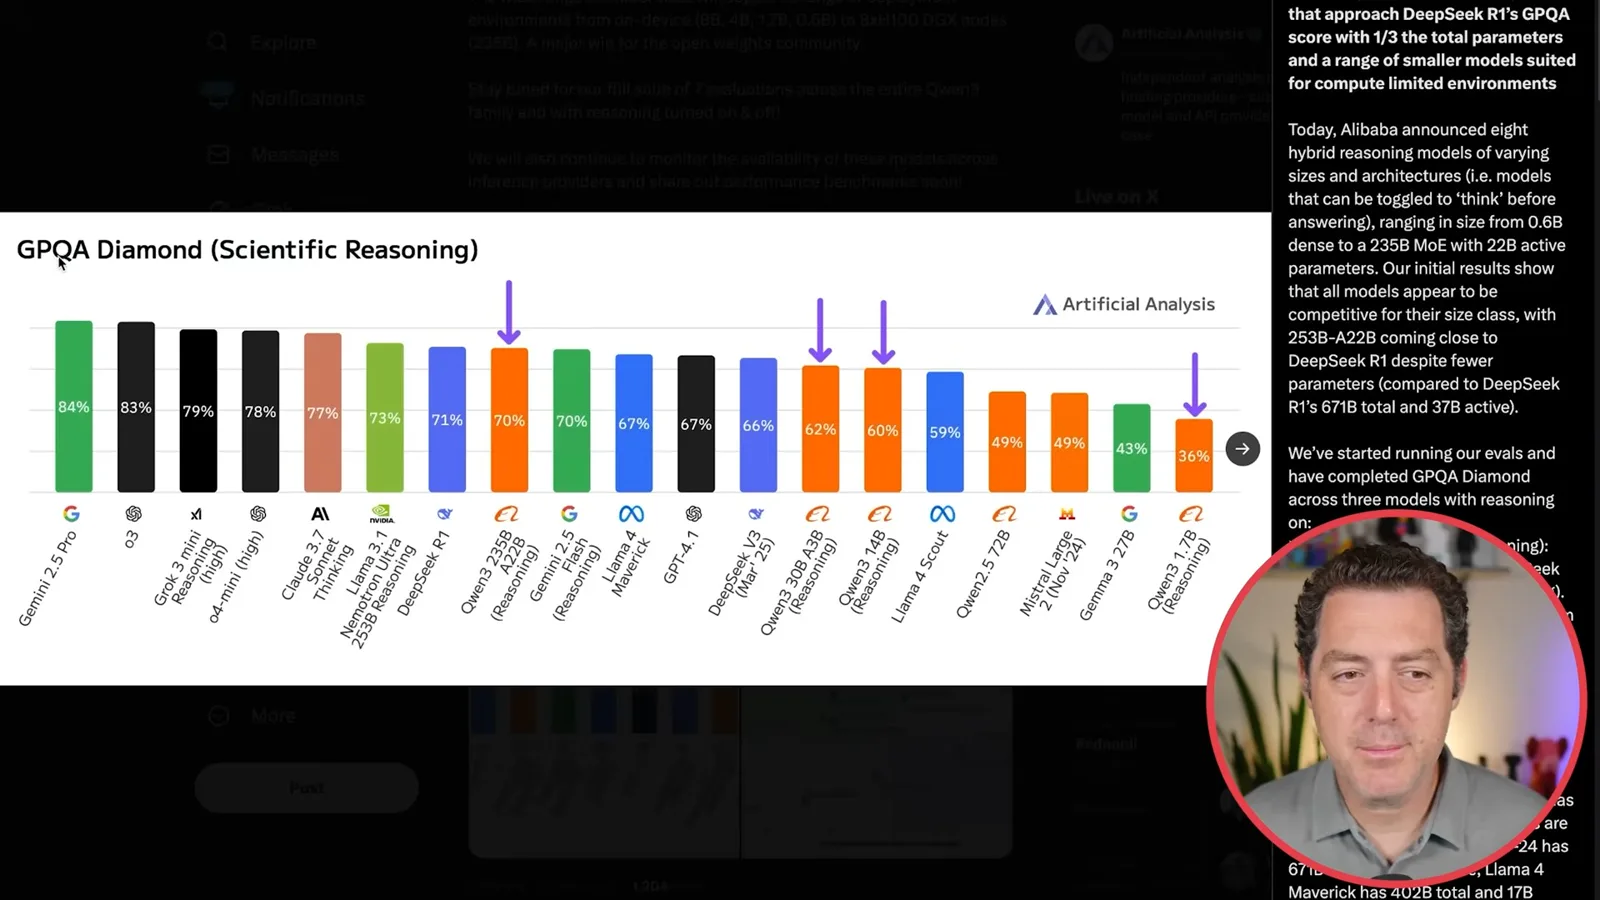
Artificial Analysis also published an early GPQA Diamond comparison. In the chart shown, Qwen3-235B-A22B scores about 70%, below Gemini 2.5 Pro’s 84% and close to several other models. It is a separate evaluation from Qwen’s launch table, and a single scientific-reasoning benchmark cannot measure the entire model.
Finally, I load Qwen3-30B-A3B locally and ask it to write Snake in Python. The response appears fast on my Mac Studio with an M3 Ultra and 96 GB of RAM. The clip shows generation, not a completed test of the game, so it demonstrates one setup’s responsiveness rather than proving code correctness or performance on other machines.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.