30 秒でわかる
Theo discusses the withdrawal of Fable restrictions and examines Sonnet 5 through launch data, third-party benchmarks and his own game and skate-trick tests. He sees an opportunity to use Sonnet inside a stronger model’s workflow, while cautioning that token consumption and task selection can outweigh its lower per-token price.
- 1Fable restrictions withdrawnTheo reads the Commerce letter as withdrawing previous controls after commitments by Anthropic.
- 2Performance must be compared with costThe charts show different trade-offs across search, computer use and coding benchmarks.
- 3Three game rebuildsTheo preferred Opus’s single run and found problems in the GLM and Sonnet versions.
- 4A costly skate-trick testSonnet scored poorly on his private test and Max consumed considerably more per question.
- 5Route tasks by difficultyTheo proposes assigning smaller tasks to Sonnet and escalating harder ones to stronger models.
- 6A refusal trade-offThe system card’s malicious and benign-request results highlight a concern about over-refusal in this evaluation.
ポイント
- A lower per-token price does not guarantee a lower cost per completed task.
- Benchmark rankings and costs depend on the evaluation, effort level and methodology.
- Theo’s individual game rebuild favored Opus, while Sonnet delegated extensively but took longer.
- Sonnet’s subagent orchestration may be useful within a larger workflow, though Theo has not validated his proposed routing strategy.
- The launch-era restrictions, prices and availability discussed in the video are time-sensitive.
チャプターごとに整えた全文を読む
Fable restrictions and Sonnet 5
Theo discusses the withdrawal of export restrictions and introduces Sonnet’s agentic capabilities.
Sonnet 5 is here, and I have been testing its strengths and weaknesses. Another piece of news matters even more to me: the Secretary of Commerce has withdrawn restrictions on Fable 5. At recording time the model was not yet back, though I expected that to change soon.
Fable was restricted on June 12, three days after release, over concerns about hacking and access by foreign actors. I read the subsequent Commerce letter as saying Anthropic had agreed to detect security risks, cooperate on protocols and report malicious activity; the prior controls were withdrawn, subject to possible reevaluation.
My reading is that the withdrawal also matters to services hosting the models through an API for users, such as T3 Chat. I was worried that such access might remain restricted. This is my interpretation of the announcement at the time, not a substitute for examining the actual rules.
Anthropic calls Sonnet 5 its most agentic Sonnet: it can plan, use browsers and terminals, and run autonomously. I think the '5' matters because of its approach to agentic work. To me the lineup has shifted upward: work once assigned to Haiku now goes to Sonnet, Sonnet work to Opus, and Opus work to Fable.
Benchmarks and task costs
He compares Anthropic, Cursor and Artificial Analysis results and separates token price from task cost.
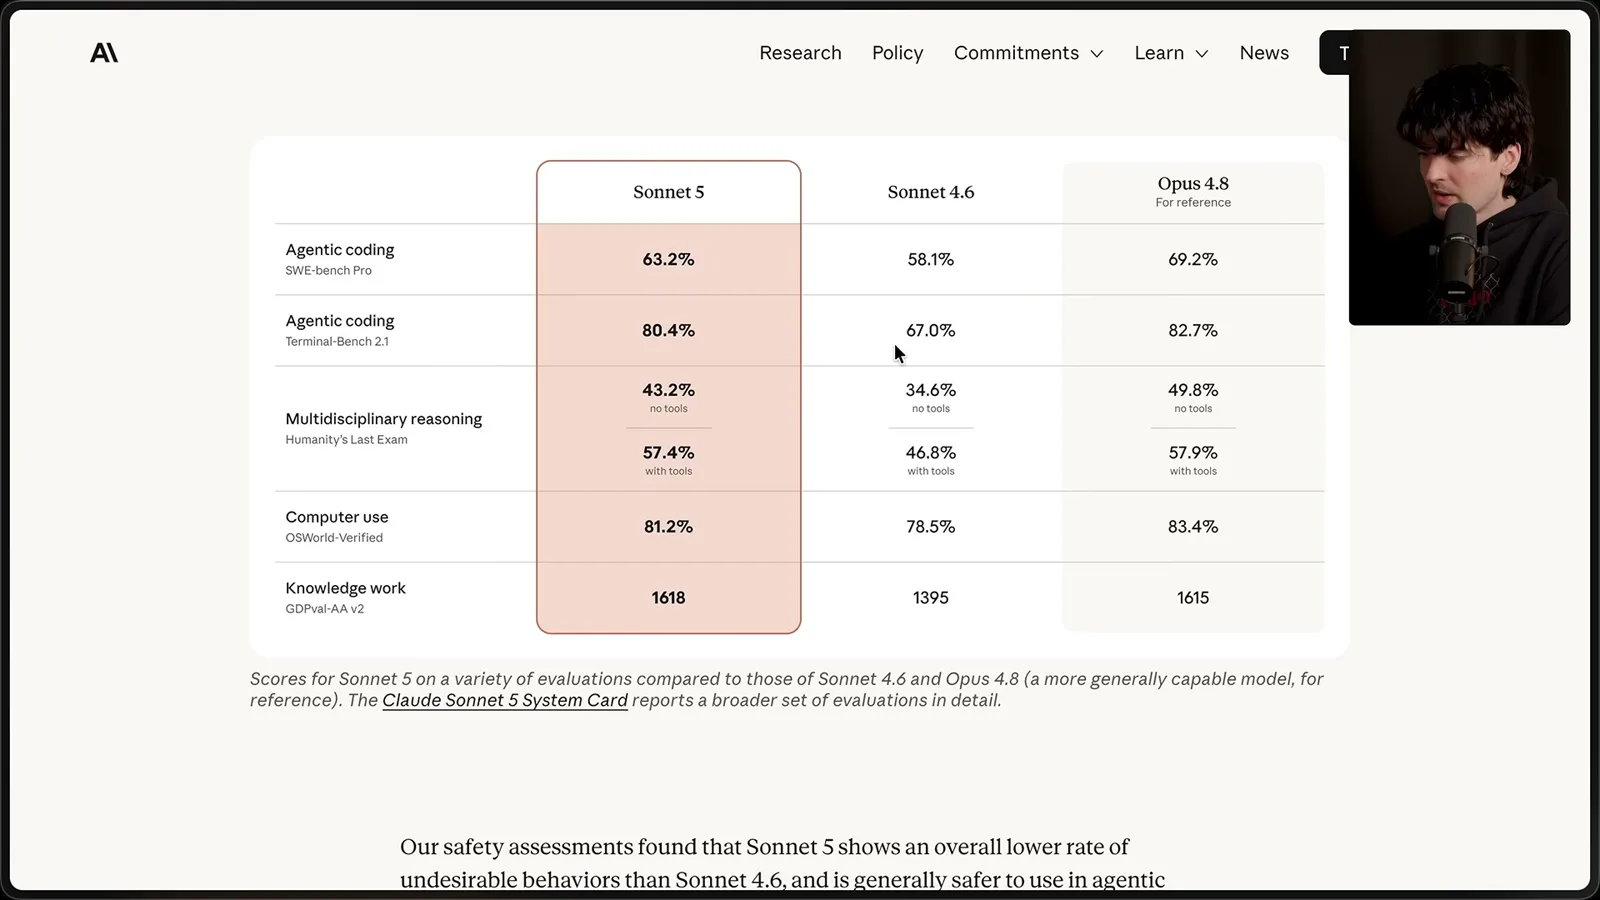
Anthropic reports gains over Sonnet 4.6 in reasoning, coding, tool use and knowledge work, with performance approaching Opus 4.8. Its table shows Terminal-Bench rising from 67% to 80.4%, and smaller gains in computer use. I question the usefulness of SWE-bench scores because I believe those tests have substantial contamination; that is a concern, not proof about every individual result.
The company's charts compare performance and cost at different effort levels on BrowseComp and OSWorld-Verified. I find the search results competitive, particularly at lower effort, but the computer-use chart makes Opus look better for the money. Cursor Bench also shows Sonnet variants costing more and performing worse than comparable GPT-5.5 settings in the results I inspect. These are benchmark-specific comparisons.
Artificial Analysis ranks Sonnet near the top of its index, but its cost numbers caught my eye. I cite roughly $6,000 to run its whole benchmark suite on Sonnet versus $5,600 for Fable. I speculate that its per-task average may handle extreme runs differently from the total; I have not confirmed that methodology with the researchers.
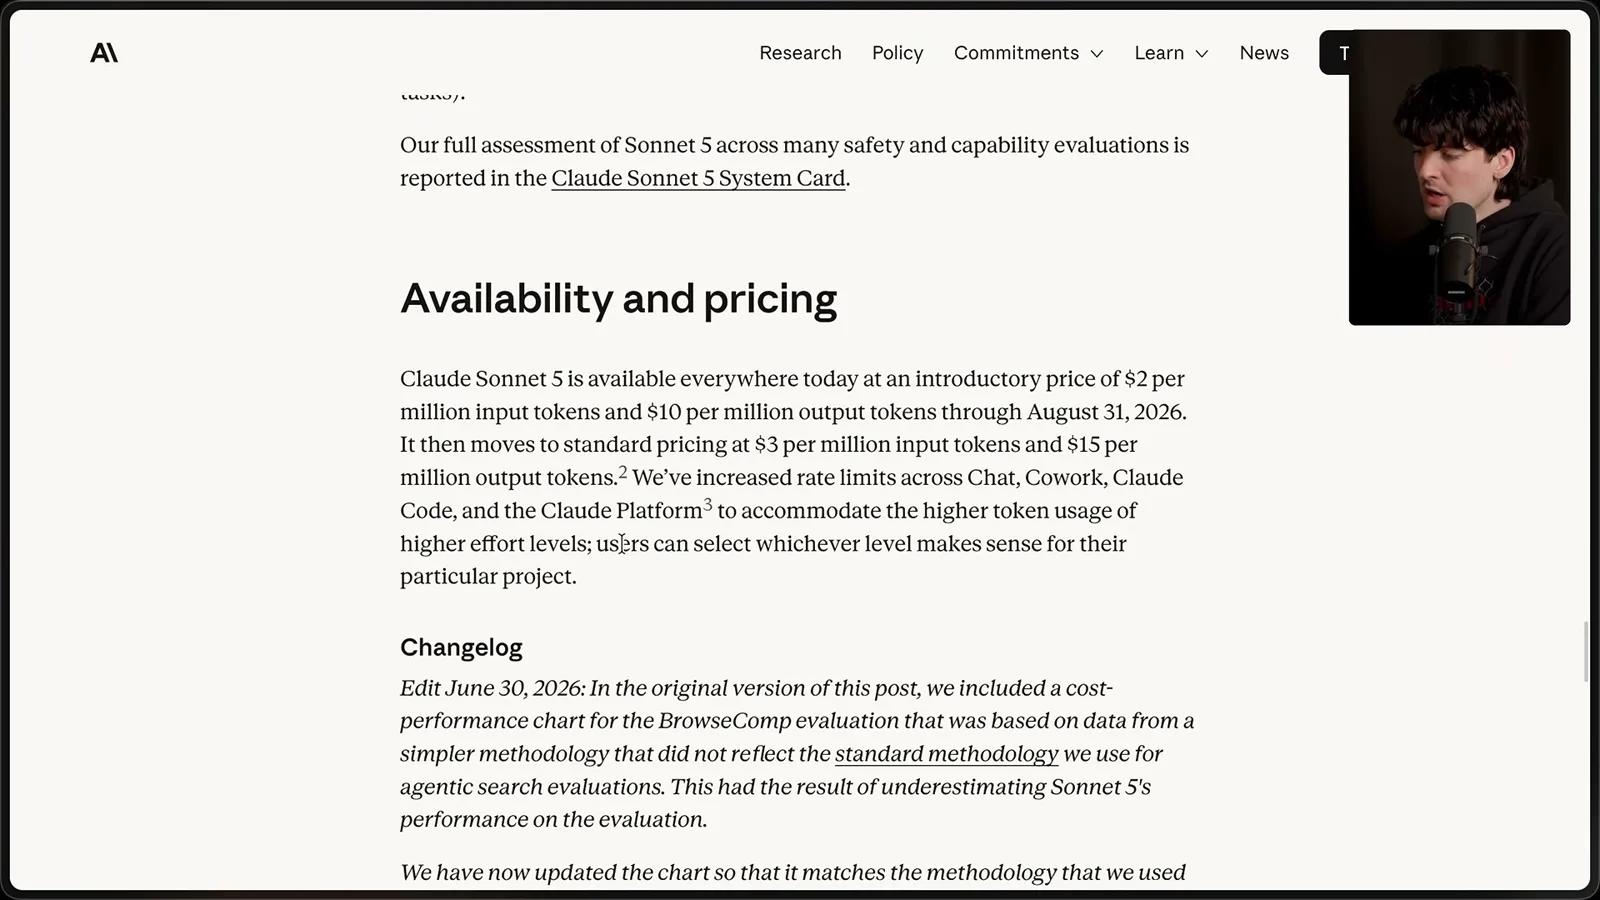
The lower price Anthropic advertises is per token, not necessarily per completed task. Its release announced $2 per million input tokens and $10 per million output tokens through August 31, 2026, then $3 and $15 respectively. I also say the separate Sonnet subscription limit has been removed. These details describe the launch period and may change.
In the token-use chart I cite, Sonnet uses roughly 69,000 tokens, almost twice the Opus figure and several times GPT-5.5 at xhigh. On my own work it also felt slow. Token use and cost depend on the task, effort setting and test setup; one chart doesn't settle the question for every use.
A game rebuild and SkateBench
Theo compares three individual game-building runs and reports his own skate-trick benchmark.
I asked Opus 4.8, GLM 5.2 and Sonnet 5 to rebuild my fish web game from scratch while allowing them to reference the original repository and assets. Opus finished in roughly 26–27 minutes. Its UI had rough edges and some creative choices I disliked, but the controls, core loop and economy made a playable starting point.
GLM's version cost $8.30 in the tool I used and took around 35–40 minutes. I found the movement choppy, the economy poor and the shooting direction wrong. I also note that the GLM setup I used lacked vision, limiting its ability to inspect the browser visually.
Sonnet's version removed buying hotkeys, started with no fish and fired when I clicked purchase buttons. The economy also felt poor. I estimate the run took at least two hours, perhaps two and a half; I did not time it precisely. These are individual runs, not a controlled study.
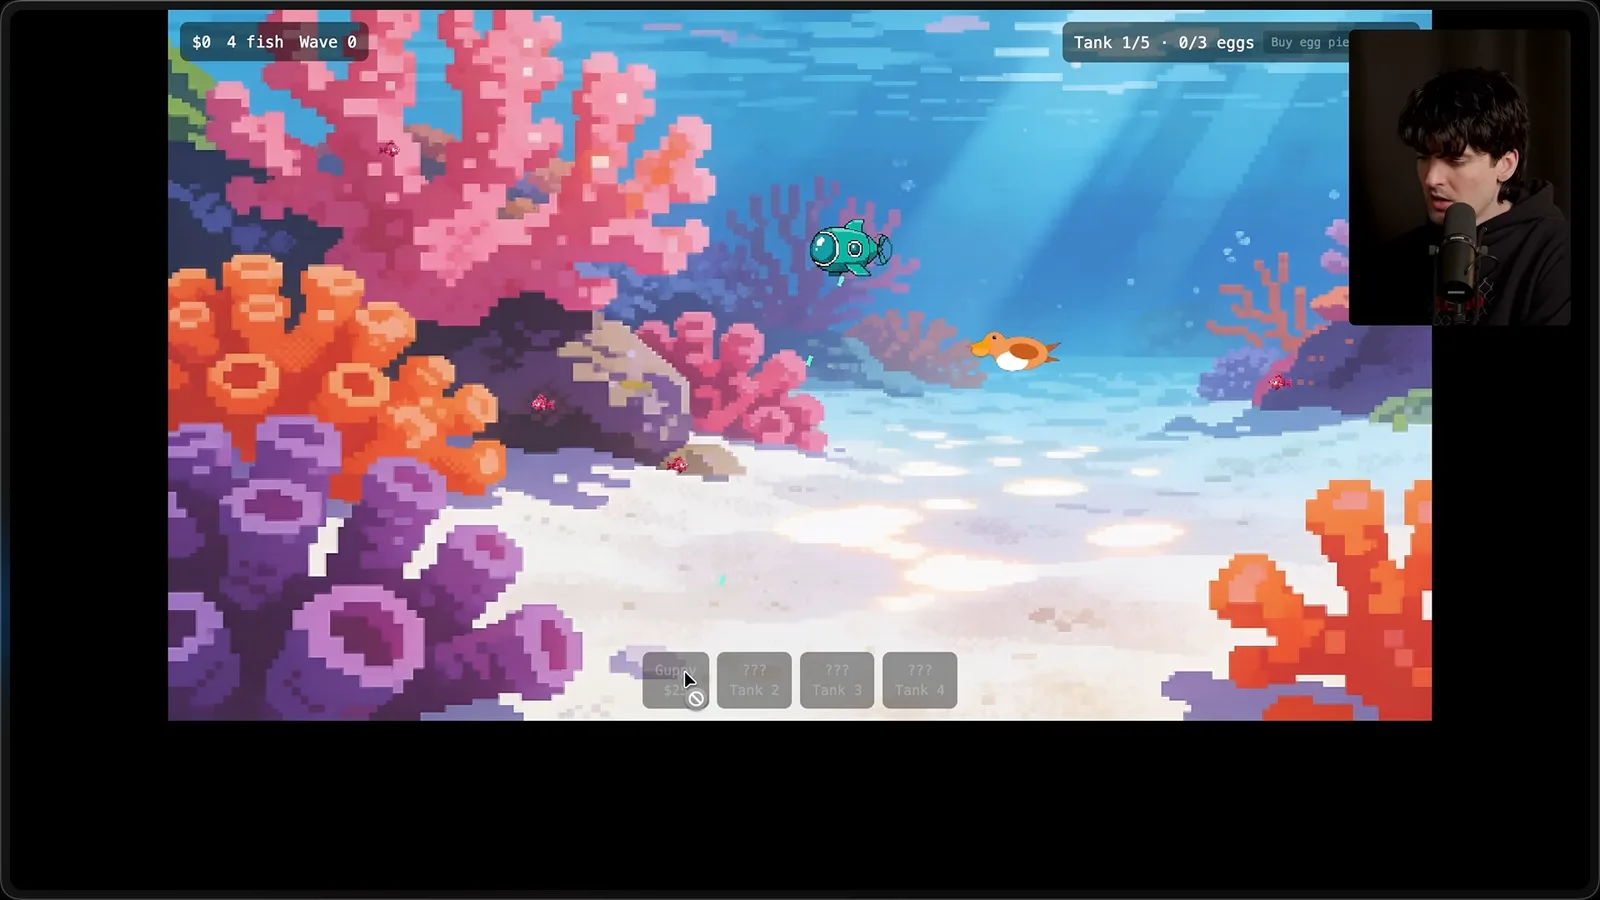
Sonnet voluntarily spawned agents to inspect the old code, plan, review the plan and implement it. It also asked useful scoping questions, whereas Opus asked none and spawned no subagents on the same prompt. I like the ability to break down and delegate work, but in this run I think it split too much and went in circles.
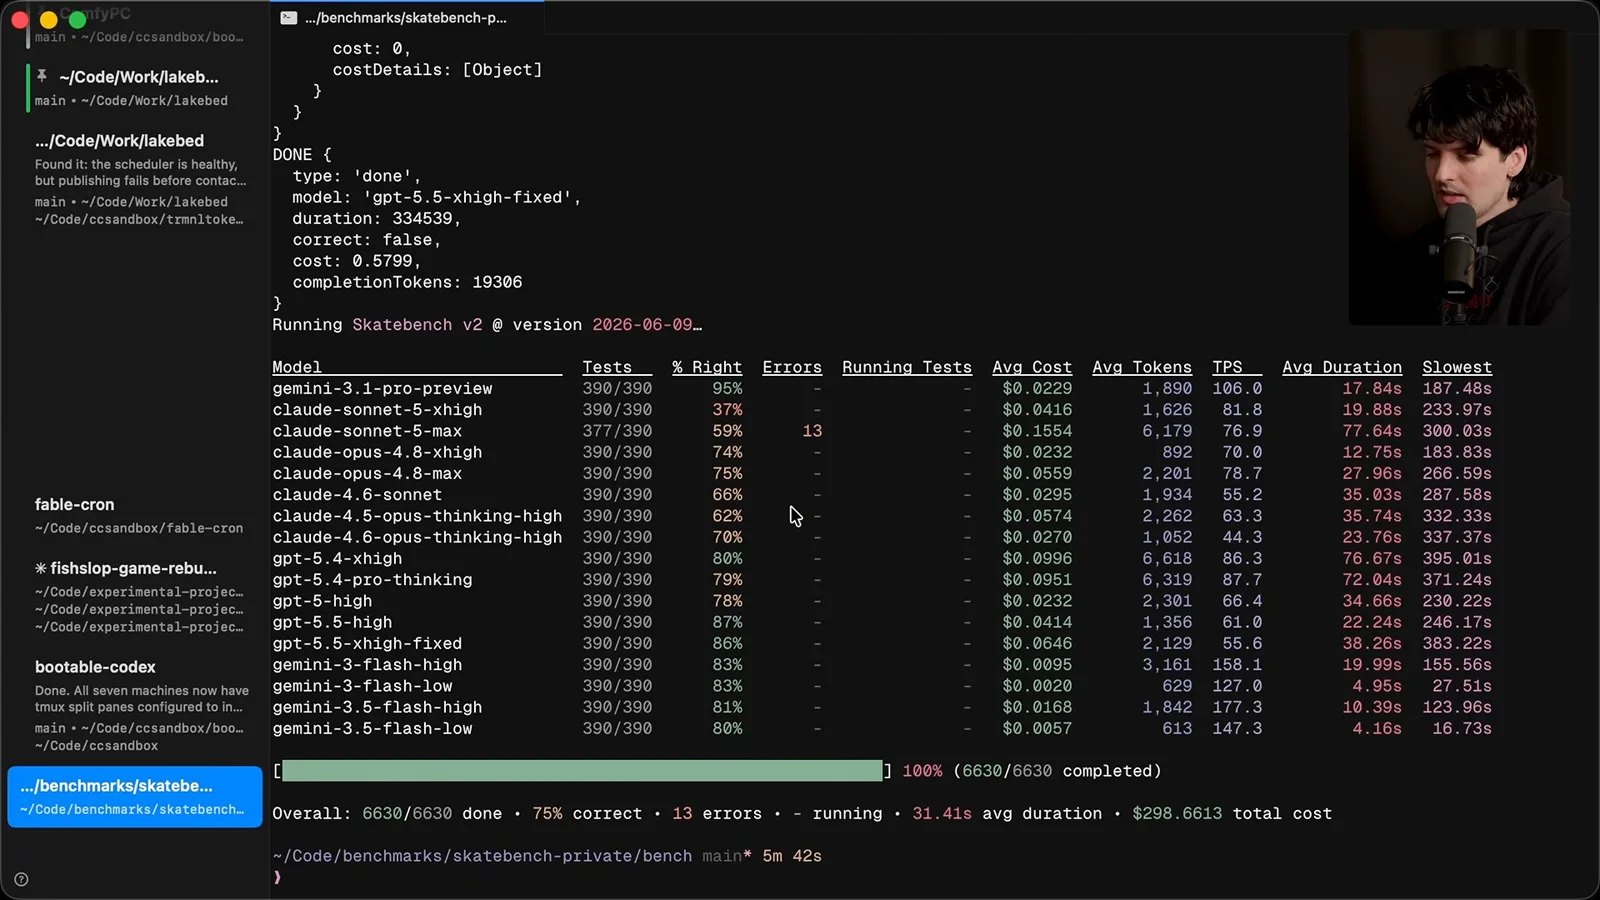
I also tried Sonnet on bugs in SkateBench and gave up because it took too long. My skate-trick naming benchmark had previously been contaminated, so I added private questions. In this test Gemini 3.1 Pro scored 95%; Sonnet 5 xhigh scored 37% at about four cents per question, while Max scored 59% at about 15 cents, with some wrong answers costing around a dollar.
Routing and orchestration
He uses an engineer-pay analogy to explain how a cheaper model can cost more on a difficult task.
The analogy is a junior engineer paid $20 an hour and a senior paid $100. A ten-hour job costs $200 with the junior and $1,000 with the senior, but if the junior takes 100 hours it costs $2,000. A lower unit price can lose its advantage when a harder task takes much longer, especially without someone deciding when to escalate.
That makes model routing an engineering problem. A stronger orchestrator could give small, suitable tasks to Sonnet and escalate harder ones to Opus or Fable. Get the balance right and you may save money; get it wrong and a cheaper model can cost more overall.
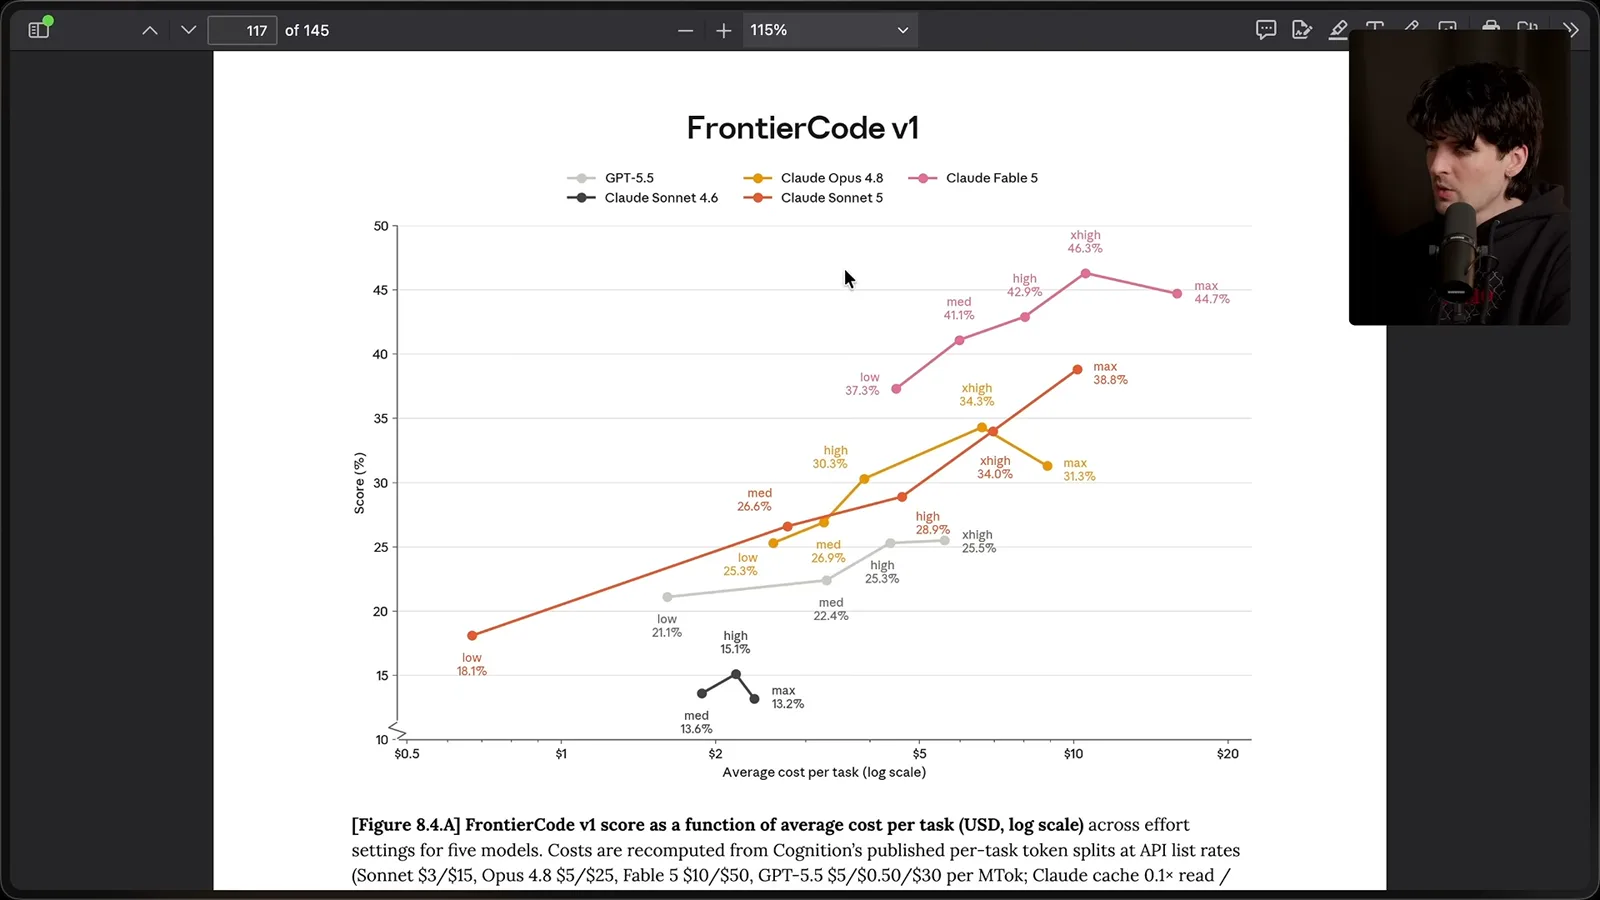
In the system card's FrontierCode chart, Sonnet's measured cost rises from under a dollar per task at low effort to roughly $12 at max, while its success rate improves. I see low and medium as potentially useful value points, although other models look more efficient at higher effort on this particular evaluation.
On Cursor Bench, I find GPT-5.5 and Fable occupy attractive parts of the performance-cost curve. My everyday preference is GPT-5.5 for tasks it can handle and Fable for harder ones. I see Sonnet less as my default coding model than as something an agent might call within a larger workflow.
Imagine Fable dividing a complex job into workflows, with Sonnet handling a subtask and, when appropriate, delegating further. I'm excited by that possibility, but it remains a proposal rather than a demonstrated result. My guess about why Anthropic released this model instead of an Opus 5 is speculation, too.
Safety and reported behavior
He reviews a refusal table and a viewer’s report of exposed thinking, distinguishing observation from speculation.
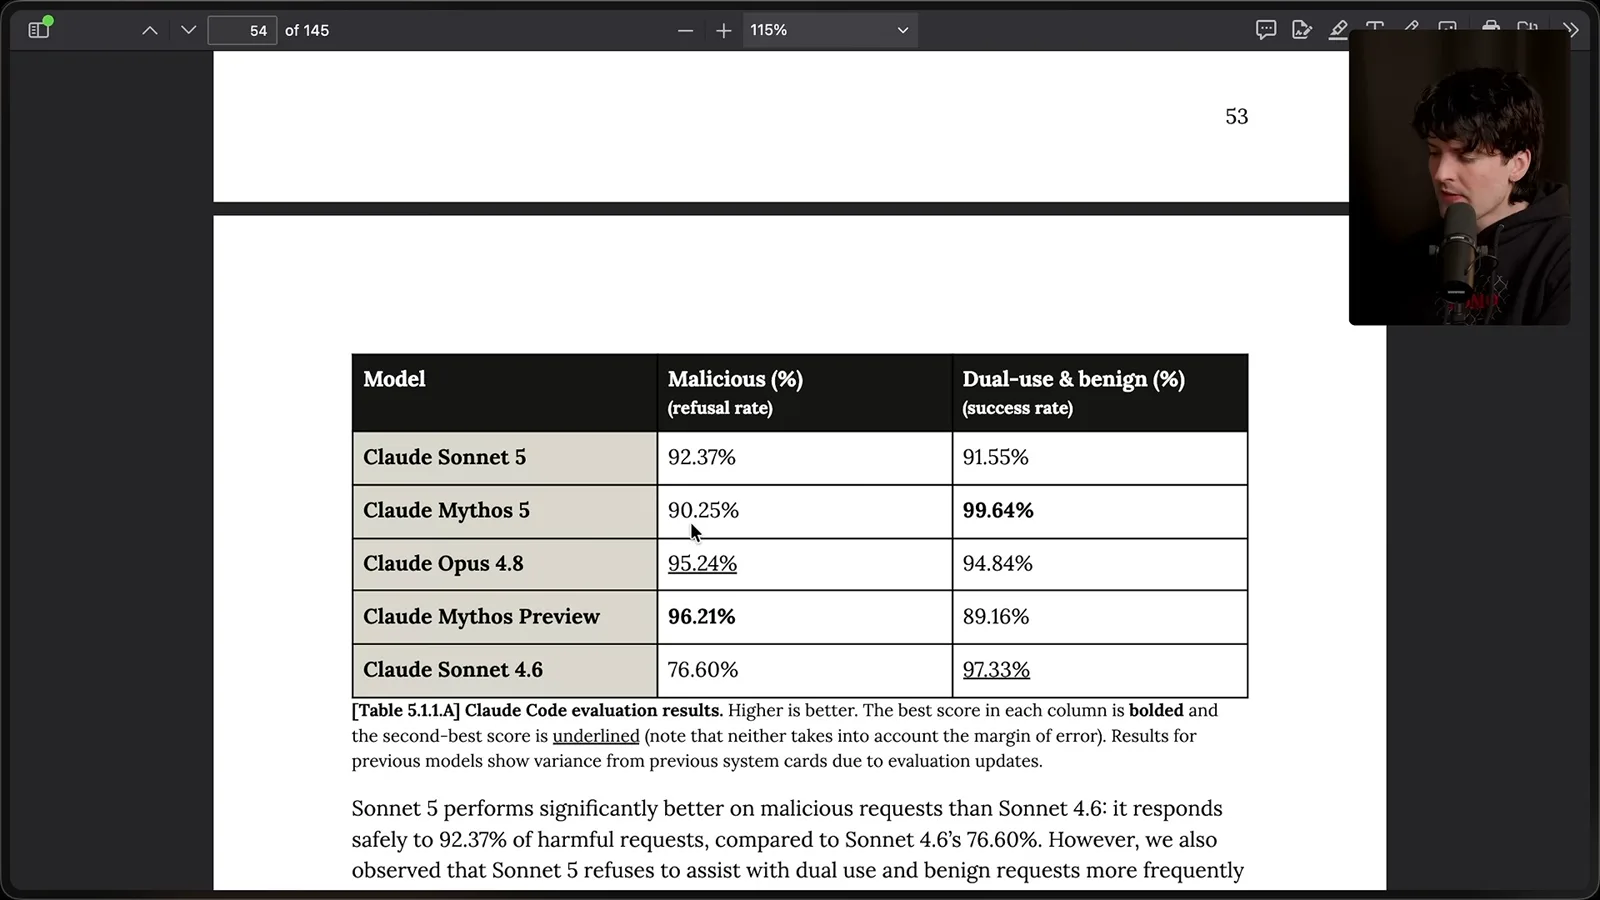
The system card compares refusals of malicious requests with successful responses to benign or dual-use requests. It shows Sonnet 5 refusing 92.37% of malicious requests and succeeding on 91.55% of benign or dual-use requests, compared with 99.64% for Mythos 5 on the latter. I worry about unnecessary refusals; the table itself is a limited evaluation, not a complete safety assessment.
A viewer reported that one Claude.ai account was exposing apparent thinking traces. I look at examples where the model repeatedly discusses searching or how to answer a simple question. I find the behavior awkward and speculate that it relates to wasted tokens, but a report from one account doesn't establish the cause or how widespread it is.
Contamination and conclusions
Theo questions benchmark contamination and outlines a possible role for Sonnet inside a larger agent workflow.
The system card discusses contamination for several evaluations, including biology, mathematics and BrowseComp. I appreciate that discussion but criticize the treatment of SWE-bench: its tasks are based on public historical pull requests, which I think makes training contamination a serious concern. Public availability alone does not prove a specific model saw every answer.
My co-host Ben was excited about Sonnet's parallel agent behavior, though when he commented he had not yet inspected completed work. I have tested it and am less impressed as a replacement for Opus. I am hopeful that a stronger model can use Sonnet for isolated tasks and perhaps have it signal when to escalate, but I have not tested that hope yet.
For now I am staying with GPT-5.5 and Opus and intend to return to Fable when access returns. I'm excited about models that can break up complex work, but I don't think Sonnet is capable enough to exploit that ability consistently on its own. It may still have a useful niche inside a well-orchestrated workflow.
同じチャンネルの記事
 38:47EN
 Theo - t3․gg· 2026年10月28日Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026年10月27日Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026年10月26日Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026年10月23日Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026年10月22日Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026年10月20日Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.