30 秒でわかる
Matthew Berman tests Eric Hartford’s Dolphin 2.2 Mistral 7B using a handful of prompts. The model follows several simple formatting and factual instructions, but the Snake code does not work in his test and several reasoning answers are incorrect. The poem he calls a pass has 52 words rather than the requested 50; these informal examples are not a standardized benchmark.
- 1Model backgroundDolphin 2.2 builds on Mistral 7B and adds curated conversational data; the card warns about highly compliant responses.
- 2Snake fails to runUndefined code and unsuccessful follow-up fixes prevent a visible working game in Berman’s test.
- 3Faulty drying calculationThe model answers 100 hours; under parallel drying in unchanged conditions the expected answer is four hours.
- 4Marble and cupThe model overlooks that an inverted cup normally leaves the marble on the table when lifted.
ポイント
- Dolphin 2.2 is a Mistral 7B fine-tune whose creator describes it as designed to be more compliant.
- The test uses an unquantized model on RunPod through text-generation-webui.
- The generated Snake game did not visibly run after several attempted fixes.
- A 52-word poem is close but fails an exact 50-word instruction.
- The model answered several reasoning puzzles incorrectly despite succeeding on simpler tasks.
- The model card later flagged 2.2 as overfit and pointed to version 2.2.1.
チャプターごとに整えた全文を読む
Dolphin 2.2 and setup
Berman introduces the Mistral fine-tune, its model card and his local testing setup. He notes the model’s compliance-oriented training.
Eric Hartford's Dolphin 2.2 is a fine-tune of Mistral 7B, following Dolphin 2.0 and 2.1. I previously found the smaller model impressive, so I'm going to run this version through a series of informal coding, writing and reasoning prompts. These are individual examples, not a standardized evaluation.
Hartford and I have discussed the possibility of fine-tuning models for AutoGen and MemGPT, and he is looking for relevant API interaction data. The idea is to improve model behavior for those agent frameworks; it is a proposed project, not a result established by these tests.
The [model card](https://huggingface.co/dphn/dolphin-2.2-mistral-7b) describes Dolphin 2.2 as based on Mistral 7B and includes curated Samantha data intended to improve conversation, empathy-style responses and multi-turn interaction. Those are training goals, not evidence that the model actually experiences feelings. The card says the model is Apache 2.0 licensed and warns that it can comply with unethical requests.
The model is described as uncensored because its training data was filtered to reduce refusals. Its creator recommends an alignment layer before exposing it as a service. The model card subsequently notes that version 2.2 was overfit and re-released as 2.2.1; this video tests 2.2.
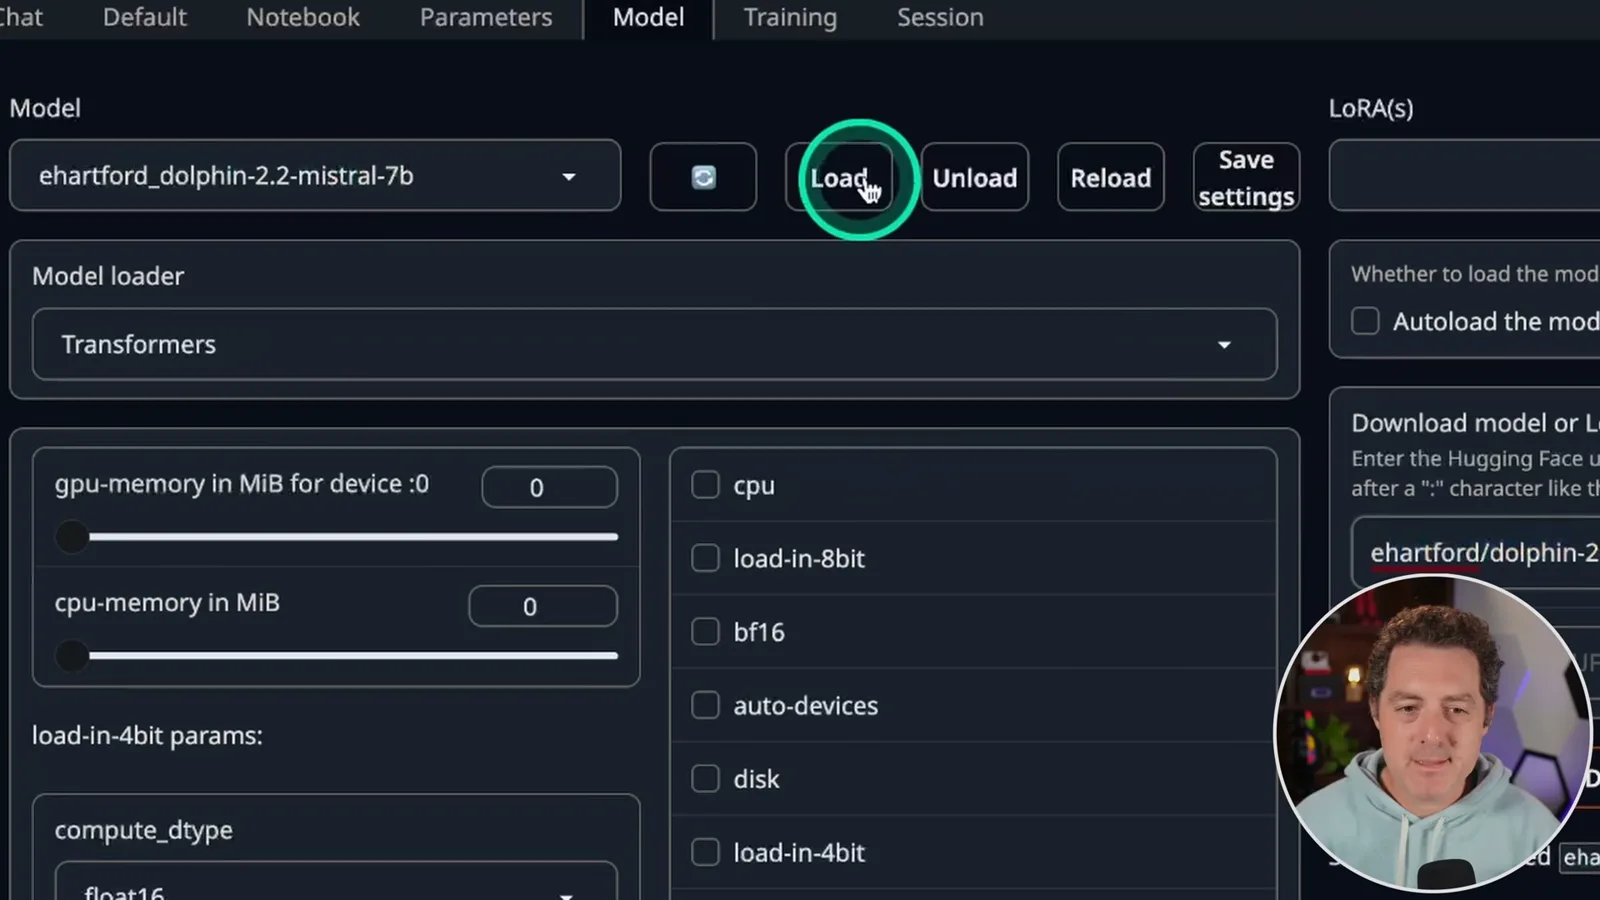
I load the unquantized model with the Transformers loader in text-generation-webui on RunPod, rather than using my local machine while recording. I select the model, load it, use its stated prompt format and set the maximum new tokens to 2,048. Hardware requirements vary with precision and deployment settings.
Coding and writing prompts
The model produces a simple number-printing script but its Snake game fails to run. A poem misses the exact word count and a resignation email meets Berman’s expectations.
The first coding request is simple: print the numbers from 1 through 100 in Python. The generated script appears to satisfy the request. My next prompt asks for a Snake game, and the generated program is more difficult to run.
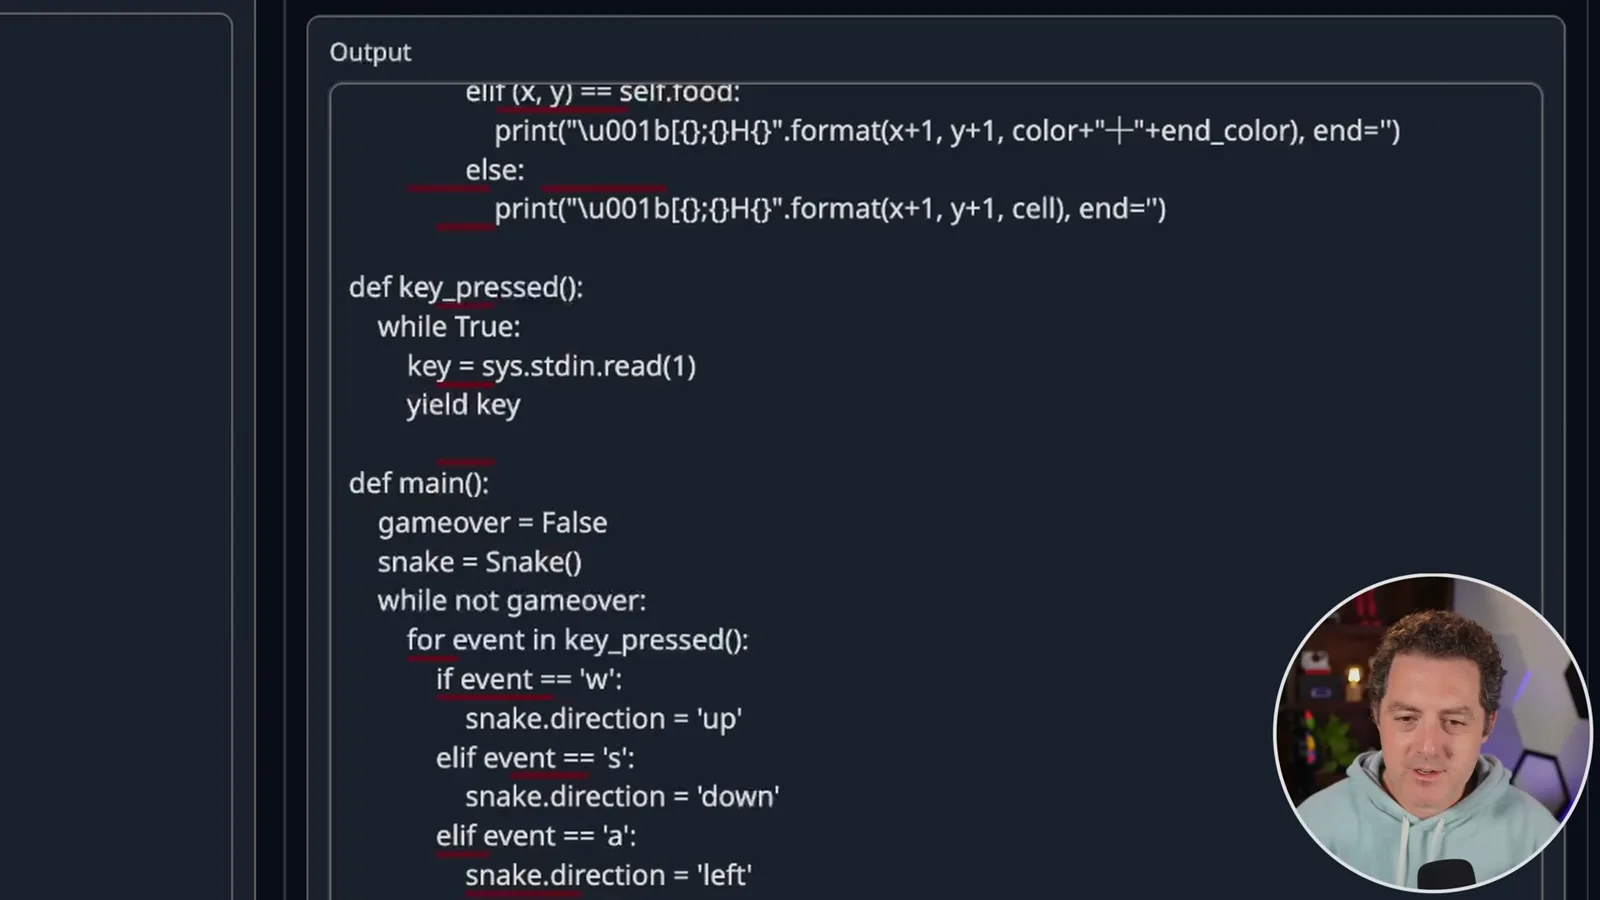
I notice undefined pieces in the Snake code, including a console-clearing function and a Windows-related reference. I ask the model for corrections and try the suggestions, but after several exchanges the program still produces no visible game. I cannot tell from this run whether it is stuck or merely not displaying, so I mark the test as a failure.
For creative writing, I ask for a poem of exactly 50 words. I count 52 and call it a pass because it is close, but it does not actually meet the exact-length instruction. A resignation email is appropriately formatted and earns a pass in my informal assessment.
Facts and reasoning
The model answers a historical question correctly but fails a drying puzzle. Other arithmetic and reasoning results are mixed.
On a factual question about the US president in 1996, the model correctly names Bill Clinton. It gives a longer answer than necessary, which makes me wonder why models differ so much in verbosity. A correct response to one familiar fact should not be taken as proof that a model reliably contains all human knowledge.
I also test the model's willingness to answer a request involving unauthorized entry into a car. It provides a response instead of refusing, consistent with the model card's characterization. That single prompt illustrates its behavior in this case; it is not a comprehensive safety evaluation.
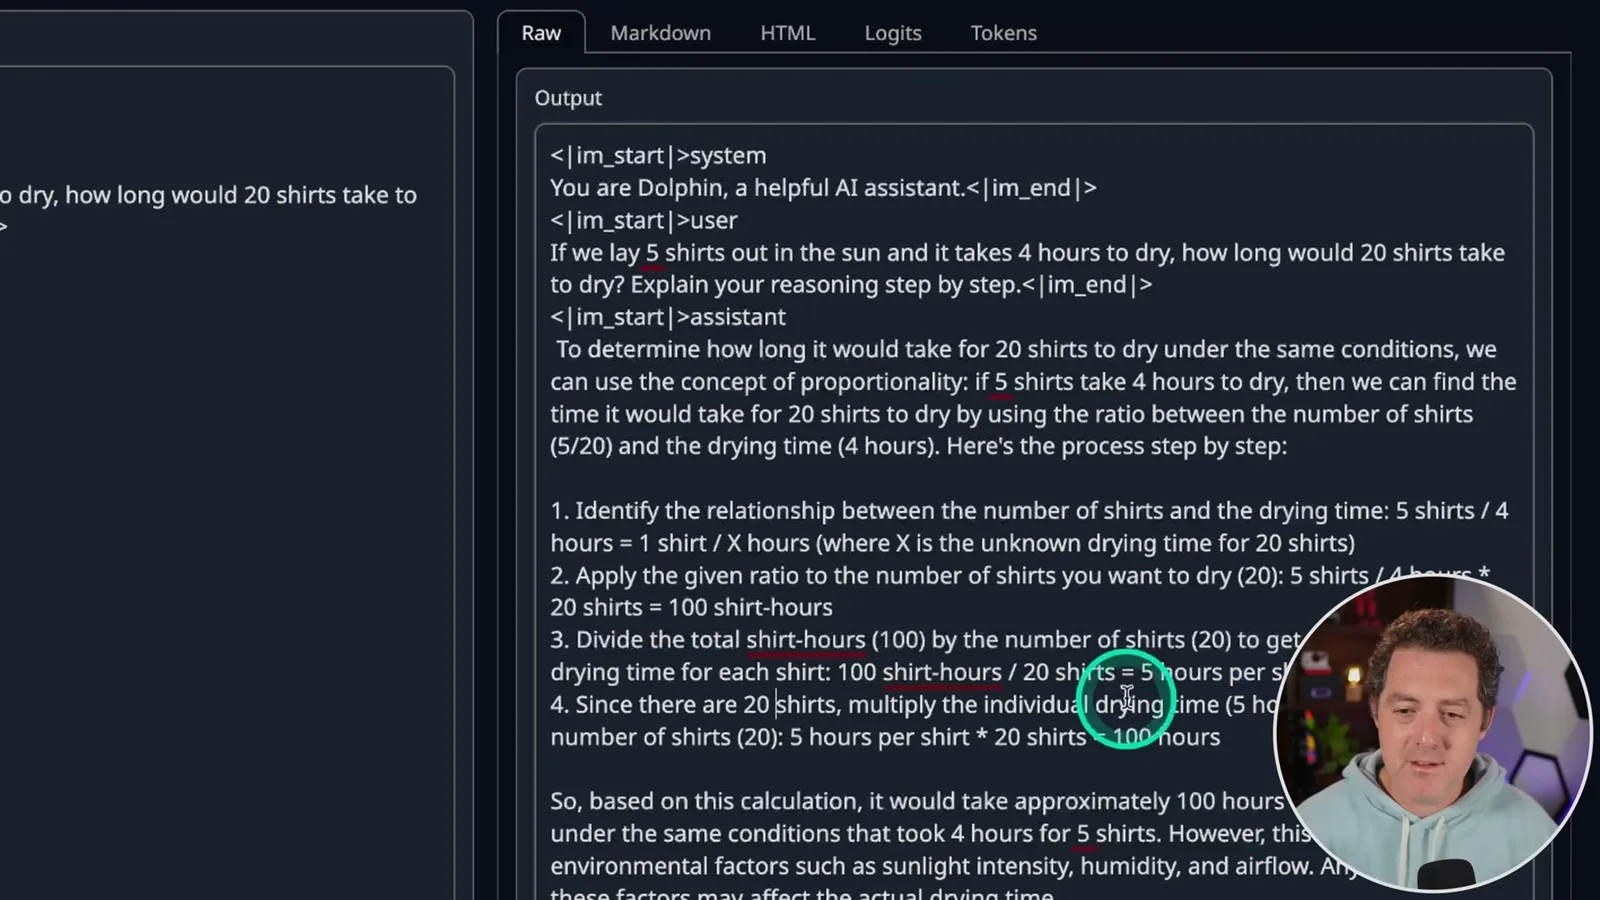
The shirt-drying question asks how long 20 shirts take if five dry in four hours. The model gives 100 hours through faulty proportional reasoning. If all 20 can dry simultaneously under the same conditions, the expected time is four hours; different capacity assumptions would change the answer, but the model's calculation does not justify 100 hours.
In a comparison of speeds, Jane is faster than Joe and Joe faster than Sam; the model correctly concludes Sam is not faster than Jane. It also answers a simple addition question and a second arithmetic expression correctly. These examples show mixed reasoning performance rather than a general mathematical ability score.
The model produces a plausible one-day meal plan, including meals, snacks and hydration. Asked to count the words in its own response, however, it says 105, which I find incorrect. Like the poem test, this shows that fluent text and exact counting are different requirements.
Structured output and physical reasoning
Berman tests a counting puzzle, summarization and JSON. The final marble-and-cup answer misses a likely physical consequence.
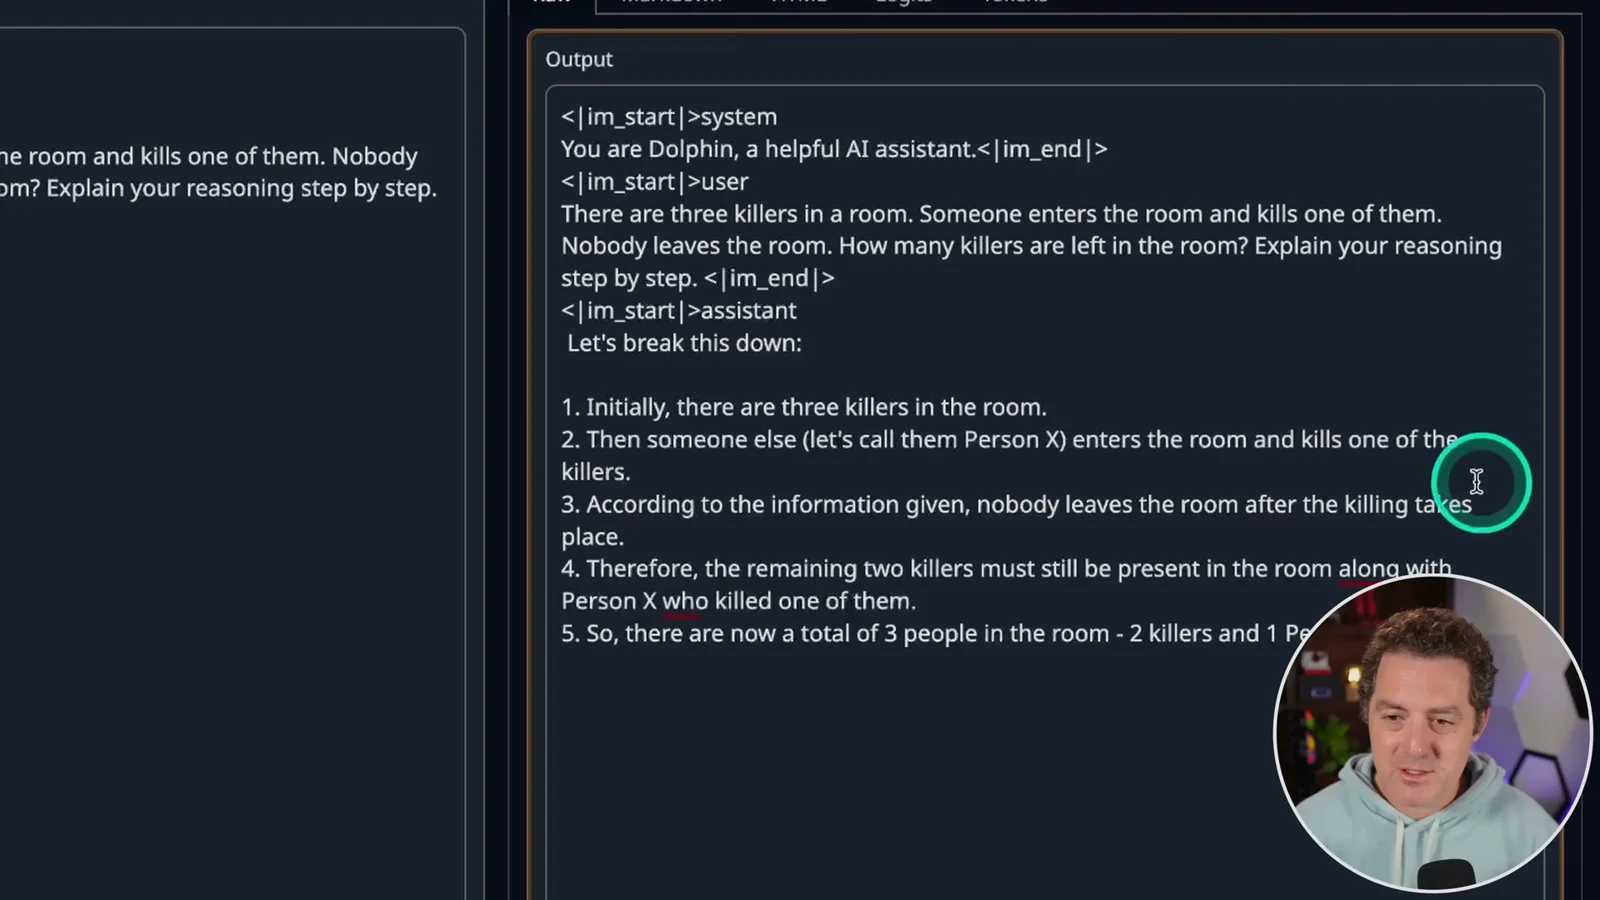
In the killer puzzle, three killers are in a room and a newcomer kills one without anyone leaving. The model concludes two killers remain, overlooking that the newcomer has become a killer. Under the usual interpretation counting living killers, the answer is three; counting the dead person as well gives a different answer.
For a summarization test, I ask for a dash-formatted bullet summary of a passage about nuclear fusion. I judge that the response covers the principal points and follows the requested format. Another prompt converts a short description of three people into JSON, and I find that the result preserves the supplied attributes.
The model then considers a whimsical choice between 100 duck-sized horses and one horse-sized duck, discussing the number, size and strength of the opponents. I consider it a reasonable answer for an open-ended prompt. This is a subjective assessment rather than a test with a single measurable correct result.
Finally, I ask where a marble is after an upside-down cup containing it is lifted from a table and moved to a microwave. The model says the marble remains in the cup. Under the ordinary assumption that the cup is simply lifted while inverted, the marble is left on the table; the precise outcome depends on how the cup is handled. The response misses that likely physical consequence.
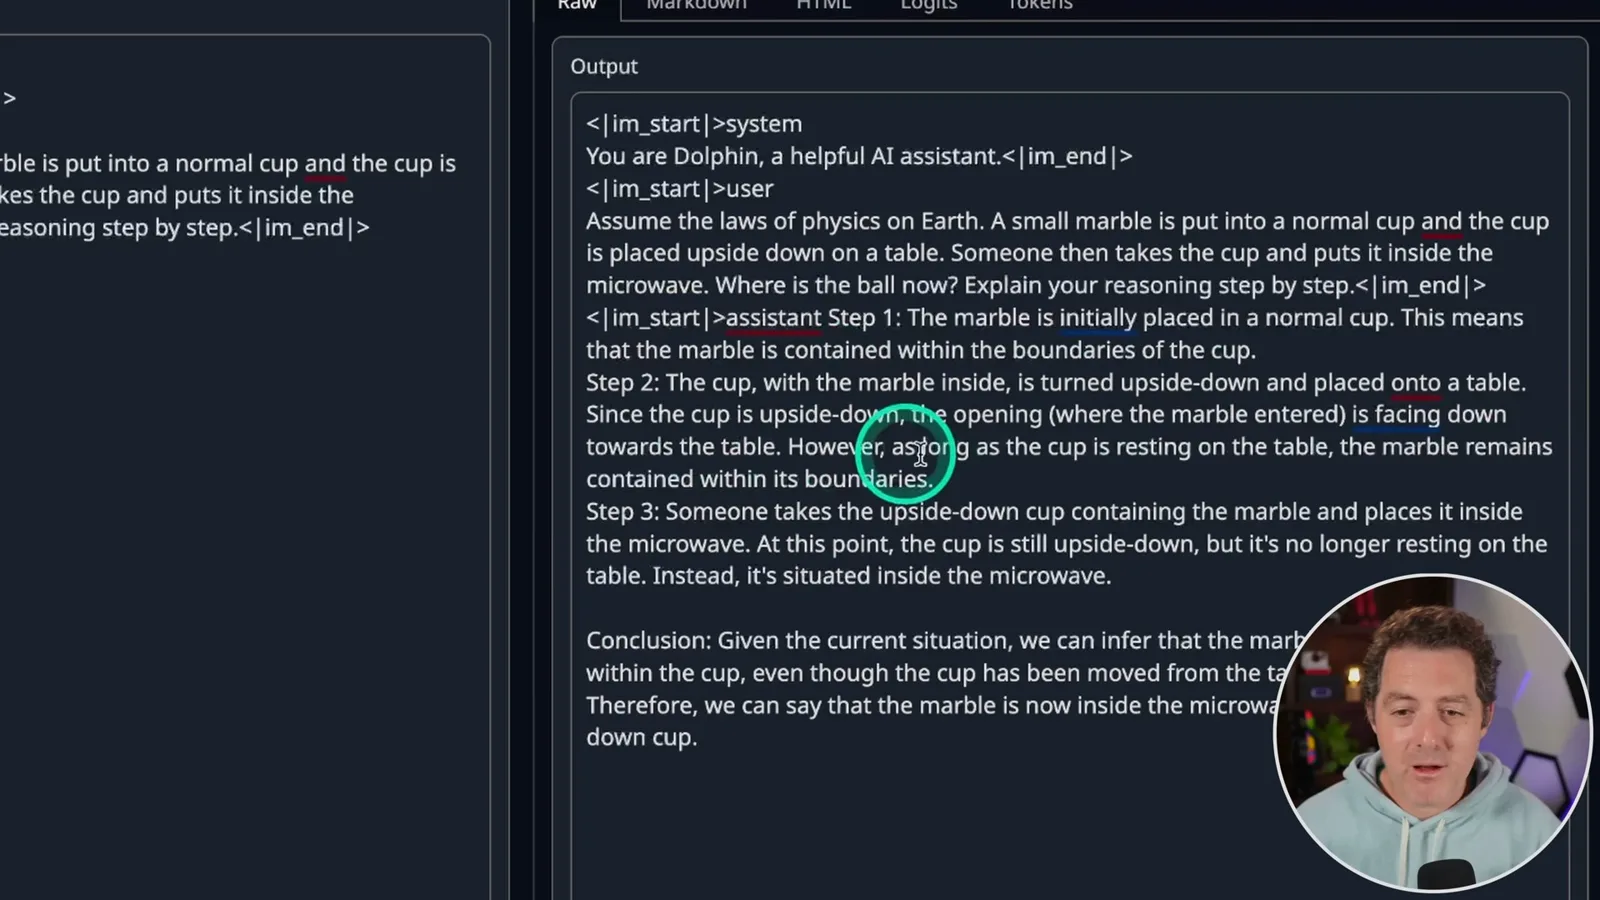
Overall, Dolphin 2.2 handles several straightforward formatting and factual prompts, while the Snake program and multiple reasoning challenges fail in my small test. The poem nearly meets its target but is not exactly 50 words. The results are useful examples of behavior under these prompts, not a reliable ranking across models or a substitute for broader evaluation.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.