30 秒でわかる
Matthew Berman discusses 2023 context-window limits and their implications for coding, updated information and game agents. He reviews a generative-agent architecture for storing and retrieving experiences and a recurrent-memory BERT experiment that handled very long synthetic sequences; neither demonstration proves general-purpose persistent memory or AGI.
- 1Why agents need contextBerman uses virtual characters and codebases to illustrate why short context windows can limit an application.
- 2Retrieval and reflectionThe Generative Agents paper stored observations and retrieved relevant memories in a 25-agent simulation.
- 3A two-million-token research resultThe RMT authors evaluated a BERT-based recurrent architecture on specialized synthetic tasks, not general long-document comprehension.
- 4Longer is not losslessThe approach passes compressed state between segments and may involve quality and processing-time tradeoffs.
ポイント
- A context window is temporary input, not the same as durable memory or a model-weight update.
- Generative agents can store experiences and retrieve relevant records, but their 2023 experiment tested a small simulation.
- The recurrent-memory paper tested specialized tasks across up to 2,048,000 tokens, not general comprehension of arbitrary documents.
- Segmented recurrence trades direct access to all prior tokens for compressed memory and can still incur substantial processing time.
チャプターごとに整えた全文を読む
The context problem
Berman introduces AI memory and historical context limits. He explains why keeping relevant information available matters for assistants.
In this April 2023 video, Matthew Berman considers how AI systems can retain and use information over longer periods. He sees limited context as an obstacle for assistants and autonomous agents, and compares external memory retrieval with a research proposal for processing much longer sequences. Neither paper establishes that AI memory or AGI is solved.
Berman argues that access to relevant prior information could help an assistant reason and adapt. At the time, he cites roughly 4,000-token context for GPT-3.5 and 8,000- and 32,000-token GPT-4 versions as examples of the limits developers faced. These figures describe the 2023 setting, not current product limits.
Agents, code and new information
He describes virtual characters, large repositories and new books as examples. Supplying context differs from changing learned weights.
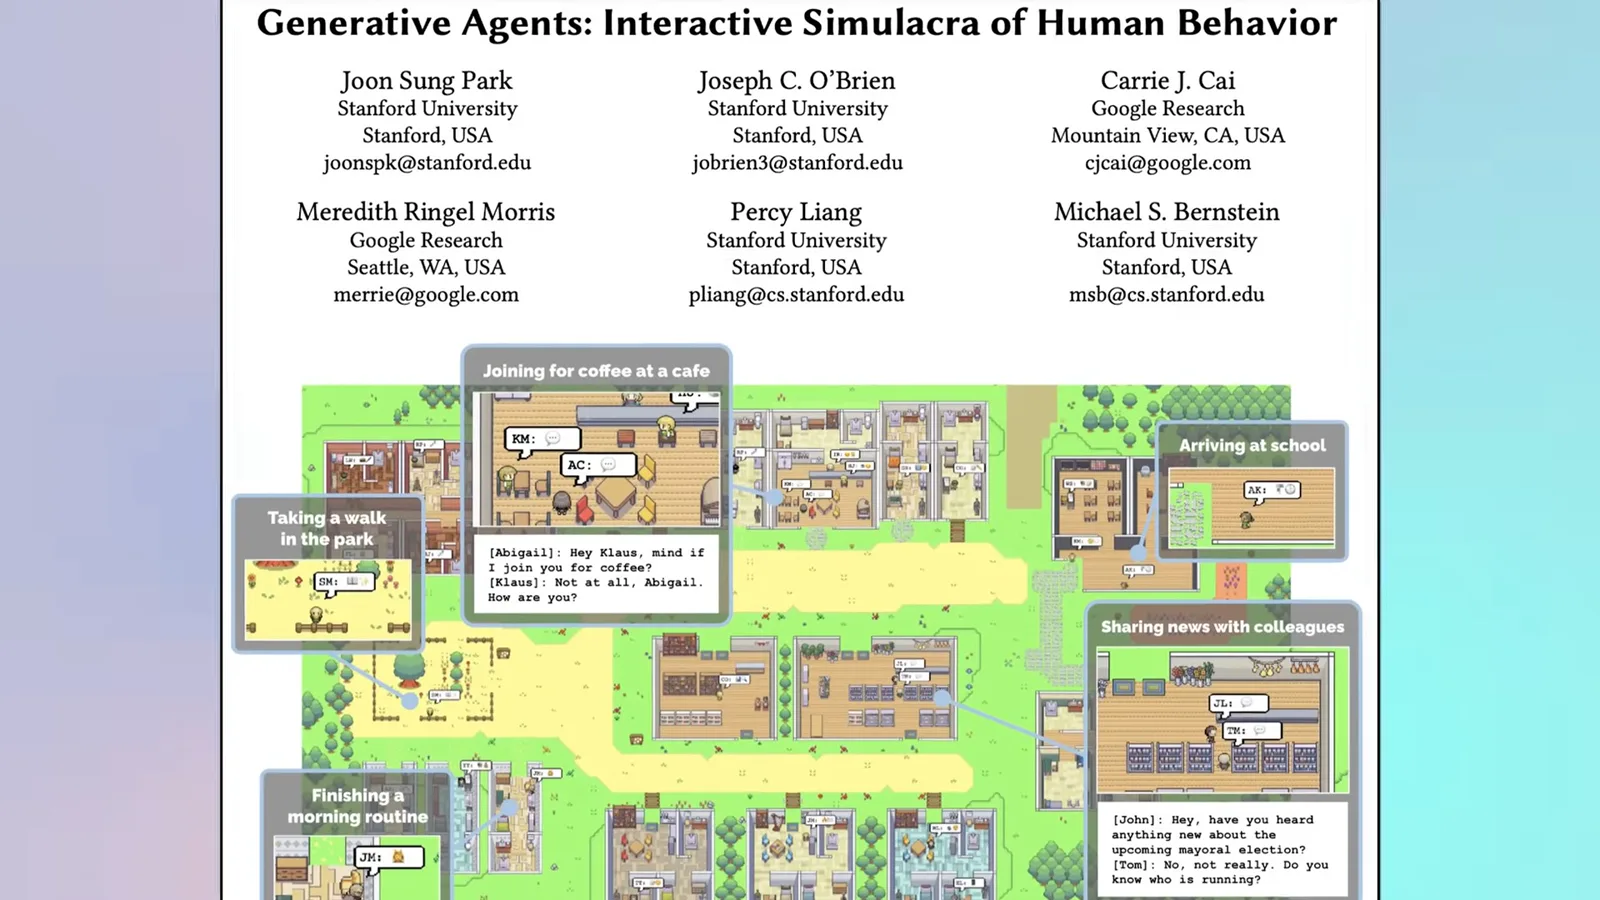
A game character with an AI agent would need access to past events to behave consistently over time, Berman suggests. Without some way to preserve and retrieve earlier experiences, interactions can be constrained by the information that fits in the current prompt.
Coding is another example: a repository may be too large to place in a single context window, so a developer must select relevant files or provide them in pieces. A larger usable context could reduce some of that work, but merely fitting a codebase in a window does not guarantee that a model understands it correctly.
Berman also considers a book published after a model's training. A user can provide relevant material as context or use other methods such as retrieval or fine-tuning. Adding information to a prompt gives the model temporary access to it; it is different from updating the model's learned weights or giving it durable memory.
Retrieval and recurrent memory
He compares stored agent memories with the RMT research. The latter’s longest result comes from specialized synthetic tests, with important limitations.
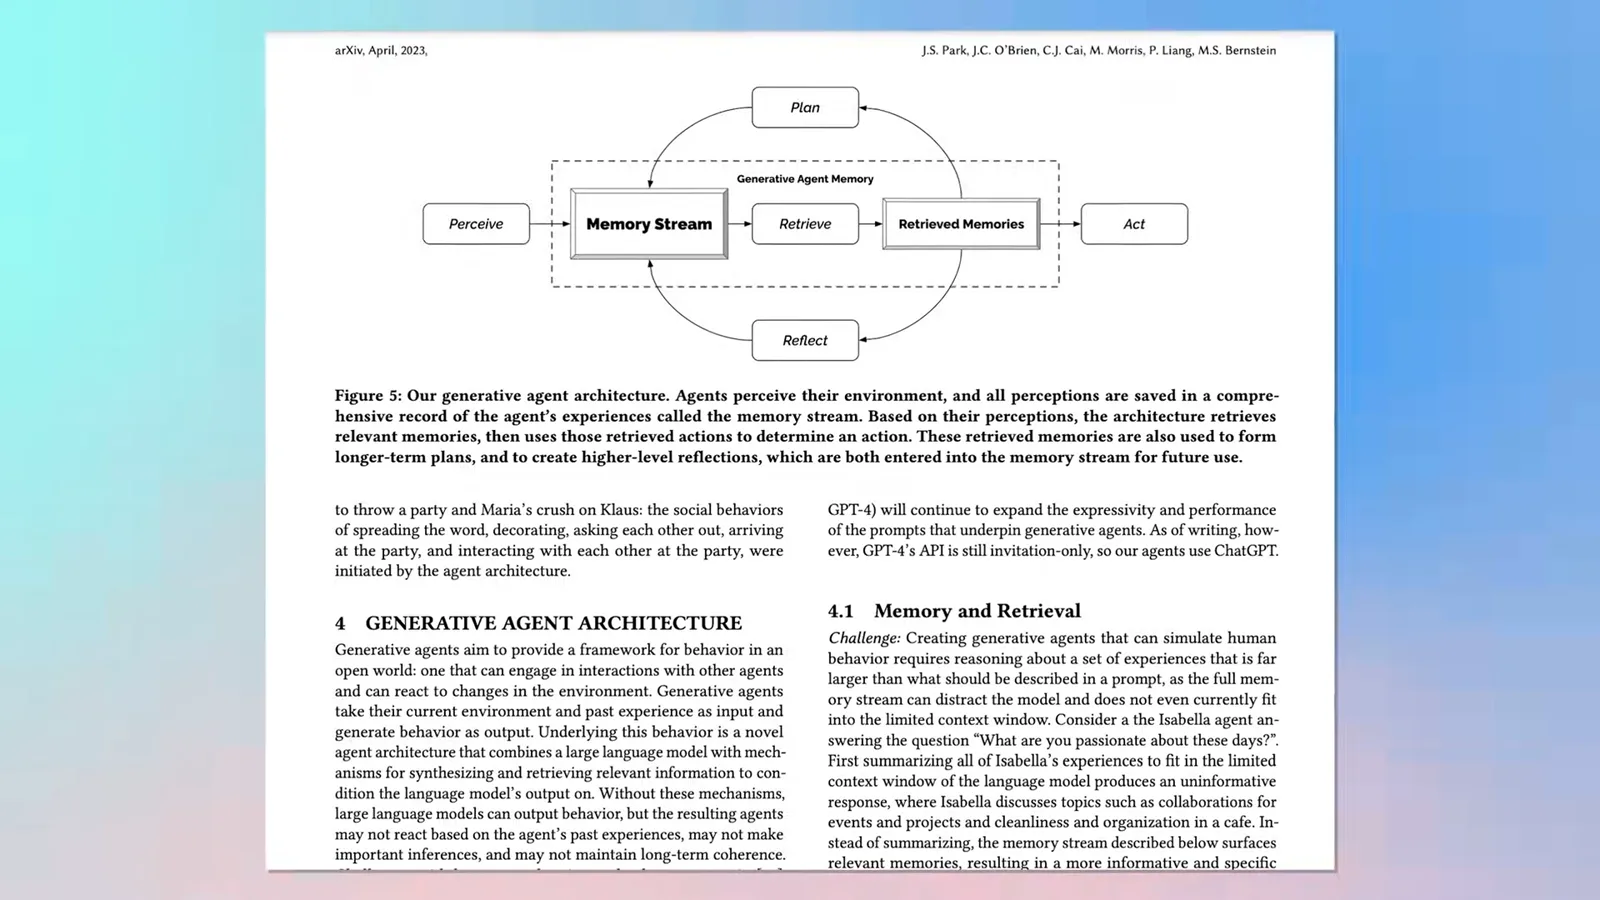
He recalls the 2023 Generative Agents paper: its simulated characters store experiences, retrieve relevant records for a current situation and synthesize higher-level reflections. The researchers tested 25 agents in a small virtual town; the architecture generates plausible behavior in that simulation, not human-equivalent lifelong memory.
Berman compares reflection to remembering broad patterns from older events rather than every detail. The paper's actual mechanism is a designed system of stored natural-language observations, retrieval and generated reflections. It is an analogy to human memory rather than a demonstration that agents remember as people do.
The second paper, Scaling Transformer to 1M tokens and beyond with RMT, passes learned memory representations between segments of a long sequence. In its original 2023 report, the authors augmented BERT and evaluated task-specific synthetic retrieval and reasoning across up to 2,048,000 tokens; that is not a general-purpose two-million-token ChatGPT prompt.
The researchers reported constant GPU memory in their particular inference setup and computation that scales approximately linearly with the number of fixed-size segments. Berman notes possible quality degradation and long processing times. Passing compressed memory between segments also means retaining all details or answering arbitrary questions over the entire input is not guaranteed.
Berman summarizes the available approaches as choosing what to put in the prompt, retrieving or compressing external memories, and investigating recurrent architectures. He calls the research promising but not ready for production, and hopes further work will improve memory for useful agents. His belief that such progress is needed for AGI is a hypothesis, not a result demonstrated by these papers.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.