30 秒でわかる
Girish Konda argues that concurrent subagents can return partial work as success, repeat writes after a lost reply or amplify a shared guess. His SAFE handoffs model attaches sources and freshness to facts, gives side effects identities, bounds fan-out and validates named outcomes in code. He emphasizes that the design adds latency and does not guarantee exactly-once delivery or undo partial work.
- 1A timeout does not prove a worker failedA slow worker, a crash and a lost reply can look alike to the caller.
- 2Shared guesses can masquerade as corroborationSeveral workers can repeat one unsupported claim.
- 3Retries can repeat a real side effectKonda recommends identifying the action and checking its outcome.
- 4A handoff needs a code-enforced outcomeThe orchestrator should check schema, evidence, freshness and calculations.
ポイント
- A timeout means the outcome may be unknown.
- Agents repeating the same shared guess are not independent confirmation.
- Bind side effects to identities and inspect their outcomes before retrying.
- Validate evidence and named states in code, and choose controls according to risk.
チャプターごとに整えた全文を読む
Subagents inherit distributed-system failures
Konda explains partial results, timeouts and shared-context risks.
Girish Konda, a Microsoft principal software engineer, introduces his open-source MCP Pacemaker and says the talk reflects his own views. He argues that subagents inherit familiar distributed-systems failure modes.
An orchestrator divides work among concurrent workers that read shared context and call external tools, then combines their results. Those ingredients make coordination a distributed-systems problem.
Konda identifies partial failures disguised as success, unchecked shared information, unbounded fan-out and retries that repeat side effects.
A worker may crash, fail to reply or return a fluent but wrong answer. A half-finished agent can look successful because its result has the same text format as a completed task.
He describes three alert investigations that all reported the same conclusion: one checked telemetry, another matched a title and a third invented an answer. The conclusion alone did not reveal the work performed.
A timeout cannot by itself distinguish a slow worker from a failed one or a lost reply. Konda says it should be recorded as an unknown outcome rather than treated as proof of failure.
In MCP Pacemaker, a first launch could exceed the ordinary timeout while downloading. A separate initialization timeout addressed that case; another fix preserved the crash cause instead of overwriting it with a timeout.
He recommends that a handoff report a named status, work completed and omitted, evidence and side effects. Partial completion should be a valid result.
A check that returns no is different from a check that could not be performed. Conflating them affects retries, escalation and later auditing.
For dirty reads, he gives an example where one worker guesses that an error rate fell by 80%. Two others repeat the claim, and the orchestrator sees apparent agreement backed by only one unsupported source.
Three agents reading the same claim are not independent confirmation. Konda contrasts that with quorum systems whose guarantees depend on overlapping reads and writes.
A consistency model for handoffs
SAFE combines source reads, at-most-once effects, fan-out budgets and explicit outcomes.
He surveys consistency terms including linearizable, sequential, causal, session and eventual consistency. He says a shared context alone does not establish any of these guarantees.
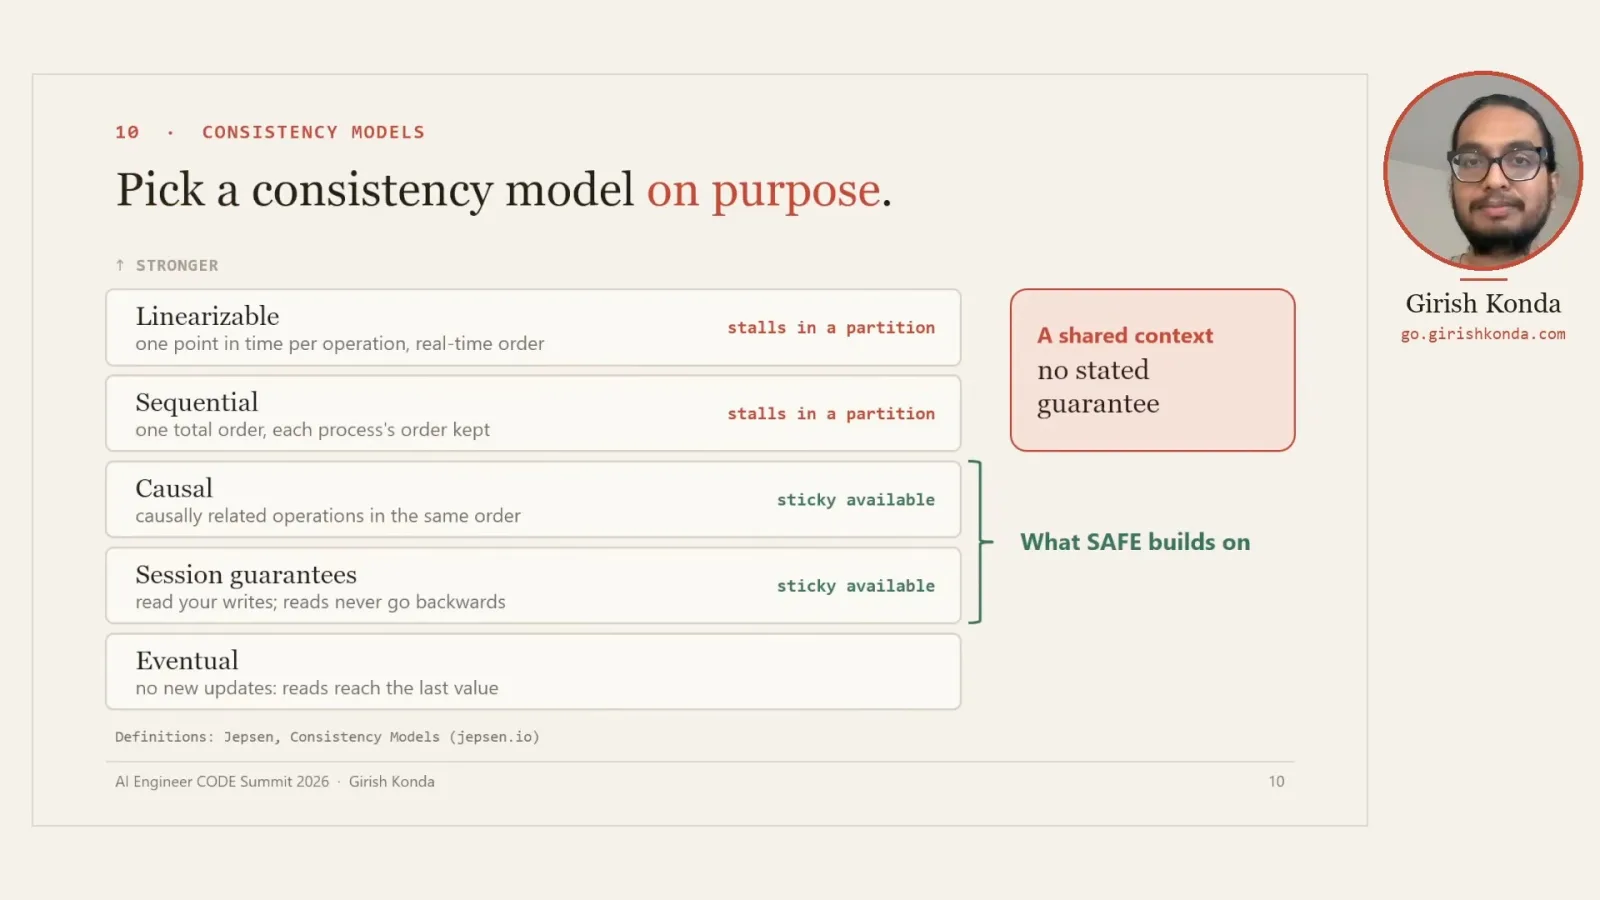
His proposed SAFE handoffs model uses source reads, at-most-once effects, fan-out budgets and explicit outcomes. He presents it as his own design for agents touching real systems, not a universal standard.
For source reads, a factual record should identify its source, version, scope and relevant times. Freshness must be checked when the information is used.
In his example a five-minute freshness window accepts data for an early decision but rejects it for a later one, which must read the source again.
Retries, approvals and flow control
Action identities, read-back, fencing and bounded concurrency address different failures.
A retry after a lost response can repeat a real write, such as creating a pull request. The caller knows the outcome is unknown and should not assume that nothing happened.
Konda distinguishes at-most-once delivery, which can lose work, from at-least-once delivery, which can duplicate it. Deduplication requires a mechanism such as an identity key.
His bridge can replay an initialization handshake after restart but does not replay an uncertain tool call. A caller should inspect the actual outcome.
For a side effect, he proposes an action identity, approval bound to that action and a read-back. A submitted action is confirmed only when its effect is observed.
A lease can expire while a worker is paused. A fencing token that increases on each grant lets storage reject a stale worker’s later write; Konda applies the same principle to checking approvals at the gate.
Unbounded fan-out is a flow-control problem. He recalls simultaneous package-manager cold starts corrupting a shared cache even though each individual request was reasonable.
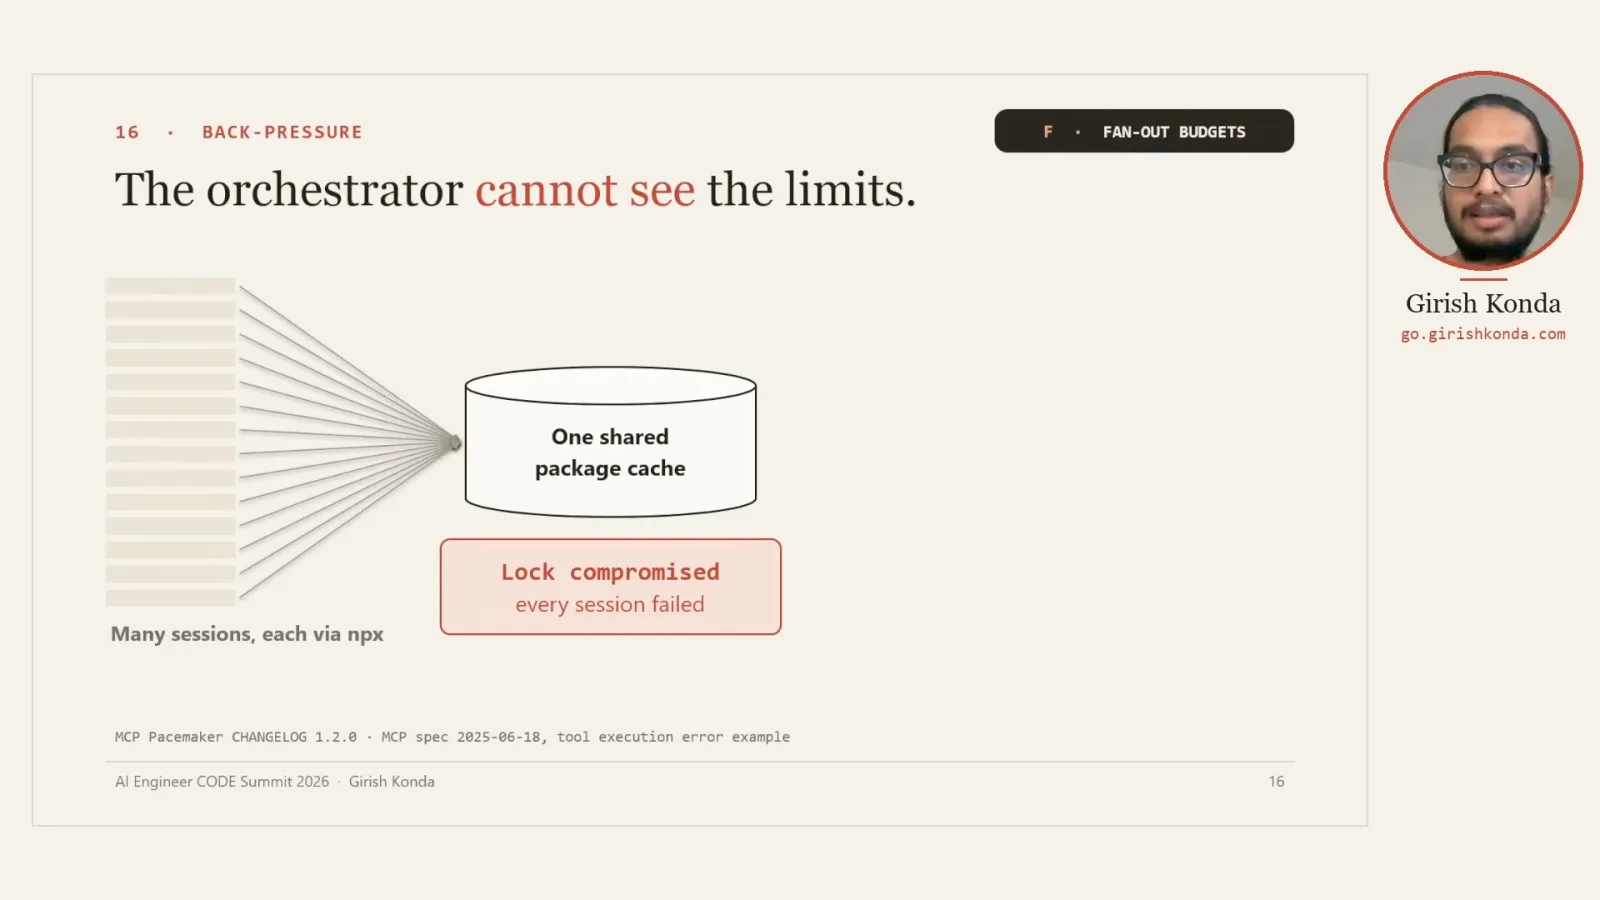
His bridge gates some cold starts, bounds the wait and deliberately allows a start after the deadline. He says that choice favors availability over the risk of cache corruption and should be documented.
A separate session cap waits briefly and then refuses new work; refusal counts as a health failure. Capacity must be reserved before a start to avoid a check-then-act race.
Validate outcomes and understand the limits
Code checks evidence and calculations, while the design has costs and cannot guarantee everything.
Explicit outcomes require code to validate the result schema, evidence, freshness and calculations. A failed check should return a refusal with a reason, not merely append a warning to accepted text.
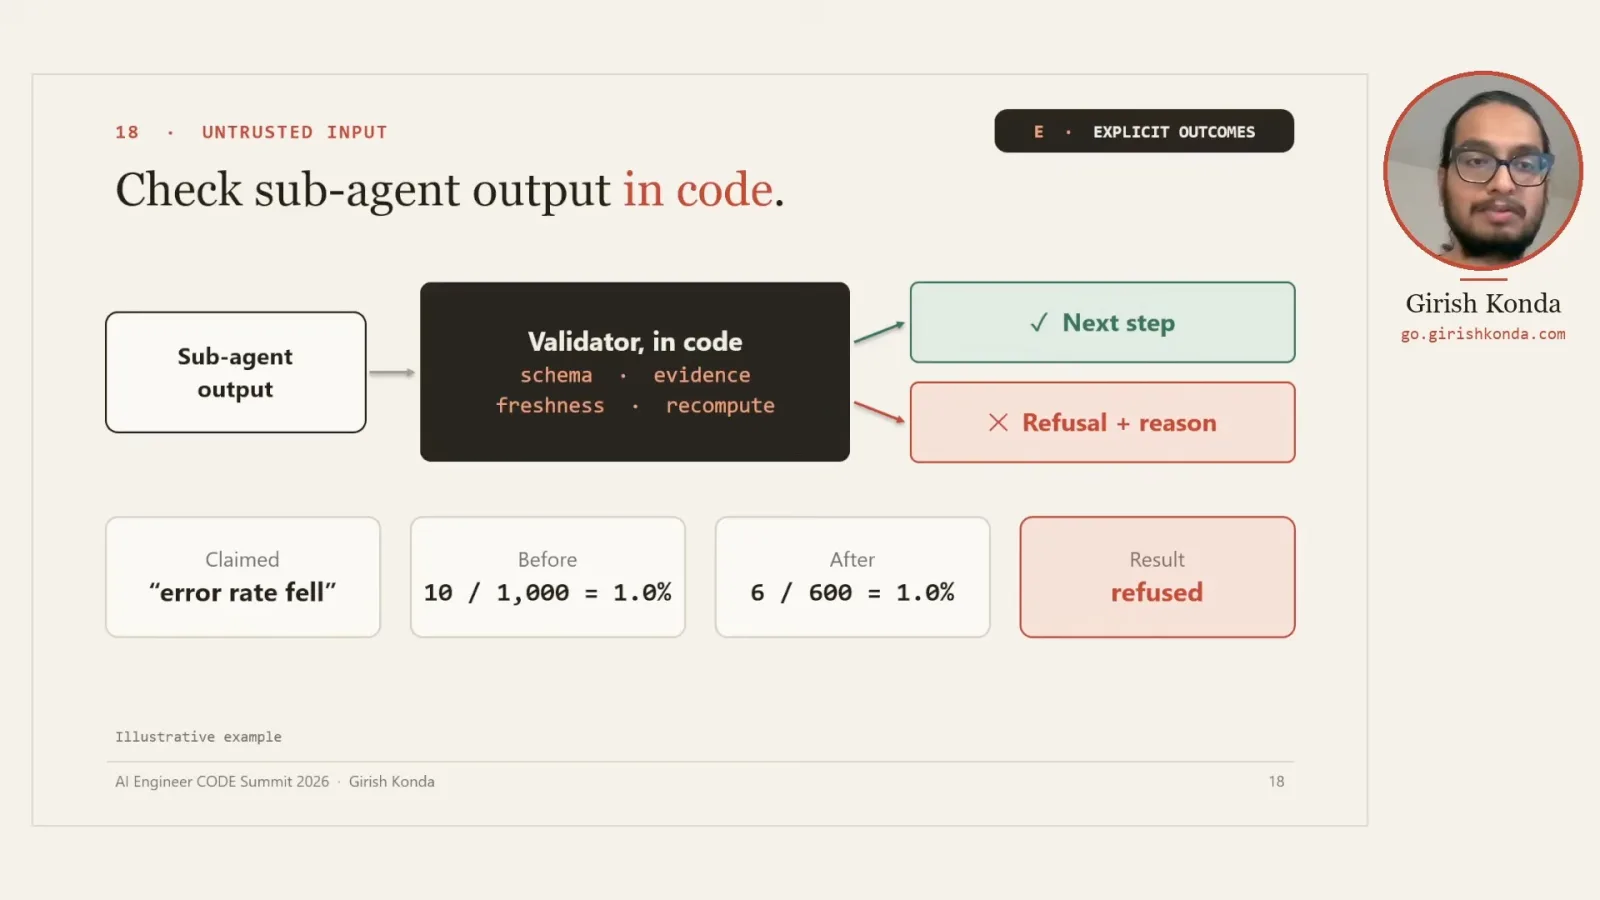
He illustrates this with ten errors in 1,000 requests versus six in 600: the raw count falls, but both rates are 1%. Recomputing the rate rejects the unsupported claim of improvement.
SAFE does not prove a source is correct, guarantee exactly-once delivery, roll back partial work or create a global order across workers. Lost replies still require read-back or other resolution.
The checks cost latency and can reduce availability. Konda says they may be unnecessary overhead for an agent that only drafts text a person reviews, and his design assumes a single orchestrator.
He closes by asking builders to treat handoffs as network calls, return explicit states and enforce appropriate checks in code.
同じチャンネルの記事
 26:49EN
 AI Engineer· 2026年11月11日Ara Khan: Choose work that improves with AI without being replaced by itAra Khan · ClineCline’s Ara Khan explains an automated evaluation loop and urges engineers to pick problems that benefit from model progress.
 38:50ENAI Engineer· 2026年11月10日LinkedIn’s self-improving agent first had to fix its judgesZiwei Guo, Saloni Gandhi · LinkedInA prompt-optimization loop improved a career agent, but unreliable evaluators required human calibration first.
 12:48ENAI Engineer· 2026年11月10日Brian Douglas: Turn agent corrections into reusable review knowledgeBrian Douglas · Paper ComputeThe Paper Compute developer captures expert pushback in coding sessions and tests ways to reuse it during review.
 12:20ENAI Engineer· 2026年11月10日Ayush Bhardwaj: Agent workarounds are feedback for your CLIAyush Bhardwaj · Allos AIAn audit of coding sessions shows where output, errors and stale instructions force agents to improvise.
 12:57ENAI Engineer· 2026年11月10日Harvey’s agents scaled until their platform and merge queue brokeJoey Wang · HarveyAfter an alert spawned 900 agents and one engineer launched 950 tasks, Harvey added deduplication and fair scheduling.
 51:48ENAI Engineer· 2026年11月10日Compose small decisions before reaching for a generative modelRaymond Weitekamp · OpenProseRaymond Weitekamp demonstrates recursive decision models and sketches a voice-first computer interface.