30 秒でわかる
Bumble product manager Supriya Subudhi shares five lessons from testing AI-generated photo feedback. She describes the gap between stated interest and adoption, the need to inspect individual outputs, model economics, and restrictions on launching in different markets.
- 1Interest did not predict adoptionAbout 78% expressed interest, but 10–15% used the tested feature.
- 2Averages hid flawed adviceSome users were told to smile more despite already smiling.
- 3Success increased the billThe initial model cost about ten times as much as a simpler approach, before evaluation costs.
- 4Changing the model changed the resultA cheaper model reduced costs but also reduced accuracy and impact.
- 5A positive test did not mean a global launchThe US version could not be shipped unchanged to other markets.
ポイント
- Measure actual adoption as well as stated interest.
- Inspect individual outputs and user segments instead of relying on averages.
- Include inference and evaluation costs when judging a successful test.
- Retest model changes because the benefit may depend on the model.
- Consider legal and compliance requirements before choosing rollout markets.
チャプターごとに整えた全文を読む
Why AI A/B tests are different
Subudhi introduces the product and the limits of a positive test.
I'm Supriya Subudhi, a product manager at Bumble. A/B testing compares two versions of a feature, email or experience to see which performs better. When generative AI and large language models enter consumer products, however, a positive result is the beginning of the investigation rather than the end.
Bumble has more than 20 million monthly active users. As a product manager, I represent users and their problems while remaining accountable for the company's finances: we don't have unlimited resources to solve every problem.
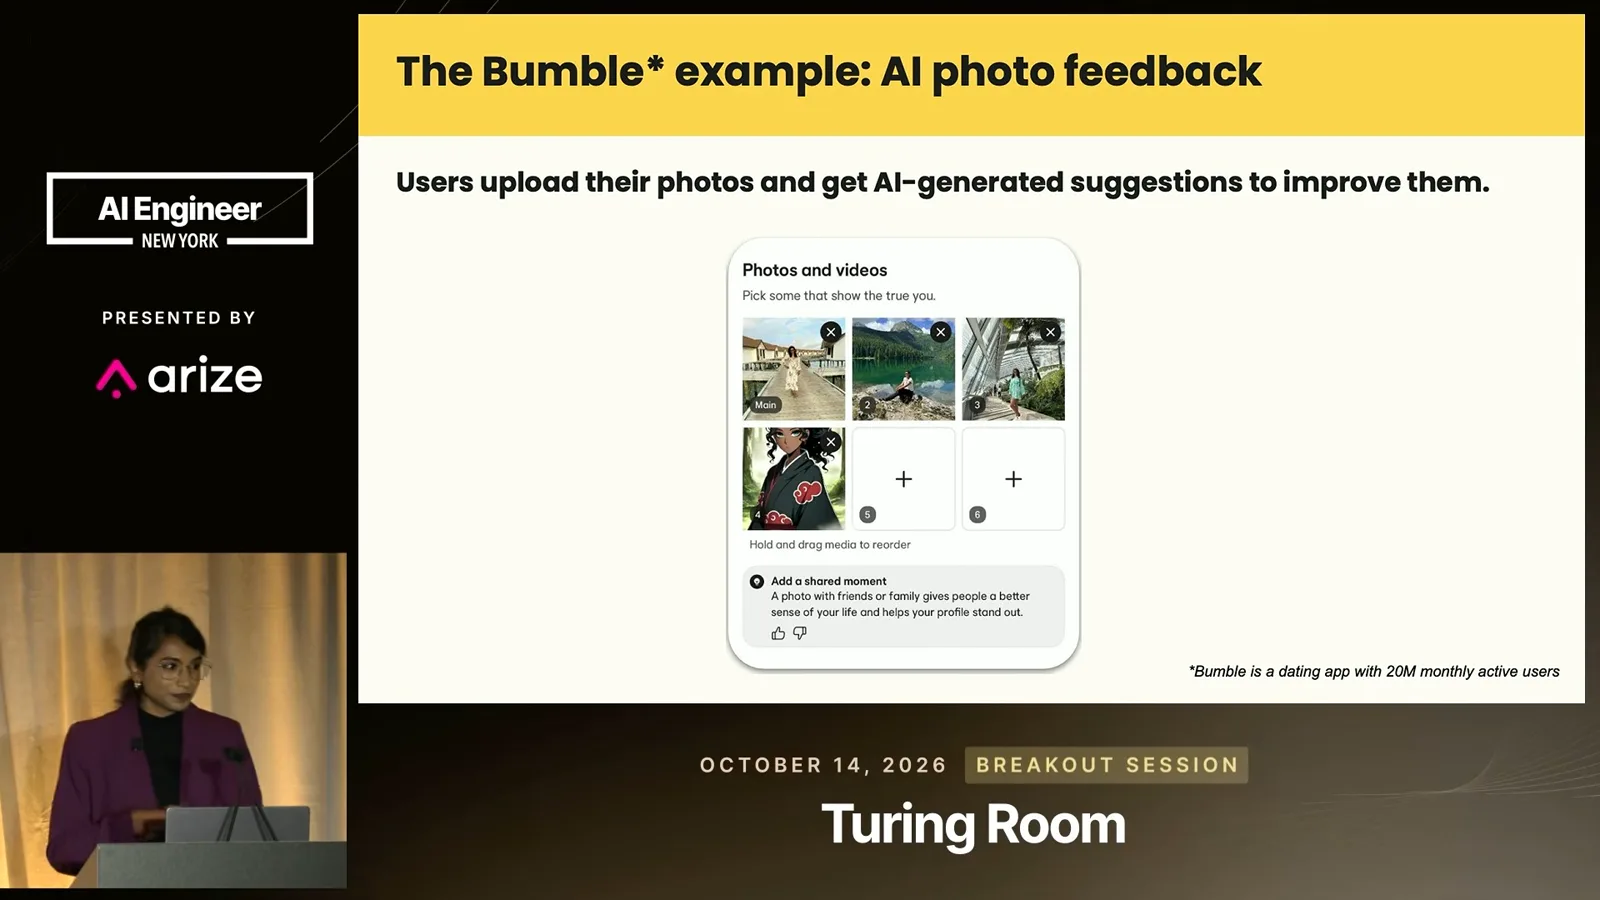
Our example is AI photo feedback. Dating-app users add pictures to a profile, but often don't know what a good profile looks like. We drew on Bumble's knowledge of what works to generate suggestions for improving the pictures people add.
Interest is not adoption
Research showed interest, but actual use was lower until the feature was integrated into user journeys.
The first lesson is that people can ask for a feature and then ignore it. In research, people repeatedly told us that they didn't know whether their dating profile was good enough and wanted support in understanding how to improve it.
We showed people possible forms of AI support that would help their dating journey without doing the dating for them. About 78% of the people we spoke to said they would love feedback. But in an A/B test, with half receiving the feature and half not, only 10–15% actually used it.
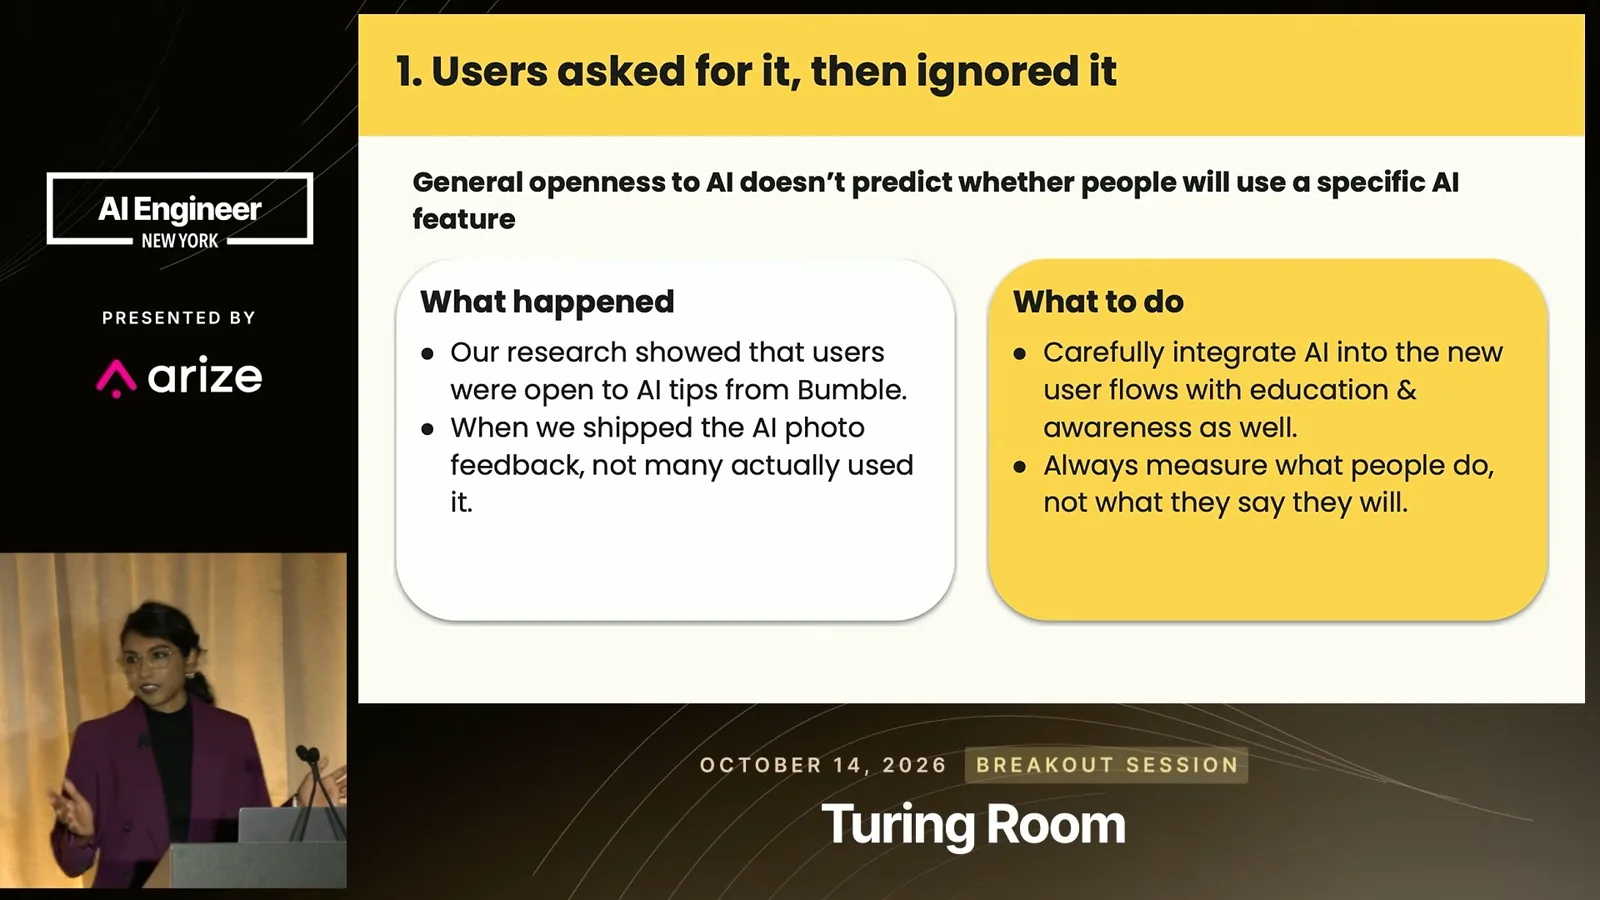
Openness to AI doesn't predict usage. We brought the feature into journeys people were already taking: when someone added a picture, we offered feedback; when someone struggled to find matches, we suggested checking profile feedback. Adoption rose. Measure actual use, not just the survey response, so that you can improve it.
Averages can hide the tail
Inspect real feedback and compare experiences across user segments.
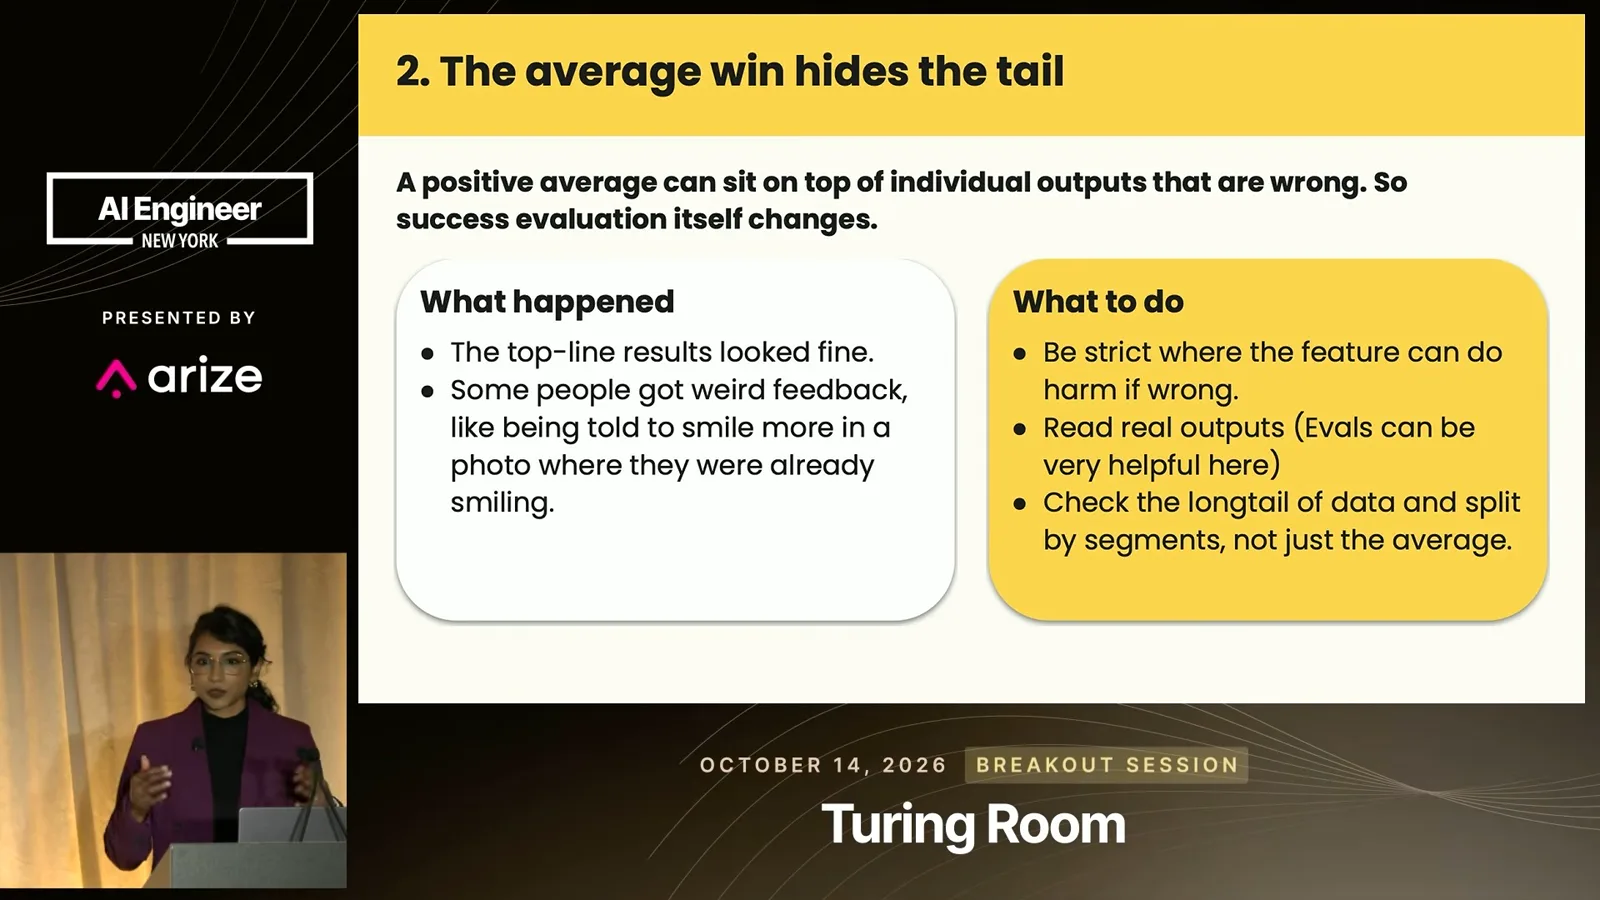
The second lesson is that an average win can hide the tail. The top-line results looked good: more people added pictures and made profile changes than in the group without feedback. But some AI tips told people to smile more when they were already smiling.
The acceptable scope of error depends on the application. A few poor selections from an AI music DJ are different from a banking app recommending a $2,000 expense someone cannot afford. This is why we established guardrails for what our generated feedback should and should not do.
For example, our feedback should not tell people to change things outside their control, such as skin color or height. We also read real outputs. Evaluation tools let us inspect what users were seeing and whether our prompts were doing a good job.
The success criterion changed from a simple green or red overall result to the distribution of experiences. Are women and men responding similarly? Are outcomes consistent across countries and languages? A French response, for instance, might differ from an English one.
The economics of a winning feature
Model and evaluation costs must be weighed against short- and long-term benefits.
The third lesson is the green dashboard and the red bill. We initially chose the best LLM to get the highest-quality, most accurate feedback. It cost roughly ten times as much as a simpler approach, before adding the cost of evaluating the system.
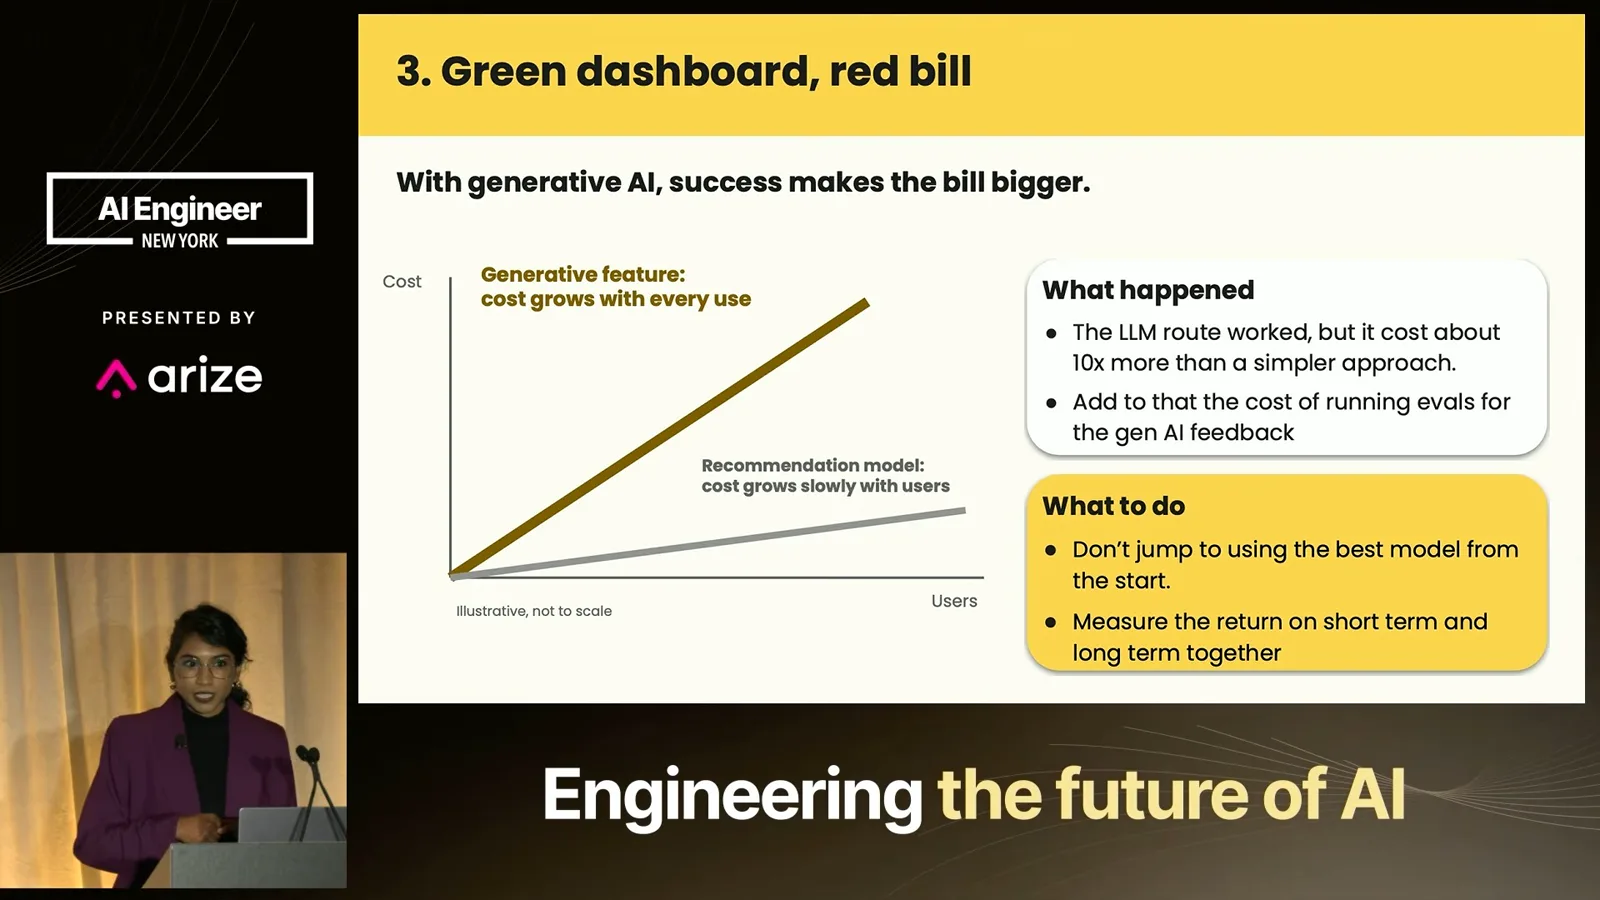
Bumble already uses AI in its matching algorithm, but the cost pattern differs. A traditional machine-learning algorithm can require considerable upfront compute and training, with a relatively small incremental cost per user after it is working. Generative AI bills grow as more people use the product more often.
Before picking a model, understand why the product uses AI. Some teams receive a mandate to add AI, but the budget should reflect whether the intended benefit is immediate or long-term. A short-term return may justify a quick calculation; a long-term strategic benefit may justify additional spending.
Consider Amazon's shopping assistant as an example. Better recommendations might increase near-term purchases, but even if they do not immediately do so, a trusted assistant could eventually make customers choose the platform more often. The objective determines what investment might make sense; this is an illustration, not a claim about Amazon's internal decision.
Model choice changes results
Testing alternatives reveals the relationship between cost, accuracy and impact.
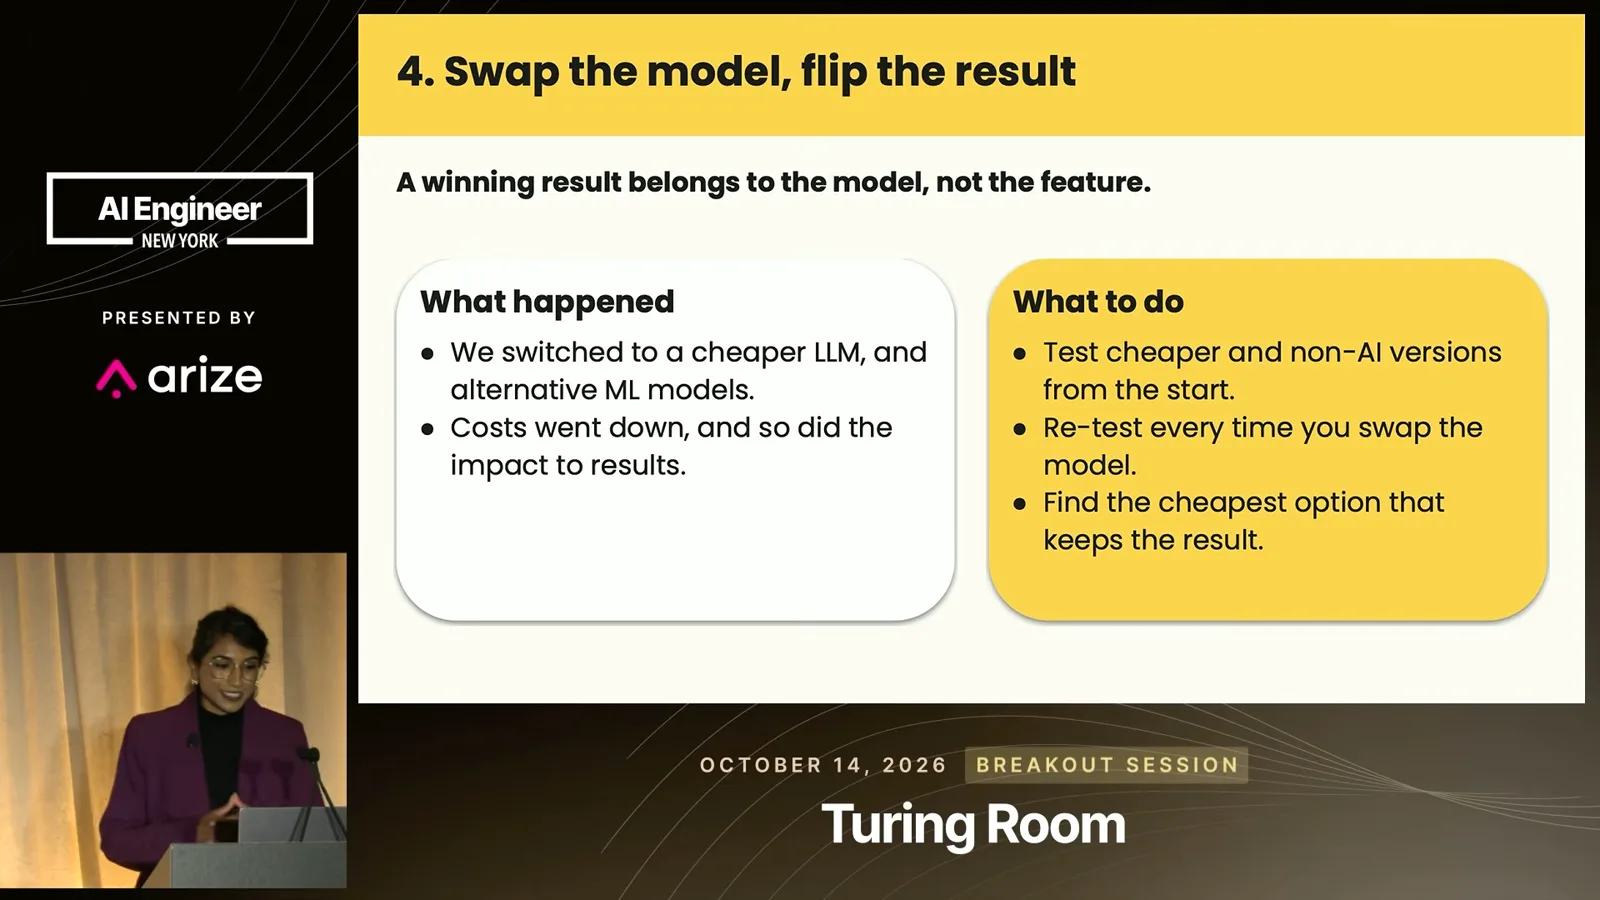
The fourth lesson is that the win may come from the model. Our initial model was too expensive to scale, so we switched to a cheaper one. Costs fell, but accuracy and the impact of the results fell as well. The A/B win depended on the model being tested, not simply on the concept of giving feedback.
We learned to test extensively and make decisions from data. Evals helped us compare models on different data sets, account for cost, and rapidly retest versions of prompts and feedback. In the end, we arrived at the cheapest option that still produced a good result.
Regulation shapes rollout
Legal constraints and market choices determine where a feature can ship.
The fifth lesson is that a global rollout may not be possible. AI regulation changes and differs between markets, and noncompliance brings legal and financial risk. We launched the feature in the United States but could not ship the same version unchanged to other countries.
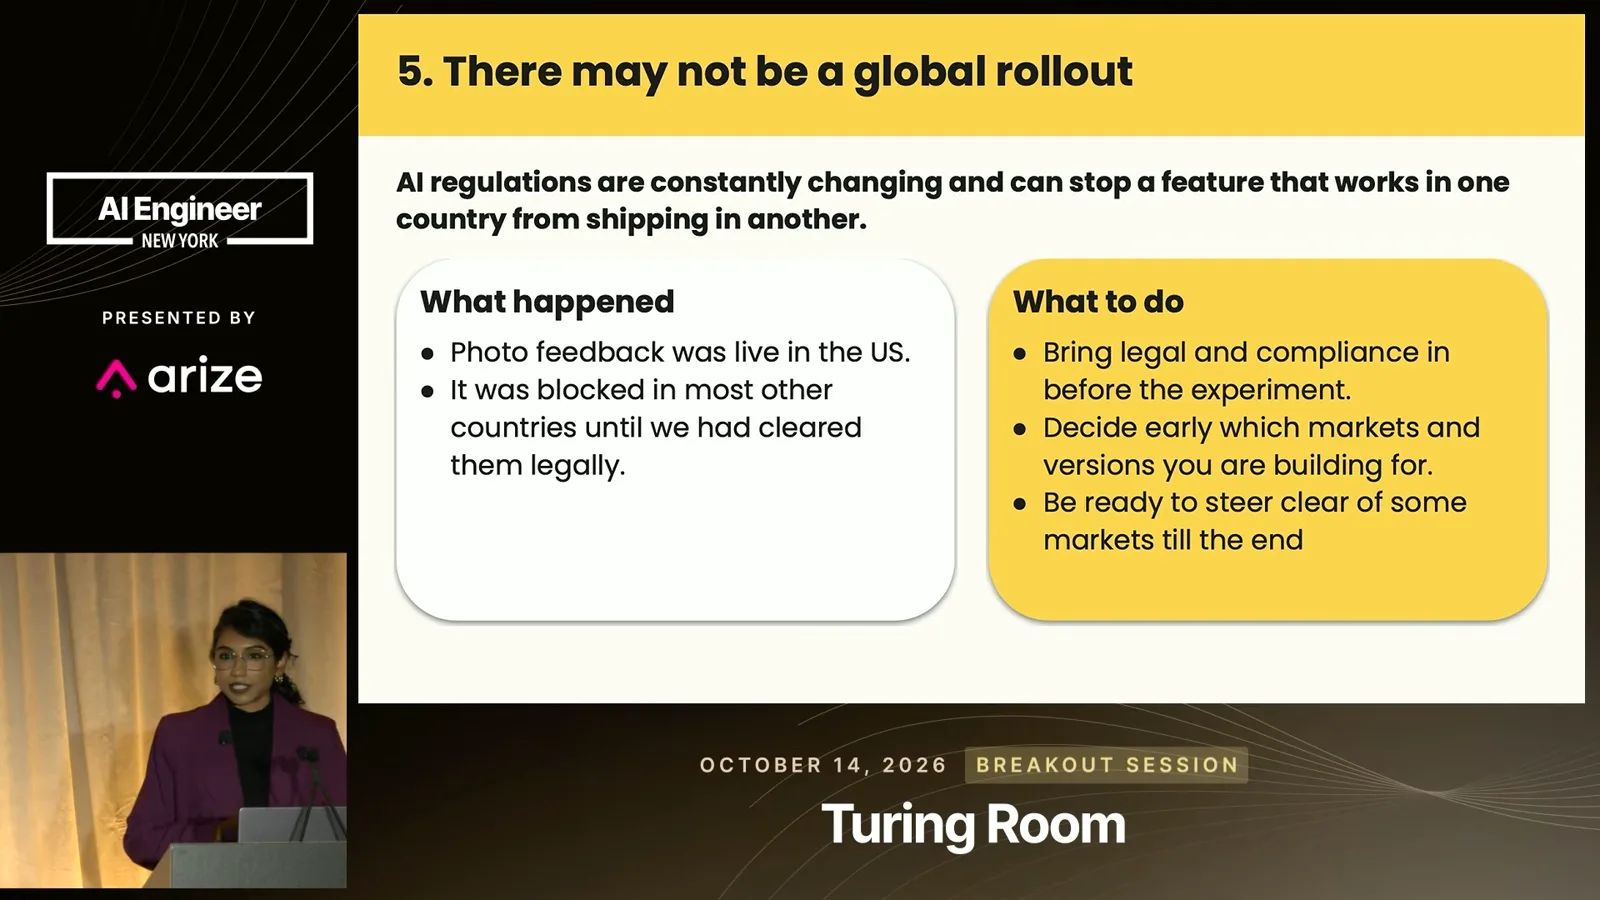
Product managers and engineers alike need to consider legal and compliance requirements early, not after the product is built. One approach is to identify restrictions everywhere and design within them from the start. Another is to optimize for the market with the greatest impact, even if that means launching in only one country.
A team can also pay the extra cost to make the application work differently in different countries. It is a spectrum of product decisions: building the best feature has limited value if users cannot legally get it.
Five questions before declaring victory
Subudhi summarizes the practical checks for a successful AI feature.
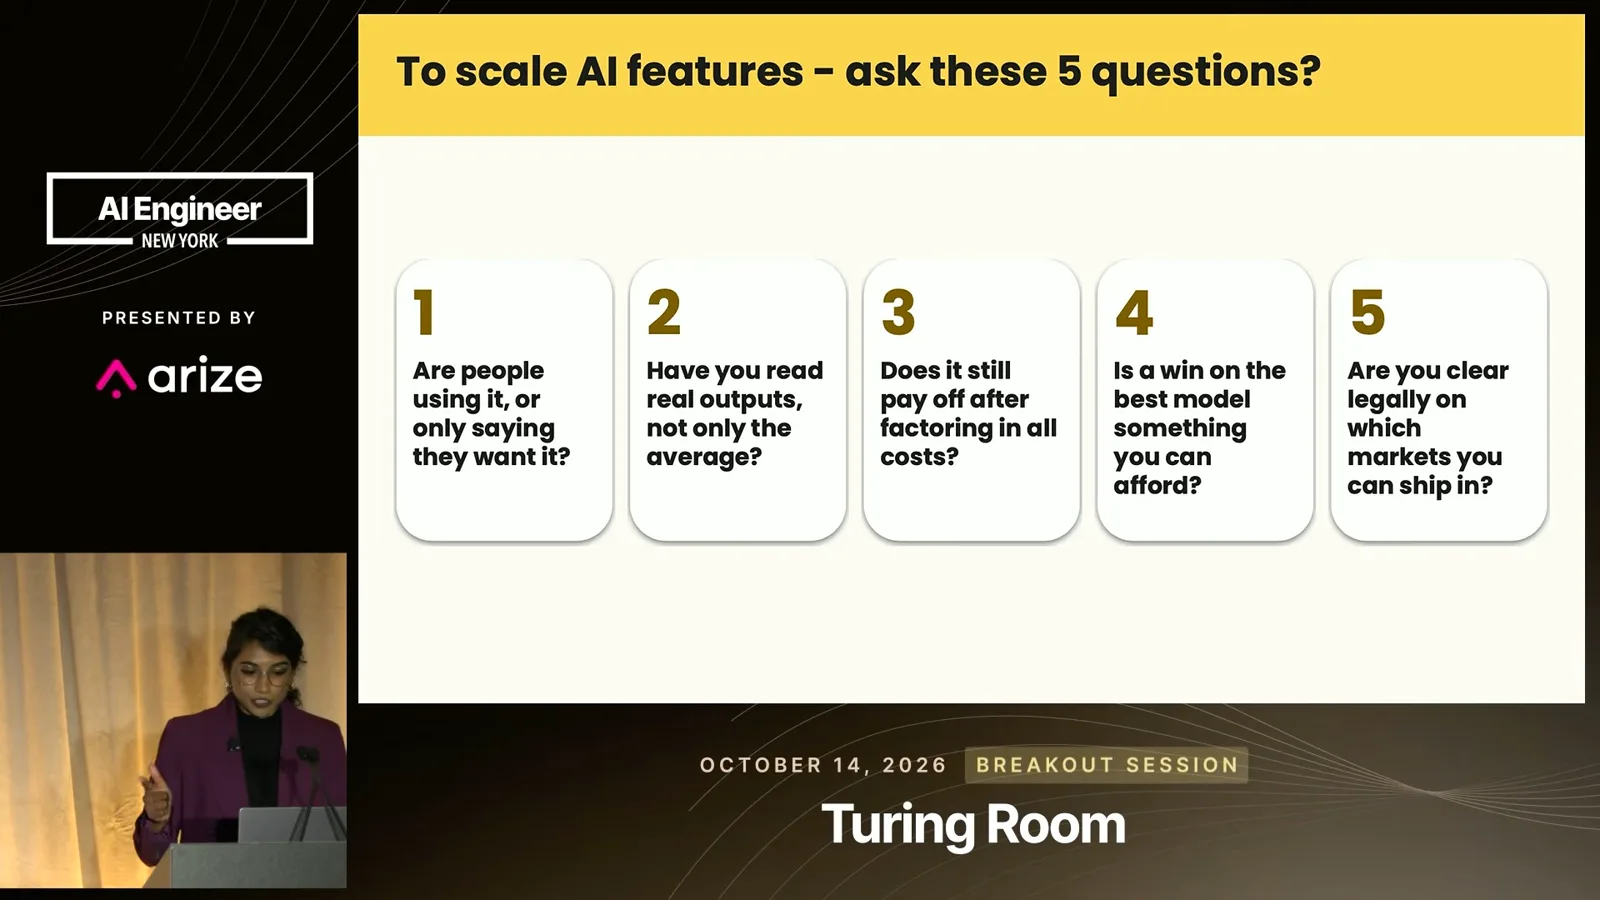
Before calling an AI test a win, ask five questions: Are people using the feature or merely saying they will? Do you read real outputs or just averages? Does the result justify all costs? Can you afford the model responsible for the win? And are you legally clear on the markets where you can ship?
同じチャンネルの記事
 18:29EN
 AI Engineer· 2026年10月31日Steven Latré on the Economics of Running Your Own AI ModelsSteven Latré · imecAn imec study compares APIs, rented GPUs and owned infrastructure for long-running coding agents.
 17:02ENAI Engineer· 2026年10月31日How Upstart Evaluates Voice Agents for Regulated Lending CallsBrooke Hopkins, Shiv Indap · CovalShiv Indap and Brooke Hopkins explain human review, LLM judges and simulation in a continuous evaluation loop.
 18:45ENAI Engineer· 2026年10月30日Jack Woodruff on AI and the Human Work of Stock PickingVinoo Ganesh, Jack Woodruff · KeplerThe former Candlestick Capital CIO discusses research, auditable data and how AI may reshape investment teams with Kepler CEO Vinoo Ganesh.
 15:27ENAI Engineer· 2026年10月30日Rayan Krishnan on Model Evaluation Beyond the Model CardRayan Krishnan · Vals AIThe Vals AI cofounder explains why task-level accuracy, total cost and company-specific evaluations can change which model is the best fit.
 19:06ENAI Engineer· 2026年10月30日Wojciech Pluta on Deciding What an AI Agent Should RememberWojciech Pluta · OracleOracle’s Wojciech Pluta explains memory promotion, a mortgage-agent demonstration, and the controls needed to carry useful information across sessions.
 16:43ENAI Engineer· 2026年10月30日Ishween Kaur on Securing Agent Payments with x402Ishween Kaur · SoFiA testnet walkthrough of price changes, replay, premature delivery, lookalike sellers and prompt injection in agent payment flows.