30 秒でわかる
Matthew Berman highlights the LLaVA team’s claims of improved reasoning, optical character recognition, and support for higher-resolution images. He lists model variants and shows an Ollama command for local use; the benchmark comparison is the authors’ historical claim, not a universal ranking.
- 1The authors’ reported improvementsHaotian Liu describes better reasoning, OCR, world knowledge, and support for higher-resolution input.
- 2A limited benchmark comparisonThe release announcement reports exceeding Gemini Pro on several benchmarks; this is an author-reported, task-specific comparison.
- 3Models and local useBerman lists several language-model backbones and says Ollama supports the release for local use.
ポイント
- LLaVA 1.6 is a multimodal model family that accepts images alongside language.
- Its developers reported improvements in reasoning, OCR, world knowledge, and image resolution compared with the earlier version.
- The release included variants based on Mistral 7B, Vicuna 7B and 13B, and Hermes-Yi 34B.
- The team’s comparison with Gemini Pro concerns selected benchmarks and does not establish superiority on every task.
- Berman shows `ollama run llava` as the local command in the 2024 demonstration.
チャプターごとに整えた全文を読む
LLaVA 1.6 and image understanding
Berman introduces the multimodal release and reads its authors’ claims about improvements and benchmark results. He lists available model backbones.
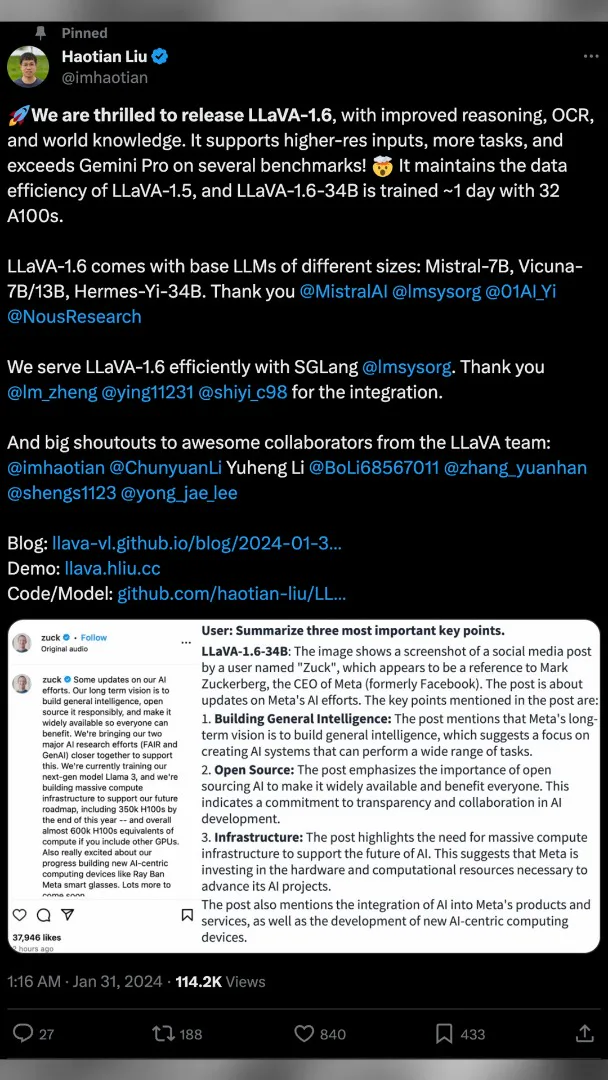
A new version of LLaVA is available for multimodal tasks, including interpreting images. In the January 2024 announcement, author Haotian Liu says LLaVA 1.6 improves reasoning, optical character recognition, and world knowledge, and supports higher-resolution image input and more tasks.
The authors also report that the model exceeds Gemini Pro on several benchmarks. That is a comparison on particular reported tests, not evidence that it is better on every task. The release lists base language models of different sizes: Mistral 7B, Vicuna 7B and 13B, and Hermes-Yi 34B.
Running through Ollama
He points to Ollama support and shows a command for local use. The instructions reflect the January 2024 video.
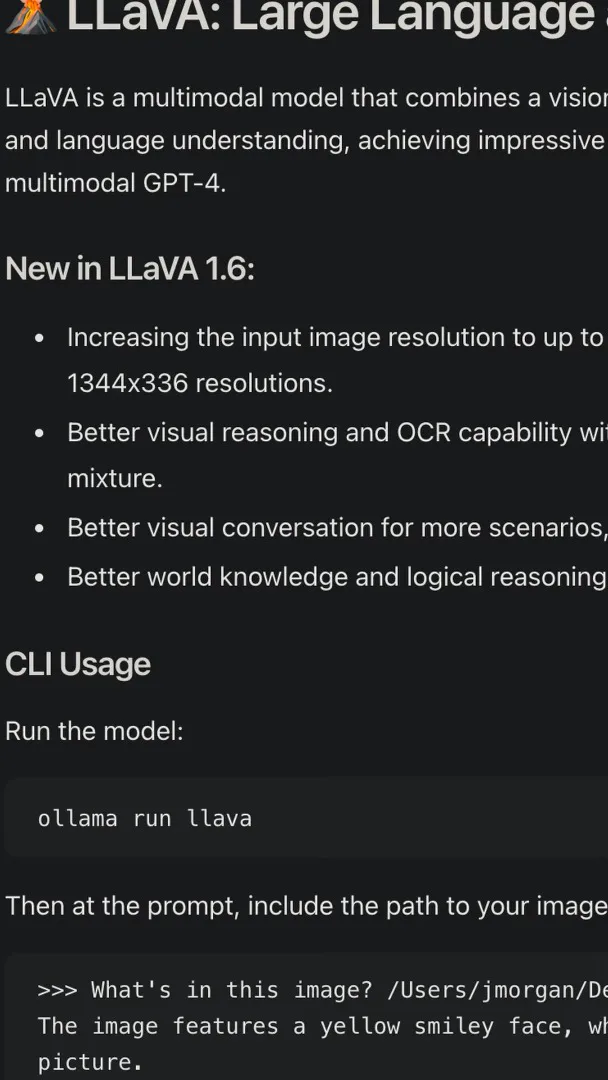
Ollama announced support for LLaVA 1.6, providing a way to run a model locally with suitable hardware. In this demonstration I point to the model library and show the command `ollama run llava`. These setup details describe the tools at the time of the video.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.