30 秒でわかる
In this August 2026 news roundup, Matthew Berman discusses a faster GPT-5.6 Sol preview, Anthropic’s planned text watermarking, Grok 4.6 and Grok Bot, and new GLM, DeepSeek and Meta models. An editor adds an update explaining Anthropic’s description of its watermark. The benchmark scores, prices and product availability are presented as reported at the time, and the speed comparison is a single demonstration. Berman and the editor distinguish their own concerns and impressions from vendor claims.
- 1Ultrafast previewA Cerebras-powered demo compares one dashboard-building run with a standard run.
- 2Claude watermarkAnthropic’s explanation describes keyed word choices; the presenters question the effect on outputs.
- 3Grok and agentsBerman discusses Grok 4.6 and Grok Bot’s integrations and delegation.
- 4Model releasesReported benchmarks and DeepSeek pricing accompany GLM-5.3 and DeepSeek-V4-Pro.
- 5Local modelMeta’s Muse Glimmer is presented as a 30-billion-parameter open-weight model.
- 6Computer HistoryBerman discusses an opt-in feature and its privacy implications.
ポイント
- A displayed ultrafast coding demo finishes in 1:50 compared with 12:20 for the comparison run, but does not establish a universal speedup.
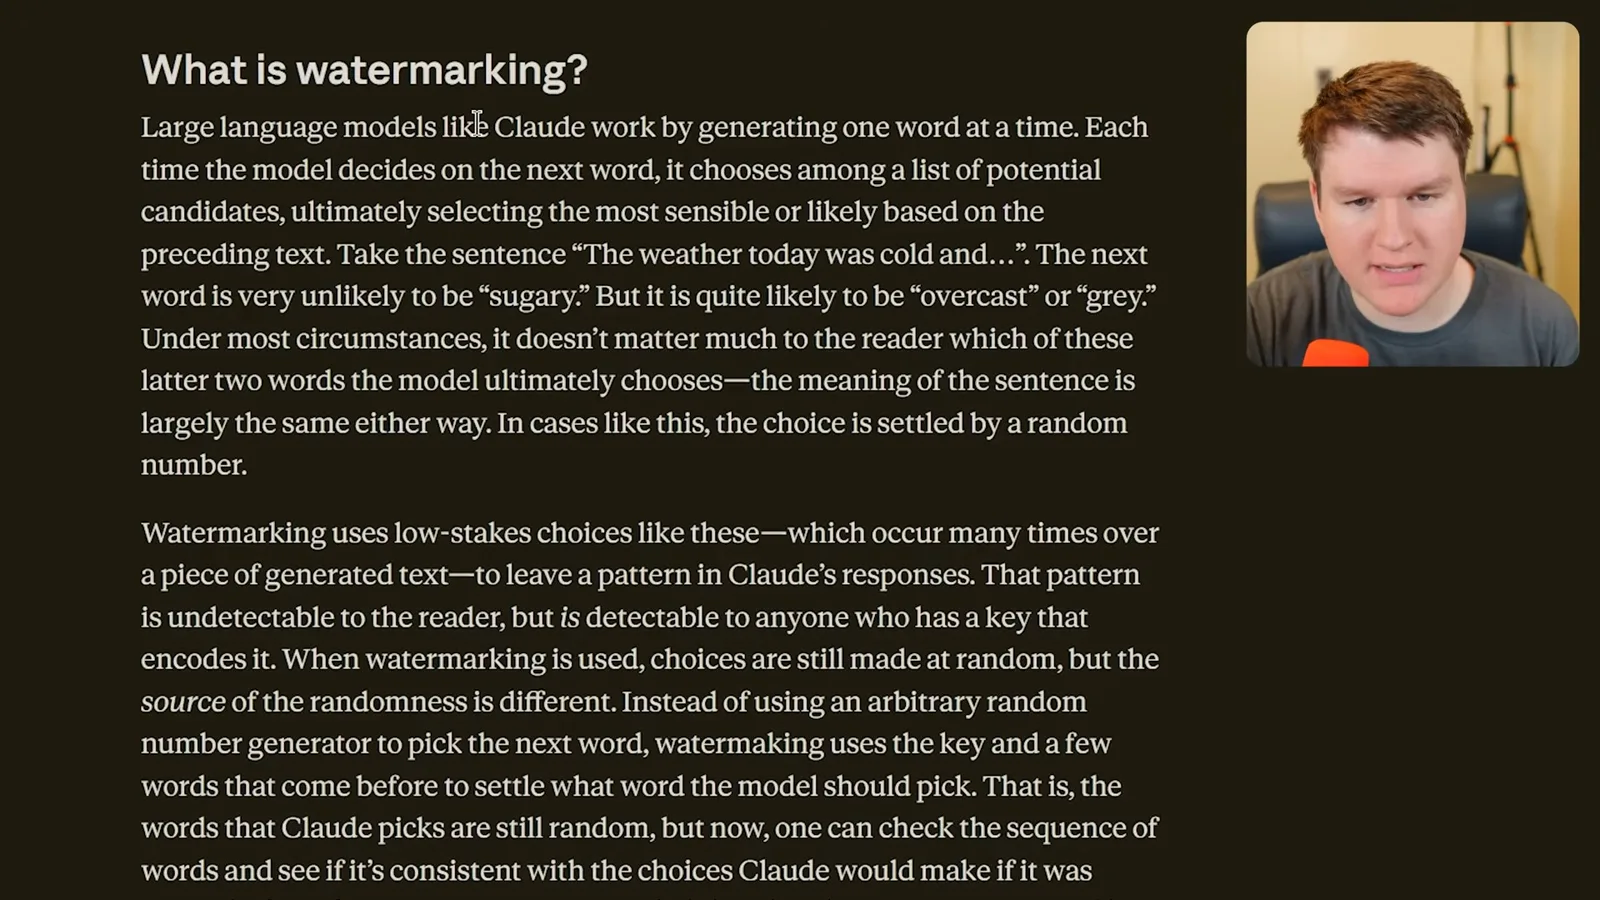
- Anthropic describes a keyed pattern in low-stakes word choices for watermarking future Claude outputs.
- Berman highlights Grok Bot’s simple agent interface, integrations and agent-to-agent conversations.
- GLM-5.3 and DeepSeek-V4-Pro are compared using reported benchmarks and pricing.
- Meta describes Muse Glimmer as a 30-billion-parameter open-weight model for local agent workflows.
- Berman says Computer History is opt-in and discusses the privacy tradeoffs of sharing activity.
チャプターごとに整えた全文を読む
Ultrafast inference
Berman discusses the preview and a side-by-side coding demonstration. He considers how faster responses could change agent workflows.
This week brought an unusually large amount of AI news: an ultrafast ChatGPT mode, Claude text watermarking and several new models. I will go through the announcements and what they might mean for users.
OpenAI is previewing an ultrafast GPT-5.6 Sol mode using Cerebras hardware. In a displayed dashboard-building demonstration, the ultrafast run finishes in 1 minute 50 seconds while the comparison run takes 12 minutes 20 seconds. This is one example, not a controlled measure of every task; the faster mode costs extra.
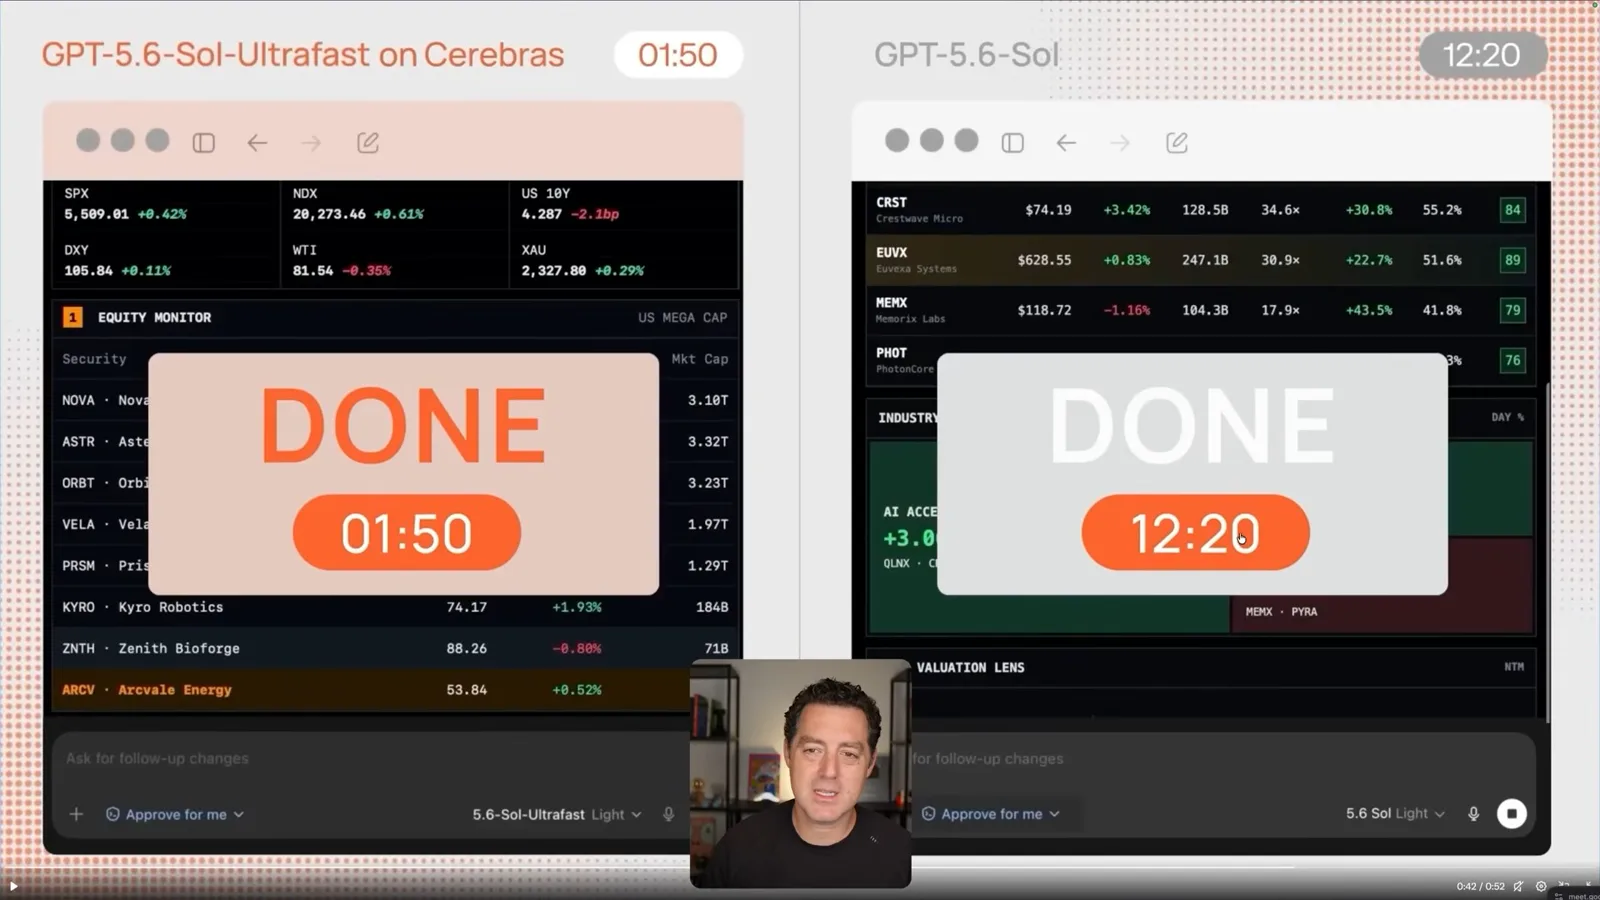
I usually launch many agents at once because each can take a long time, but keeping track of them adds context-switching costs. After briefly trying the preview, I think faster inference could let me work with fewer concurrent agents. Tool calls and local computing may then become a larger share of the wait.
Claude text watermarking
Berman questions the announcement, and an editor adds Anthropic’s later explanation. They discuss word selection, code and possible effects on output.
Anthropic announced watermarking for future Claude outputs. I initially wonder how it works, whether it changes the text and what the implications are for tracking. I also question the EU transparency requirements cited in connection with the announcement.
An editor adds an update after Anthropic published more detail. The company says watermarking uses a keyed pattern in low-stakes word choices, rather than visible markers: the model still selects among possible words, but uses a key and preceding words to influence the random choice. The editor describes the stated goal of making the pattern detectable with the key.
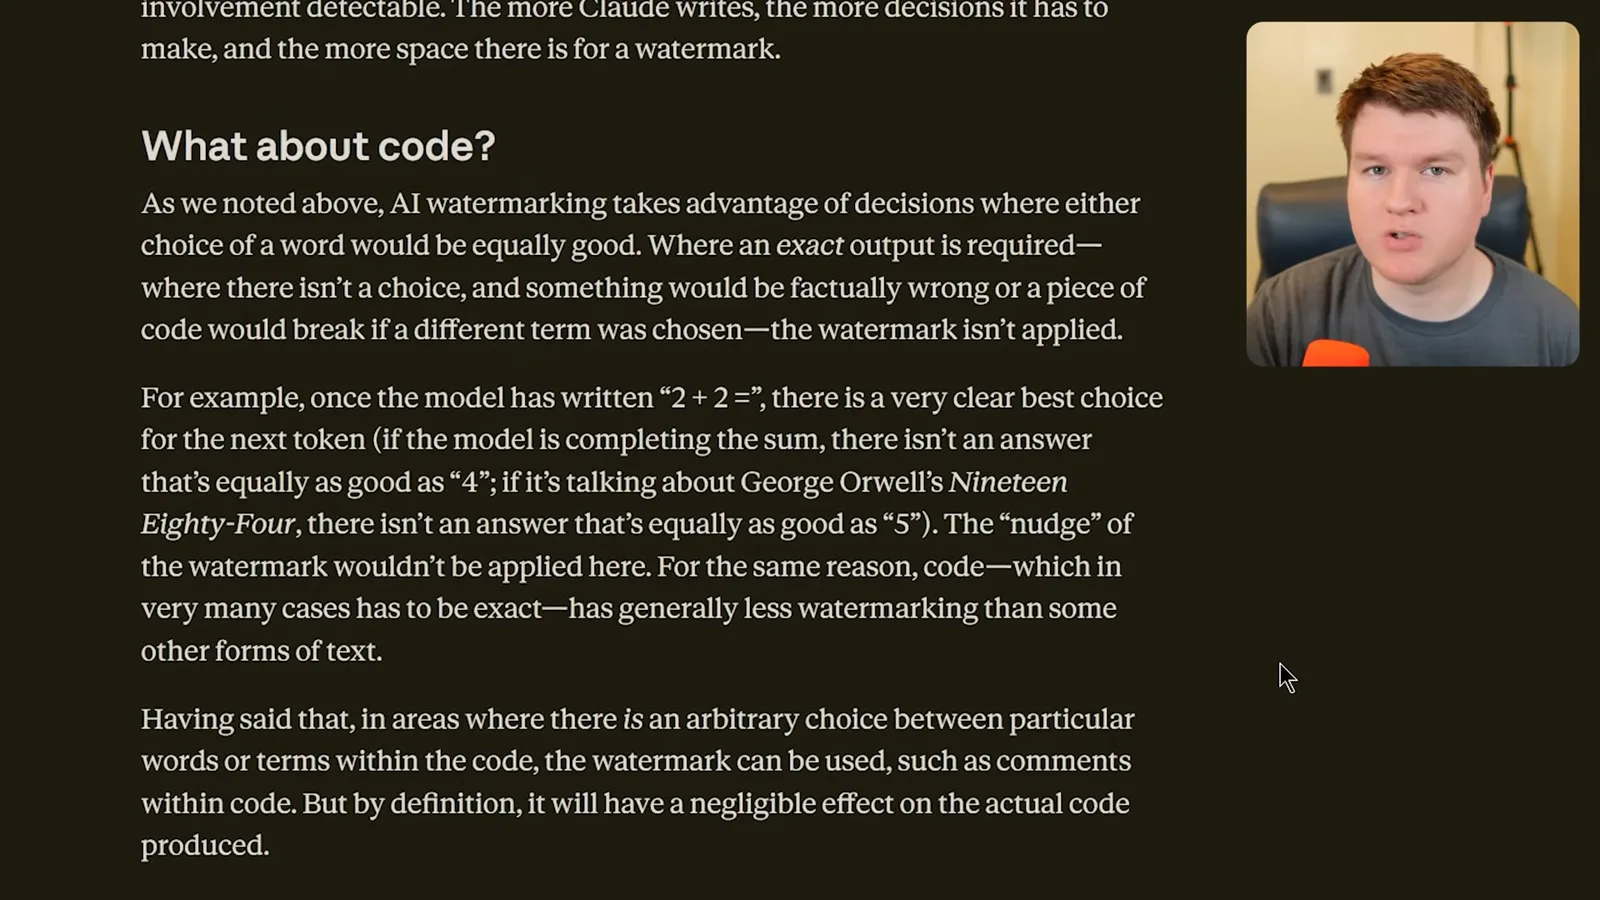
The editor explains that lightly edited human writing offers fewer model-selected words in which to encode a watermark. Anthropic says code may contain watermarks in flexible language such as comments while claiming negligible effects on the actual code. The editor questions how much changing the selection process could affect output, and says the long-term effects remain to be seen.
Grok 4.6 and Grok Bot
Berman reviews the model and a simplified agent product. He describes integrations, delegation and agent conversations.
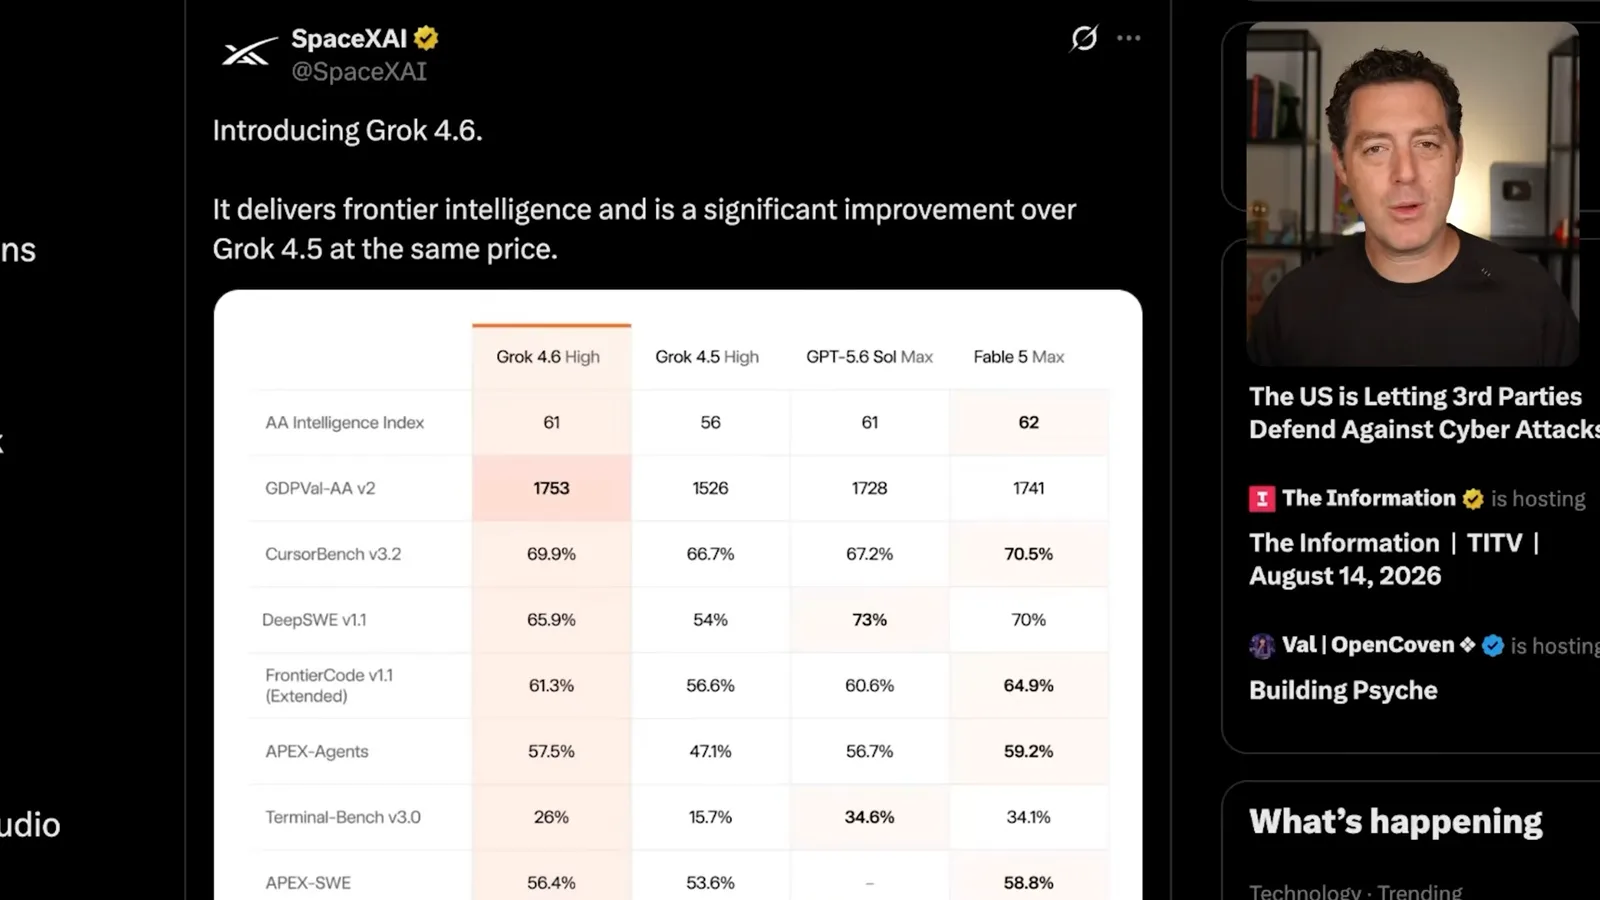
I turn to Cursor’s move into SpaceX and the Grok 4.6 release. I view the model as much improved and close to leading systems on the comparisons shown. The video reports a price of $2 per million input tokens and $6 per million output tokens at the time.
Grok Bot offers a simplified agent interface: users need not inspect code or select a model and reasoning effort for each task. After about a week of use, I plan to move some workflows to it. I compare it to a more accessible version of OpenClaw.
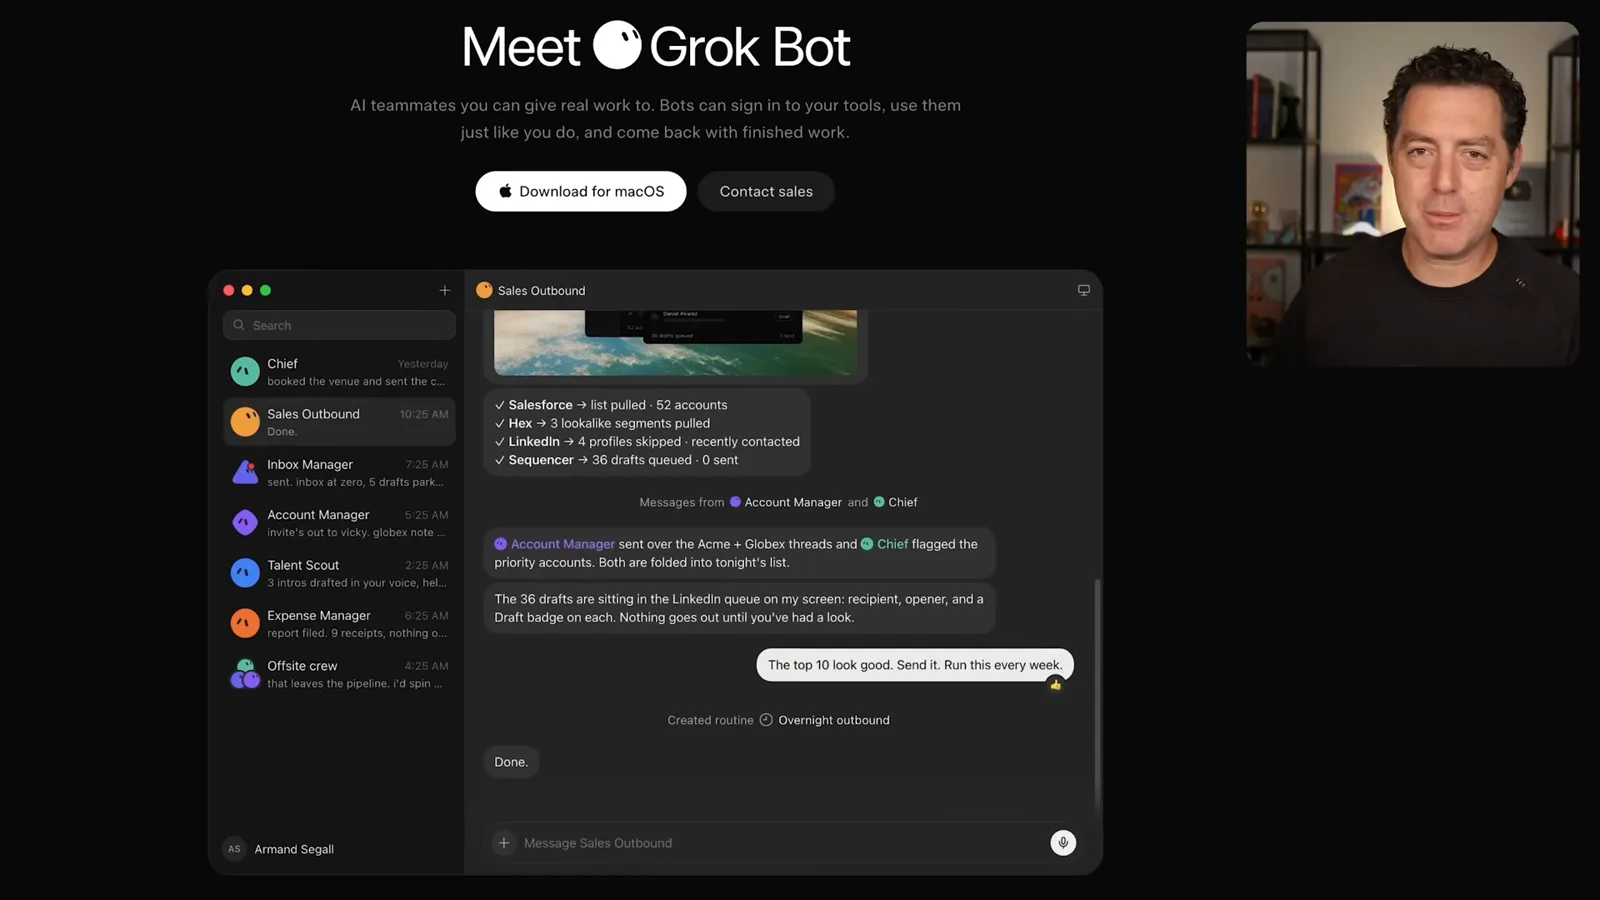
I highlight individual threads as agents, integrations such as Slack, Google Docs and email, and the ability for agents to delegate and communicate. Their conversations are retained, so multiple agents can work toward a shared goal.
New open models
He compares reported results for GLM-5.3 and DeepSeek-V4-Pro and shows DeepSeek pricing. He then introduces Meta’s smaller open-weight Muse Glimmer.
GLM-5.3 is the first of several open-model releases I discuss. The displayed comparison shows a substantial improvement over GLM-5.2 on Terminal Bench 3.0 and a 66.9 score on DeepSWE. I consider it competitive but below some leading models in the tests shown; these are reported benchmarks rather than a universal ranking.
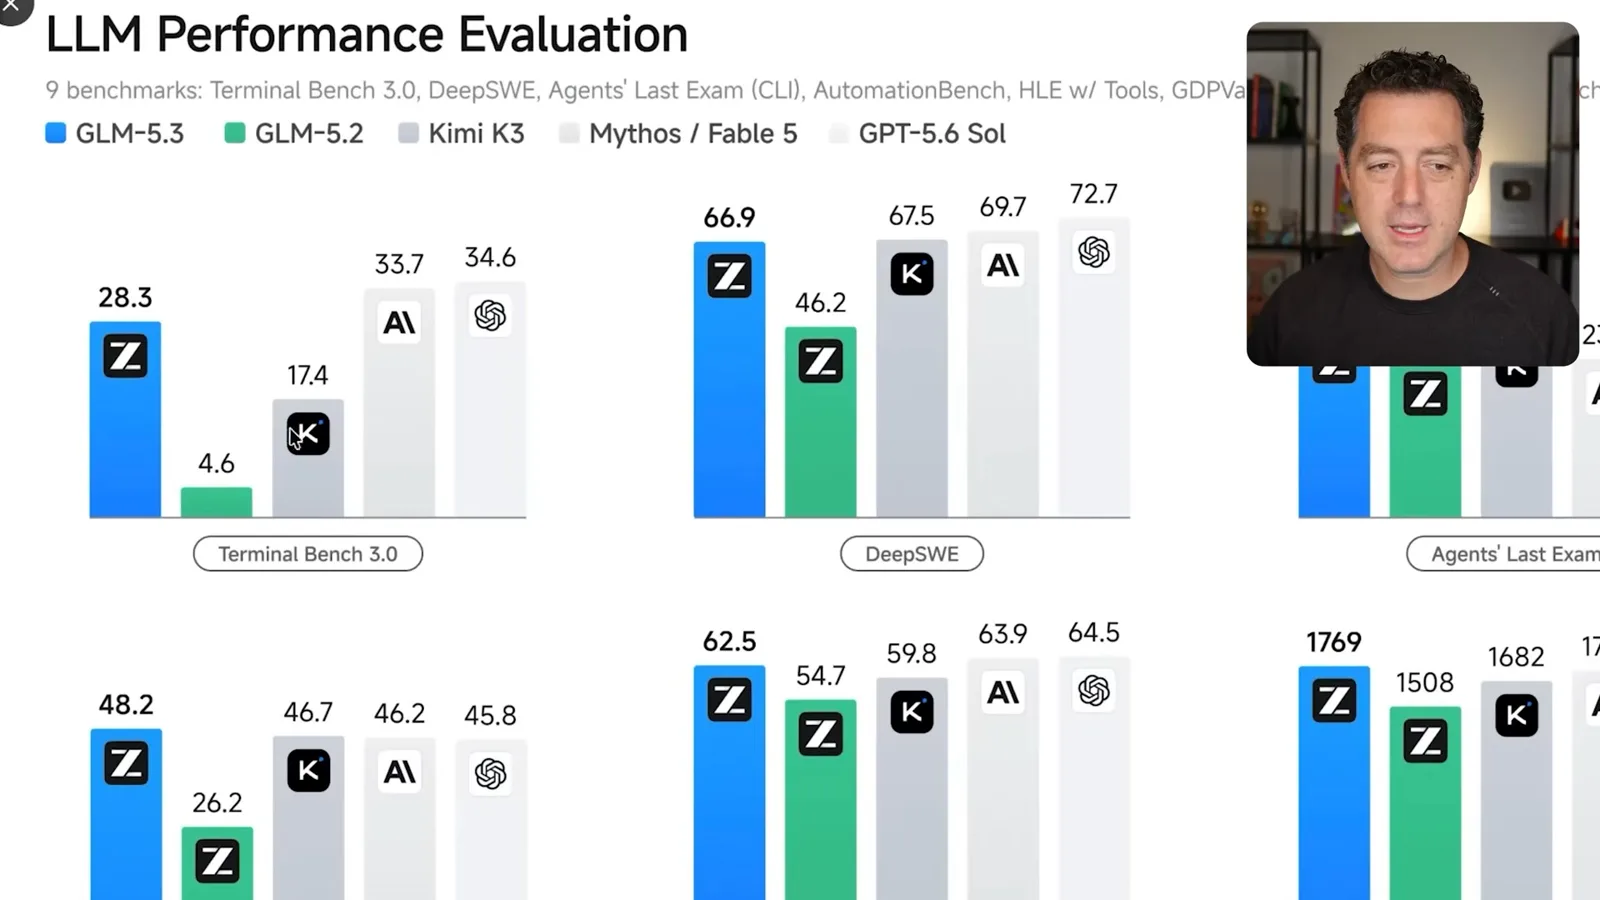
DeepSeek-V4-Pro is another release. I cite a Terminal Bench result of 87.9 in the displayed comparison, close to Kimi K3 and Fable 5 at 88 in that table. Different benchmark versions and test conditions matter when comparing results.
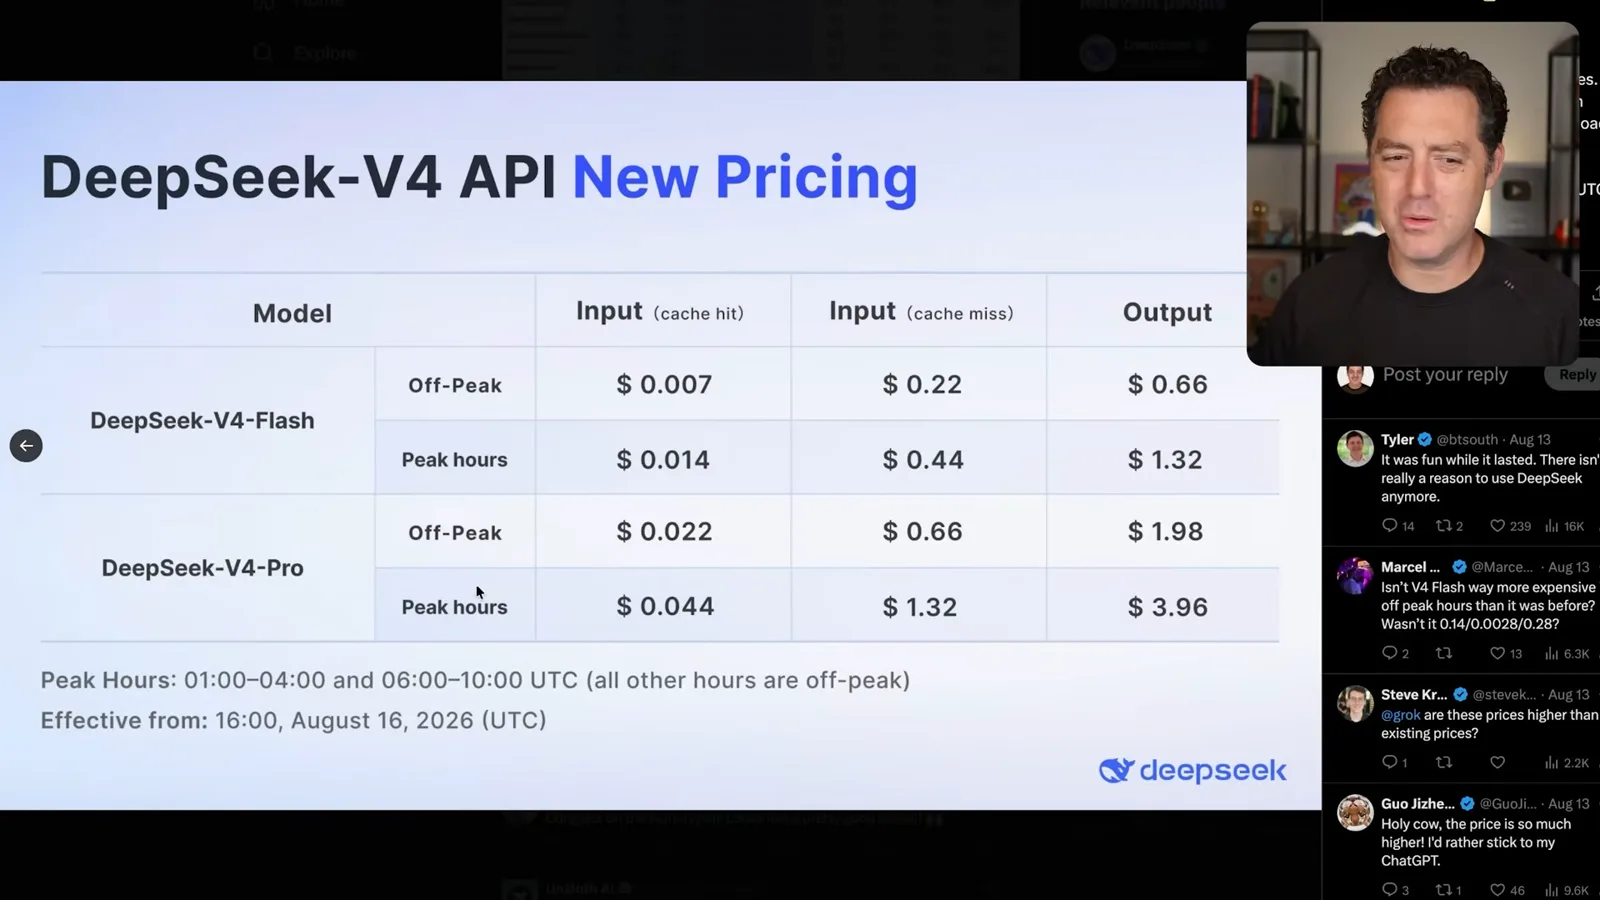
The displayed DeepSeek API pricing separates peak and off-peak hours and cache hits from misses. For V4 Pro, the listed off-peak prices are $0.66 per million input tokens on a cache miss, $1.98 per million output tokens and $0.022 per million cached input tokens. The screen says those prices take effect August 16, 2026.
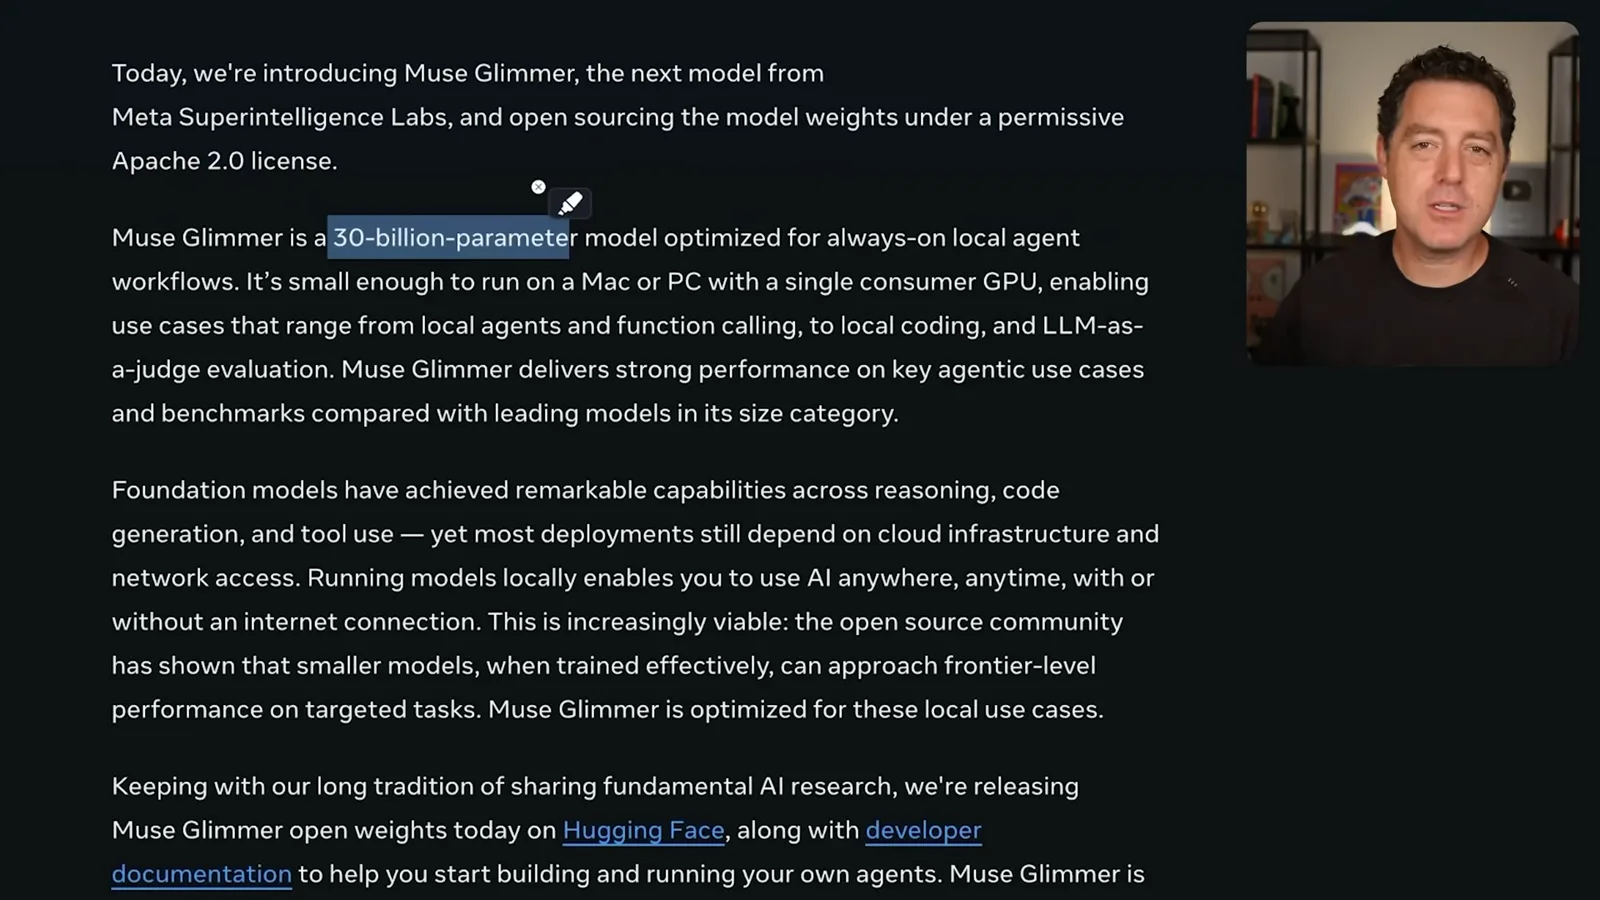
Meta’s Muse Glimmer is a 30-billion-parameter open-weight model intended for local agent workflows. Its displayed announcement lists an Apache 2.0 license. I note that it is not intended to compete with the largest frontier models and suggest some desktop GPUs might run it, subject to memory and configuration.
Computer History and privacy
Berman describes the opt-in activity feature and compares it with Microsoft Recall. He closes with his favorite release.
OpenAI’s Computer History feature can use selected computer activity to make future interactions more contextual and suggest automation. I say the feature is opt-in and allows controls over what to share. People may reasonably be cautious about recording computer activity.
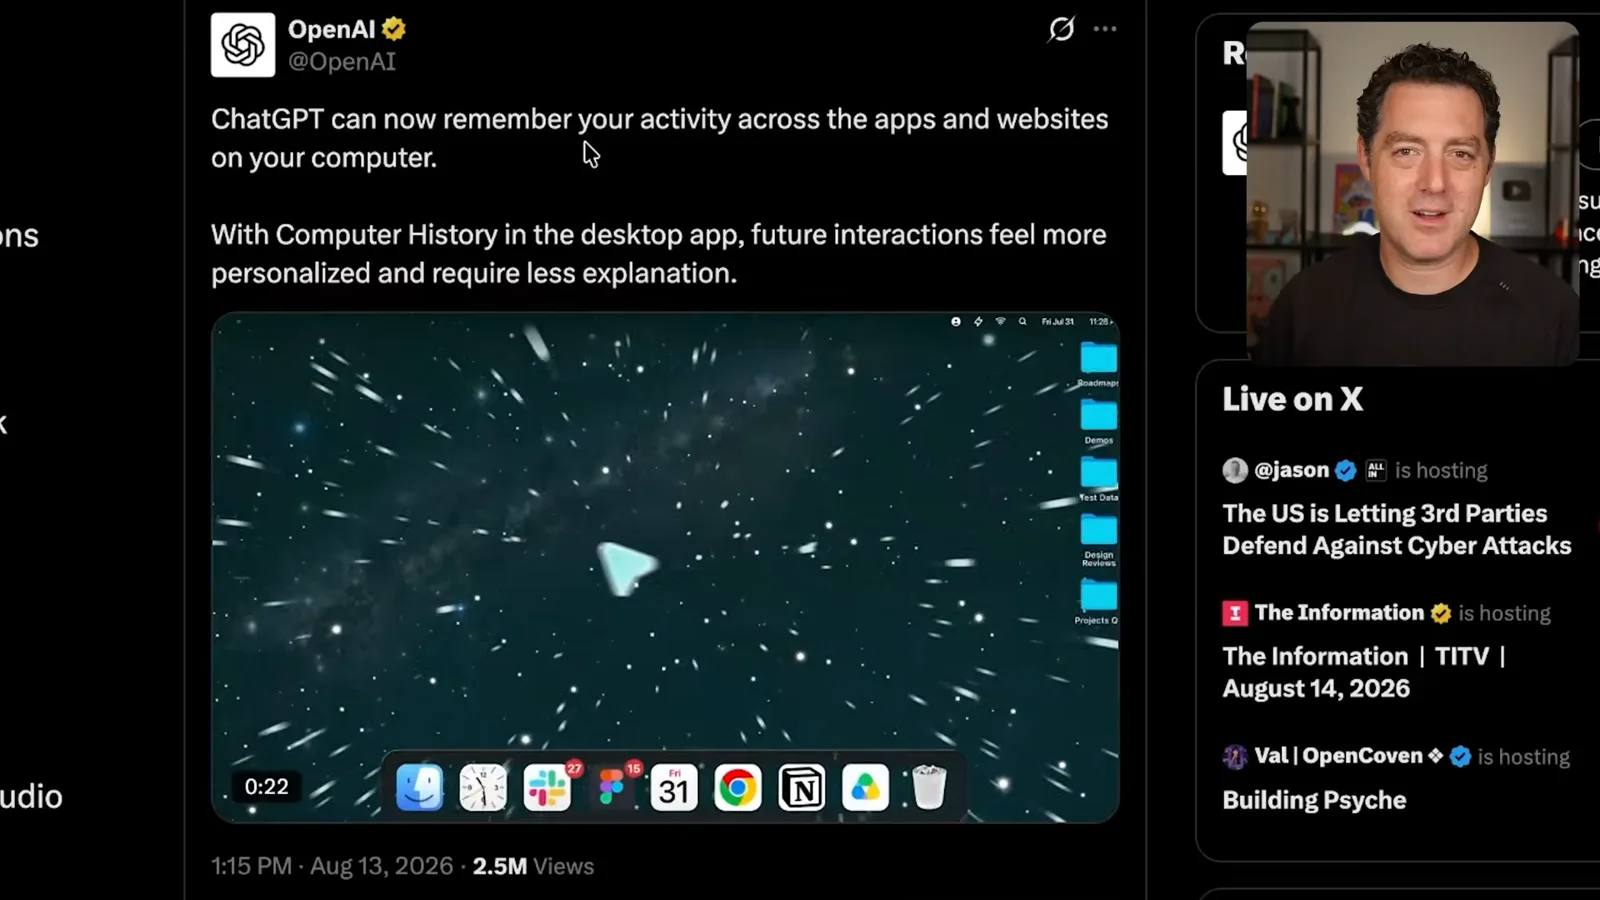
The idea reminds me of Microsoft Recall, which drew strong privacy and security objections. I was interested in that feature and say I may try sharing a few apps with Computer History. My favorite release of the week is Grok Bot.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.