30 秒でわかる
Matthew Berman introduces Petals, a project for distributed inference and fine-tuning of large language models. He explains the distinction between using the network as a client and contributing hardware as a server, cites a historical LLaMA 65B speed figure, and shows a Python inference example. His torrent analogy, proposed blockchain rewards, and thoughts about mixture-of-experts models are explanations or speculation, not evidence that Petals uses BitTorrent or offers such rewards. Performance, supported models, availability, and privacy depend on the setup and period described.
- 1A distributed optionPetals is introduced as a way to distribute model work across networked computers.
- 2Model blocks on serversBerman describes participants hosting separate portions of a model and likens resource sharing to torrents.
- 3Historical speed figureHe cites roughly five to six tokens per second for LLaMA 65B; actual throughput depends on the network and configuration.
- 4Client and server rolesA client uses distributed inference or fine-tuning, while a server supplies hardware.
- 5Incentive proposalBerman suggests blockchain-based rewards for contributors as a possible future idea, not an existing feature.
- 6Python inference exampleThe displayed code loads a supported model using the Petals library and generates text.
ポイント
- Petals distributes model blocks across participating servers, allowing a client to use the network without storing the entire model locally.
- The torrent comparison is a loose analogy for shared resources, not a claim that the project uses BitTorrent.
- A client can request inference or fine-tuning, while a server contributes hardware; the video also mentions private swarms.
- Berman cites five to six tokens per second for LLaMA 65B as a 2023 reported figure, not a guaranteed rate for every network or device.
- Distributed operation depends on participating hosts and network conditions; the video does not establish confidentiality guarantees.
- Blockchain rewards and possible mixture-of-experts applications are Berman’s proposals, not features demonstrated in the video.
チャプターごとに整えた全文を読む
Why distribute large models?
Berman contrasts proprietary services and local hardware requirements as he introduces Petals. His assessment of its importance is a personal view.
I introduce Petals as a potentially important development for accessing large language models. My enthusiasm about its significance is a forecast. The goal I describe is to use a model through a distributed network without needing one client device to hold the complete model.
I contrast centralized services such as ChatGPT with models such as LLaMA, BLOOM, and MPT that users could obtain and run. My concern is the cost of hardware for large models: I estimate that a 33-billion-parameter model needed an expensive GPU to achieve reasonable inference speeds. That cost and availability context is from 2023, and licenses differ among models.
Model blocks and the Petals network
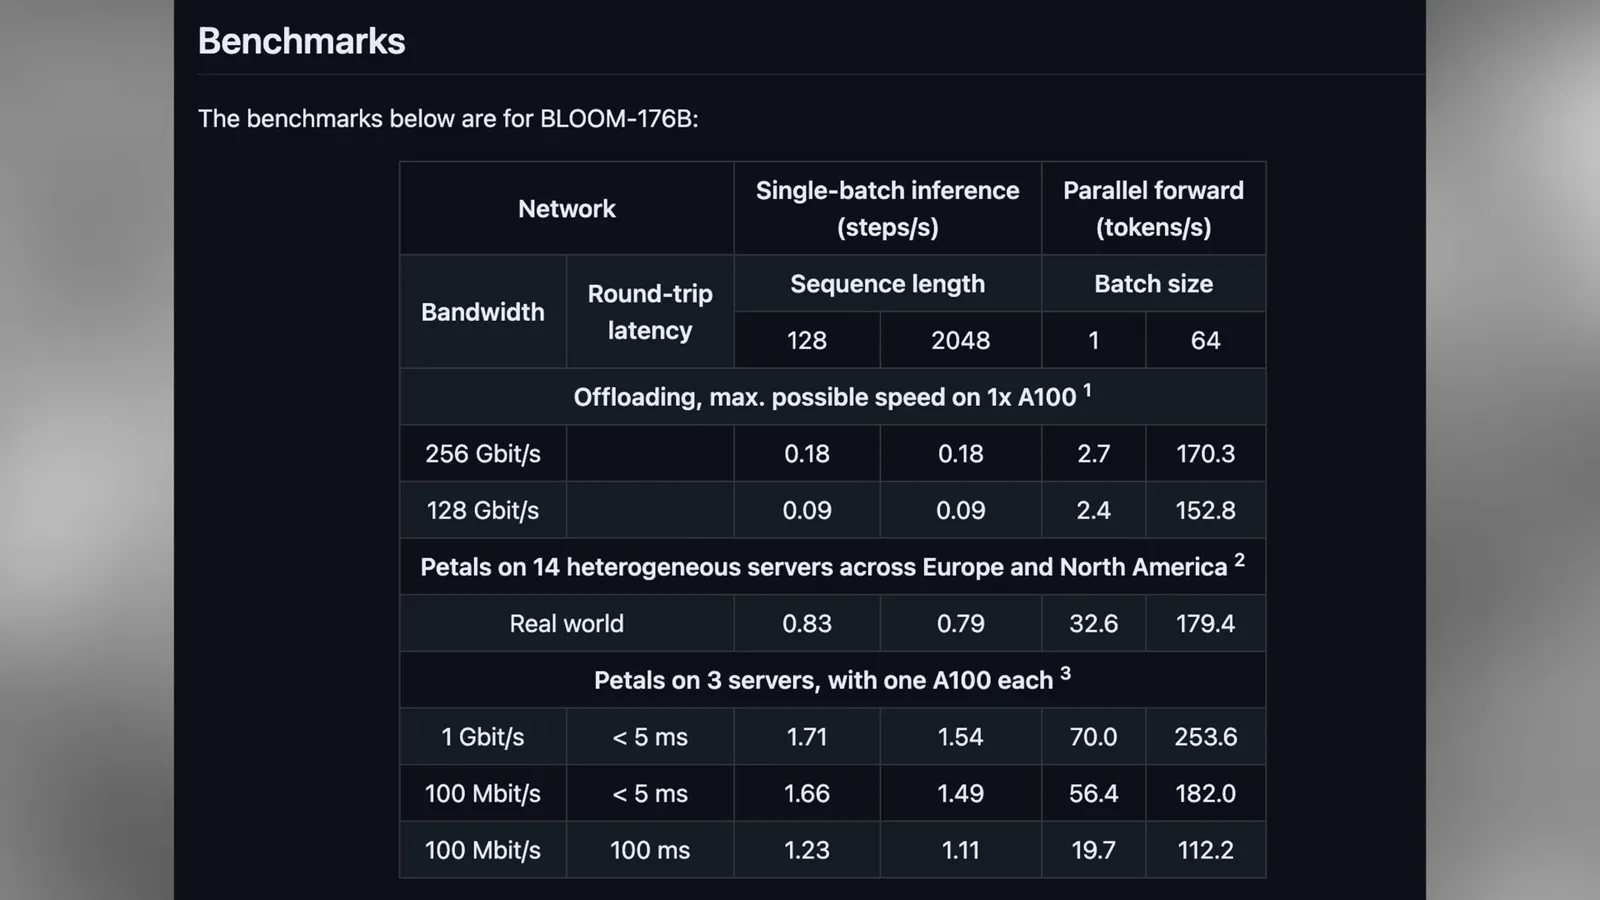
He uses a torrent analogy to explain how participating machines host pieces of a model. He cites a historical speed figure and shows a separate benchmark table.
Petals offers another approach: distribute inference and fine-tuning across a network. I compare the shared-resource idea to torrents, but this is an analogy rather than evidence that Petals is BitTorrent. A client’s ability to use the system depends on compatible software, networking, and participating servers, not literally every device without conditions.
I describe the model as split into blocks hosted by different participants. Each contributing server supplies a portion rather than needing to run the whole model. The client coordinates work across the network, and a user can also access it from an environment such as a Google Colab session rather than using only a local GPU.
I cite a speed of approximately five to six tokens per second for LLaMA 65B. The figure is a historical reported observation, not a guarantee: network latency, available hosts, model, and configuration can change performance. The table shown separately in the video reports benchmarks for BLOOM-176B under several server and network setups.
Clients, servers, and future ideas
Berman describes client and server roles, private swarms, and potential mixture-of-experts uses. His proposed token incentives are speculative.
A participant can be a client, a server, or both. I describe clients using the network for inference or fine-tuning and servers contributing hardware to run model blocks. A client can use the Petals Python library without personally managing every server, while a group can also create a private swarm.
I speculate that distributing model components might be useful for mixture-of-experts architectures. I also mention a then-circulating description of GPT-4’s internals; the video does not verify those details or demonstrate that Petals supports a particular mixture-of-experts system.
A practical challenge is that the public network depends on people contributing available compute. I imagine idle GPU time as a potential resource, but the video does not measure how many contributors are needed or guarantee that a volunteer network will always have sufficient capacity.
One possible incentive I suggest is rewarding server operators with tokens, perhaps providing priority or higher usage and potentially tradable value. This blockchain idea is my proposal, not a reward mechanism demonstrated or promised by Petals.
A Python example and next steps
The video shows a short inference example and discusses support for BLOOM and LLaMA at the time. Berman says he plans to test the network as both client and server.
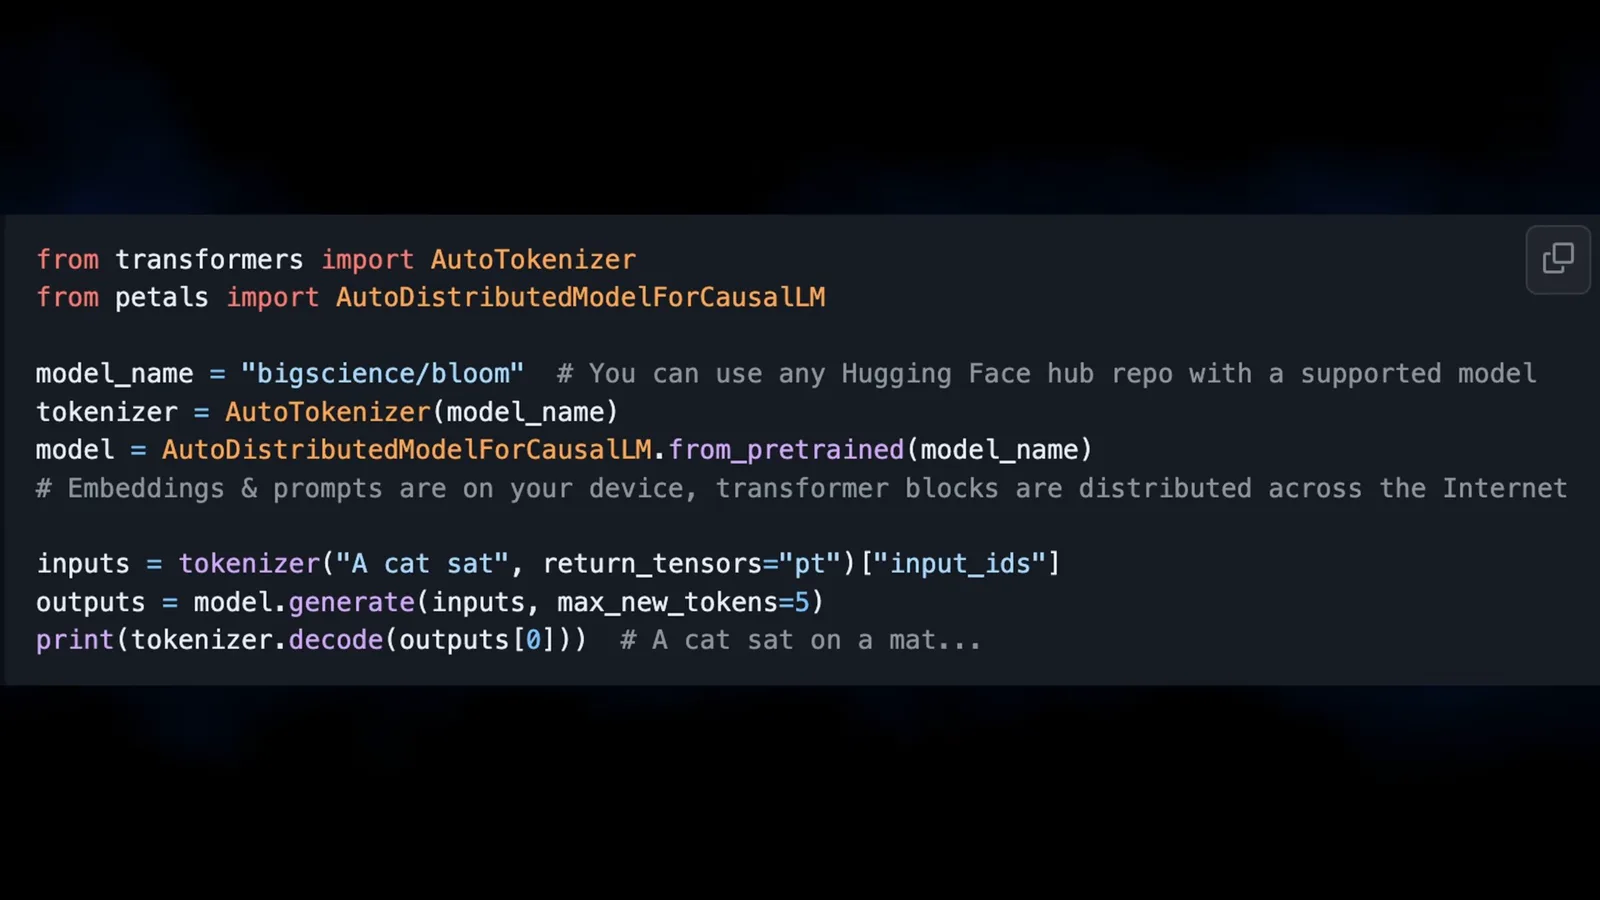
At the time of the video I describe BLOOM and LLaMA support and show a short Python example. It imports a tokenizer and Petals distributed model class, loads a supported model, and generates text. The example illustrates inference; current model support and installation details may differ.
I plan to try Petals as both a client and a server and invite interest in a longer tutorial. I am excited by the possibility of sharing idle GPU resources, while the video itself does not demonstrate my completed tests or establish the privacy properties of all participating hosts.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026年10月21日A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.