30 秒でわかる
Theo Browne explains how he uses Fable 5 to coordinate other models, configure skills and triage a backlog of pull requests. He describes his personal reasoning-effort and cost choices, explicit authorization for merges into staging, and subsequent human and agent verification.
- 1Cost is contextualTheo estimates the value of a long run and delegated work, while using subscriptions with limits and terms specific to that period.
- 2Subagents and workflowsHe distinguishes bounded delegated tasks from scripts that coordinate multiple stages.
- 3PR triageHe asks for 16 pull requests to be classified and reviewed before deciding what to keep or rewrite.
- 4Explicit boundariesHe authorizes merges in his own project and keeps production deployment under human control.
- 5VerificationAfter the work lands in staging, he reports personally testing it and asking other agents for additional checks.
ポイント
- Reasoning effort and model routing should be selected for the task and measured against actual usage.
- Instruction files and skills can evolve from observed failures and project-specific preferences.
- Independent review results need verification against the work itself.
- A large PR backlog can be triaged into bounded work with explicit checkpoints.
- Theo authorized merges in his own project while retaining human control over production deployment.
- Fast or slow agent work is a clue about complexity, not proof of correctness.
チャプターごとに整えた全文を読む
A different way to use the model
Theo describes his enthusiasm and the backlog he moved forward. He frames the video as a walkthrough of his own workflow.
Fable 5 impressed me more after a few days of work than it did on the first day. When access returned, I used it to move a backlog of unfinished work forward. This is my experience, not a controlled productivity measurement, but it changed how I think about what to ask an agent to do.
I do not see it simply as a smarter Opus. The difference for me is how far it can go through an implementation, testing and verification, especially when it divides work among subagents. Using exactly the same prompts as before may not reveal that strength.
I want to show the prompts, instruction files and skills I used, and how my approach changed. This is a walkthrough of one evolving workflow, not a configuration everyone should copy or a guarantee that autonomous work is correct.
Lakebed had accumulated many partly finished pull requests. I did not trust some implementations or like the SDK changes, and the effort needed to clean them up kept the project stalled. With Fable I worked through a large number in a few days, including a series of merges from one thread.
Reasoning effort and model routing
He discusses estimated costs, reasoning settings and delegating work to other models. The prices and limits are specific to his setup and time.
Before showing the larger workflow, I want to discuss cost. I estimate that a five-and-a-half-hour run and its delegated models would have been around $150 in usage, compared with the thousands I expected. I used subscriptions, not a $150 API invoice, and the economics depend on the plans and conditions at the time.
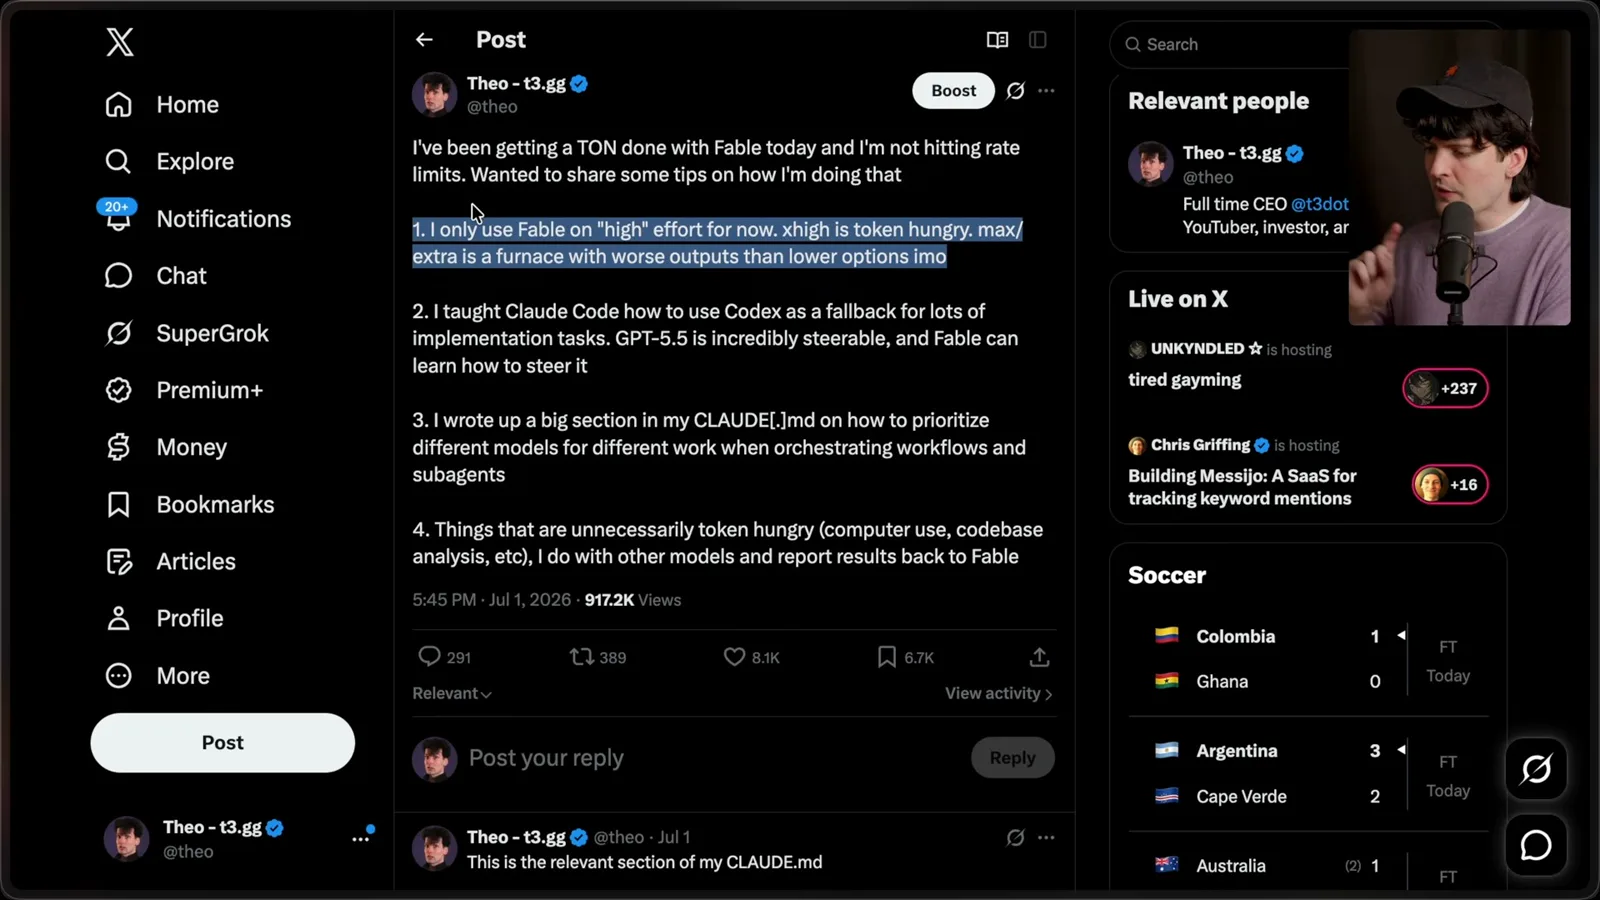
My first recommendation is to try high reasoning effort rather than automatically selecting xhigh, max or Ultra Code. In my experience, higher settings consumed far more and sometimes produced overworked changes. This is a personal default for this model and workload, not a universal rule about every task.
I distinguish reasoning effort per step from the total duration of an agent task: a lower setting can still participate in a long sequence of tool calls. More thinking at every step does not necessarily mean more useful work, and I found it could lead to overthinking.
I also taught Claude Code to call Codex for work that fits it, including computer use and token-heavy investigation. Examples include reading large logs or documents and examining many screenshots. The goal is to let a coordinating model use another tool where it is useful, then bring the result back.
For my own subscriptions at the time, this routing reduced the cost pressure I experienced. My usage limits and promotions are not a guarantee of anyone else’s allowance, and subscription policies can change. Measure your own usage rather than assuming delegated work is free.
Instructions and skills
Theo explains his model-selection glossary and separate skills for review, implementation and computer use. He emphasizes adapting instructions after observing failures.
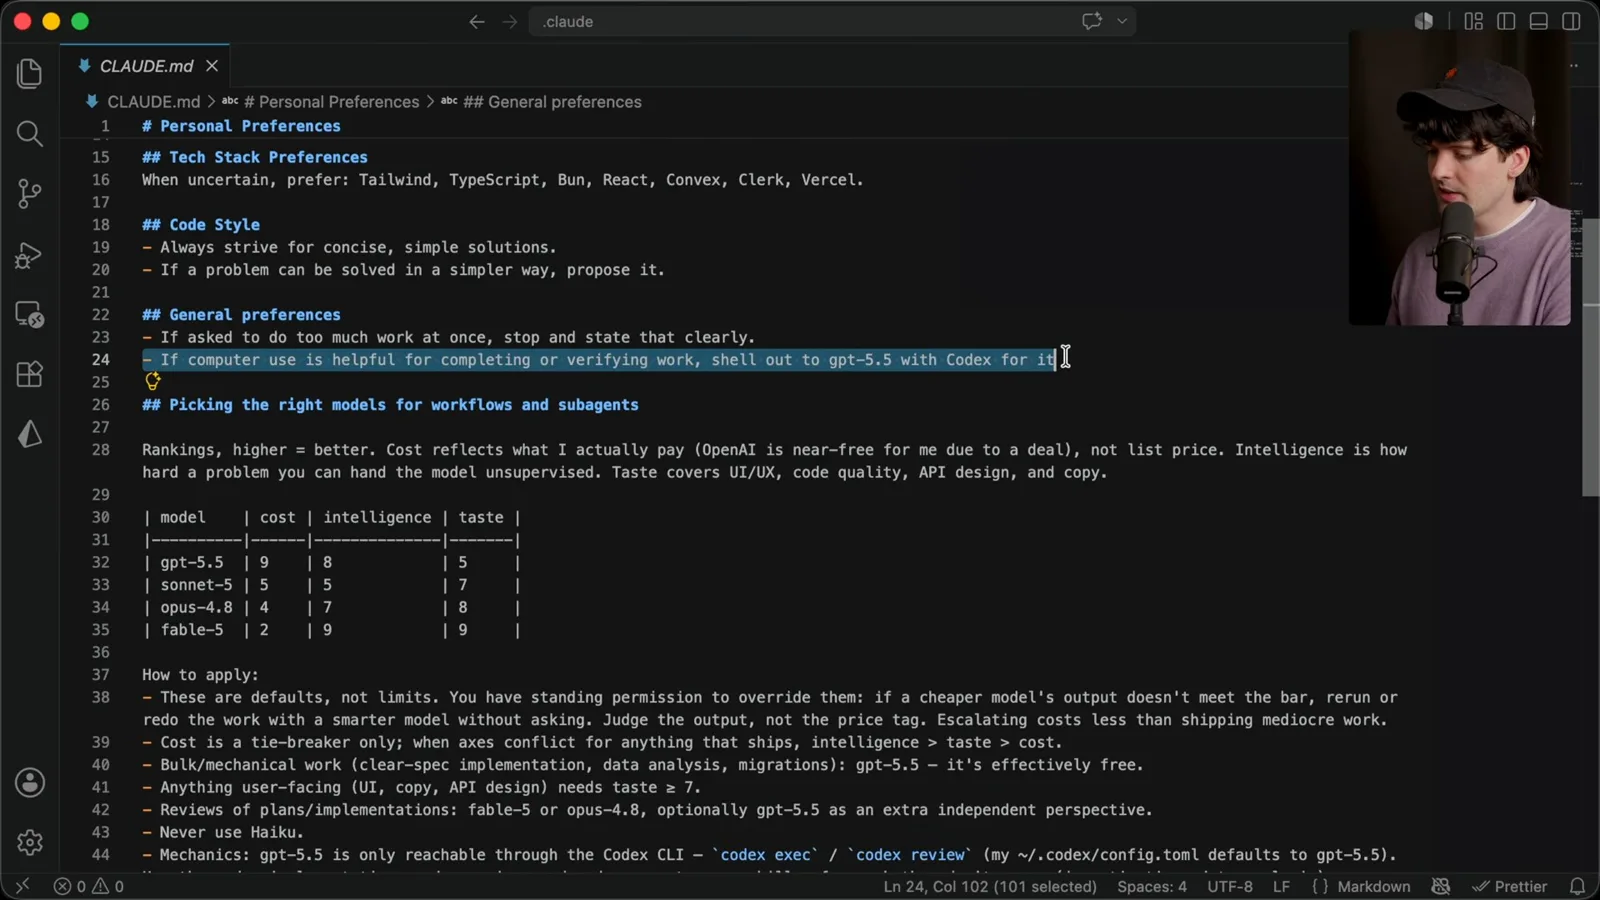
I put the routing guidance in my global CLAUDE.md along with ordinary preferences about technology and code style. One instruction tells the agent to use Codex when computer use would help complete or verify work. It can invoke another tool through the shell and return the findings to the parent session.
I distinguish a subagent, which can investigate a bounded piece of work, from a workflow that programmatically coordinates stages and their results. For example, a first stage can inspect multiple files or PRs, then route selected findings to reviewers in a later stage.
That was useful for Lakebed’s stale PRs. An agent could categorize the changes and send them to different review stages. I like letting the model adapt reviewer roles to the task, although that does not remove the need to inspect the results or choose appropriate boundaries.
The model does not automatically know my current subscriptions or the strengths I have observed in other tools. One line on screen says OpenAI is nearly free for me “due to a deal”; I clarify that I had no special personal deal. It was the agent’s interpretation of a then-current offer, not a price promise.
I made a subjective table for cost, intelligence and taste. By taste I mean things such as UI, code quality, API design and copy; by intelligence I mean how difficult a problem I think the model can handle. The scores encode my preferences and are not objective benchmarks.
A glossary in an instruction file helps the agent understand the words you use. Define what “taste,” “intelligence” or any project-specific term means to you, then explain how those concepts should influence the task. That makes your preferences more actionable than a vague ranking alone.
I tell the agent that model choices are defaults, not hard limits, and that it should judge the output. While reading the file I notice a cost rule the model wrote that does not match my preference, so I edit it live: use cheaper options to gather information or try things, but use the right model when needed.
My own routing sends mechanical work with a clear specification to GPT-5.5 and uses models I prefer for user-facing design or plan review. Those choices depend on my experience and costs. A different team should adjust them for its own quality bar, budget and available models.
In the setup I show, the agent reaches Codex through its CLI and uses specific skills for implementation, review and computer use. I also describe an adapter that lets a Claude workflow launch a Codex task and report back. Visibility into which agent is doing what and handling timeouts became practical concerns.
I did not invent the complete configuration in one sitting. I got a first version working, noticed failures, returned to the thread and asked how to prevent each one, then shortened and added the useful guidance. Treat the instructions as something to revise from experience.
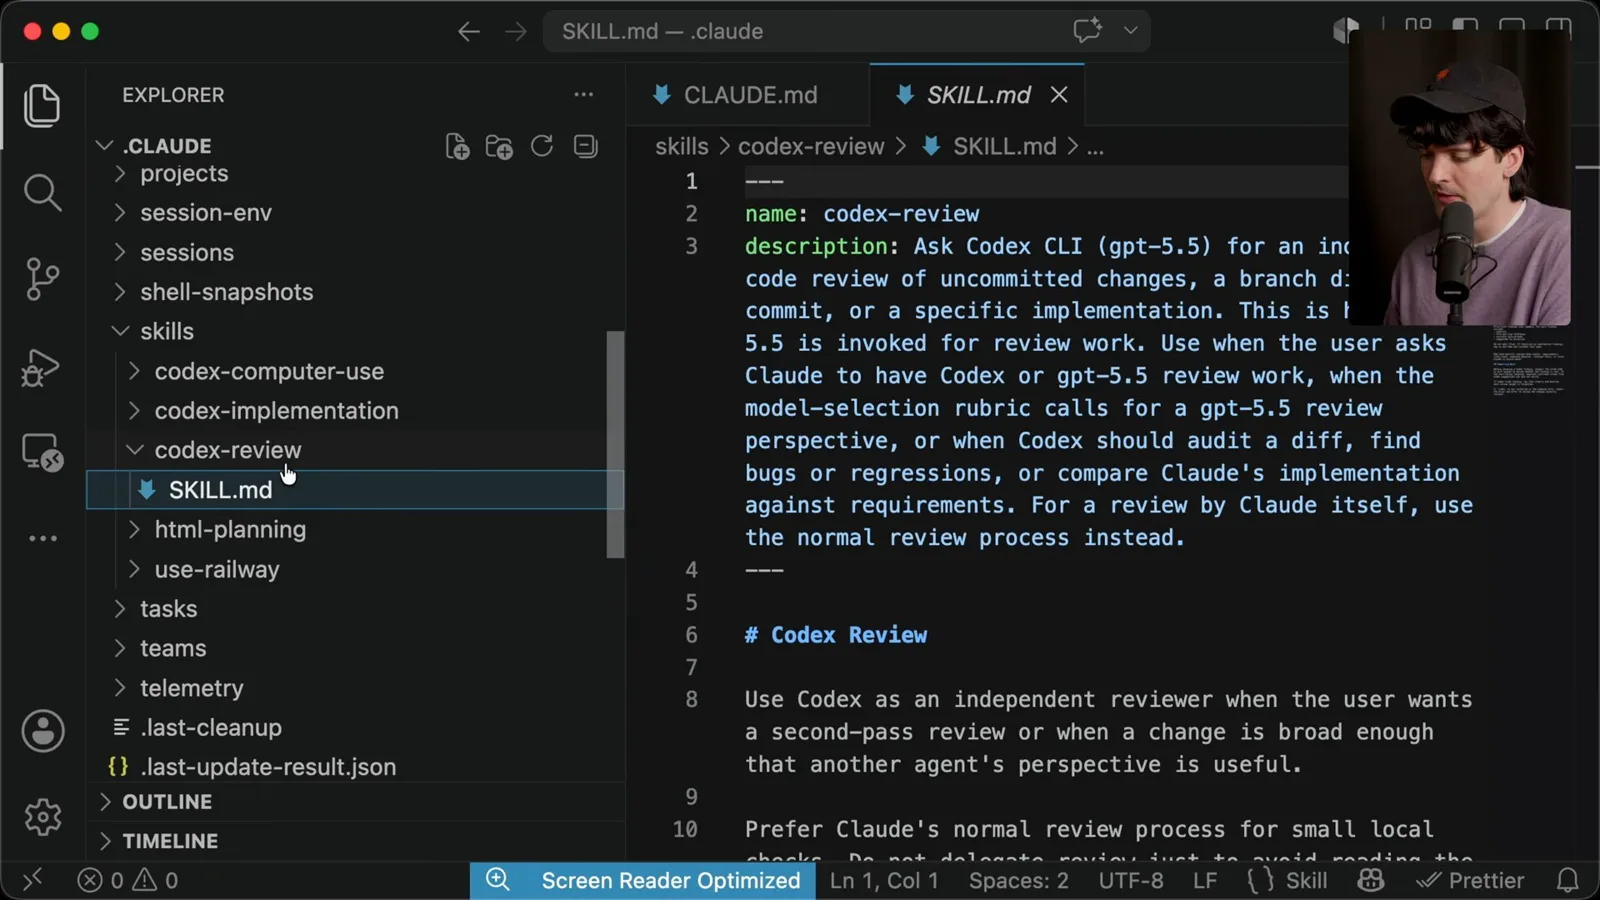
My review skill asks Codex to inspect a specific target, produce a report and have the parent verify important claims against the code. An independent review can be useful for a broad change, but a second agent’s assertion is still evidence to check, not an automatic approval.
I record command details in the skill because even occasional mistakes in invocation are annoying. I also added guidance for an empty review: say clearly that no findings were found and identify what was inspected, rather than confusing the parent into repeating the same task.
Do not blindly copy my files. Build a version that fits your own tools and edit it when you see a problem. Understanding and changing the configuration is more valuable than being afraid to touch a pasted block of someone else’s instructions.
I have a separate implementation skill for bounded changes, often in a worktree, and another for computer-use verification. The skill description matters because the model initially sees that description and loads the fuller instructions when it selects the skill.
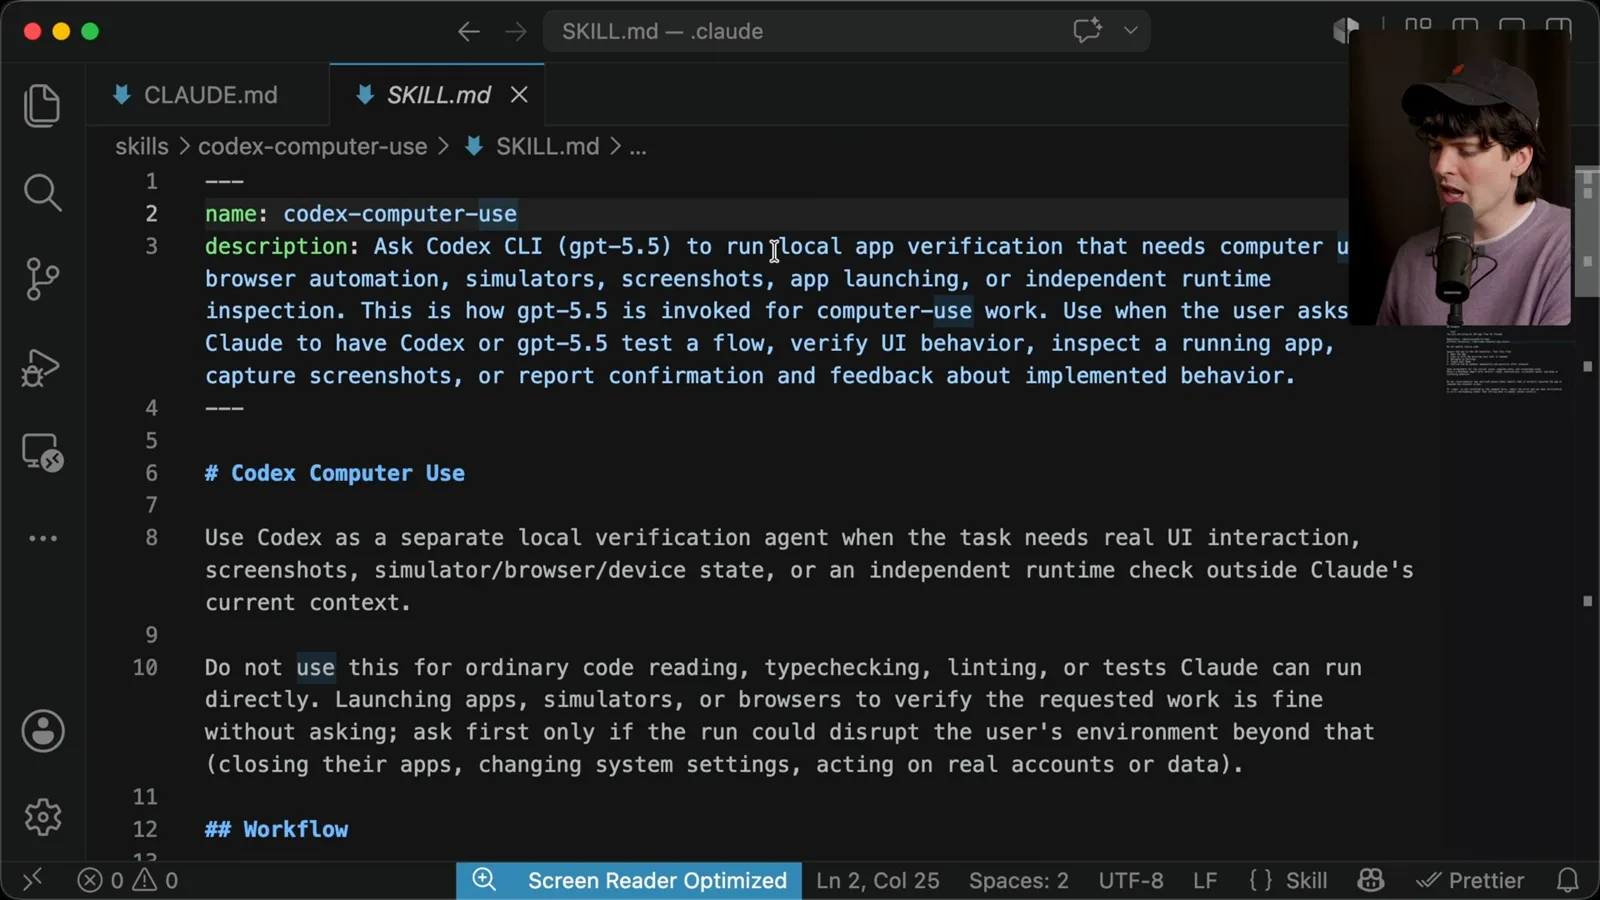
The computer-use skill covers tasks such as inspecting a running app, checking UI behavior, using a browser or simulator and capturing screenshots. I edit its trigger wording during the video so the agent can select it based on the verification needed, not only when I name a particular model.
Triaging a PR backlog
He shows a multi-agent review of 16 PRs and reads the resulting plans. The work is split into bounded changes with checkpoints.
For the Lakebed example, I asked the agent to investigate 16 open PRs and classify them: ready to merge, needing small fixes, superseded, or containing ideas better rewritten. I also asked for multiple reviewers to strengthen the decisions.
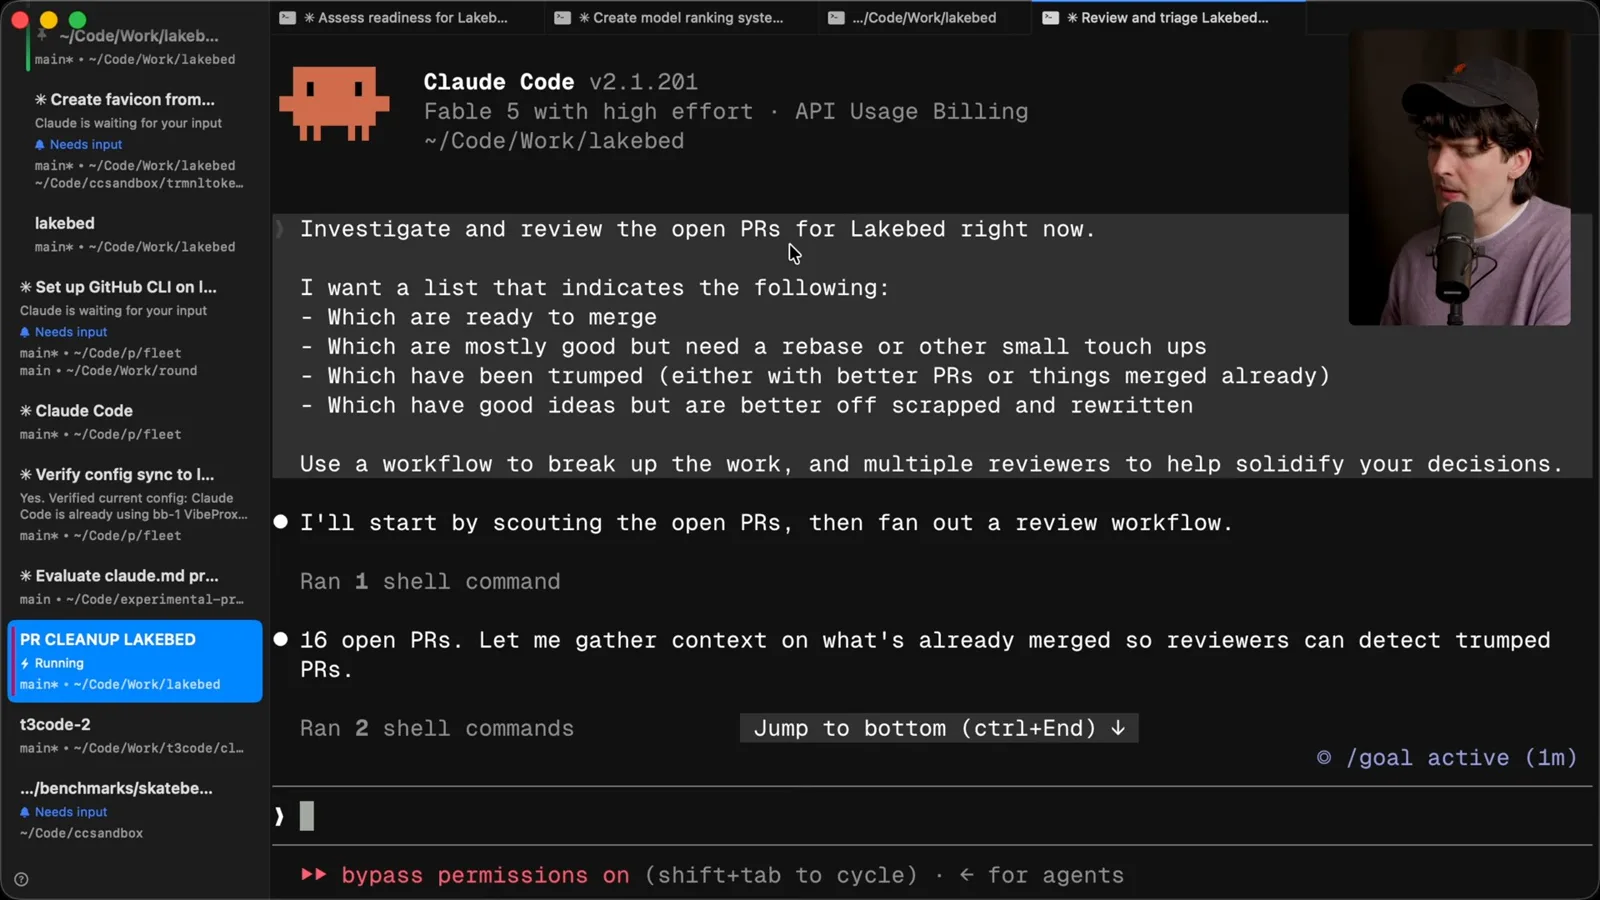
The reported workflow used 48 agents, including one investigator per PR and a review panel. It returned a triage list and a suggested sequence. I read the recommendations and made my own decisions; the agent count is what the session reported, not independent proof that every conclusion was correct.
Next I explicitly asked it to close superseded work and prepare new plans for the ideas worth keeping. I wanted links to the original PRs and an explanation of the existing implementations. The plans went back to me for review before the next stage.
I read the plans, examined the PRs that inspired them and asked questions about the remaining work. Asking questions helped align my understanding with the agent’s. The resulting plan separated ready PRs from new implementations and broke larger changes into bounded pieces.
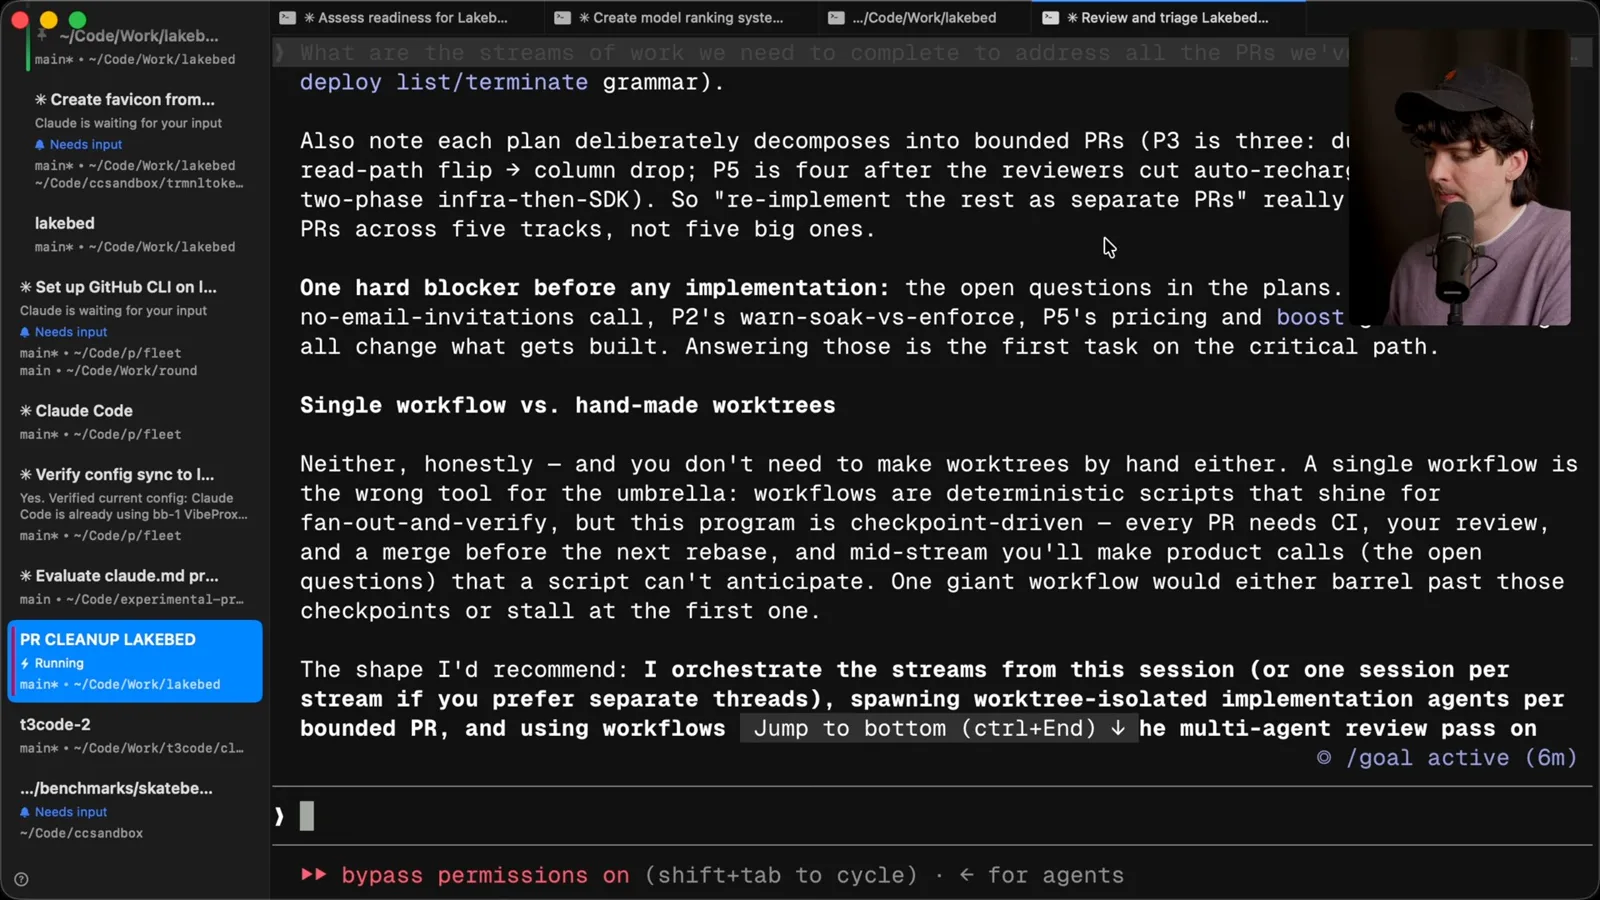
The agent advised against one giant deterministic workflow for the entire program. Each PR needed checkpoints such as CI, review and merging before later rebases, and some product decisions required me. It proposed session-level orchestration with isolated worktrees and workflows for fan-out review where appropriate.
Authorization, staging and verification
He explicitly authorizes merges, requires automated review and retains human control over production. He then describes testing the result in staging.
After discussing the plan, I set a goal to complete the agreed work and explicitly authorized operations including branches, worktrees and PR merges. That permission applied to my project and this run. It was not a general instruction that agents should merge changes without the relevant owner’s authorization.
I instructed it to track completed items in TODO.md and require my automated reviewers’ approval before merging. It ran for about five hours. Automated reviewers are part of the process, but their approval is not a substitute for understanding the risk and independently checking important results.
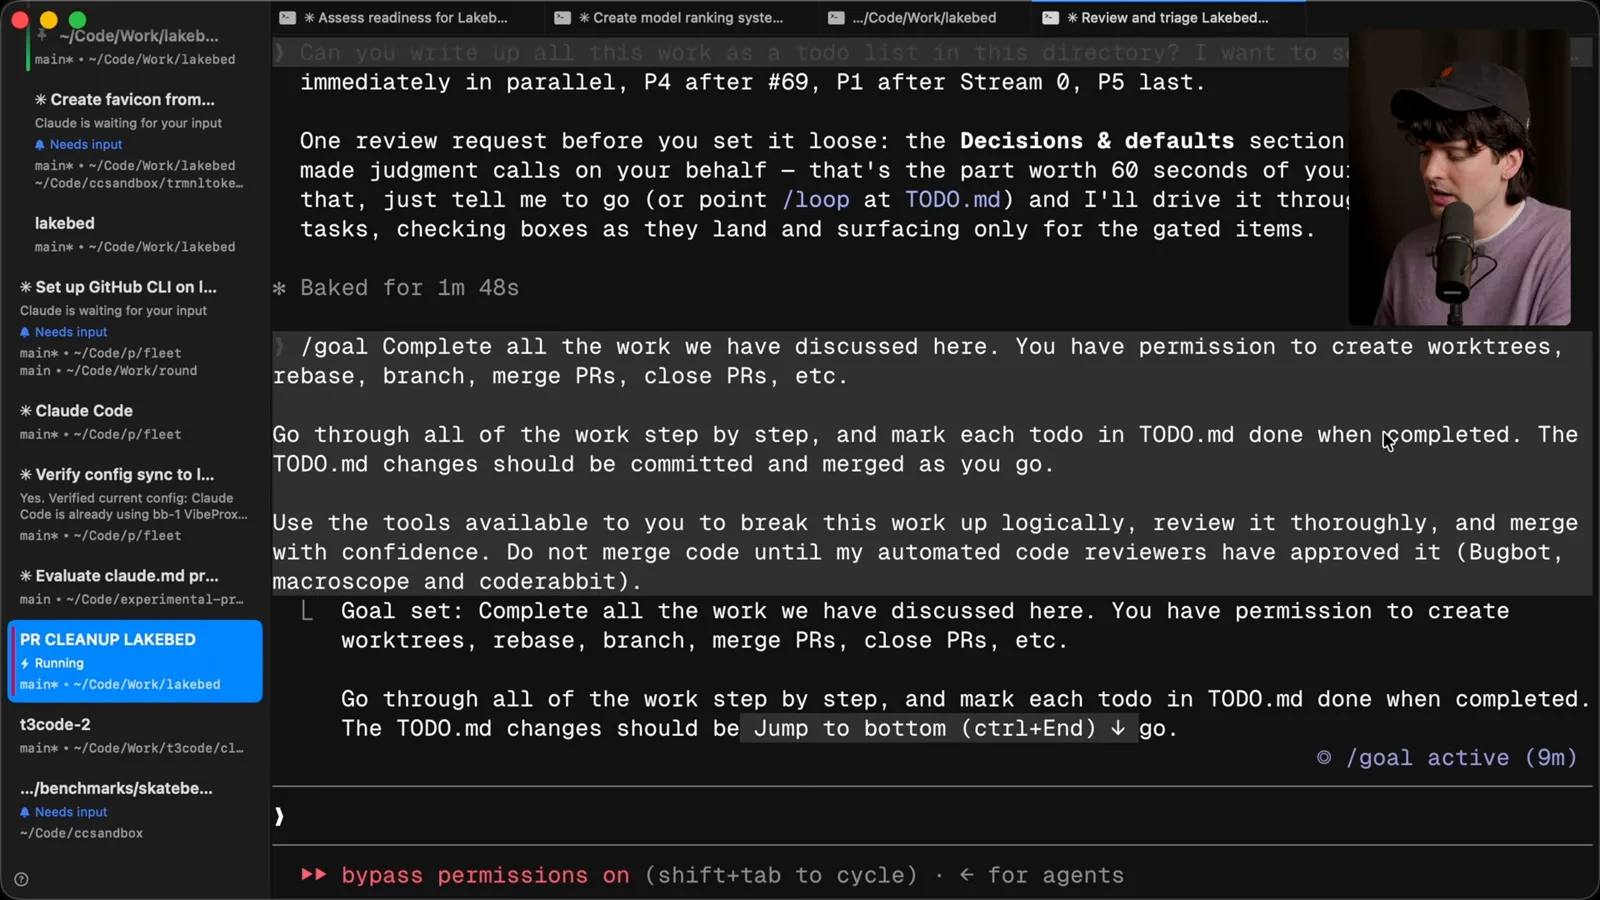
The important boundary was deployment: merging main deployed to staging, while production deployment remained under human control. I had also repaired staging first. This distinction is why I was more comfortable letting the agent work through the merge sequence.
Afterward I personally stress-tested staging, asked other agents to exercise new and existing features, and had them inspect the difference from production. I report that I found little to fix in that pass. That is my account of this project, not proof that an automated review can catch every defect.
Working across machines
Theo shows remote agent work, investigating a flaky test and combining worktrees. He closes with a warning not to blindly merge experimental output.
To continue other work, I connected to additional machines. I found plain SSH frustrating for the interactive features I wanted and used T3 Code to manage remote agents instead. The desktop, web and mobile interfaces let me check work from different devices.
I used private networking to connect to those machines and experimented with the mobile app. That made it easy to start separate worktrees for ideas or small bugs as I encountered them. T3 Code is my own project, so my enthusiasm for it comes with that obvious connection.
When a test failed intermittently on a PR, I took a screenshot, selected a machine and repository, and asked an agent in a worktree to investigate with a link to the failing run. Starting a separate investigation let me continue other work while the failure was examined.
I also asked an agent to combine changes from multiple worktrees into one branch, resolving overlaps so I could test them together. The agent reported completion in about five minutes. The combined branch still needed testing and review before a PR could be considered.
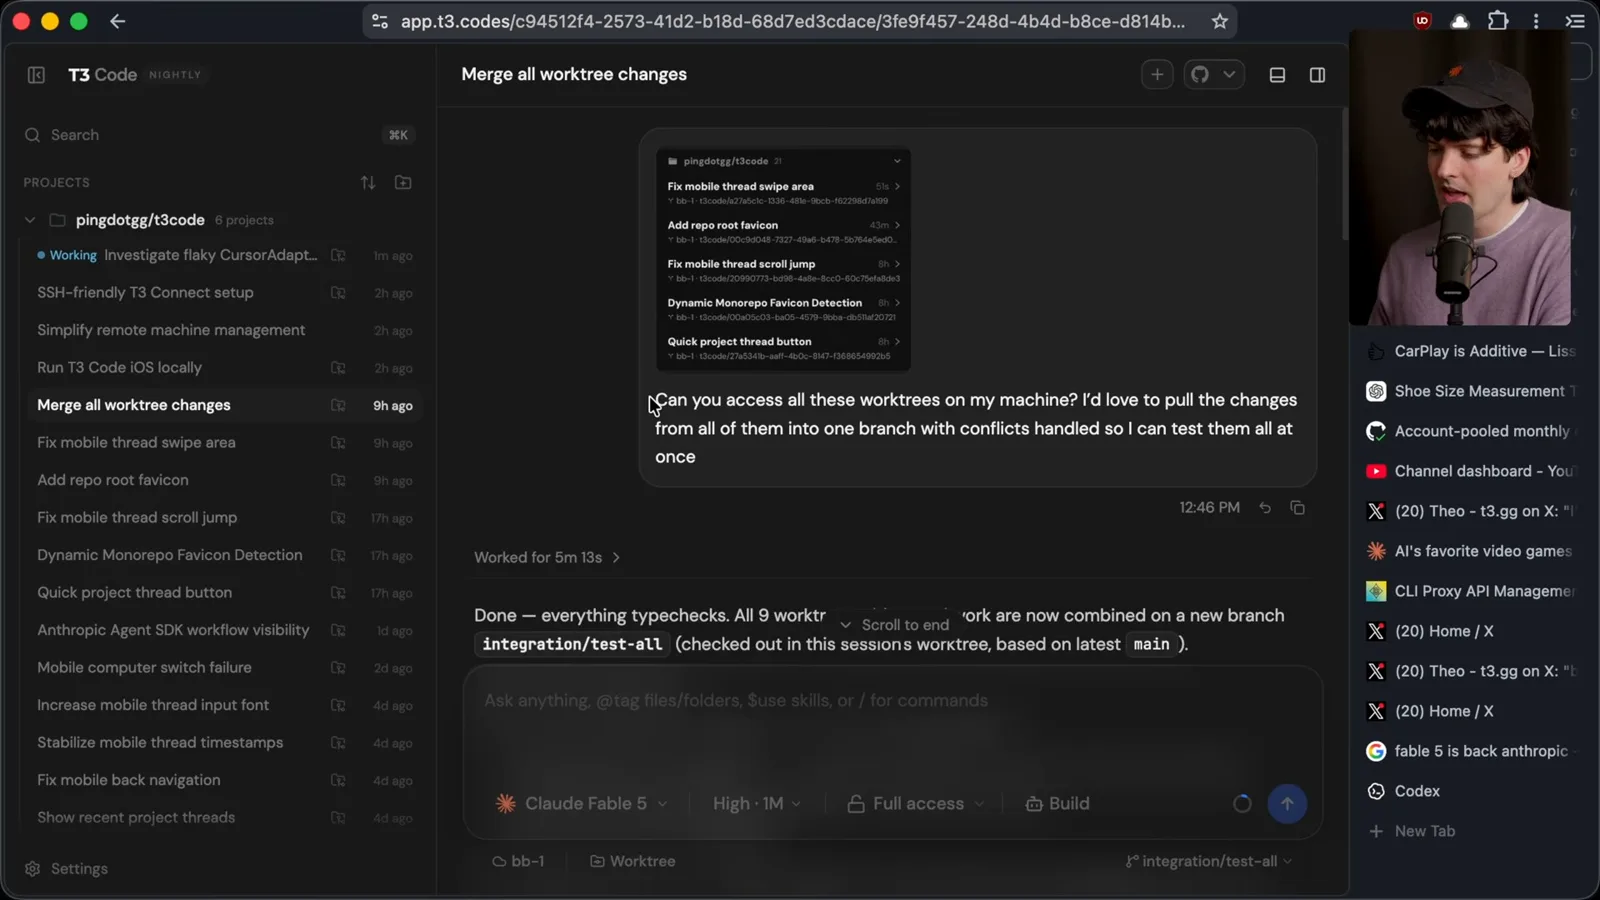
I do not expect most experimental changes to be merged. The time and scope of an attempted fix can be a signal: a short change might be simple, while a long investigation can reveal architectural complexity. It is a heuristic, not proof that a fast patch is correct or a slow one is bad.
A mobile scroll issue took much longer than a swipe issue, so I wanted more scrutiny rather than blindly merging. Even the quick fix referred to a drawer in a way that raised questions, so I asked about it. Think about architecture, the request and the diff, and ask when something does not make sense.
I also mention a proxy I experimented with for managing multiple accounts and note that this setup changes some product features. Its compatibility and account rules should be checked for the services involved. My broader lesson is to keep refining the workflow while reviewing the work it produces.
同じチャンネルの記事
 38:47EN
 Theo - t3․gg· 2026年10月28日Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026年10月27日Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026年10月26日Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026年10月23日Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026年10月22日Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026年10月20日Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.