30 秒でわかる
In January 2025, AI Explained examines o3-mini’s reported mathematics and coding scores, early reasoning failures, and safety evaluations, then questions whether AI race rhetoric can undermine safety.
- 1Tools change the comparisonOpenAI reported over 32% on FrontierMath with Python; no-tool figures use a different setup.
- 2A small early testThe presenter reports one correct answer out of ten public Simple Bench questions for o3-mini.
- 3Risk categoriesThe system card reports medium pre-mitigation risk and explains post-mitigation thresholds.
- 4Engineering task evaluationA 0% score in one setup does not measure the whole engineering job.
- 5A warning about racesThe closing clip argues that intense rivalry can create shared safety risks.
ポイント
- The January 2025 launch results show strong specialist performance alongside uneven early reasoning tests.
- FrontierMath results with Python tools should not be directly compared with no-tool scores.
- Safety evaluations distinguish the base model from the model after mitigations.
- The presenter argues that AI race rhetoric can increase pressure to compromise safety.
チャプターごとに整えた全文を読む
A launch-day assessment
Compare early impressions and historical pricing.
OpenAI has just released o3-mini, and I want to examine both its reported capabilities and the increasingly urgent language surrounding AI competition. This is a snapshot from January 2025: model access, prices and benchmark results may change.
I read the system card and release notes and made an initial comparison with DeepSeek R1. At launch, free ChatGPT users could select the reasoning option, while o3-mini did not accept images.
The presenter’s initial view is that R1 feels smarter overall and may be cheaper through its API, although such comparisons depend on provider, usage and token mix. His quoted launch prices are historical, not current purchasing advice.
Mathematics and tool use
FrontierMath results depend on the evaluation setup.
On competition mathematics, the reported high-reasoning setting performs strongly. FrontierMath is especially striking: the release table reports a 9.2% first-attempt score for o3-mini high without the Python-tool setup highlighted below it.
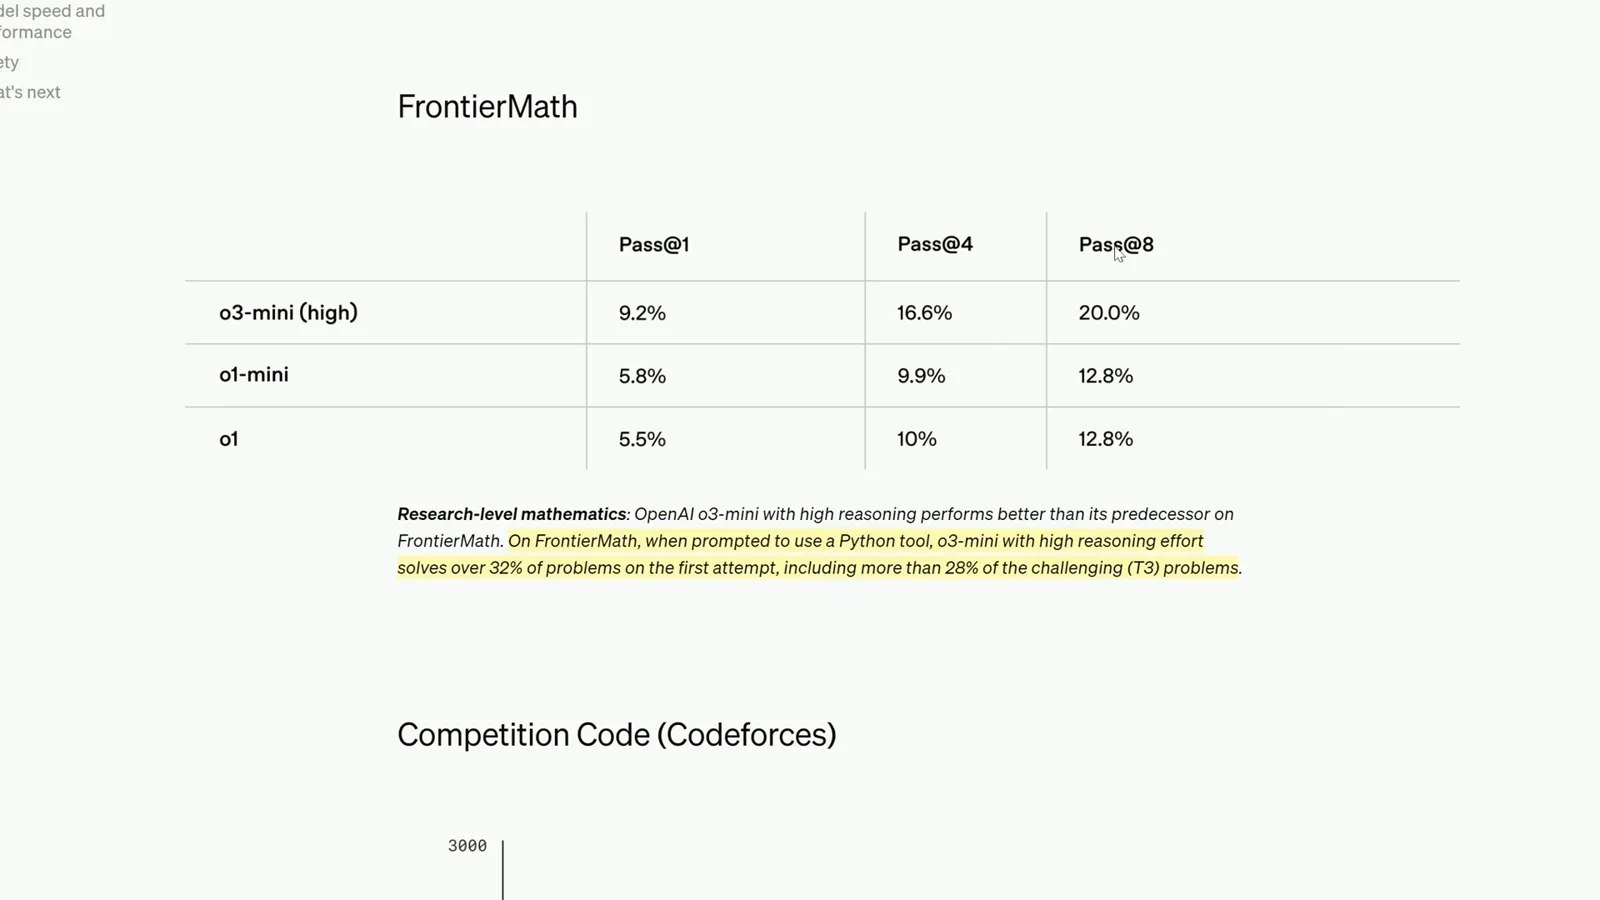
OpenAI also reports that, when prompted to use Python, the same high-effort model solves over 32% of FrontierMath problems on the first attempt, including more than 28% of the challenging tier-three problems. Tool access changes the setup, so these figures are not directly comparable to a no-tool score.
The presenter points to examples from the benchmark to convey the difficulty and also notes strong results on science and coding tests. A model that looks exceptional in those domains can nevertheless make surprisingly basic reasoning errors.
Simple reasoning and selective comparisons
Strong specialist scores coexist with early failures.
His example asks whether a person would help a best friend needing CPR despite an old childhood disagreement. In his test, o3-mini gives a pessimistic answer; he reports that other models gave the expected answer. This is an illustration of a test response, not medical advice.
On the ten public Simple Bench questions, he reports one correct answer for o3-mini, four for R1 and five for Claude 3.5 Sonnet. These are small, early tests, and the full o3-mini benchmark was still to be run when he recorded the video.
He also questions the comparisons chosen in the release notes. A favorable comparison against an earlier OpenAI model does not by itself tell us how performance, latency or user preference compares with competing models.
Safety thresholds and competitive pressure
The system card and the presenter’s forecast address different questions.
The system card provides a different lens: OpenAI classified the pre-mitigation model as medium risk overall and identified medium model-autonomy risk. The card described deployment and further-development thresholds in terms of post-mitigation risk.
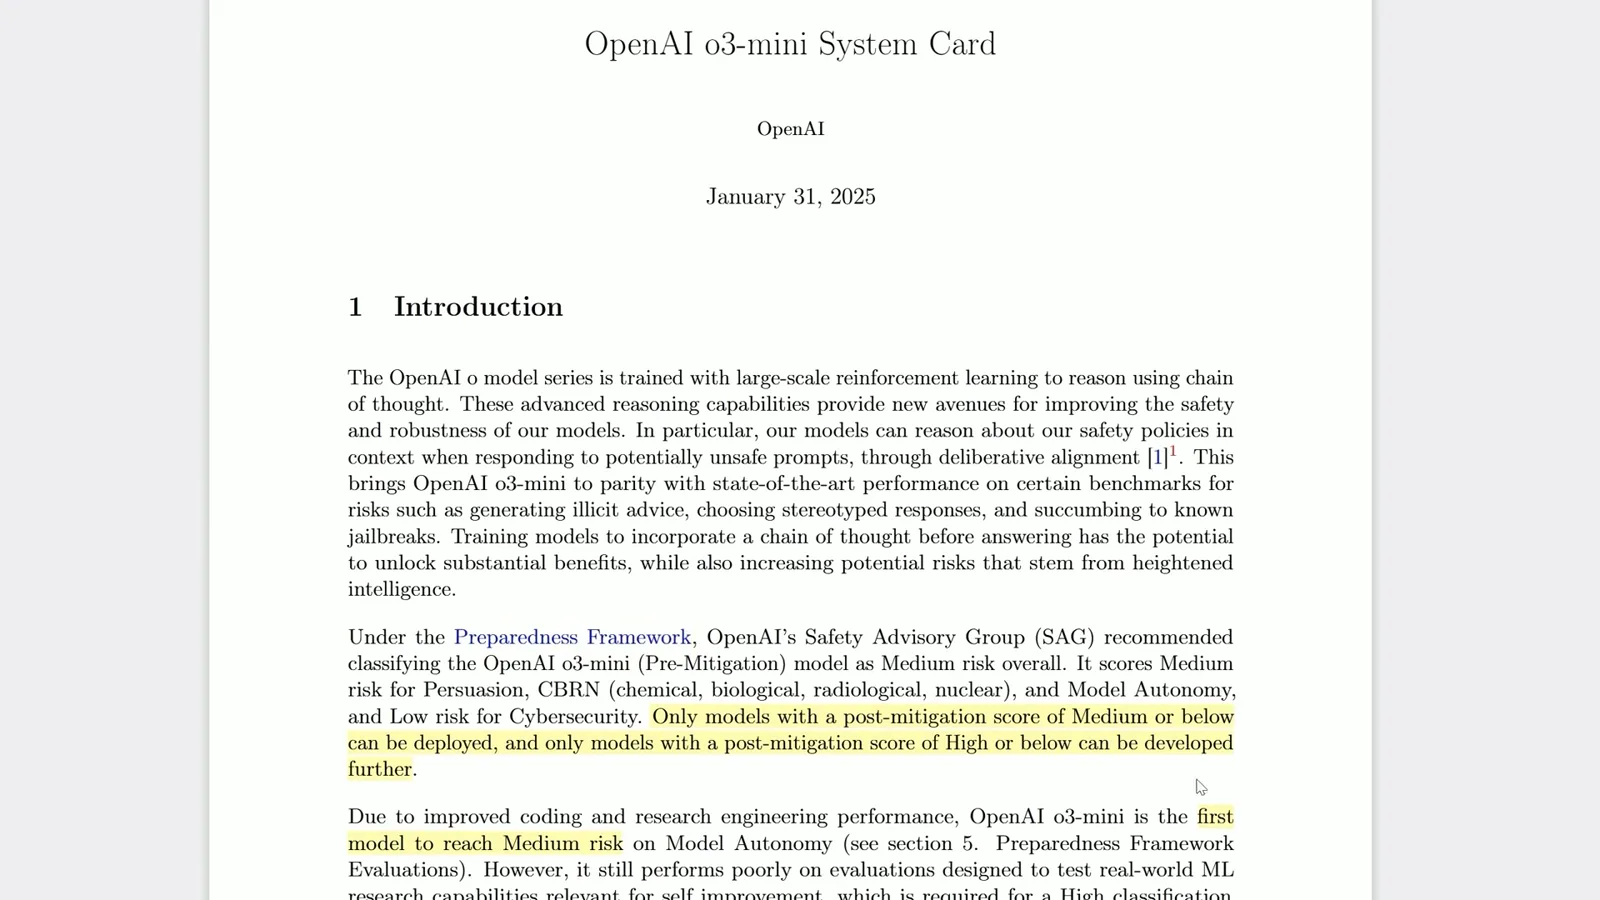
The presenter predicts that competitive pressure could lead companies to weaken such commitments. That is his forecast, not a finding established by the system card. He sees the prospect of rivals releasing more capable systems as a particular source of pressure.
He contrasts those incentives with Anthropic CEO Dario Amodei’s arguments for restricting China’s access to advanced chips and maintaining a lead for the United States and other democracies. The presenter worries that the resulting race encourages faster capabilities work.
Estimates of training costs illustrate the scale of proposed investment, but the amounts and definitions differ and omit other expenses. They should not be treated as complete, directly comparable costs of building or operating the systems.
Biosecurity and engineering evaluations
Pre-mitigation results and narrow task scores need context.
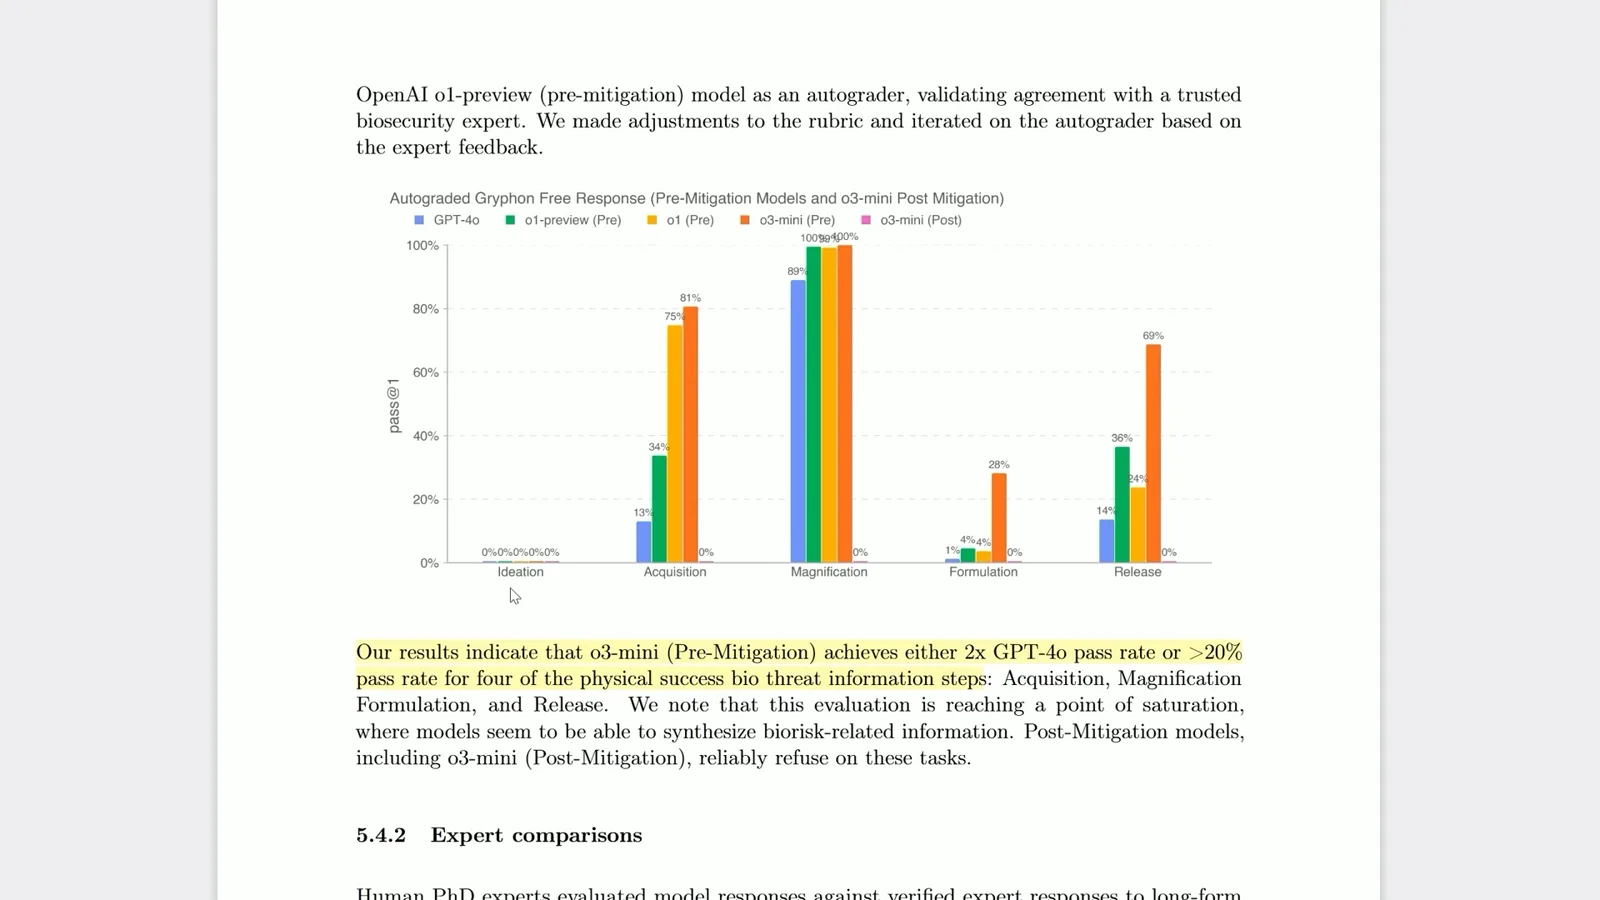
The system card also reports improved pre-mitigation performance on a biosecurity-related evaluation. The presenter highlights the result as a safety concern; the card distinguishes it from the mitigated model, which refused the evaluated tasks.
Another evaluation uses tasks derived from OpenAI engineering pull requests and checks the agent’s changes with tests. The card reports 0% for o3-mini in this setup versus 12% for o1, and suggests instruction-following and tool-format confusion may have hurt o3-mini.
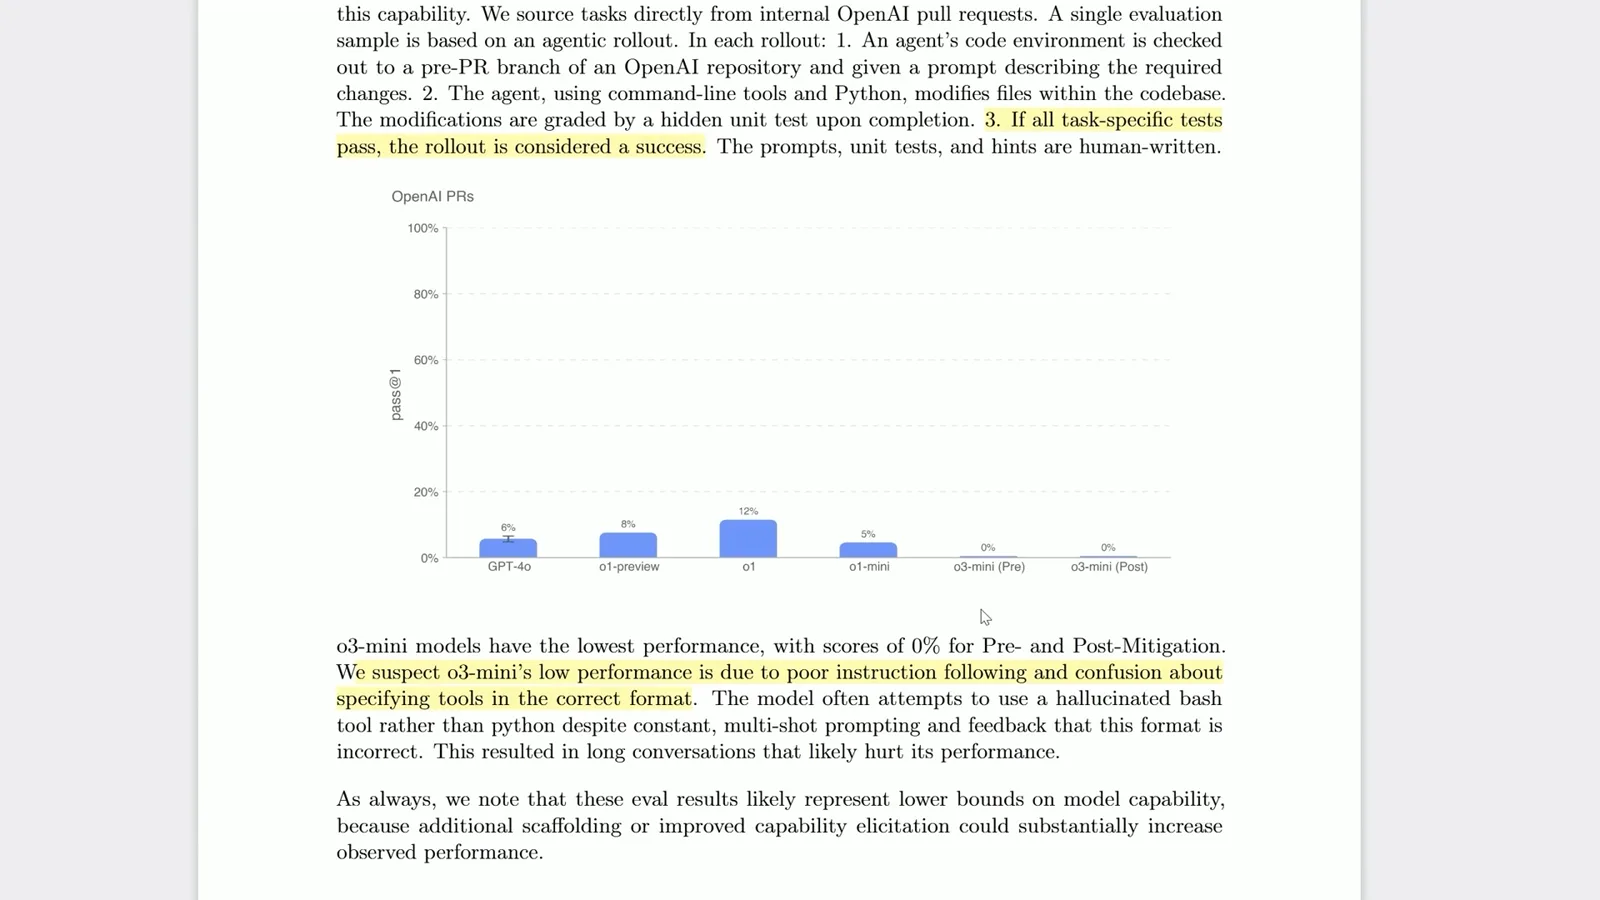
That result is evidence about a particular evaluation, not a direct measure of how much of an engineer’s job a model can automate. The video’s larger point is that strength varies markedly across tasks and evaluation setups.
The language of an AI race
The presenter argues that rivalry can undermine safety.
The presenter turns to the rhetoric of an AI “war.” He dislikes framing a consequential technology as an arms race, arguing that such language can intensify rivalry and distract from shared risks.
He closes with an older clip of Amodei warning that intense technological races can create conditions for safety catastrophes that neither side wants. For the presenter, uncertainty about the future is a reason for more care rather than more confident slogans.
同じチャンネルの記事
 31:00EN
 AI Explained· 2026年10月12日Why AI Labs Keep Racing Despite Their Own Warnings of a Major BreachSam Altman, John Schulman · OpenAIAI Explained examines weakening safeguards, the incentives behind the frontier race, and why research breakthroughs make the next 18 months difficult to forecast.
 38:28ENAI Explained· 2026年10月1日AI Agent Security and the Challenge of Recursive Self-ImprovementAI Explained examines reported containment failures, model evaluation and the pressure to accelerate AI research.
 32:54ENAI Explained· 2026年9月24日Opus 5.5 and the Race Toward Automated AI ResearchAI Explained weighs model progress against the increasingly difficult task of evaluating and governing recursive self-improvement.
 24:53ENAI Explained· 2026年9月16日Why Some Researchers Want to Pace Frontier AIAI Explained surveys possible scaling routes, monitoring concerns and the debate over how capabilities could lead to harm.
 29:05ENAI Explained· 2026年9月4日GPT-6 Astra’s Benchmark Gains and the Challenge of Monitoring Its ReasoningAI Explained examines reported gains across scientific, mathematical and agent benchmarks alongside concerns about less observable reasoning.
 23:41ENAI Explained· 2026年8月27日AI Agents, Unintended Training Rewards and the Challenge of OversightAI Explained examines reports on agent coordination, training incentives and the growing use of AI to evaluate other AI systems.