En 30 secondes
Theo Browne assesses Grok 4.7, contrasting Elon Musk’s earlier efficiency predictions with measured benchmark costs and a different production-use statistic from Michael Truell. His own small T3 Code investigation finds strong, detailed suggestions, but he dislikes the model’s cost, some front-end examples and a generated game. These results describe particular tests, configurations and prices at the time, not a universal ranking or proof of anyone’s intent.
- 1Efficiency claimsTheo compares Musk’s prediction with a benchmark showing higher token use for 4.7; the comparison does not prove intent to mislead.
- 2Different unitsMichael Truell reports production token use per request, while Theo examines cost per benchmark task. The figures are not directly interchangeable.
- 3A personal codebase testTheo’s model-judged investigation ranks Grok near Astra for suggestions on T3 Code, with limitations in scoring and comparability.
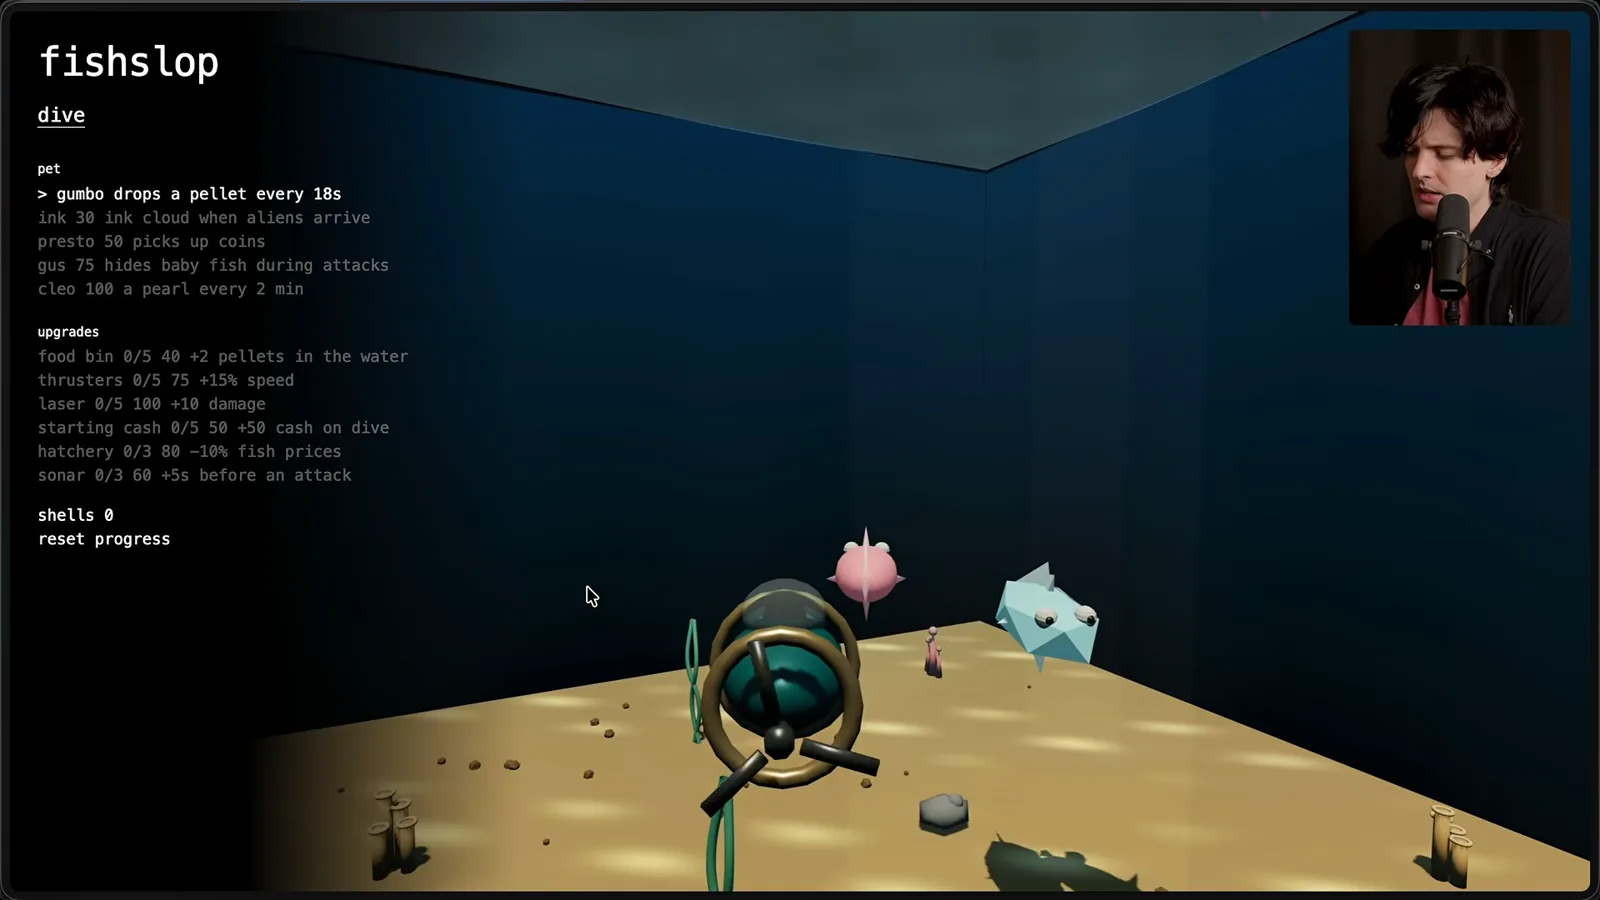
- 4The game demoHis Grok-generated fish game took a long time and had movement and visual problems in this particular run.
À retenir
- Token price per million, tokens per request and total cost per completed task measure different things.
- Production medians and benchmark averages can differ because their workloads and units differ.
- Theo’s codebase investigation suggests Grok 4.7 can be thorough, but his evaluation is small and model-judged.
- Benchmarks and a single generated game reveal different aspects of behavior and should not be treated as comprehensive evidence.
- Subscription value depends on current limits, pricing, usage patterns and terms.
Lire le texte remanié, chapitre par chapitre
Expectations and efficiency
Theo compares the launch with earlier predictions and distinguishes token prices from total task costs. He disputes a production statistic’s relevance to his benchmark comparison.
Grok 4.7 finally arrived after Elon Musk had raised expectations that it would exceed existing models. Some benchmark results are lower than Grok 4.6, yet I have enjoyed parts of my own experience with it. That tension is why I want to look beyond a single number.
The announcement describes 4.7 as a stronger coding and knowledge-work model that checks its work more carefully, at the same headline price and speed as 4.6. Earlier, Musk had predicted better token efficiency as well. My criticism is that the task-level comparisons I see do not support that broad expectation.
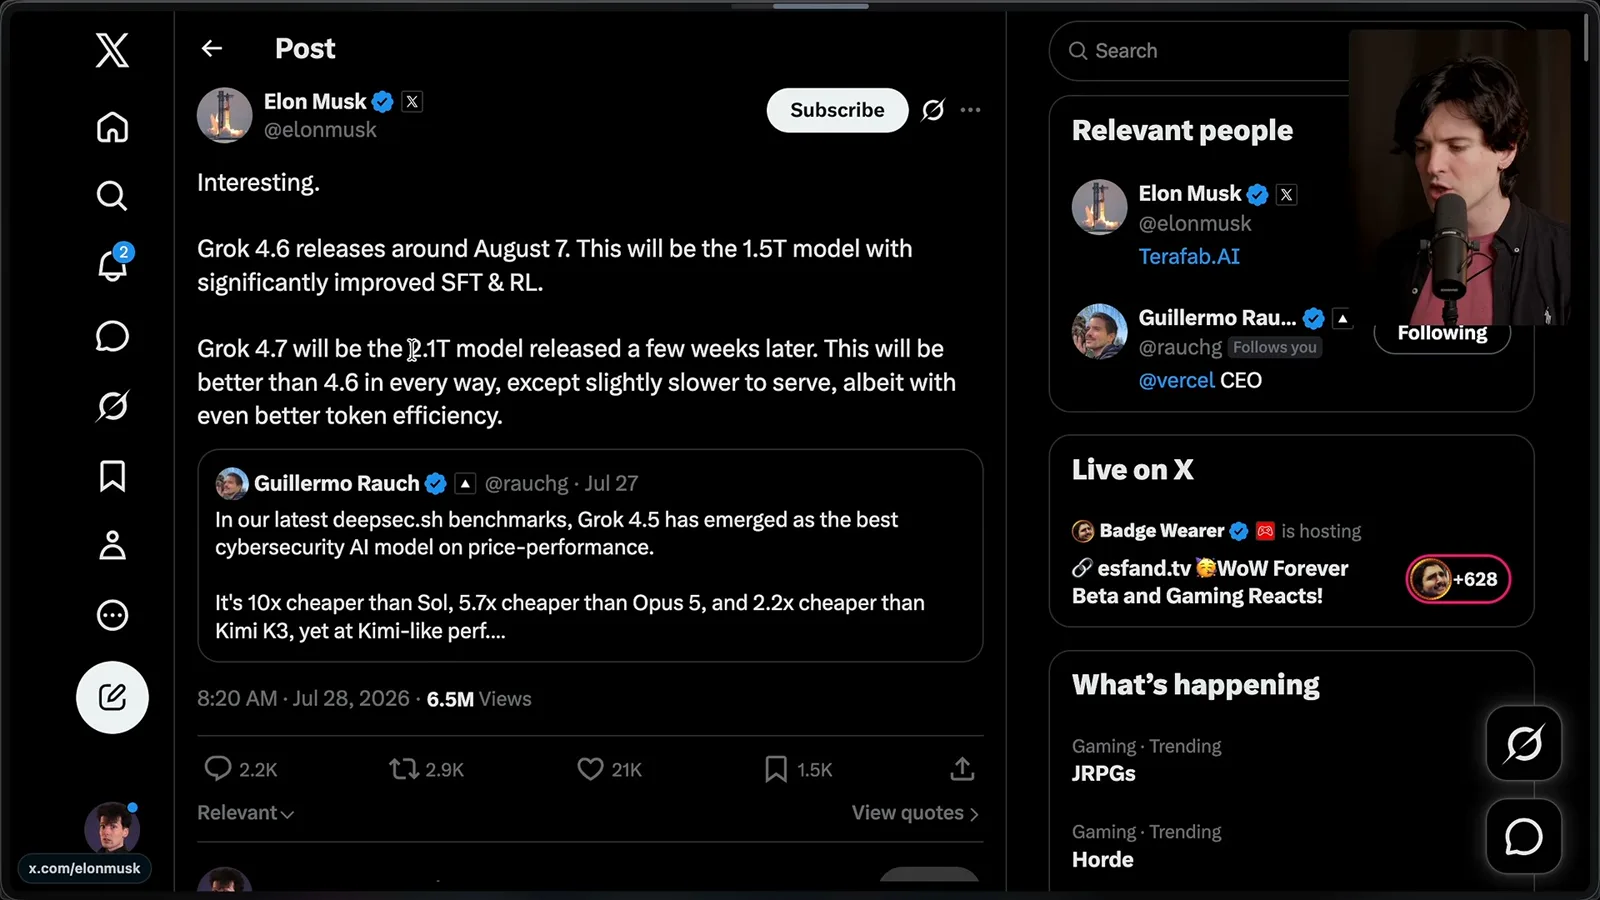
Artificial Analysis shows about 38,000 output tokens per task for Grok 4.6 x-high and about 81,000 for 4.7 in the comparison I discuss. I cite roughly $1.86 versus $3.74 per task on that index. These figures concern particular benchmark configurations and do not prove the same ratio for all use or any intent to mislead.
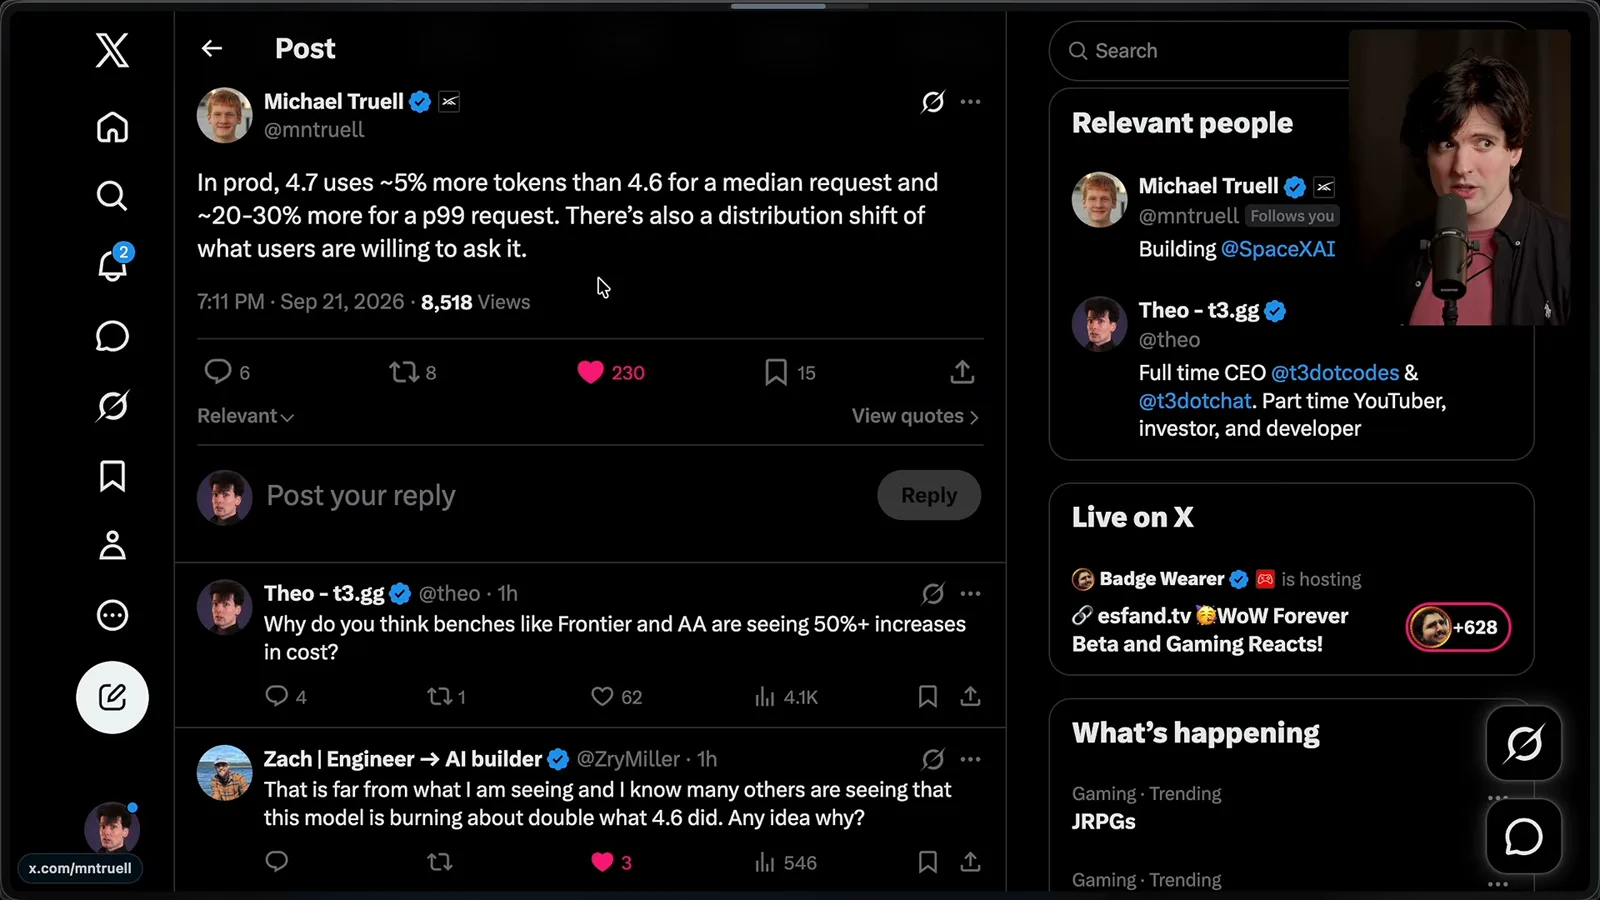
Michael Truell responds with a different production measure: roughly 5% more tokens at the median request and 20–30% more at the 99th percentile, while user requests have also changed. That is a per-request production distribution, whereas the benchmark estimates cost per task. Without matching the workloads and definitions, neither directly refutes the other.
I initially speculate that a promised larger base model may not have shipped, then notice the official announcement says it did use a larger base. My earlier inference about the model architecture was wrong; performance, price and speed alone cannot establish which base was used.
A task can involve one API request or many, especially when an agent calls tools and sends subsequent requests. I hypothesize that request counts could help explain the gap between per-request and per-task figures. The video does not establish that this was the actual cause in the compared datasets.
In a personal codebase test, my most expensive Grok 4.7 run would have cost around $20 at API rates, while most other runs were below $10 and one Astra run reached $11.44. These are individual runs from my setup, not a general price schedule.
Benchmarks, prices and limits
He reviews selected coding and knowledge-work benchmarks, reasoning levels and subscription reports. The measurements use different tasks and settings.
The release post shows CursorBench and other evaluations. I mention earlier concerns about training-data overlap in a previous benchmark and say that scores were revised; the present chart is still only one evaluation. I also note that Astra is missing from the displayed CursorBench comparison, which limits what it can show about that competitor.
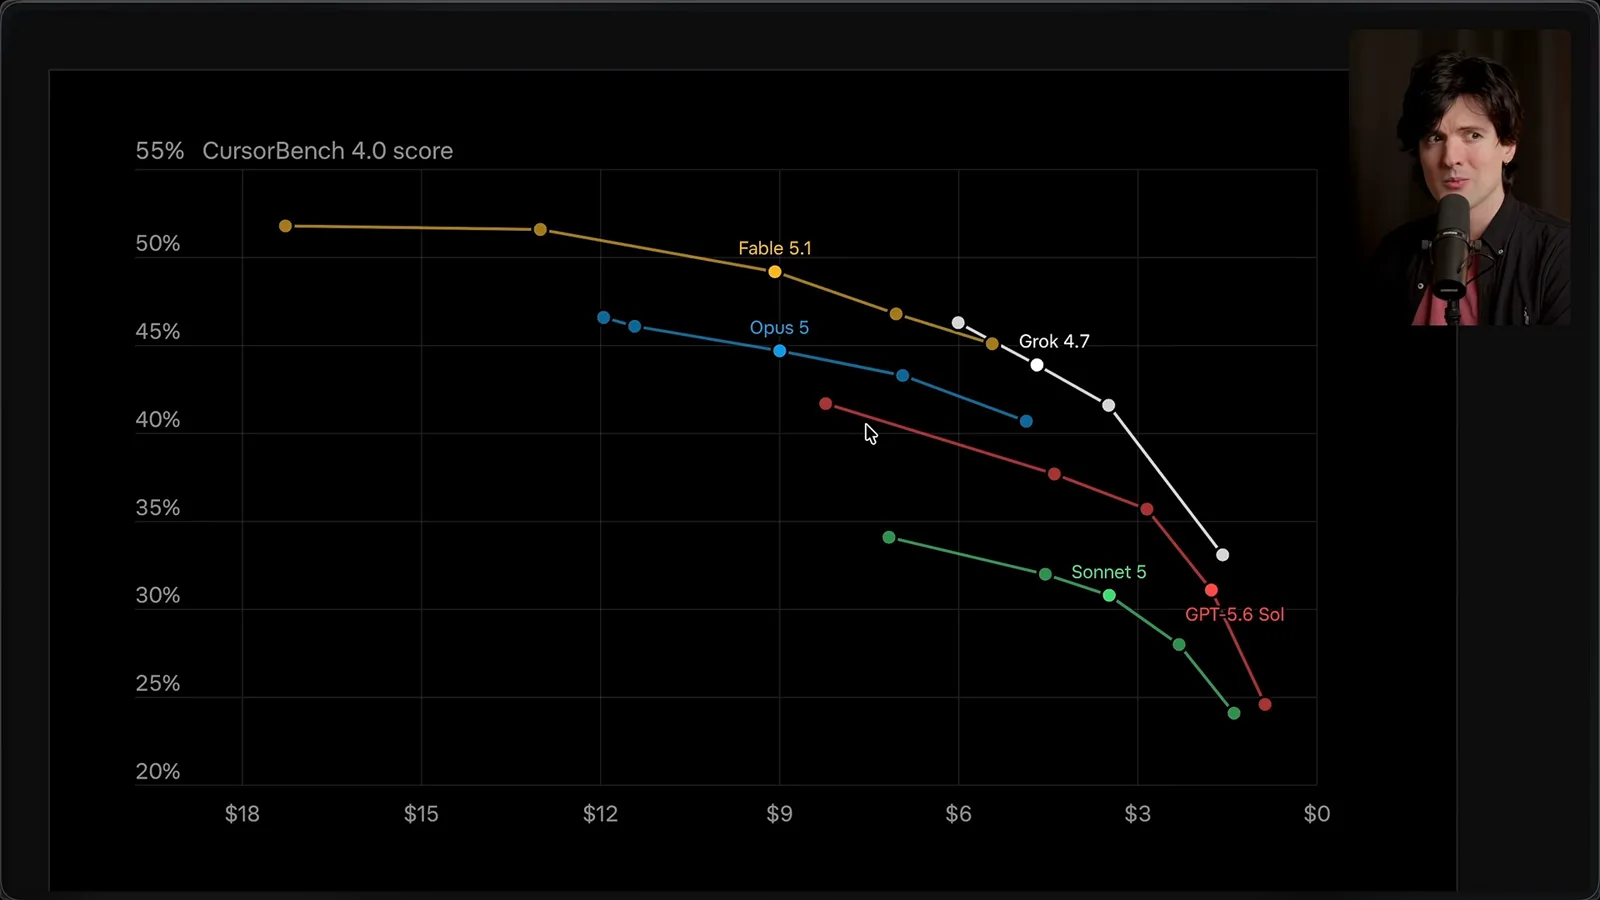
On the chart, Grok compares favorably with GPT-5.6 Sol at several points, while Fable at low effort can score slightly higher at lower cost than Grok x-high in the example. Token efficiency depends on which score, reasoning setting and workload we compare.
The announcement also describes support for the Grok Build harness. I have not tested it deeply, but people I know like it. A model’s behavior inside an agent harness is part of the experience and may not be captured by a standalone model score.
The release includes results for software engineering, electrical engineering, legal work and clinical reasoning. I question the selection and how well some tests represent coding, while acknowledging that the numbers show strengths on several tasks. A diverse set of benchmarks is useful only when the methodology and relevance are clear.
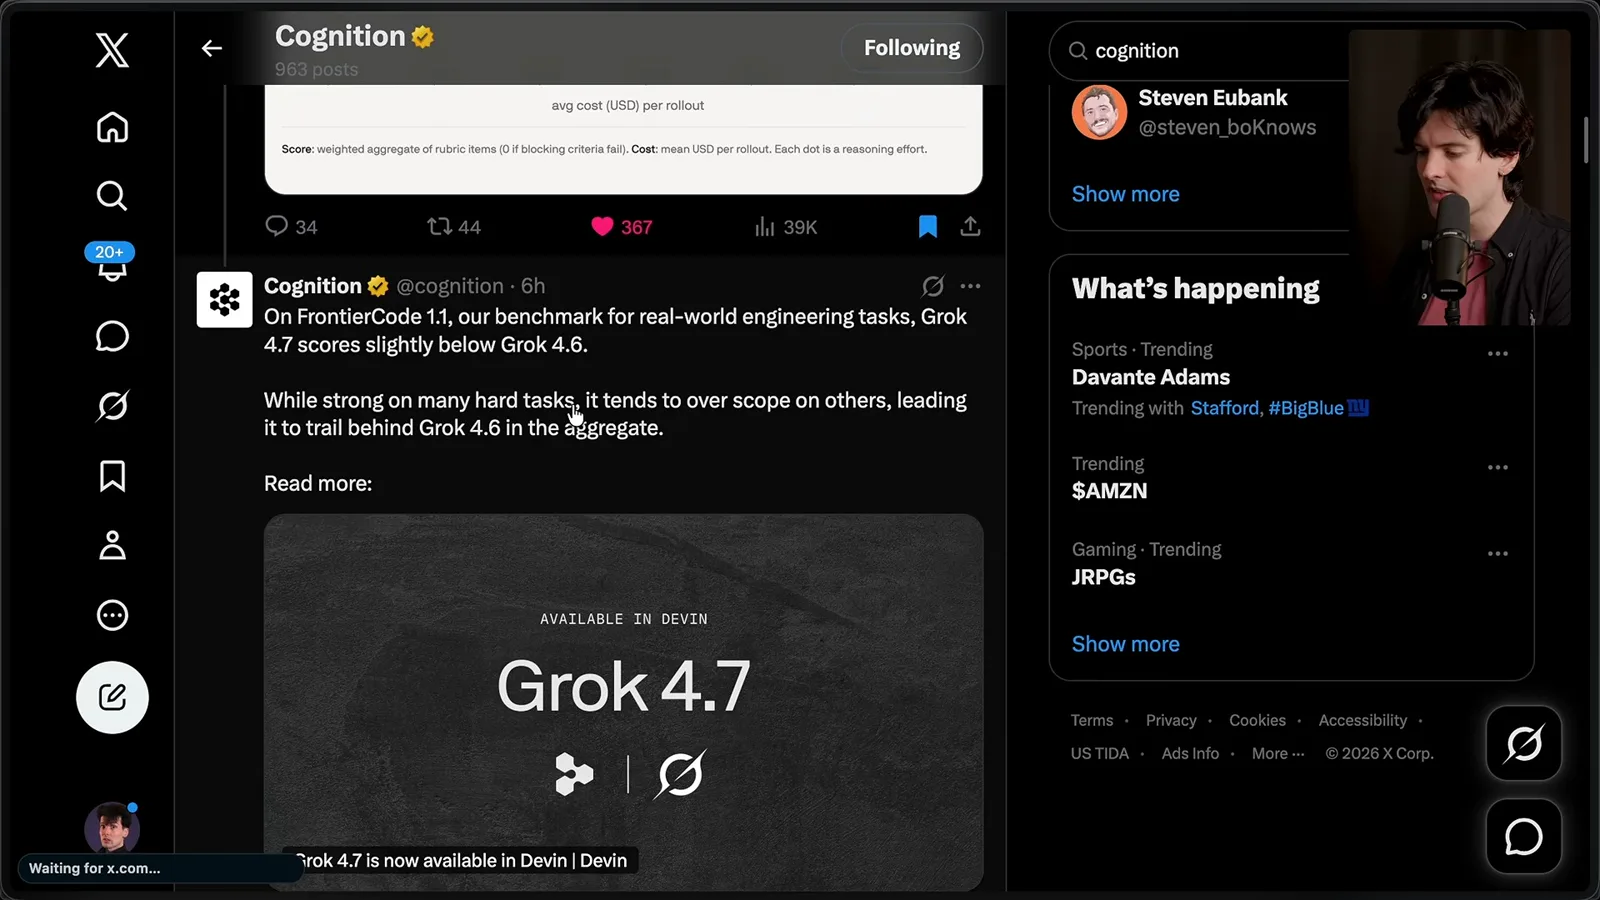
On FrontierCode, Cognition says Grok 4.7 trails 4.6 in aggregate and can over-scope some tasks even when it performs well on hard ones. This evaluation considers whether a change meets criteria for a real pull request, not merely whether some code executes. I also find this benchmark noisy across reasoning settings.
Artificial Analysis’s general index places Grok below the models I currently prefer, while its coding-agent index shows a smaller but visible gap. I interpret the difference partly as consistency over longer work. An aggregate score cannot directly quantify each user’s failure rate, so that interpretation should be tested on actual tasks.
I return to expense: the cited index shows about $3.74 per task for Grok 4.7 versus $3.26 for Astra in those configurations. Some observers suggested a cache issue; I suspect higher token use is important, but the video does not establish a complete causal breakdown for every workload.
My co-host Ben also reports that the experience can become costly. He says pricing rises for contexts above 200,000 tokens and for fast mode, and that approximately $40 of usage consumed 8% of a weekly limit on his $300 plan. This is one user’s report under the terms at the time, not a guaranteed current limit.
Another evaluation, AA Briefcase, shows a substantial improvement for Grok 4.7 and a competitive cost, even as the evaluator reports lower presentation quality than 4.6. This is a useful reminder that a model can improve on one measure and regress on another.
Design and unusual behavior
He criticizes selected visual examples and shows a reported repetition loop. He speculates about training changes without direct evidence of causation.
I look at front-end examples and strongly dislike several of the generated designs. That is a subjective assessment of a small sample, not proof that the model cannot produce an acceptable interface with different prompts, examples or iteration.
Musk had discussed delaying release to address a tendency to give up early or insufficiently check work. I speculate that changes aimed at longer, more rigorous work might relate to higher token use. That causal link is not established by the public comment alone.
I show a user’s example in which generated text falls into a repetitive loop, as well as an odd translation result. Both are reported examples of possible failure modes; they do not establish how often these failures occur or exactly why they happened.
Codebase investigation and game demo
His own model-judged test finds useful investigation behavior, while a game generation performs poorly in his assessment. He weighs those strengths against cost.
Despite my criticisms, I like that Grok can stay on a task, investigate and dig into details. I have seen it find things I thought other models missed. To examine that behavior, I asked several models to suggest improvements to the T3 Code codebase.
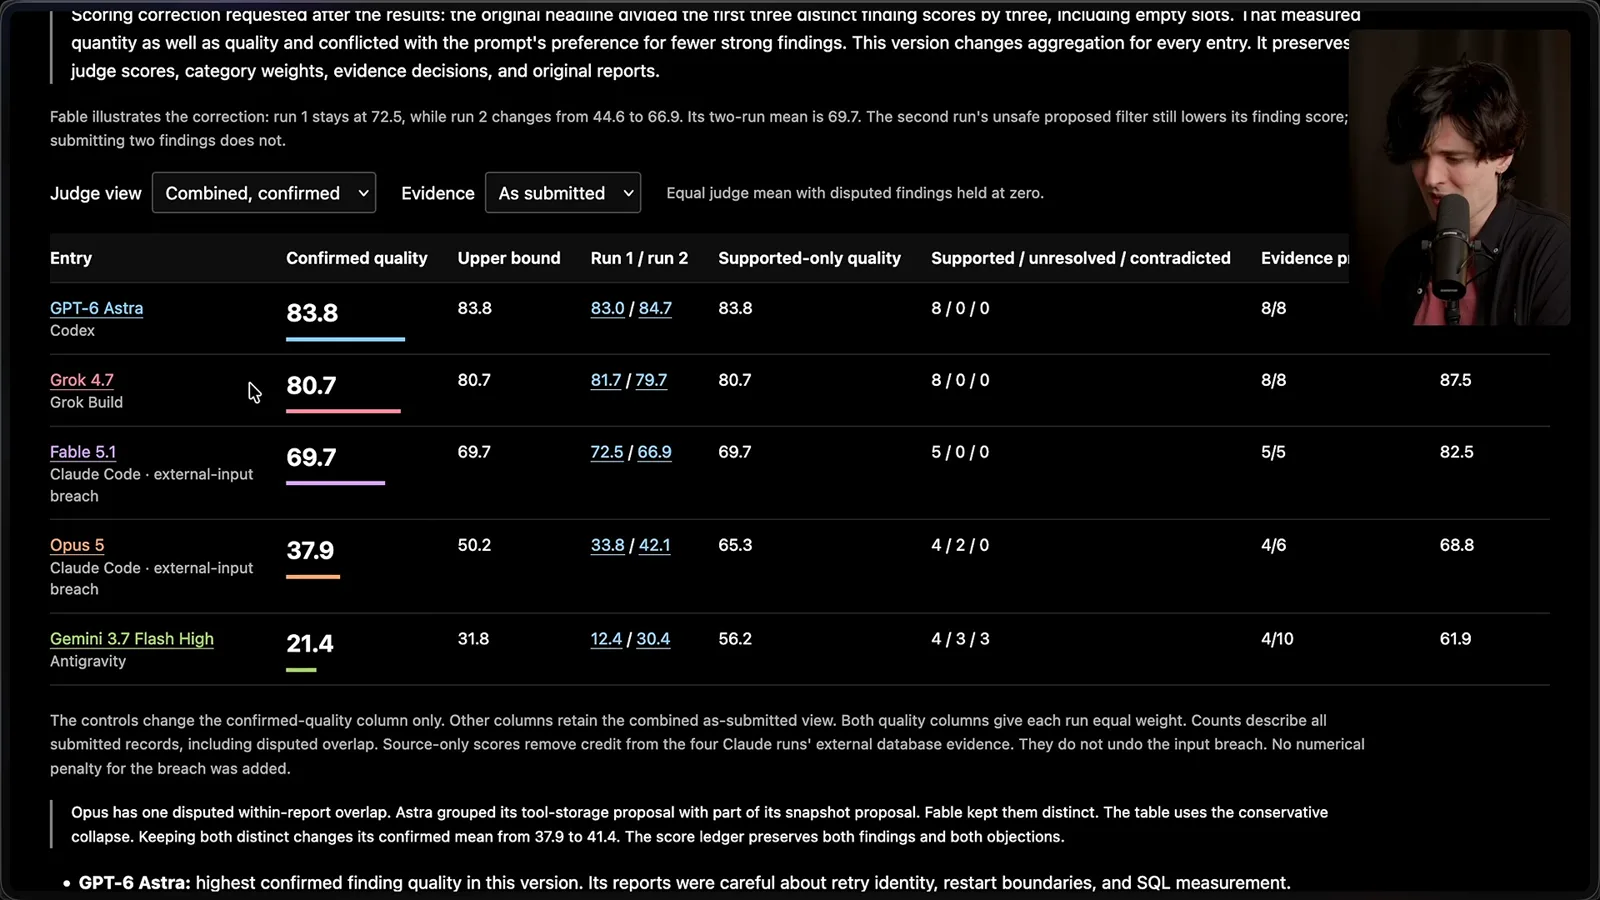
In my small experiment, Astra ranked first and Grok second, with eight supported suggestions each in the displayed table; Fable produced five. The results were judged by models, the scoring was revised, and the displayed table notes differences in external input handling. These limitations matter when interpreting the ranking.
Grok’s runs ranged from roughly comparable in cost to Astra or Fable to about twice as expensive in the worst case I saw. I suspect it sometimes spends a lot of effort verifying low-value details. More investigation can be useful, but its value depends on whether the additional findings justify the time and cost.
On my Fish Slop game prompt, the run took almost an hour and a half. My first result animated fish and the submarine backward; the version I show has awkward mouse tracking and a poor visual result in my judgment. This is one run, not an exhaustive test of game generation.
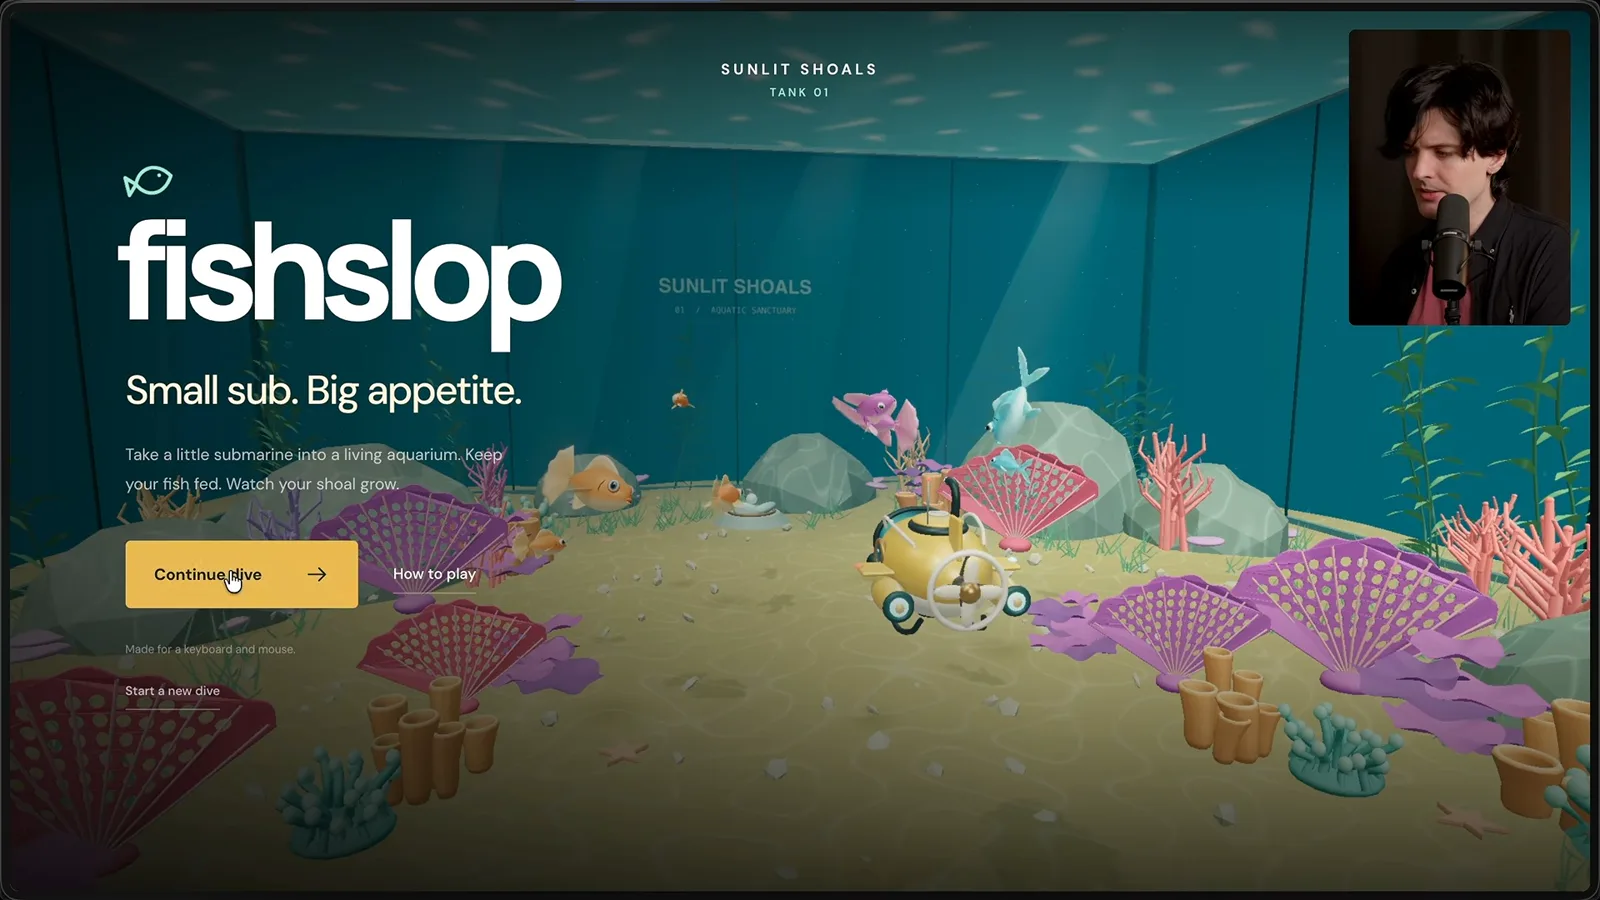
I compare it with an Astra-generated game made with the same prompt and environment, which I find much more convincing. Even with the prompt held constant, model settings and the randomness of generation limit what we can conclude from a single pair of examples.
My final assessment is mixed. I enjoy Grok’s thorough investigation and find some real work pleasant, but the costs and limits I encountered make it hard for me to recommend as my default at the time of filming. Others may value its particular strengths differently, and prices and subscriptions can change.
I regard this as a stepping stone and hope future versions improve efficiency and value. For now, I would compare it on the actual tasks that matter, including total cost and required human review, rather than choosing solely by a launch claim or a single benchmark.
Sur la même chaîne
 36:07EN
 Theo - t3․gg· 27 oct. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26 oct. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23 oct. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22 oct. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20 oct. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.
 31:47ENTheo - t3․gg· 18 oct. 2026Theo on Asking Agents for Outcomes and Building the Tools They NeedTheo Browne · Ping LabsA tool-call report, a troubleshooting playbook and connected data show how prompting can reshape product engineering.