En 30 secondes
In this May 2024 short, Matthew Berman discusses Microsoft Build and NVIDIA’s RTX AI announcements, including local model inference, developer tools and applications for games and creators. NVIDIA is his disclosed video partner. The company’s up-to-threefold performance figure applies to specific workloads and software, not every model or PC.
- 1Windows AI developmentBerman describes Microsoft’s AI assistant ambitions and NVIDIA’s collaboration on Windows. The presentation is a 2024 outlook rather than proof that a single model operated at every operating-system layer.
- 2A qualified inference speedupNVIDIA’s announced figure was up to 3× for selected LLM inference with ONNX Runtime, DirectML and the R555 driver, not a universal improvement.
- 3Developers, games and creatorsBerman highlights local model development tools, game performance and AI characters, and accelerated creative workflows. NVIDIA is his disclosed partner.
À retenir
- Microsoft discussed Windows Copilot Runtime and collaboration with NVIDIA on local AI development at Build 2024.
- NVIDIA reported up to 3× faster LLM inference with ONNX Runtime and DirectML using its R555 driver under specified conditions.
- AI Workbench, cuDNN and CUDA support model development and customization; performance depends on hardware and configuration.
- The video highlights AI-driven game characters and RTX-accelerated creative tools as potential applications.
Lire le texte remanié, chapitre par chapitre
Microsoft Build and Windows AI
Berman introduces Microsoft’s AI assistant plans and NVIDIA’s Windows collaboration. The video is an NVIDIA partnership.
Microsoft’s 2024 Build announcements point toward AI assistants integrated more closely into Windows. Microsoft described Windows Copilot Runtime and developer capabilities, including collaboration with NVIDIA on RTX systems. My description of GPT-4 across every operating-system layer is a broad vision, not proof that one model ran everywhere. NVIDIA partnered with me on this video.
Local models and development tools
He discusses the announced inference speedup and tools for local model development. The speed claim is workload-specific.
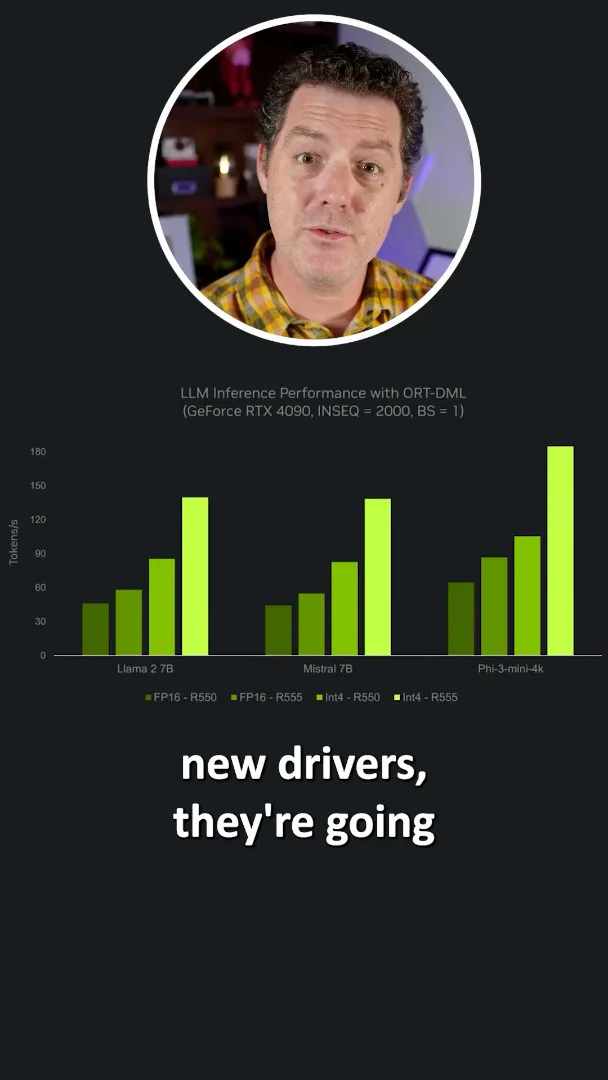
For local language models, NVIDIA announced that its R555 driver could deliver up to three times faster inference with ONNX Runtime and DirectML in selected configurations. That is a company performance claim with specific model, hardware and software conditions; it does not mean every model becomes three times faster. NVIDIA also highlighted AI Workbench, cuDNN and CUDA on Windows Subsystem for Linux for development and fine-tuning.
Games and creative applications
Berman highlights game performance, AI-driven NPCs and creator software. Actual benefits vary by application and hardware.
For games, I point to RTX performance improvements and the possibility of AI-driven non-player characters. I also highlight RTX-accelerated AI features in creator applications such as Adobe Premiere and DaVinci Resolve. These are examples of workflows NVIDIA and its partners were promoting in 2024; the available features and actual speedups depend on the software and hardware.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.