En 30 secondes
Matthew Berman discusses GameNGen, a research prototype from Google Research, Tel Aviv University and Google DeepMind that learns from recorded DOOM gameplay and generates interactive frames with a diffusion model. The paper reports real-time play at over 20 frames per second on a TPU, while noting limited context and imperfect state tracking. Berman extrapolates to personalized games, other media and software; those longer-term outcomes are predictions, not capabilities established by the experiment.
- 1From procedural rules to generationBerman contrasts traditional and procedurally generated games with a proposed future of generated interactive environments. GameNGen itself learns from an existing coded game.
- 2A playable neural simulationThe researchers show DOOM-like gameplay generated by a model instead of the original game engine at inference time.
- 3Learning from recorded playAn agent plays DOOM and its sessions provide training data for a diffusion model conditioned on prior frames and actions.
- 4Game state in pixelsThe model can approximate health, ammunition and interactions, but does not reliably maintain a complete explicit game state.
- 5Short memory and artifactsThe paper describes just over three seconds of history, imperfect simulation and gaps in the training agent’s exploration.
À retenir
- GameNGen simulates a version of 1993 DOOM by predicting frames conditioned on recent frames and player actions.
- Researchers first recorded an agent playing the original game, then trained a diffusion model on its gameplay.
- The initial paper reported interactive simulation at over 20 frames per second on one TPU.
- The model sees a little over three seconds of history and can produce inconsistent state or visual artifacts.
- Prompt-created games, replacement of developers and realistic simulations of the world are speculative extrapolations.
Lire le texte remanié, chapitre par chapitre
The idea of generated games
Berman introduces a vision of games produced interactively by AI. He contrasts conventional games, procedural generation and video synthesis.
NVIDIA CEO Jensen Huang has described a future in which game pixels are generated. Imagine a game created interactively for a particular player. In August 2024, a research project called GameNGen offers an early demonstration of part of that idea: it simulates the classic game DOOM using a neural model. This is an experiment based on an existing game, not a system that can already create any game on demand.
DOOM, released in 1993, is a landmark game and a familiar target for people who enjoy getting software to run on unusual devices. I have seen examples on phones, price checkers and even a pregnancy test. Its familiar appearance makes the researchers’ simulated version easy to compare with the original.
Conventional games use code and authored assets to implement rules and display scenes. Procedural generation adds algorithms that create levels or worlds from rules, as in games such as Diablo and No Man’s Sky. I see learned frame generation as a possible next step, although conventional games can also combine authored and procedural elements.
Text-to-image and text-to-video models show how a model can produce visual content from a prompt. I have been excited by OpenAI’s Sora demonstrations and the possibility of more consistent video. But a video that looks game-like is not automatically interactive, and examples do not establish that its physics are always accurate.
How GameNGen simulates DOOM
The research model predicts frames based on previous images and actions. Training relies on recordings from an agent playing the original game.
The paper “Diffusion Models Are Real-Time Game Engines” presents GameNGen. The researchers show a playable simulation of DOOM in which the neural model generates successive views in response to actions. Enemies, corridors and interface elements are synthesized rather than drawn by the original DOOM renderer during this simulation.
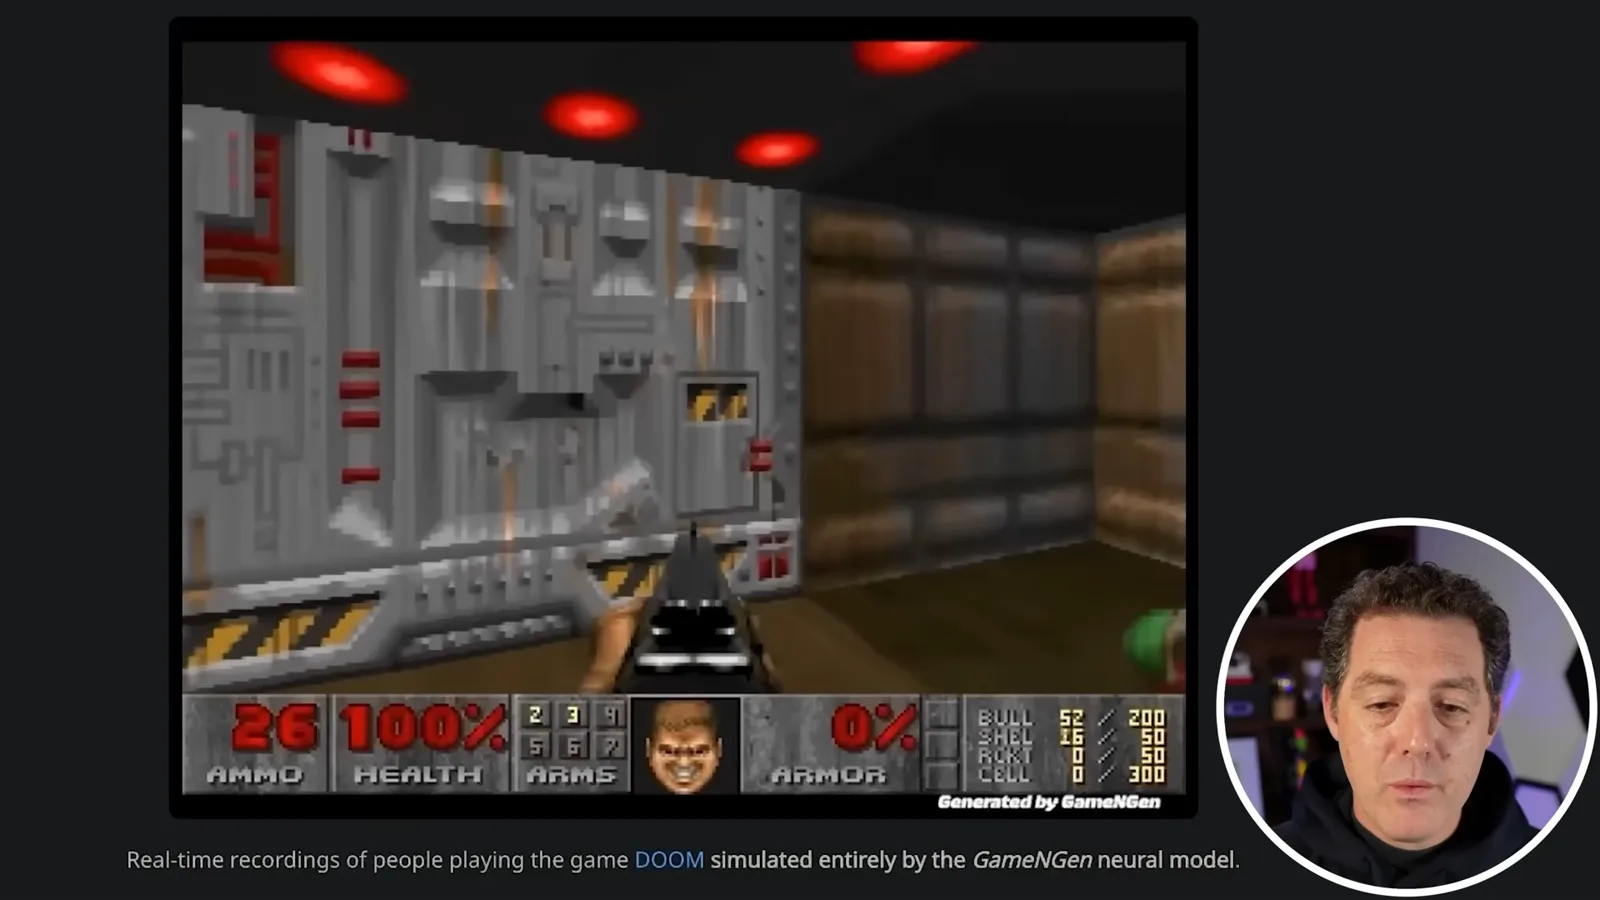
The 2024 paper reports that the system can simulate the game at over 20 frames per second on a single TPU, a processor specialized for machine learning. That is a result for the tested setup, not evidence that a modern commercial game can run the same way on a typical consumer device.
At each step, the model predicts a new frame using a sequence of earlier frames and actions. Training has two phases: a reinforcement-learning agent learns to play the original coded game and its sessions are recorded; a diffusion model then learns to generate the next frame from those observations and actions. It inherits information from the game and human-built training pipeline.
Potential applications and the research result
Berman speculates about tailored media, software and simulated worlds. He then examines the paper’s findings and possible future game modifications.
I imagine a future in which a person describes a game or show and receives an experience tailored to them. That could change how content is created and consumed. GameNGen does not demonstrate such unrestricted text-to-game creation; it demonstrates an interactive simulation learned from a particular game.
I also speculate that systems like these could reshape programming and perhaps reduce the need for some development work. Extending the idea still further, one could imagine simulating the real world, raising questions reminiscent of The Matrix and simulation theory. These are my forecasts and speculations, not conclusions the DOOM experiment proves.
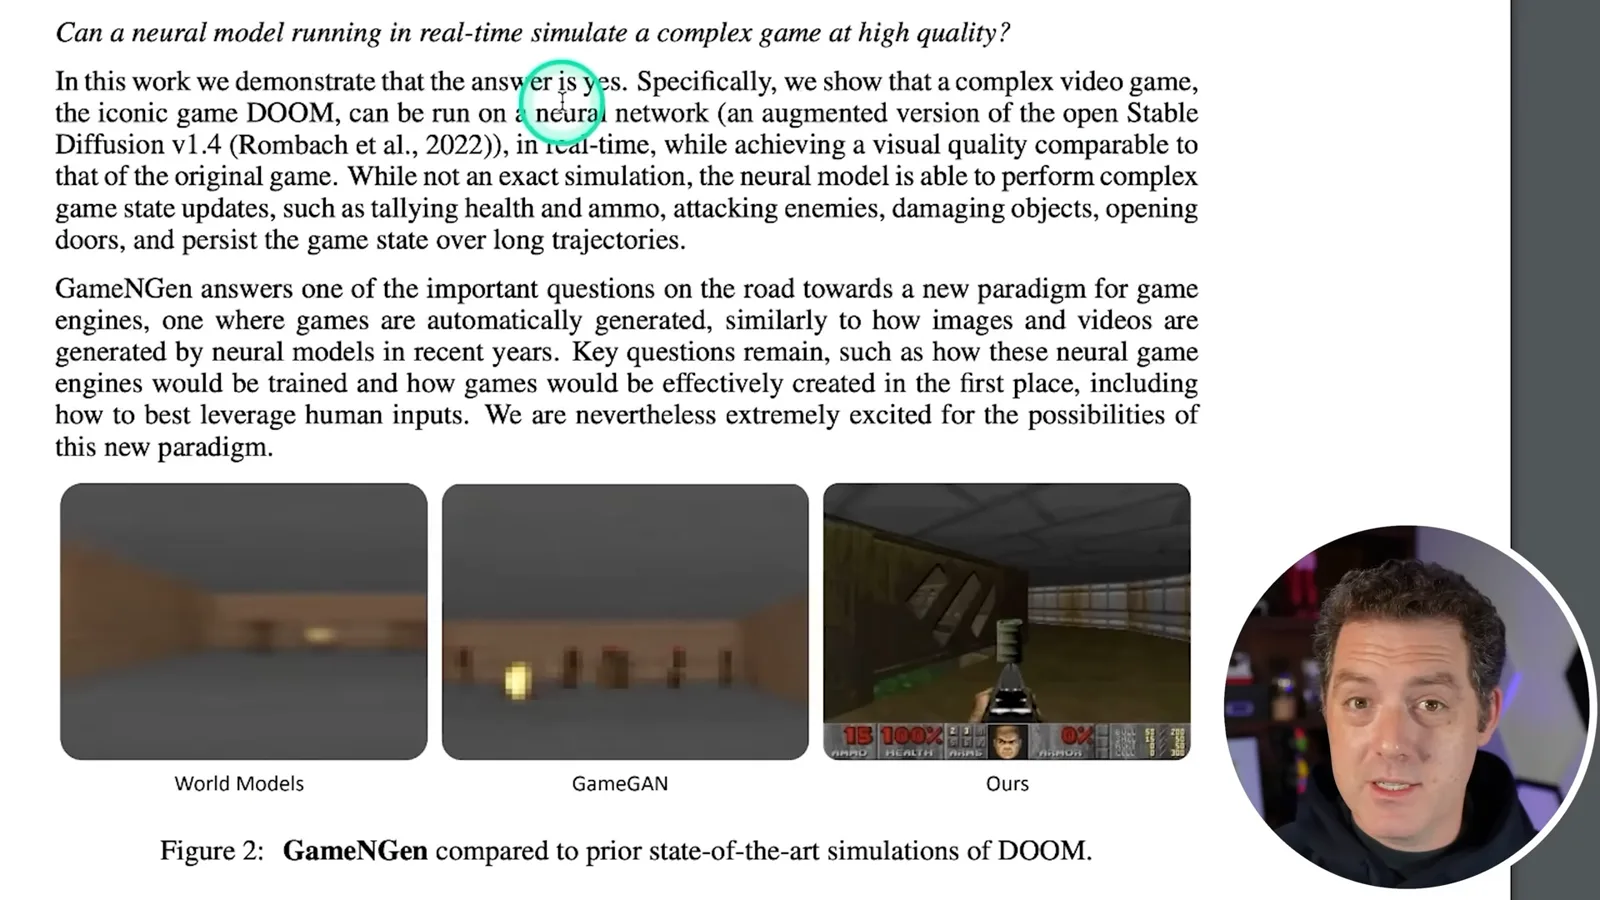
The researchers used an augmented Stable Diffusion 1.4 model. Their simulation can approximate updates such as ammunition and health counters, shooting enemies and opening doors, but it is not an exact copy. Some state remains visible in the generated pixels, while the model infers other information from recent context; the paper does not demonstrate a conventional persistent game-state database.
The authors frame GameNGen as a proof of concept for an interactive game represented by model weights. They suggest that modifying existing games, creating a new level from frames or a character from example images could be shorter-term possibilities. Those applications were proposed future work, not features established by this DOOM demonstration.
Limitations and future predictions
The system has a short context and imperfect state tracking. Berman closes with predictions about generated games, interfaces and computing.
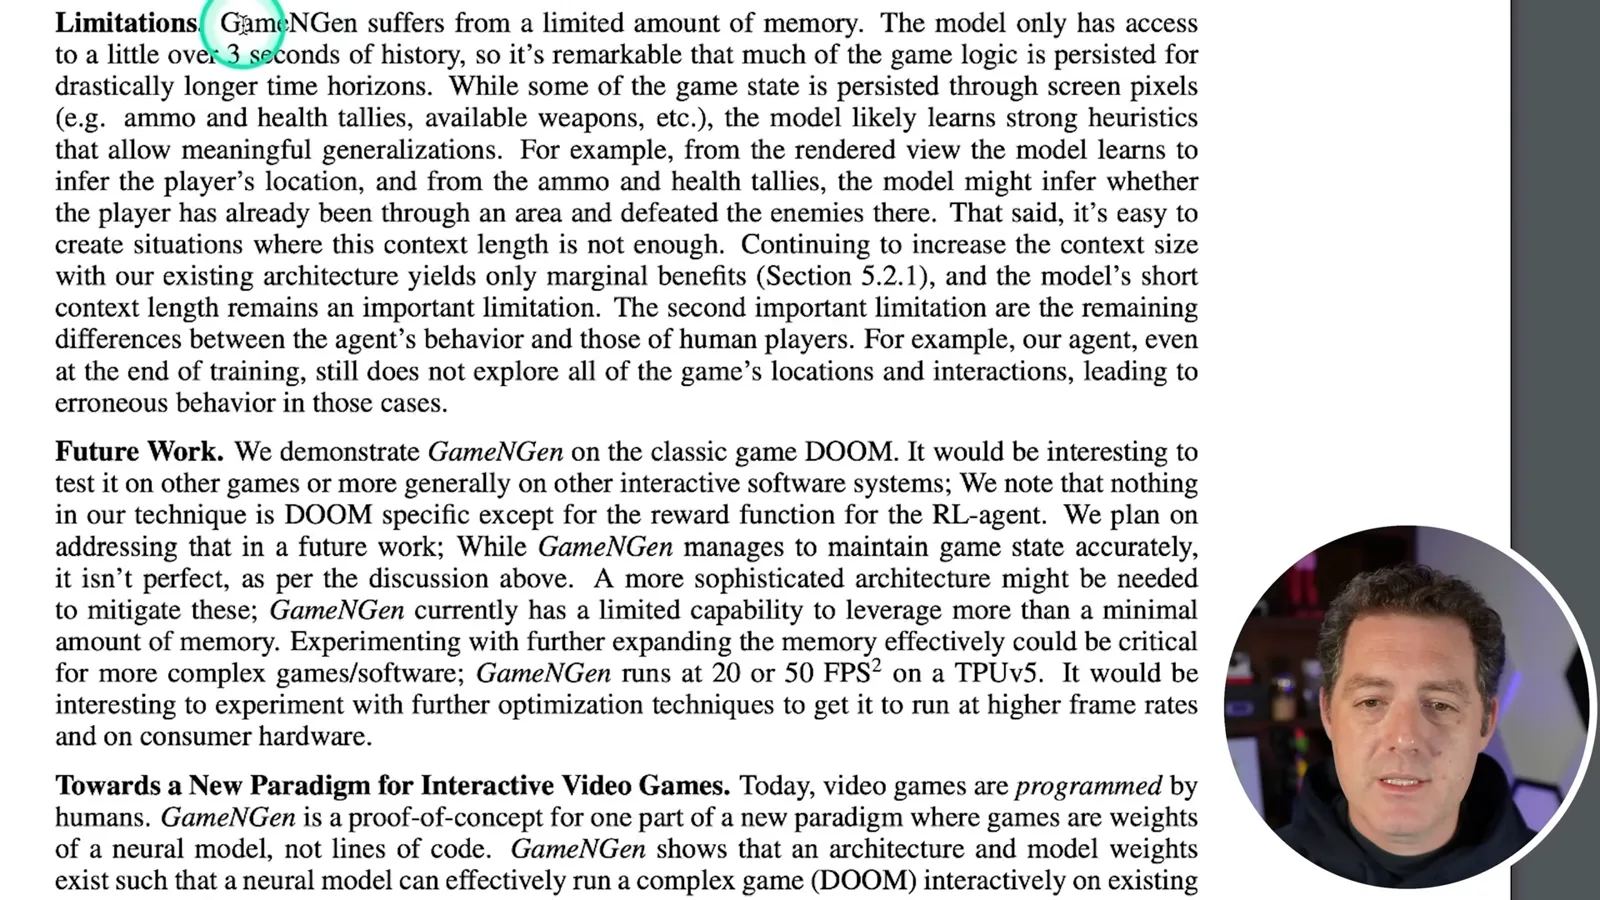
The paper identifies a major limitation: the model has access to a little over three seconds of history. Some state can persist in the visible display, but once an event is outside that context the model can make incorrect guesses. The training agent also did not explore every location and interaction, which can produce errors in unfamiliar situations.
There are visible artifacts and inconsistencies, including flickering facial details and incorrect counters. Longer memory, better stability, more data and compute might help, though simply generating a new game does not remove the need for consistent rules and state. These remain research challenges rather than solved engineering problems.
My prediction is that generated experiences will eventually reach games, movies, music and software interfaces. I imagine asking AI for the interface and data I need rather than relying on conventional applications or an operating system. That is a broad vision for the future; GameNGen’s measured result is the narrower DOOM simulation described in the paper.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.