En 30 secondes
Anthropic product lead Jess Yan joins Peter Yang to explain Claude Managed Agents and demonstrate an agent that analyzes grocery data. They discuss tools and permissions, traces, self-correction and evaluations, internal product-management workflows, and a gradual approach to enterprise adoption. The episode includes a paid Riverside sponsor segment; product claims and predictions are the speakers’ perspectives.
- 1From prompt loops to agent harnessesJess describes a harness as the scaffolding that lets a model use tools, access memory, and determine when to request human input.
- 2Managed infrastructure for long-running tasksClaude Managed Agents combines a prebuilt harness with infrastructure for delegated work, according to its product lead.
- 3A grocery-data analysis demoA configured agent receives a schema and task instructions, uses tools, and produces HTML reports on a dataset.
- 4Evaluation and tracesJess discusses replaying interactions, pass/fail and scored tests, trigger checks, and built-in review loops.
- 5How a product lead works with agentsShe uses codebase access, scheduled summaries, and ad hoc research to follow the product and help customers.
- 6Start adoption with individualsJess recommends templates that help employees extend their capabilities before scaling to complex processes.
- 7The future of delegated workJess predicts more long-running and specialized agents, while Peter questions how durable standalone products will be.
À retenir
- An agent harness connects a model to tools, memory, permissions, and human input.
- Jess demonstrates a configured agent that analyzes grocery data and generates reports; results and predictive models need independent validation.
- Agent evaluation can combine test cases, scored judgments, action-trigger checks, and review of execution traces.
- Internal agents help Jess follow code changes, summarize customer activity, and prepare for conversations.
- She recommends empowering individuals with useful templates before automating complex multi-team workflows.
Lire le texte remanié, chapitre par chapitre
Defining agents and harnesses
Models, tools, permissions, memory, and human steering.
Anthropic product lead Jess Yan joins Peter Yang to discuss agents that can run longer tasks with access to tools and data. Jess presents Claude Managed Agents from the perspective of the team building it. The episode also contains a separate paid sponsor segment for Riverside.
Jess describes an evolution from simple prompt-and-response loops toward agents that can use tools, interact with external systems, and run longer. A harness is the surrounding scaffolding that gives a model access to tools and memory and determines when to ask a person for input. As capabilities and access expand, she says, permissions, observability, and steering become more important.
Managed agents and the demo
Jess configures an agent for grocery-data analysis.
She characterizes Claude Managed Agents as a prebuilt harness and supporting infrastructure for delegating complex tasks. Rather than treating the model alone as the whole system, she argues that model behavior must be evaluated together with the environment and harness in which it operates. This is her view as the product lead.
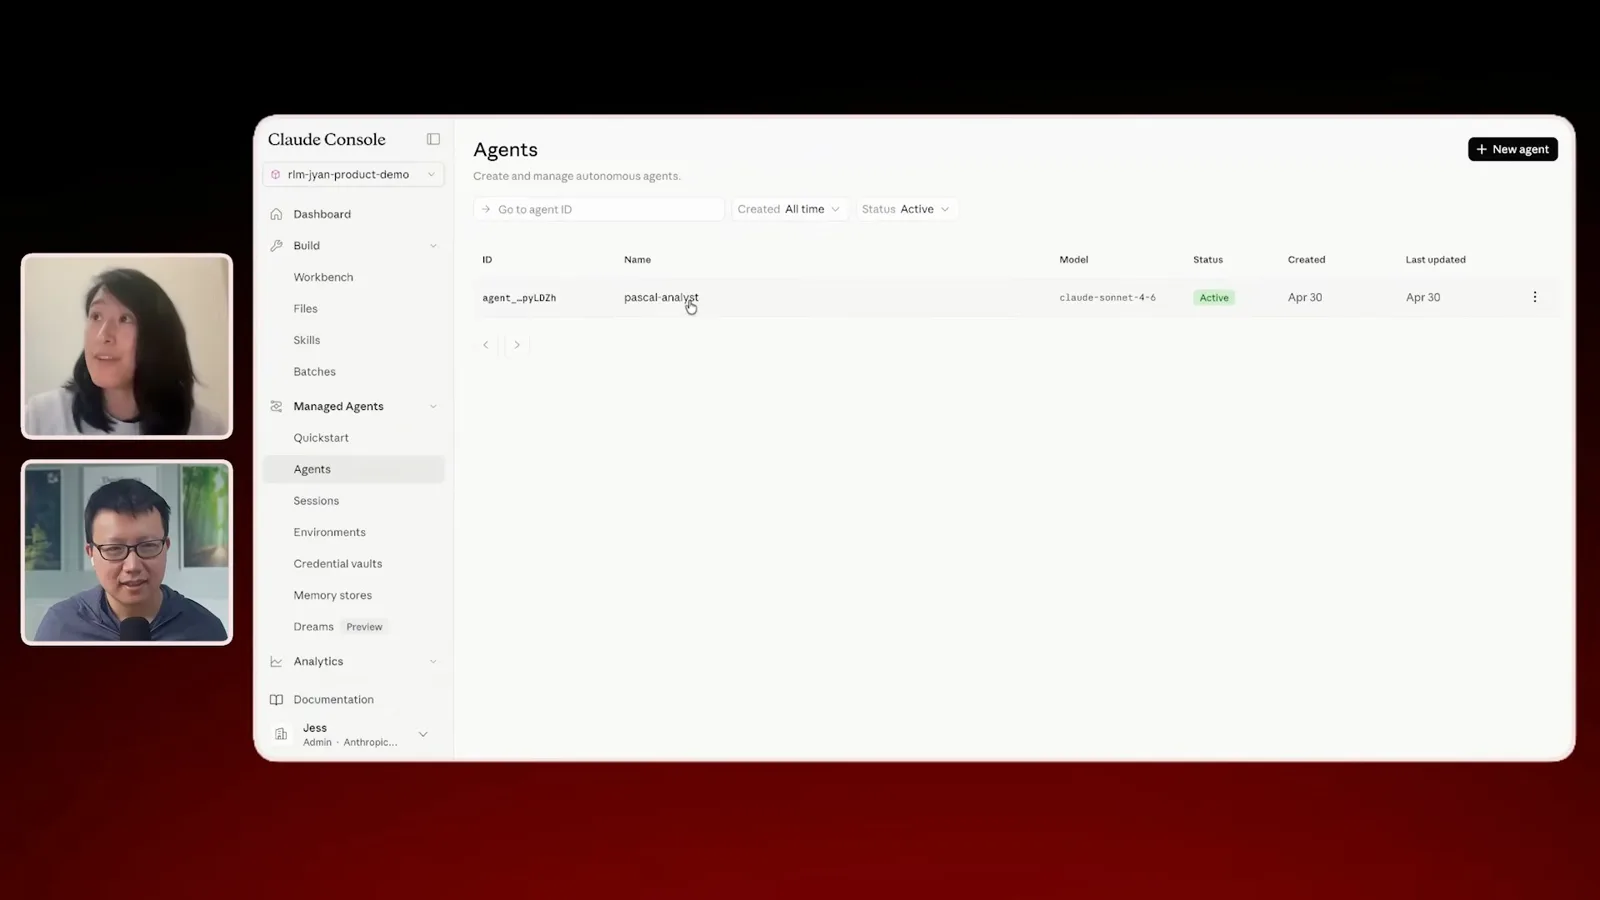
In a demonstration, Jess opens a preconfigured data-analysis agent. It has a selected model, behavioral instructions, filesystem tools, and configurable permissions; skills can also be attached. For this example, she supplies the schema and instructions for analyzing a large grocery dataset, then lets the agent use its tools and produce HTML reports.
Instructions, reports, and recovery
Schema, execution steps, trace review, and output artifacts.
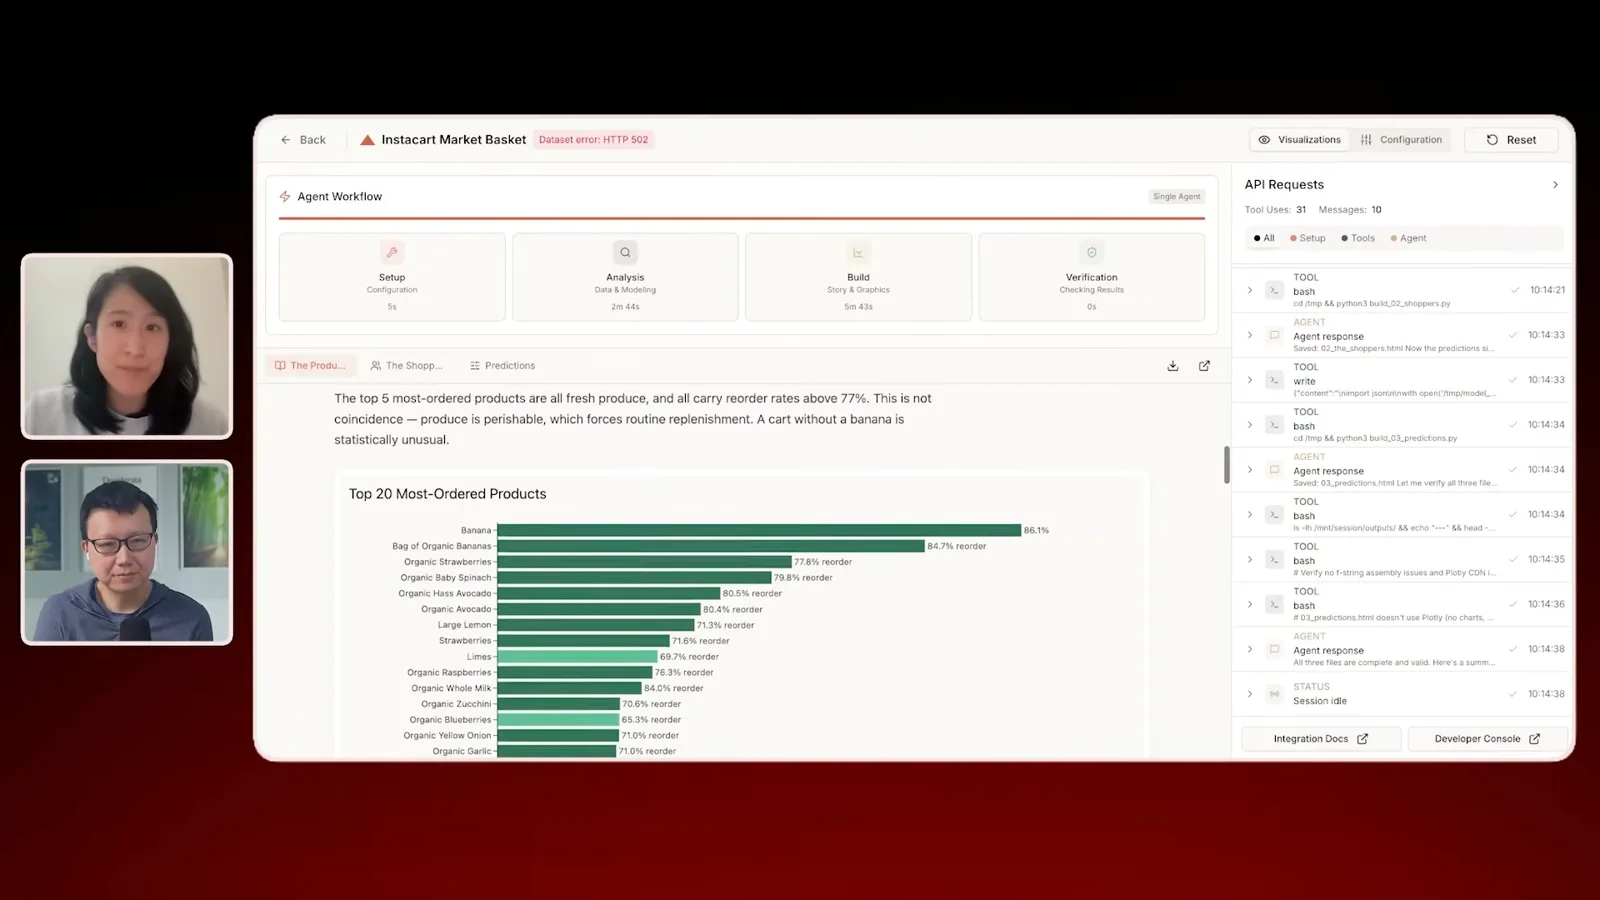
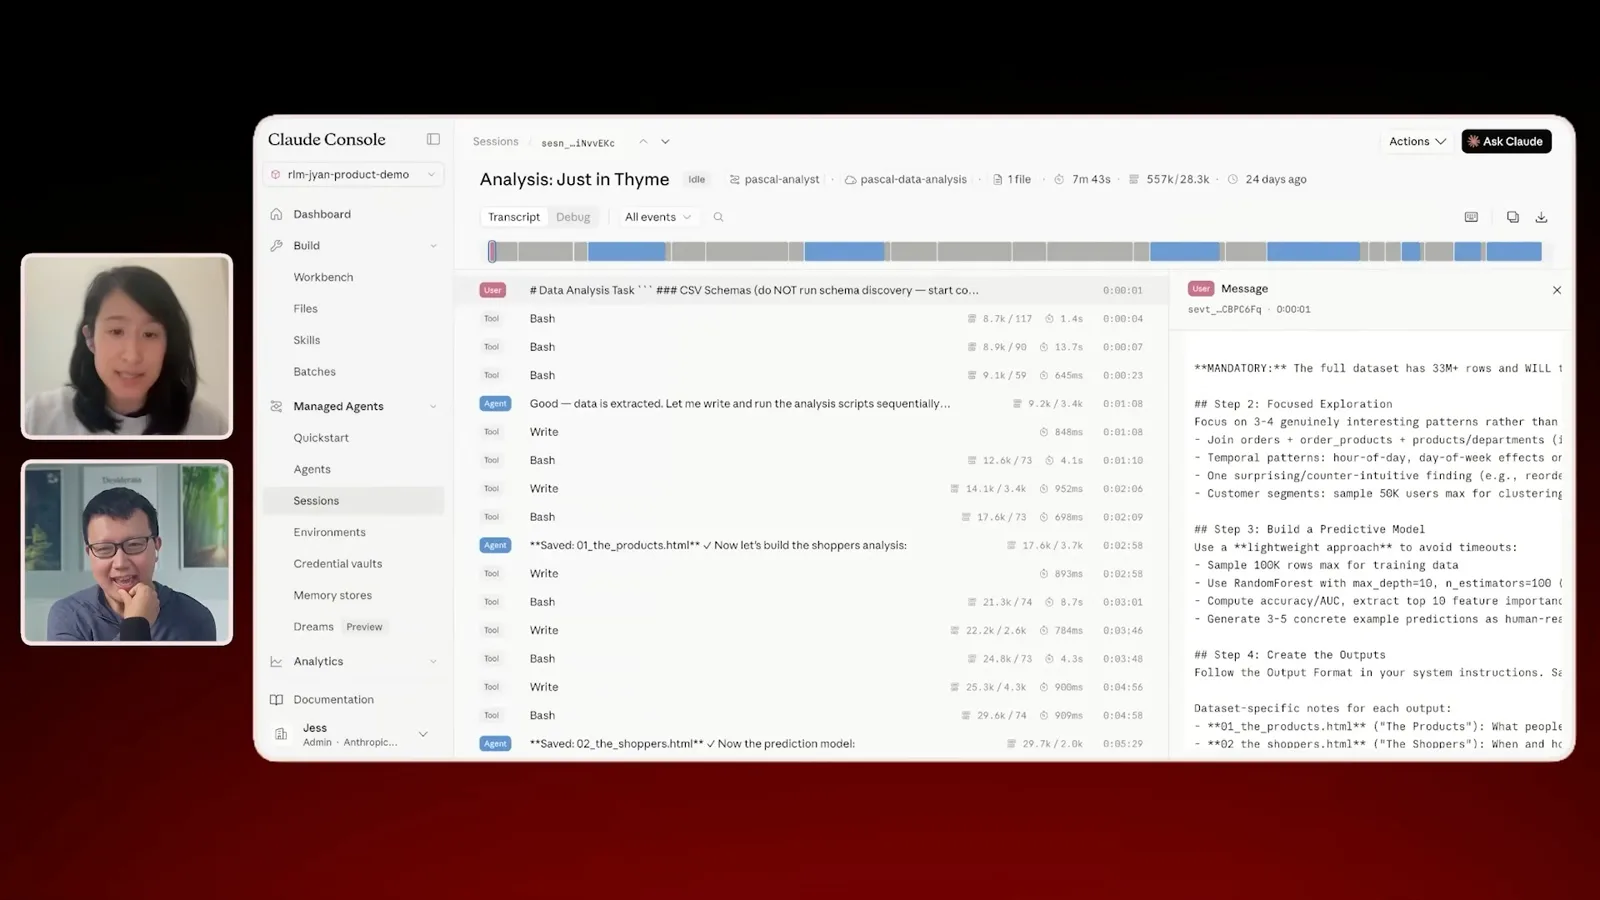
The output includes product patterns, shopper analysis, and an example predictive model for customer return. Jess says providing schema and a sequence of steps helps produce a more predictable result. The console exposes actions and session history, and she describes a debugging agent that can inspect the trace. A generated chart or prediction is not by itself proof of accuracy: data quality, methodology, and performance need separate validation.
Evaluate an agent
Tests, scoring, triggers, and self-review.
Evaluation becomes harder as agent tasks grow more complex. Jess discusses fixed test cases, replaying multi-step interactions, comparing versions, binary checks, scored judgments, and checking whether skills or actions trigger when expected. She also describes agents reviewing outputs during a run. Automated review can be useful, but it does not guarantee a correct result or replace independent testing.
The speakers consider how instructions change when users specify a desired outcome instead of every intermediate format. Jess suggests giving the agent an example of quality or a target score and letting it iterate. Clear success criteria still matter, as do limits on what the agent may access and do.
Agents inside Anthropic
Codebase exploration, customer summaries, and product work.
For her own product-management work, Jess says codebase access helps her track merged and deployed pull requests, understand implementation, prototype, and support customers. She uses scheduled activity summaries and ad hoc research, and describes agents summarizing customer Slack channels. She sees current context and proactive triggers as important, while direct customer conversations remain part of her work.
A temporary waitlist agent
Jess describes automating a short-lived prioritization workflow.
Jess describes a temporary agent for a feature waitlist: it cleans invalid or duplicate entries and helps prioritize organizations for feedback and invitations. Because the need was expected to last only a few weeks, she preferred a task-specific agent to building a polished permanent product. Such workflows still require appropriate access controls and review of selection criteria.
Enterprise adoption
Begin with individual capability and reusable templates.
For enterprise adoption, Jess recommends beginning with individual employees: give them examples or templates and let them adapt agents to extend their own capabilities. Organizations can then learn from that work before attempting large, cross-team automation. She and Peter discuss early user feedback and more formal evaluations as usage grows.
Where agents may go next
Overnight work and increasingly specialized products.
Looking ahead, Jess expects longer-running agents to increase the amount of work people can delegate and anticipates increasingly specialized products. Peter questions whether a standalone application can remain differentiated when users can create their own skills. They agree that agents need to fit the places and workflows where people already work. These are forecasts and product opinions, not guarantees.
Sur la même chaîne
 46:40EN
 Peter Yang· 8 nov. 2026Podcast · 2 voixAshley Alexander: How AI Helps Me Care for My Parents With CancerInvité : Ashley Alexander · Anime : Peter YangA caregiver uses AI to prepare for appointments, organize records and ask better questions—while keeping doctors at the center of treatment.
 17:50ENPeter Yang· 4 nov. 2026PodcastPeter Yang’s Five Steps for Using AI to Help Care for His MotherYang uses a shared care brief and organized records to navigate appointments, while making time for family.
 15:03ENPeter Yang· 3 nov. 2026PodcastHow Peter Yang Used an AI Phone Agent to Negotiate His Internet BillAn AI call negotiated a lower price and faster service, but Yang still had to approve the change himself.
 33:09ENPeter Yang· 1 nov. 2026Podcast · 2 voixJaclyn Konzelmann: When AI Can Build More, Choose What Deserves to ExistInvité : Jaclyn Konzelmann · Anime : Peter YangGoogle Labs pairs short strategy documents with prototypes, user co-creation and lessons from experiments that end.
 13:05ENPeter Yang· 28 oct. 2026PodcastPeter Yang Tests Genie 4: Convincing Worlds, Unfinished GameplayFive live demonstrations show scenes that respond to prompts and sound, alongside inconsistent actions and limited game mechanics.
 1:06ENPeter Yang· 26 oct. 2026PodcastPeter Yang on Setting Up Payroll for a One-Person BusinessIn a paid partnership, Yang describes the paperwork he encountered and a payroll product integrated with a business account.