En 30 secondes
In March 2025, Matthew Berman tests Inception’s Mercury Coder playground and discusses diffusion language models, coding speed and possible applications. The reported figures depend on model, hardware and workload; faster generation does not itself establish better reasoning or a tenfold cost reduction. Earlier diffusion language-model research existed before Mercury. The video contains a GrowthSchool sponsorship.
- 1Coarse-to-fine generationBerman contrasts sequential autoregressive decoding with iterative parallel refinement. Text diffusion is analogous to image diffusion but operates on discrete text representations.
- 2Speed in contextInception reports over 1,000 tokens per second on H100 for a stated configuration; this is not a guarantee for all Mercury variants or tasks.
- 3Playground demosThe host tries a particle animation, a bigram model and a Snake example; these simple demonstrations do not assess production reliability.
- 4Speed versus qualityThe displayed Artificial Analysis chart compares specific early-2025 models and tasks, with Mini and Small showing different speeds and scores.
- 5Reasoning claims need testsIterative refinement does not itself prove fewer hallucinations or better reasoning than autoregressive models.
- 6Earlier diffusion researchLLaDA was a trained 8B diffusion language model with released research code before this video, contrary to the claim that the earlier paper had no working model.
À retenir
- Diffusion language models can refine multiple text positions iteratively, whereas conventional autoregressive decoding proceeds token by token.
- Inception reported over 1,000 output tokens per second on NVIDIA H100 hardware for Mercury Coder in its stated setup; speeds vary by model and workload.
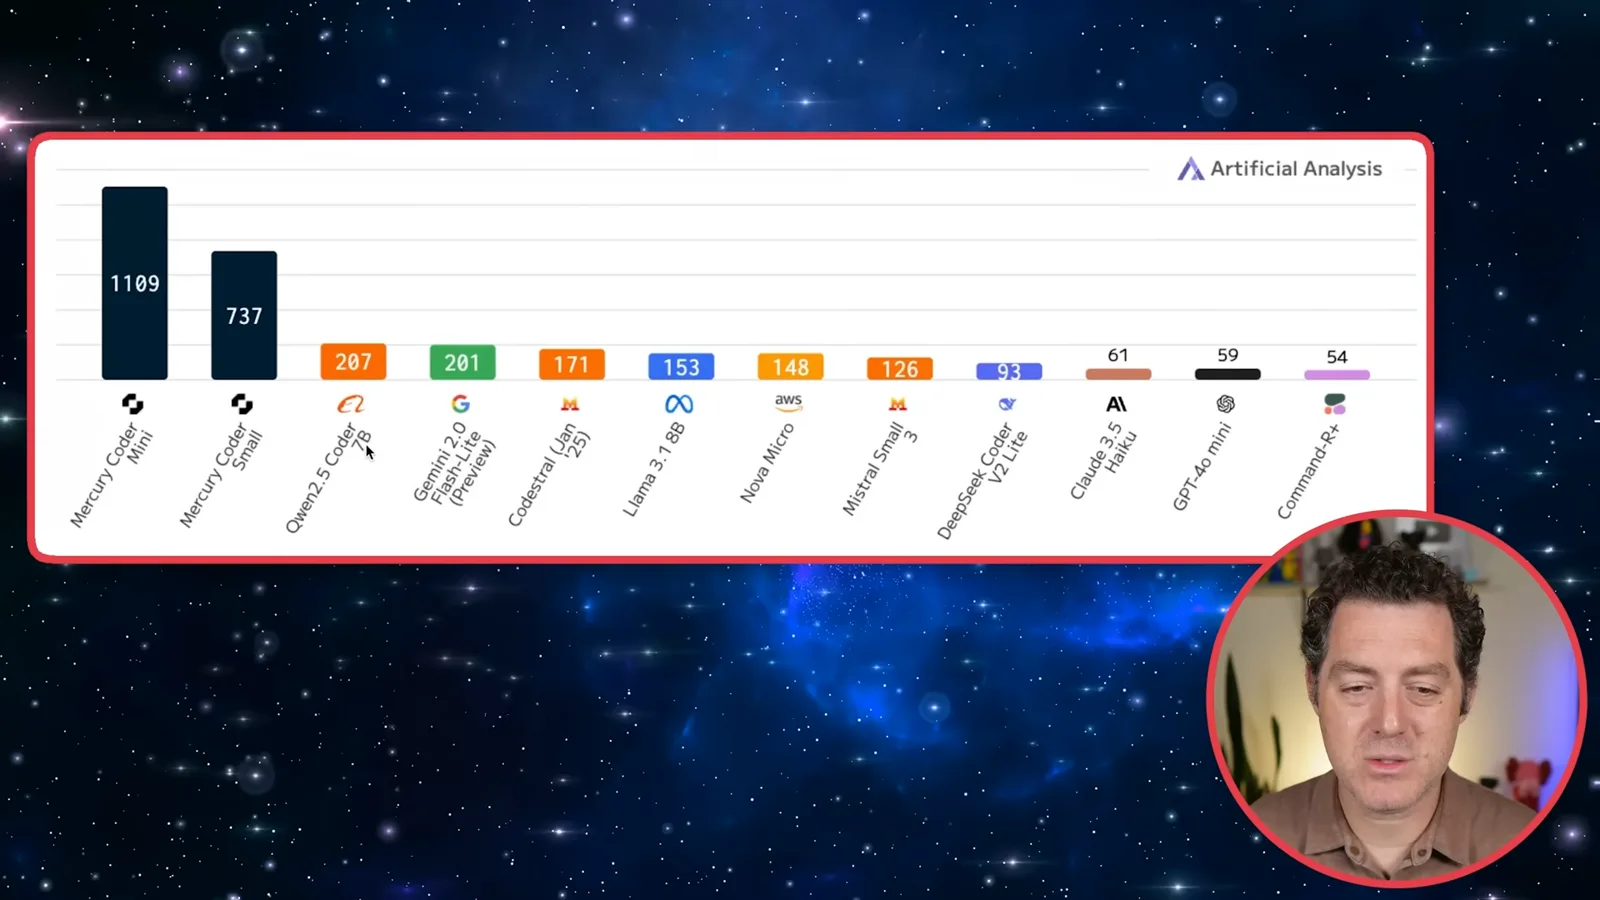
- The displayed historical chart shows Mercury Coder Mini at about 1,109 tokens per second and Small at about 737.
- A fast demo or a benchmark comparison does not establish universal coding quality, lower hallucination rates or a tenfold reduction in end-to-end cost.
- The 2025 LLaDA paper had already described a trained diffusion language model before Mercury’s commercial-scale launch.
- The video’s local-device and test-time-compute benefits are possibilities requiring implementation and measurement, not demonstrated outcomes.
Lire le texte remanié, chapitre par chapitre
How Mercury generates text
Berman introduces diffusion and compares it with sequential generation. The article qualifies the first-of-its-kind and speed claims.
Inception Labs has introduced Mercury Coder, a diffusion-based language model for code. I am excited by the company’s speed claims and its different generation method. The video’s “world’s first diffusion LLM” phrasing is too broad: earlier research included trained diffusion language models, while Inception described Mercury as commercial-scale.
A conventional autoregressive model typically generates the next token conditioned on the prior sequence. A diffusion language model instead can work from a corrupted or masked representation and update multiple text positions over several refinement steps. That does not mean the answer is correct in a single instant, and implementations may generate in blocks rather than one entire response at once.
I compare this with image diffusion, which iteratively transforms noise into an image rather than drawing one pixel at a time. The analogy helps illustrate coarse-to-fine generation, though discrete text models use representations and procedures that differ from continuous image generation.
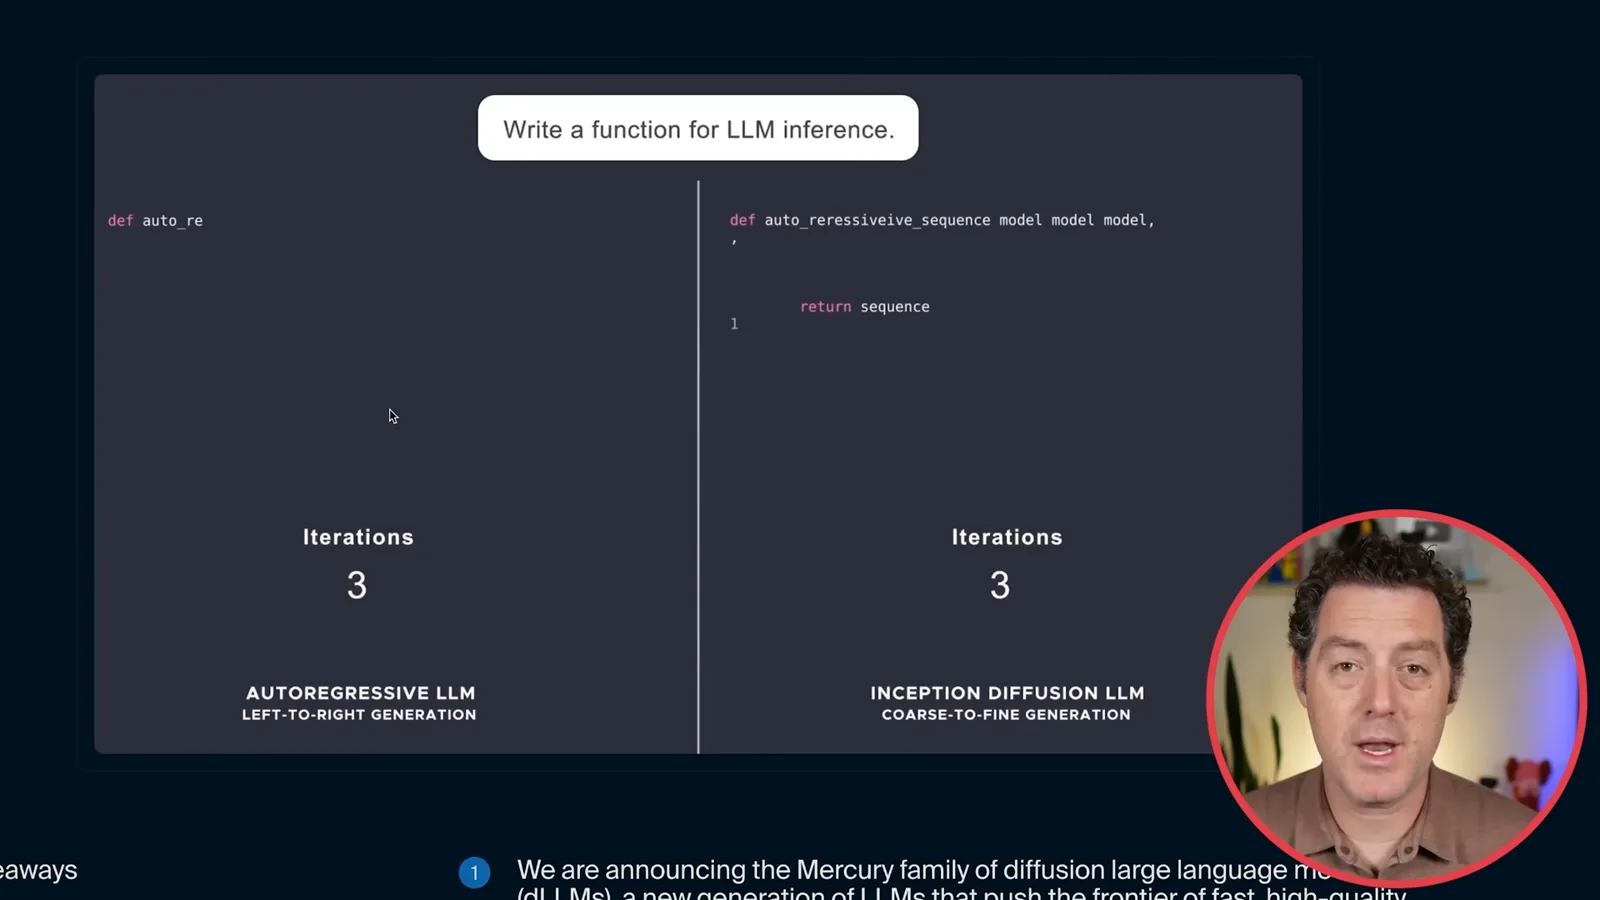
Inception’s animation contrasts sequential output with parallel refinement of a code response. I discuss 14 versus 75 illustrated iterations, but those are properties of the example, not a general ratio for all inputs or deployments. The company’s description and animation are illustrative rather than independent measurements.
I think faster generation could make coding and test-time computation feel more responsive. Yet token throughput is only part of total latency: prompt processing, network, tool calls, model quality, task length and retries all matter. More generated tokens or refinement steps do not automatically produce better answers.
Inception reported Mercury Coder running at over 1,000 output tokens per second on NVIDIA H100 hardware in its stated setup, and described a speedup of up to 10 times against selected speed-optimized frontier models. H100 is a commercially available accelerator, not custom hardware made for Mercury. These are historical, configuration-specific comparisons.
Coding demos and sponsor
He tries simple coding prompts in the playground. The video includes a GrowthSchool-sponsored training promotion.
In the playground I ask for a particle animation that follows the mouse, with controls for size, speed and color. The resulting simple demo responds to the controls. I then request a Python bigram model and inspect the code; neither example establishes reliability on a large software project.
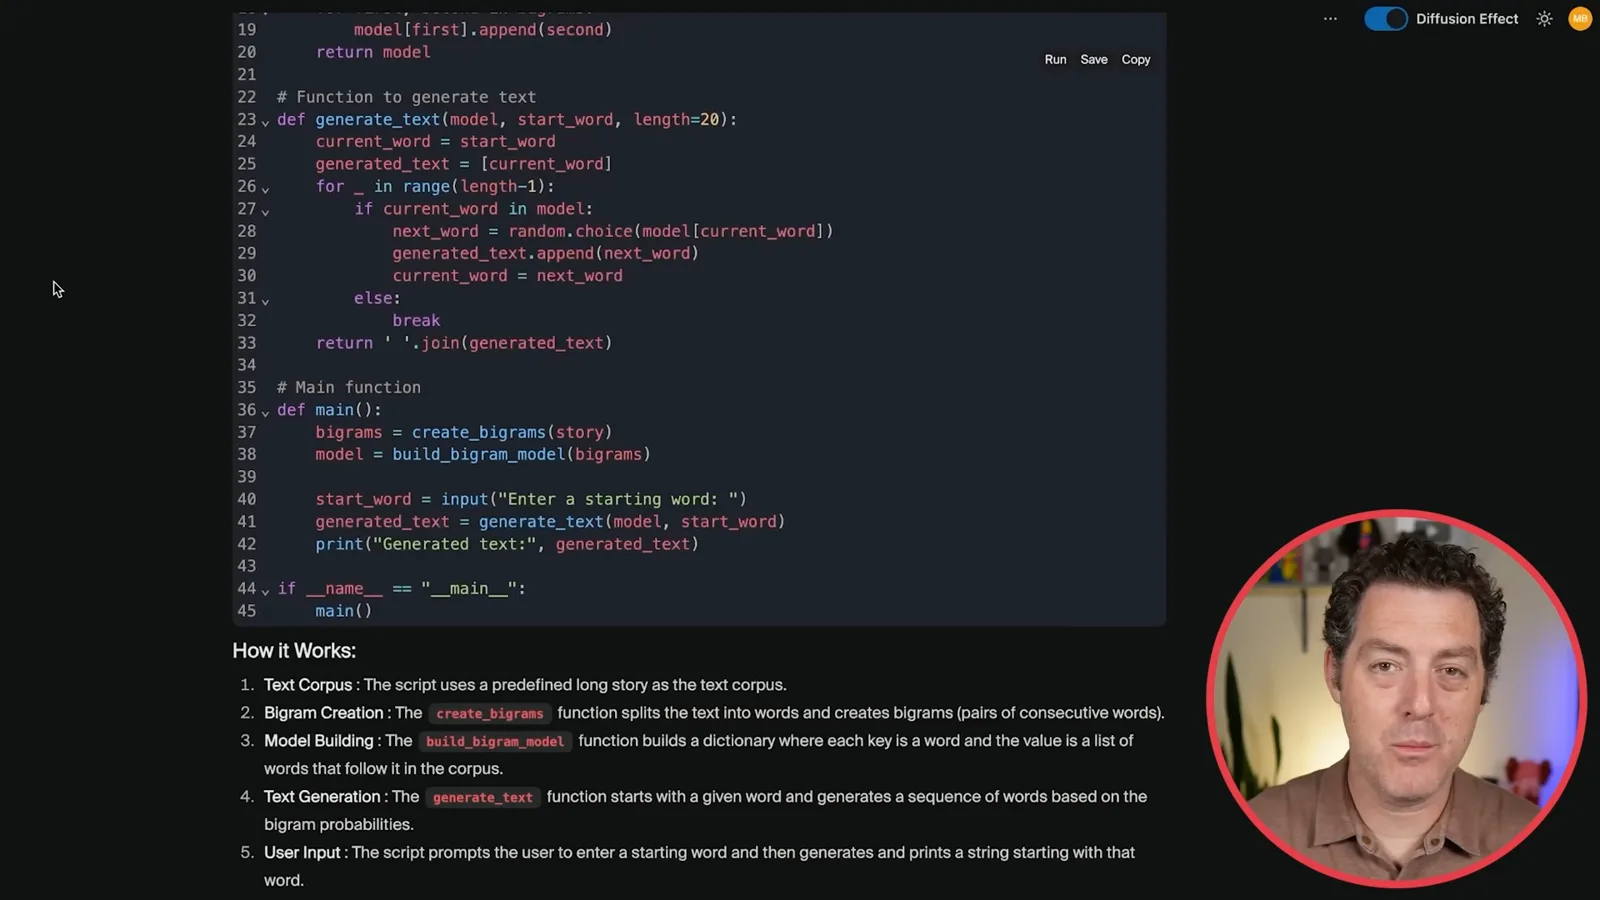
The playground also offers a visual diffusion effect. I slow an example to see rough text become coherent and show a simple Snake game running. The visualization illustrates the process, but the interface alone does not reveal all internal implementation details or guarantee every generated program will work.
The video includes a sponsored segment for GrowthSchool’s AI training. Its statements about course benefits, audience reach and a free offer are promotional claims and the offer was specific to the time of the video.
Benchmarks and possible applications
Berman reviews historical speed and coding comparisons, then considers reasoning, agents and edge use. These possibilities require workload-specific evidence.
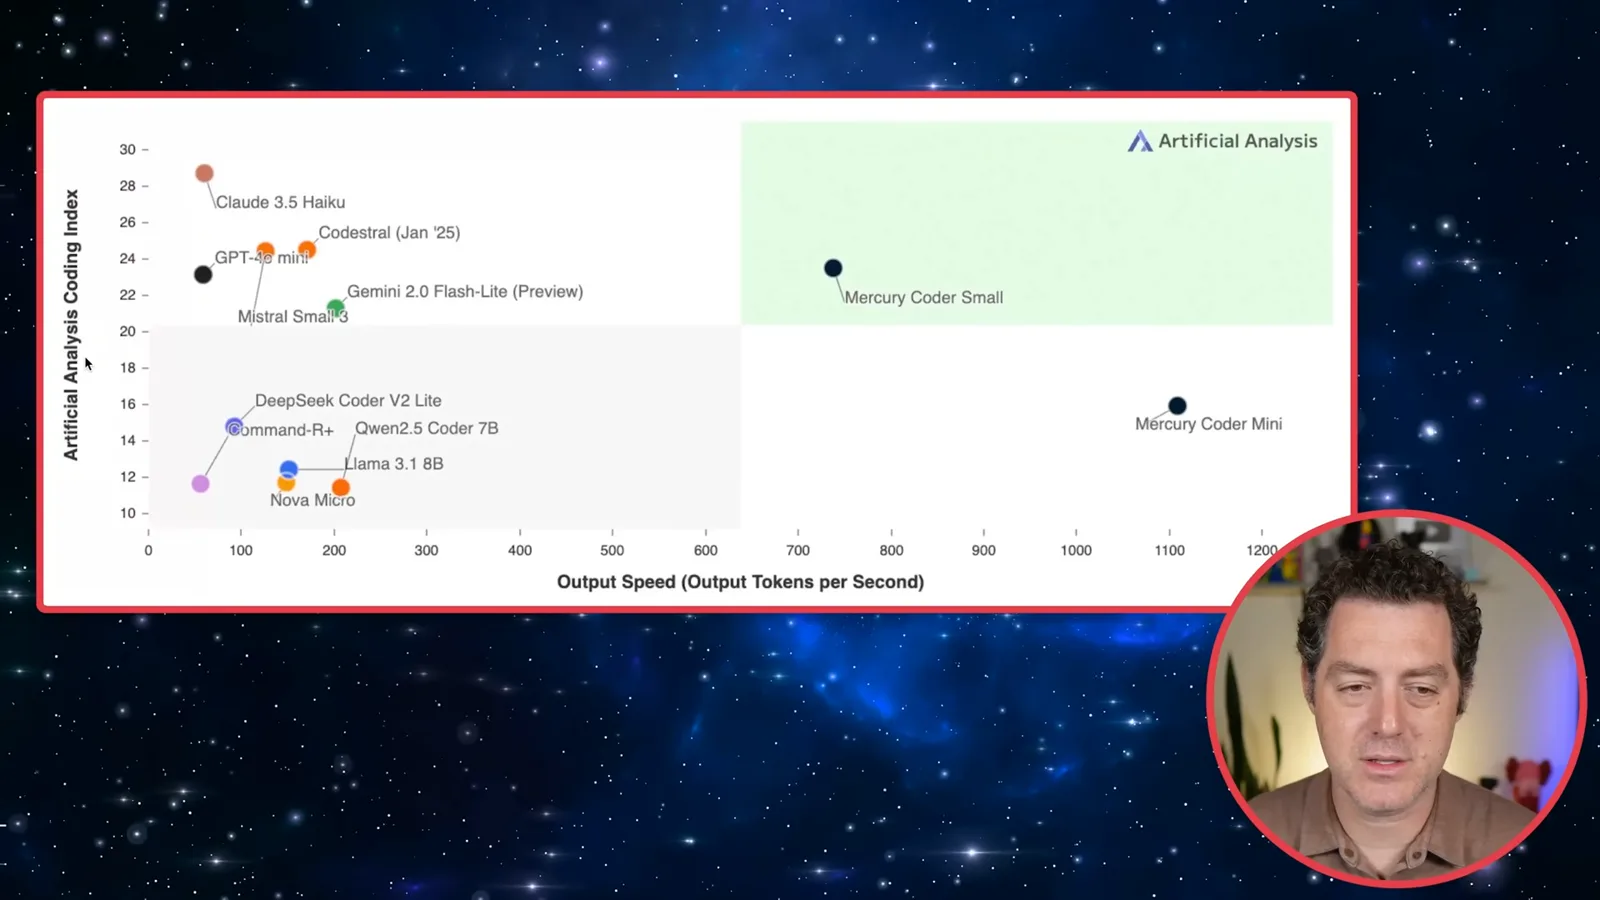
The displayed early-2025 Artificial Analysis chart compares coding scores and output speeds. Mercury Coder Mini is shown around 1,109 tokens per second and Small around 737; Small sits near GPT-4o mini on that chart while Mini is closer to smaller coding models. The results apply to that evaluator’s specific tests and serving conditions.
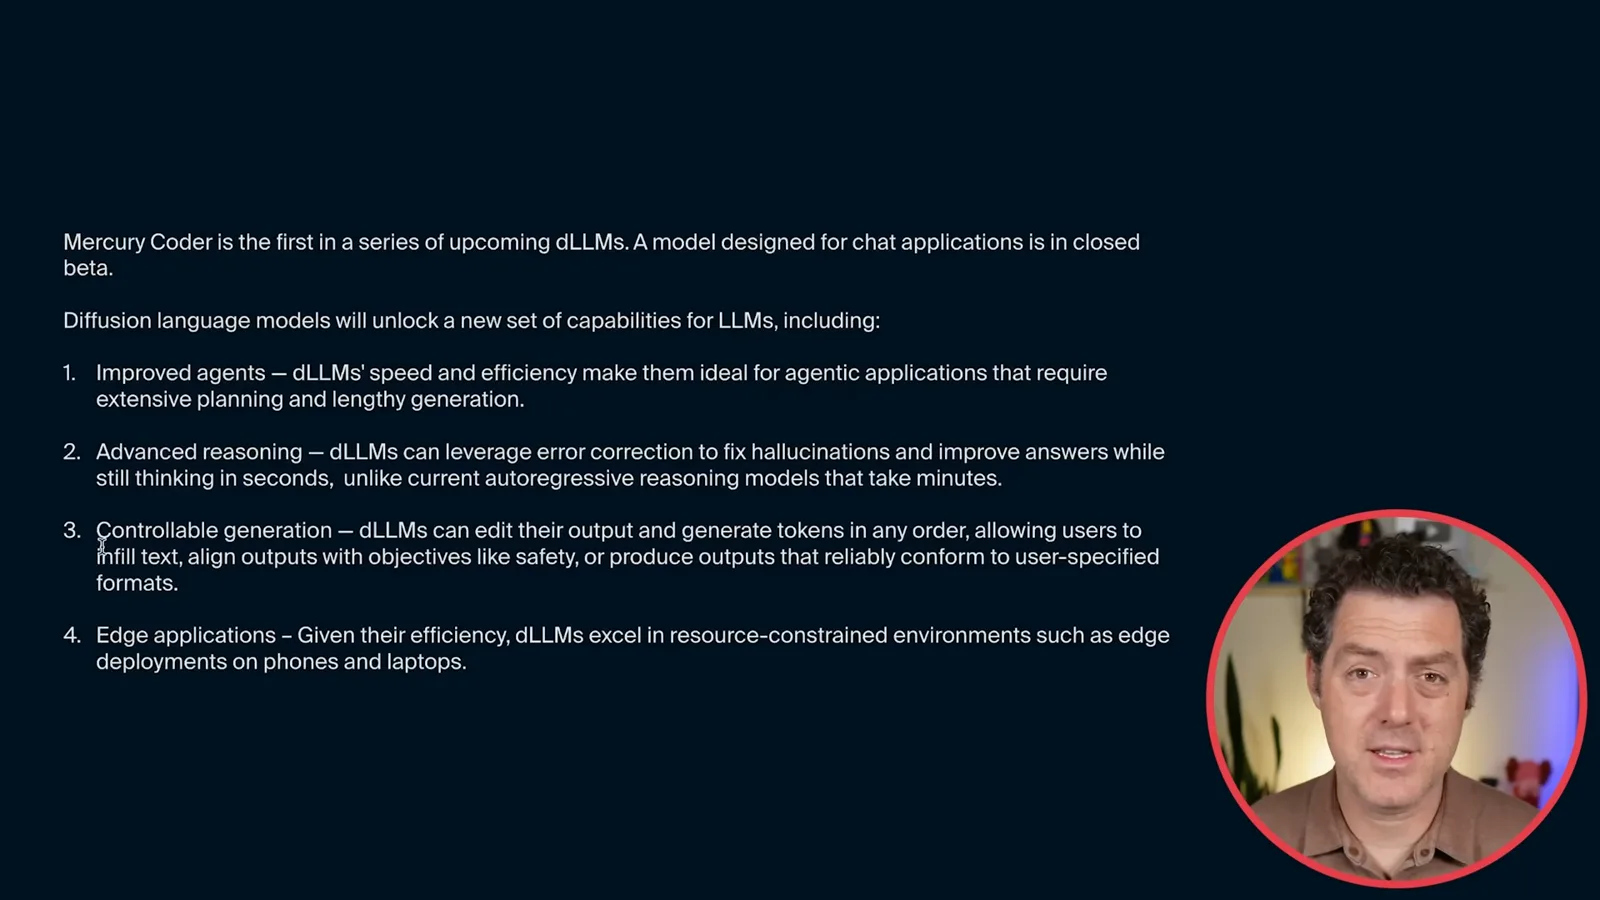
Inception’s presentation argues that faster output could permit more test-time work in a fixed interval. I find that promising, but the opening claim of ten times lower cost is not substantiated by a complete like-for-like price or cost-per-task comparison here. A faster model may also need different amounts of work or produce different-quality results.
The company suggests iterative revision can help structure answers and correct mistakes. That is a plausible research direction, not proof that diffusion models are inherently better at reasoning or eliminate hallucinations. Accuracy and error correction need direct evaluation against appropriate baselines.
A separate promotional speed comparison shows Mercury completing an example faster than Claude and ChatGPT. Individual demo timings depend on model versions, prompts, output lengths, infrastructure and interface conditions. They do not establish a universal speed ratio or comparable answer quality.
I consider agents, longer reasoning, structured generation and edge applications as possible uses. Speed is valuable, but agent systems also face tool latency, reliability, permissions and cost constraints. Claims of better task outcomes or safe local deployment require tests of the actual model and hardware.
Research context and outlook
He cites Andrej Karpathy’s reaction and earlier diffusion research. The article corrects the suggestion that LLaDA lacked a working model.
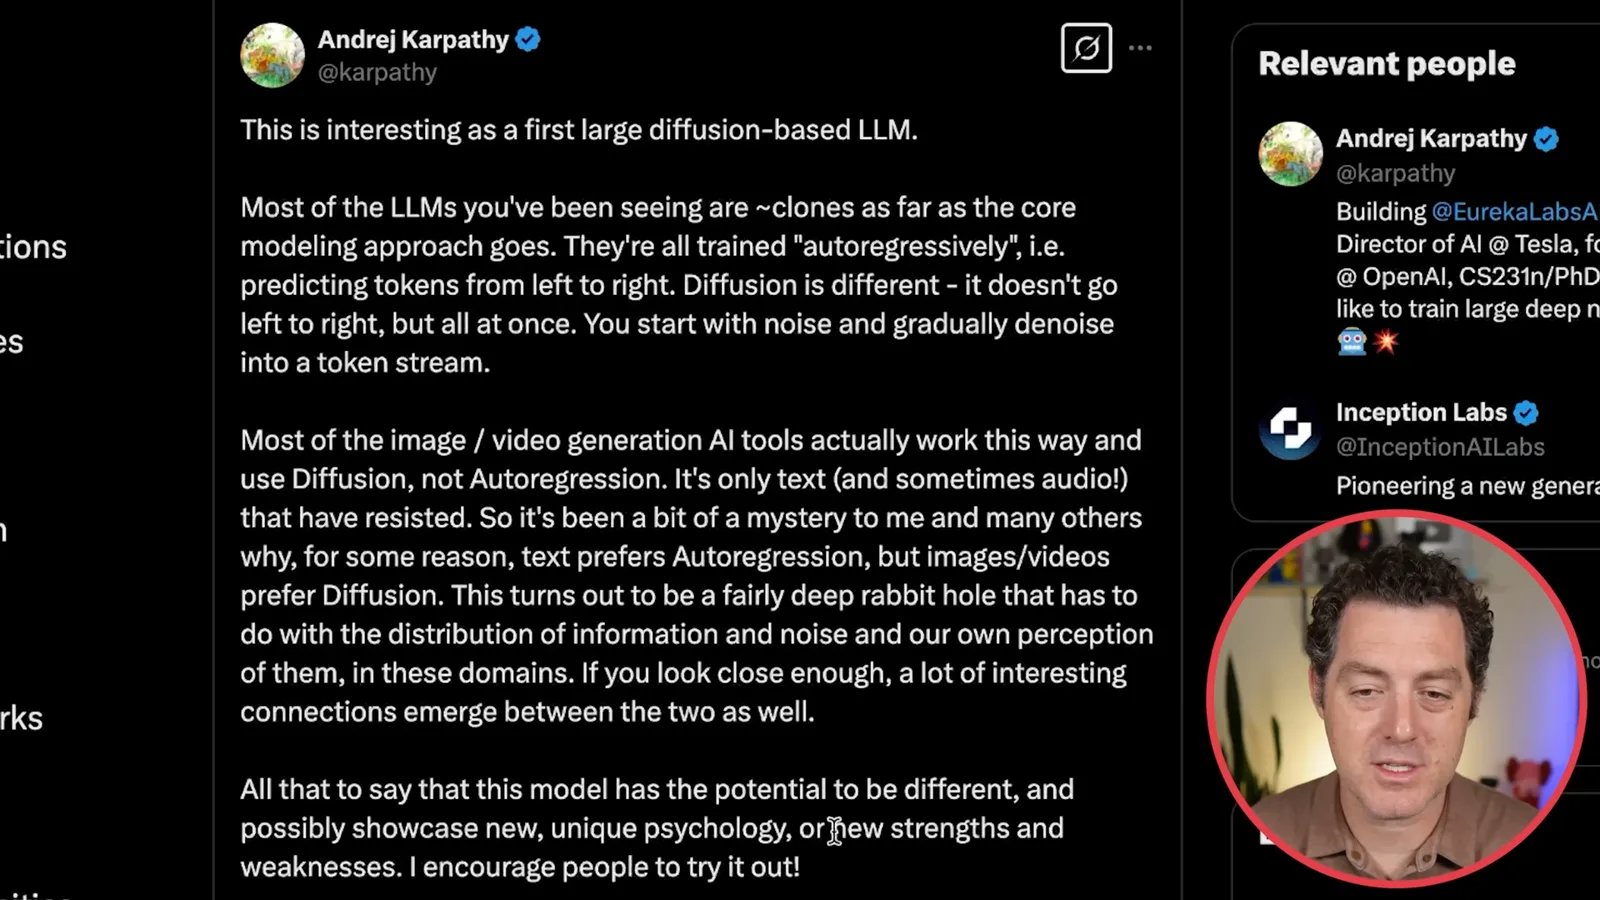
Andrej Karpathy’s commentary notes that diffusion methods are common in image and video generation while autoregressive models have dominated text. He suggests that differences in information, noise and perception may lead to distinctive strengths and weaknesses; this is a research question, not a demonstrated advantage across all tasks.
I mention the earlier paper “Large Language Diffusion Models” but say it did not have a working model. Correction: the February 2025 LLaDA paper described an 8-billion-parameter model trained from scratch and released research code and a project page. Mercury’s commercial-scale release was not the first working diffusion language model.
I want to continue testing the approach in coding tools. Its value will depend on measured task quality, latency, deployment requirements and cost, not speed alone.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.