En 30 secondes
In this June 2026 video, Theo argues that restrictions around Anthropic's Fable model limit who can use it and complicate evaluation. He cites benchmark results that use an Opus fallback and a report of refusals on ProgramBench, and criticizes the precedent he believes the restrictions set.
- 1A powerful model with access limitsTheo praises Fable's capabilities but criticizes how Anthropic implemented access restrictions.
- 2Benchmark fallback mattersHe notes that strong reported results can include an Opus 4.8 fallback rather than Fable alone.
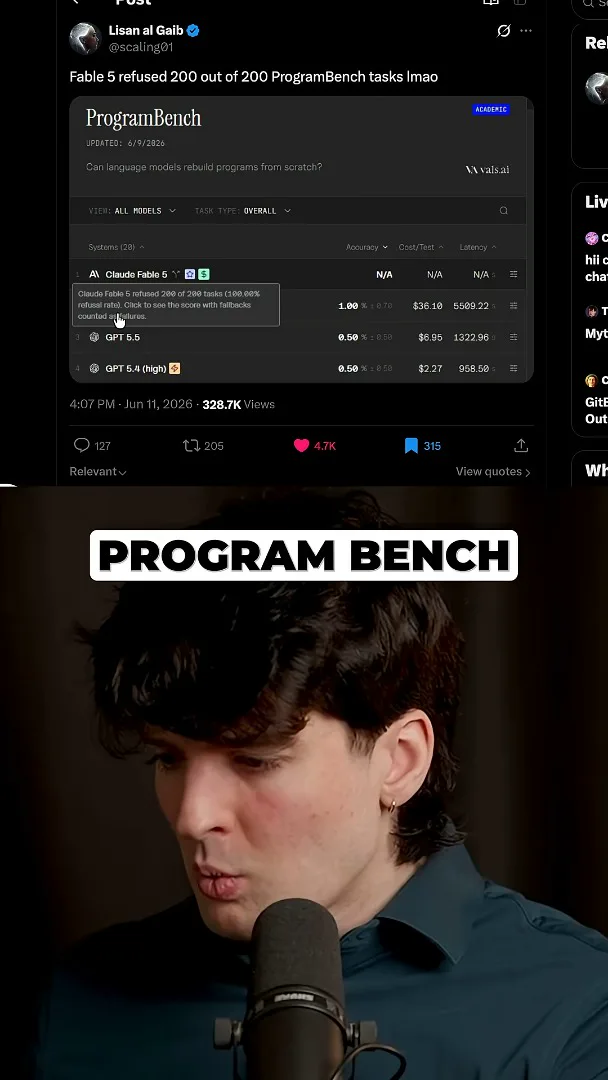
- 3ProgramBench refusalsHe cites a reported run in which Fable refused all 200 tasks, and argues that restrictions affect evaluation.
À retenir
- Theo says some people could not access Fable at the time of the video.
- Some benchmark results for Fable included an Opus 4.8 fallback.
- Theo cites a report that Fable refused all 200 tasks in a ProgramBench run.
- He argues that the restrictions set a troubling precedent for future models.
Lire le texte remanié, chapitre par chapitre
Access and benchmark restrictions
Theo criticizes the limits on who can use Fable. He also examines benchmark results and the role of a fallback model.
Fable, Anthropic's new Mythos-class model, is powerful, but at the time of this video some people cannot use it at all. I think the way Anthropic implemented these restrictions is unacceptable.
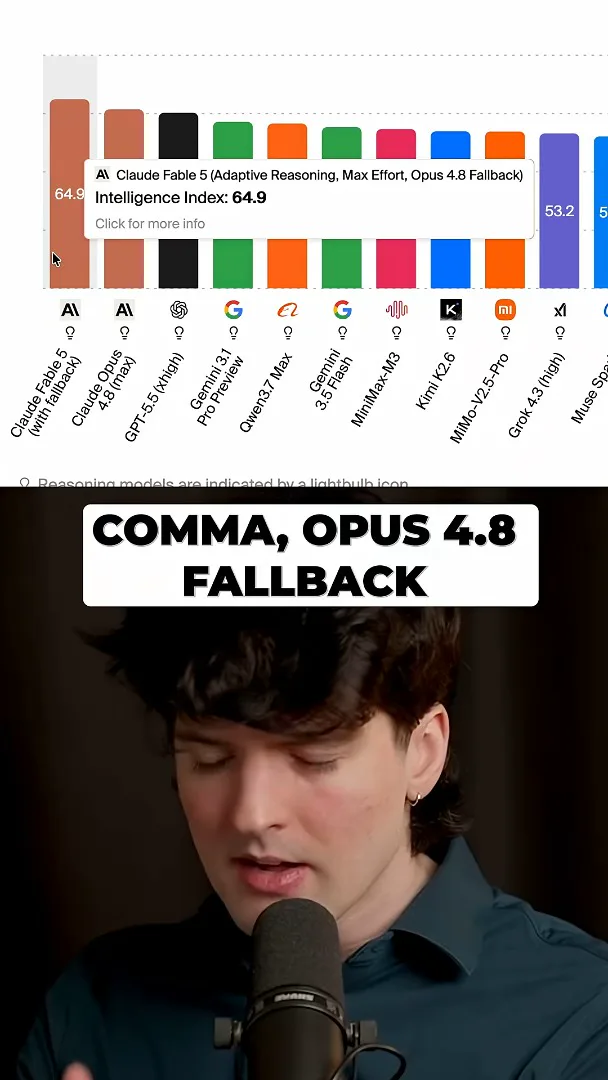
The model has benchmarked very well, but some results come with a qualification: an Opus 4.8 fallback. In another example, a reported ProgramBench run says Fable refused all 200 tasks. I find the restrictions absurd, and I worry about the precedent they set.
Refusals and precedent
He cites reported refusals on ProgramBench. He worries about the precedent set by such restrictions.
Sur la même chaîne
 38:47EN
 Theo - t3․gg· 28 oct. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27 oct. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26 oct. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23 oct. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22 oct. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20 oct. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.