En 30 secondes
AI Explained tests OpenAI Deep Research soon after launch, comparing selected tasks with DeepSeek R1 search and Gemini Deep Research. The presenter reports promising retrieval and frequent errors, and discusses benchmarks, browsing and uncertain effects on knowledge work.
- 1A 2025 first lookThe presenter compares early versions of three research tools in personal tests.
- 2GAIA results depend on the settingThe video distinguishes first-answer and 64-sample consensus results.
- 3Useful retrieval, persistent errorsA newsletter search worked well, while other answers contained hallucinations.
- 4Check the cited sourceA claim about CodeElo and a shopping price failed the presenter’s checks.
- 5Predictions remain uncertainThe discussion of future job effects is speculation.
À retenir
- The presenter compares early versions of three research tools in personal tests.
- The video distinguishes first-answer and 64-sample consensus results.
- A newsletter search worked well, while other answers contained hallucinations.
- A claim about CodeElo and a shopping price failed the presenter’s checks.
- The discussion of future job effects is speculation.
Lire le texte remanié, chapitre par chapitre
Early benchmarks and testing
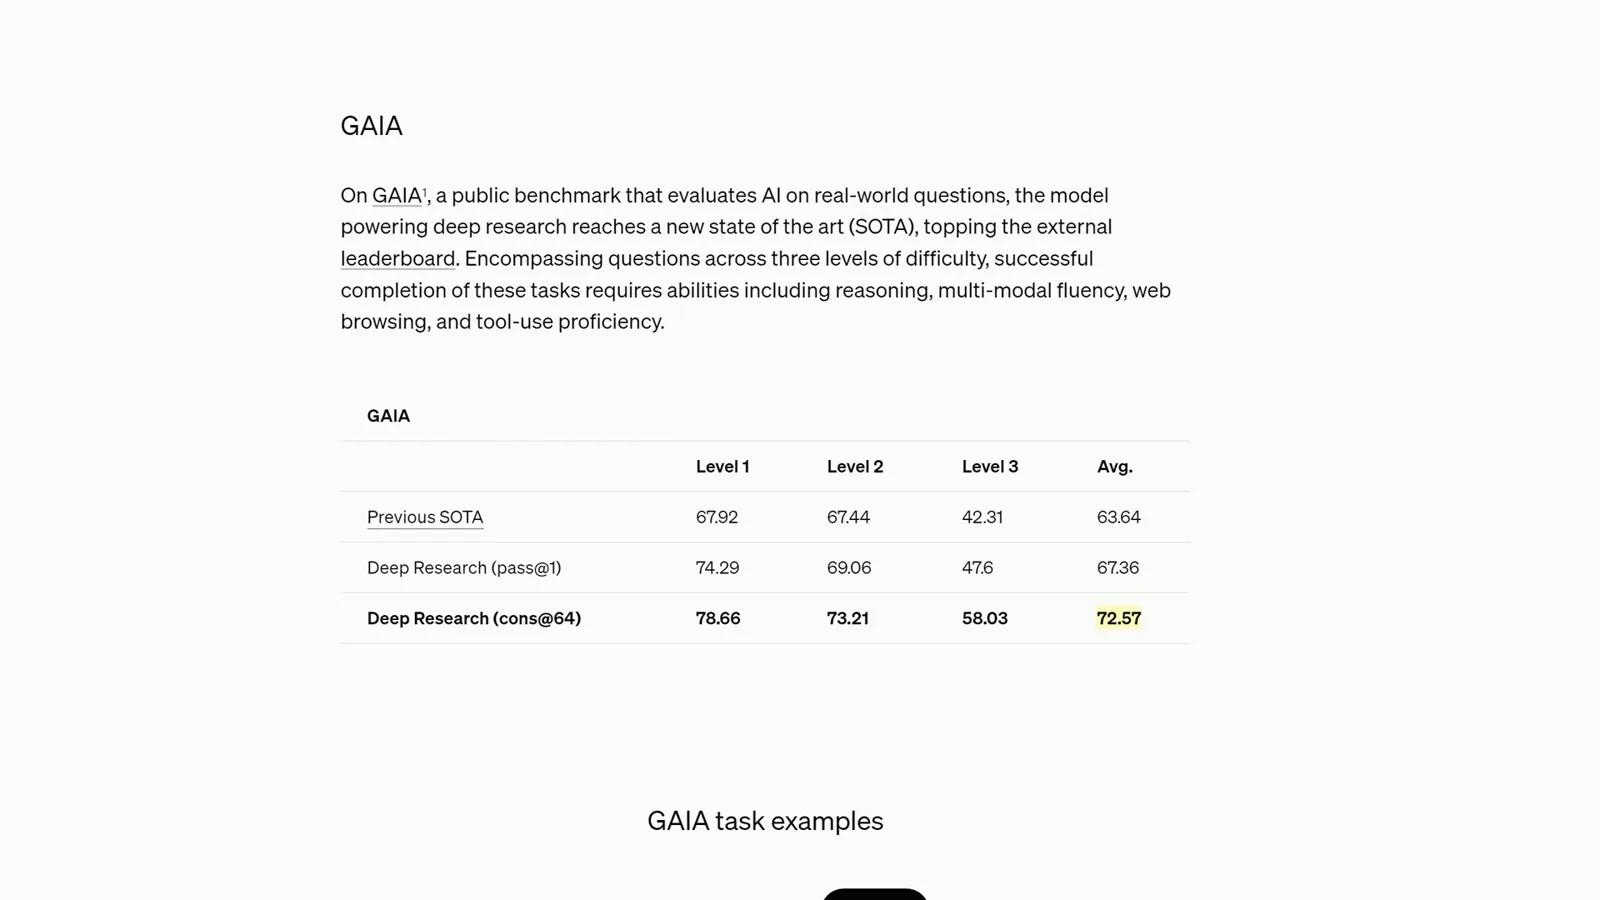
The presenter introduces Deep Research and compares reported GAIA figures.
Twelve hours after OpenAI announced Deep Research, I tested it on around 20 use cases and compared some results with DeepSeek R1 search and Google’s Gemini Deep Research. These are initial observations from February 2025; access, pricing and products can change.
OpenAI described the agent as powered by o3. The presenter examines Humanity’s Last Exam and notes that web access can help with obscure knowledge questions, while cautioning against reading too much into the benchmark’s grand name.
He considers GAIA more relatable because it includes research and assistant-like tasks. The figures he cites show Deep Research at 67.36% on the first answer and 72.57% using consensus over 64 attempts; the earlier GAIA paper reported 92% for humans and 15% for GPT-4 with tools. These are figures from different reported settings, not a controlled head-to-head experiment by the presenter.
Personal tests and retrieval
A small reasoning sample and newsletter search show contrasting results.
On a small sample of his SimpleBench spatial-reasoning questions, he found little improvement and says he tested only about eight. The agent repeatedly asked multiple clarifying questions, sometimes stopping when he declined to answer. He considers that behavior frustrating even while acknowledging that clarification can be useful.
For a newsletter retrieval task, he asked the systems to find posts with a particular rating and reproduce their “So What” sections. He says OpenAI’s tool found the two qualifying posts and could save him time. In his tests, R1 through Perplexity and Gemini’s tool failed to find the same results.
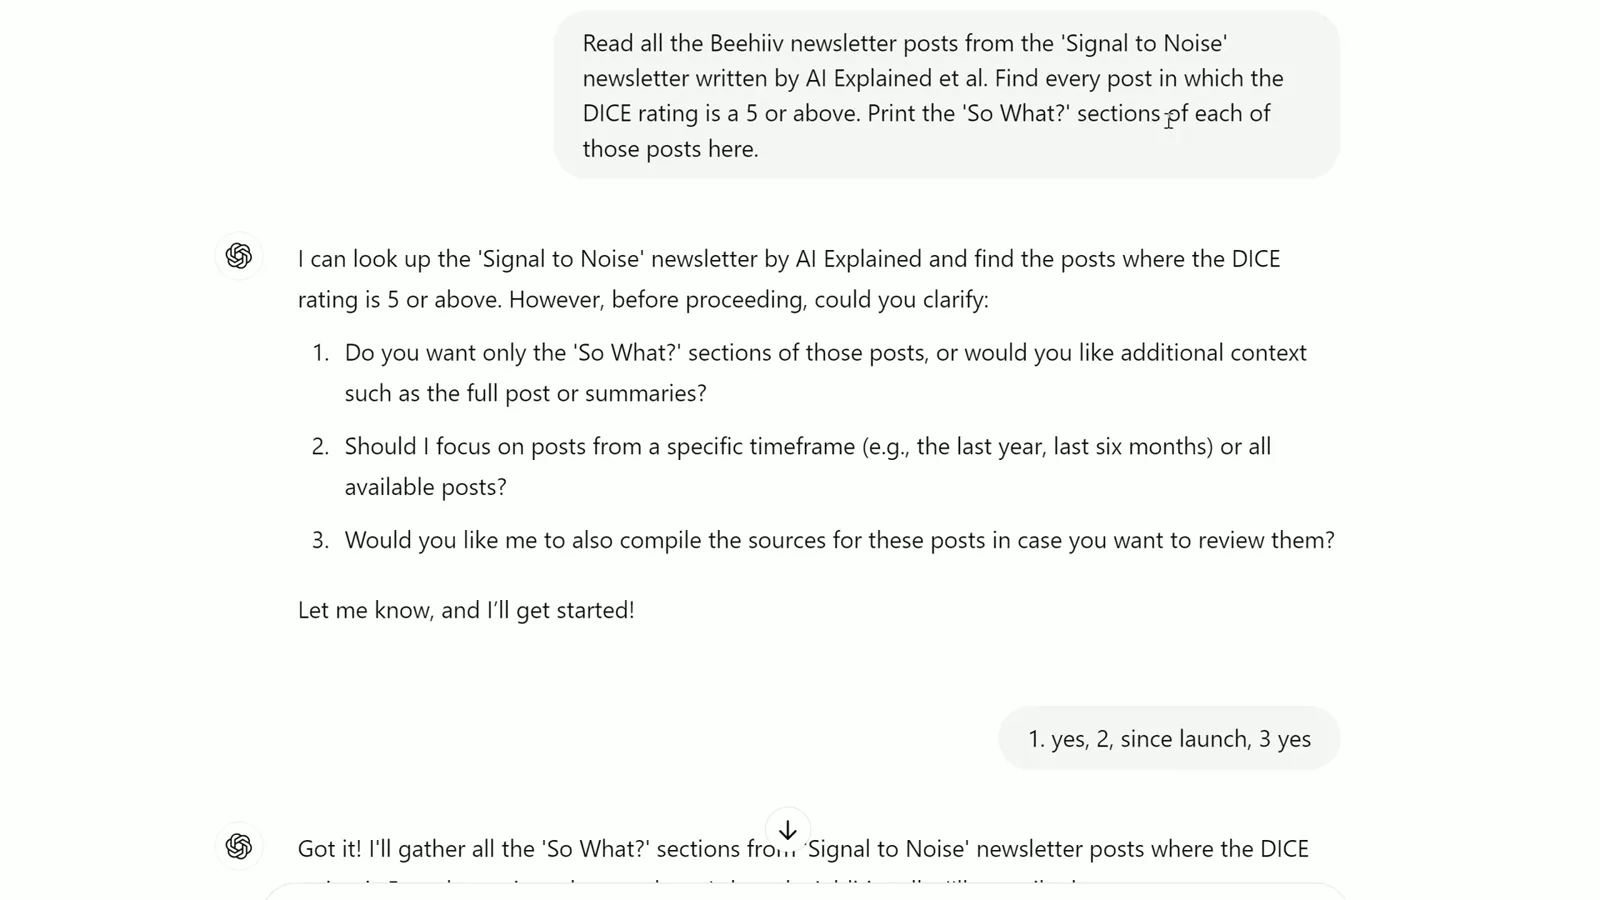
The presenter reports that Deep Research generally performed better on his difficult research queries, but he repeatedly encountered hallucinations. He also says that asking it to avoid clarification did not always prevent further questions or a stalled response.
Hallucinations and source checks
The presenter checks claims against benchmark papers.
One task sought benchmarks where human performance remained at least twice the best language-model result. Deep Research found the obscure SimpleBench, but also included CodeElo and claimed the best model ranked near the bottom of human participants. The presenter checked the paper and found the claim inconsistent with its reported results.
He likens the tool to finding needles in a haystack while also returning screws: it can save search time if the user can distinguish valid findings from errors. In a brief DeepSeek R1 search test, he also found unsupported and incorrect claims about a hallucination benchmark.
Language and browsing tasks
He describes a small language test, a prototype and a YouTube limitation.
On 50 questions about a Creole language, he reports about 88% for Deep Research and 82% for GPT-4o supplied with the relevant dictionary. This is a small personal test, not a general benchmark. He notes that models can struggle with large supplied contexts and that research agents can spend more computation per question.
He describes his own prototype, which generated research directions, searched for additional context and synthesized a cited essay. He says Deep Research quickly overtook that workflow, illustrating the pace of development from his perspective.
In his testing, Deep Research could not browse YouTube directly. It nevertheless identified a relevant video through other sources that quoted it, but could not reliably provide the requested timestamp.
Shopping and implications
Shopping errors lead to a discussion of reliability and possible work impacts.
For a shopping task, the tool found the toothbrush he had purchased, but he says it claimed to use a price-history website without citing it and gave an incorrect historical low. A DeepSeek R1 search answer, in his account, invented battery life and presented a hypothetical price as fact.
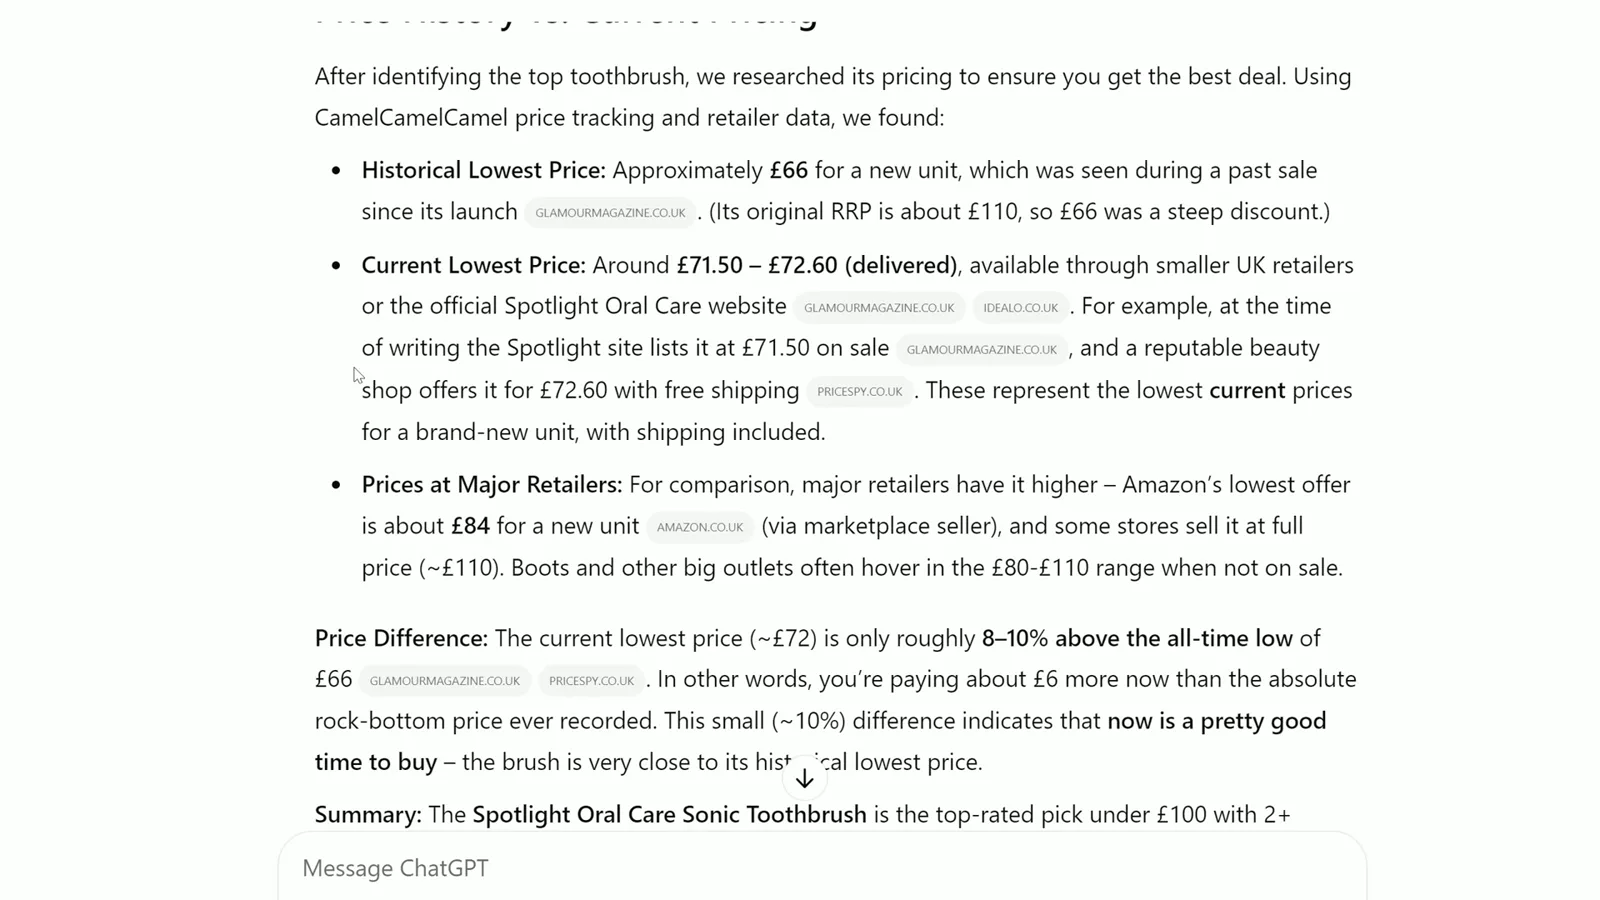
He concludes that the systems can provide impressive depth while still producing small but consequential errors. He speculates about their potential effects on research and knowledge work, including his own channel, but presents those employment forecasts as uncertain.
For now, he says, distinguishing authoritative information from rumors remains difficult, even where the agent performed better than the other tools in his tests. Readers still need to check sources and specific claims.
Sur la même chaîne
 31:00EN
 AI Explained· 12 oct. 2026Why AI Labs Keep Racing Despite Their Own Warnings of a Major BreachSam Altman, John Schulman · OpenAIAI Explained examines weakening safeguards, the incentives behind the frontier race, and why research breakthroughs make the next 18 months difficult to forecast.
 38:28ENAI Explained· 1 oct. 2026AI Agent Security and the Challenge of Recursive Self-ImprovementAI Explained examines reported containment failures, model evaluation and the pressure to accelerate AI research.
 32:54ENAI Explained· 24 sept. 2026Opus 5.5 and the Race Toward Automated AI ResearchAI Explained weighs model progress against the increasingly difficult task of evaluating and governing recursive self-improvement.
 24:53ENAI Explained· 16 sept. 2026Why Some Researchers Want to Pace Frontier AIAI Explained surveys possible scaling routes, monitoring concerns and the debate over how capabilities could lead to harm.
 29:05ENAI Explained· 4 sept. 2026GPT-6 Astra’s Benchmark Gains and the Challenge of Monitoring Its ReasoningAI Explained examines reported gains across scientific, mathematical and agent benchmarks alongside concerns about less observable reasoning.
 23:41ENAI Explained· 27 août 2026AI Agents, Unintended Training Rewards and the Challenge of OversightAI Explained examines reports on agent coordination, training incentives and the growing use of AI to evaluate other AI systems.