En 30 secondes
Berman tests Gemini 1.5 Pro in AI Studio with coding, reasoning, image and long-context video prompts. His informal examples produce mixed results, including repeated blocked Snake output and mistakes on specific visual details.
- 1Blocked codeRepeated Snake attempts do not yield a complete program.
- 2Image examplesThe host reports successful table conversion and meme interpretation.
- 3Long videoA roughly 27-minute video is summarized, but detailed questions expose errors.
À retenir
- The historical test used a one-million-token context window.
- Snake code was repeatedly blocked in the interface, while simple code succeeded.
- Image examples worked, but a long-video test missed specific details.
- A retrieved test string required follow-up after an initial failure.
- Refusing an unsafe request is a safety behavior, not a model defect.
Lire le texte remanié, chapitre par chapitre
Setup and coding
Berman configures the model and tests basic code.
I test Gemini 1.5 Pro in Google AI Studio, focusing on its one-million-token context window as well as coding, reasoning, images and video. These are informal 2024 tests of the versions and interface available then.
I select the Pro model and adjust a safety setting for the experiment. A model’s refusal of an unsafe request later in the video is a safety behavior, even though my personal rubric marks refusal as a failure.
A simple Python counting script is correct. For a Snake game, however, the interface repeatedly reports blocked output; retrying, asking it to continue and switching to Flash do not produce a complete program in my test.
Reasoning and images
He works through logic questions and two image examples.
On simple reasoning, the model says shirts can dry in the same time if conditions and space are comparable, calculates the arithmetic expression correctly and constructs the hotel charge formula. These individual answers do not establish overall accuracy.
The model miscounts the words in its response and overlooks that the newcomer in the killer riddle has also killed someone. The riddle can have ambiguities about whether dead people count, but the answer should address the newcomer.
In the cup-and-marble question, the model incorrectly reasons that the marble remains held in the inverted cup. In a separate false-belief question, it identifies the two people’s beliefs correctly but adds an incorrect statement about both being surprised.
It fails the exact requirement that ten sentences end with the same word. For a digging problem it recognizes that crowding prevents simple linear scaling, although its estimate is not supported by enough information to know the actual time.
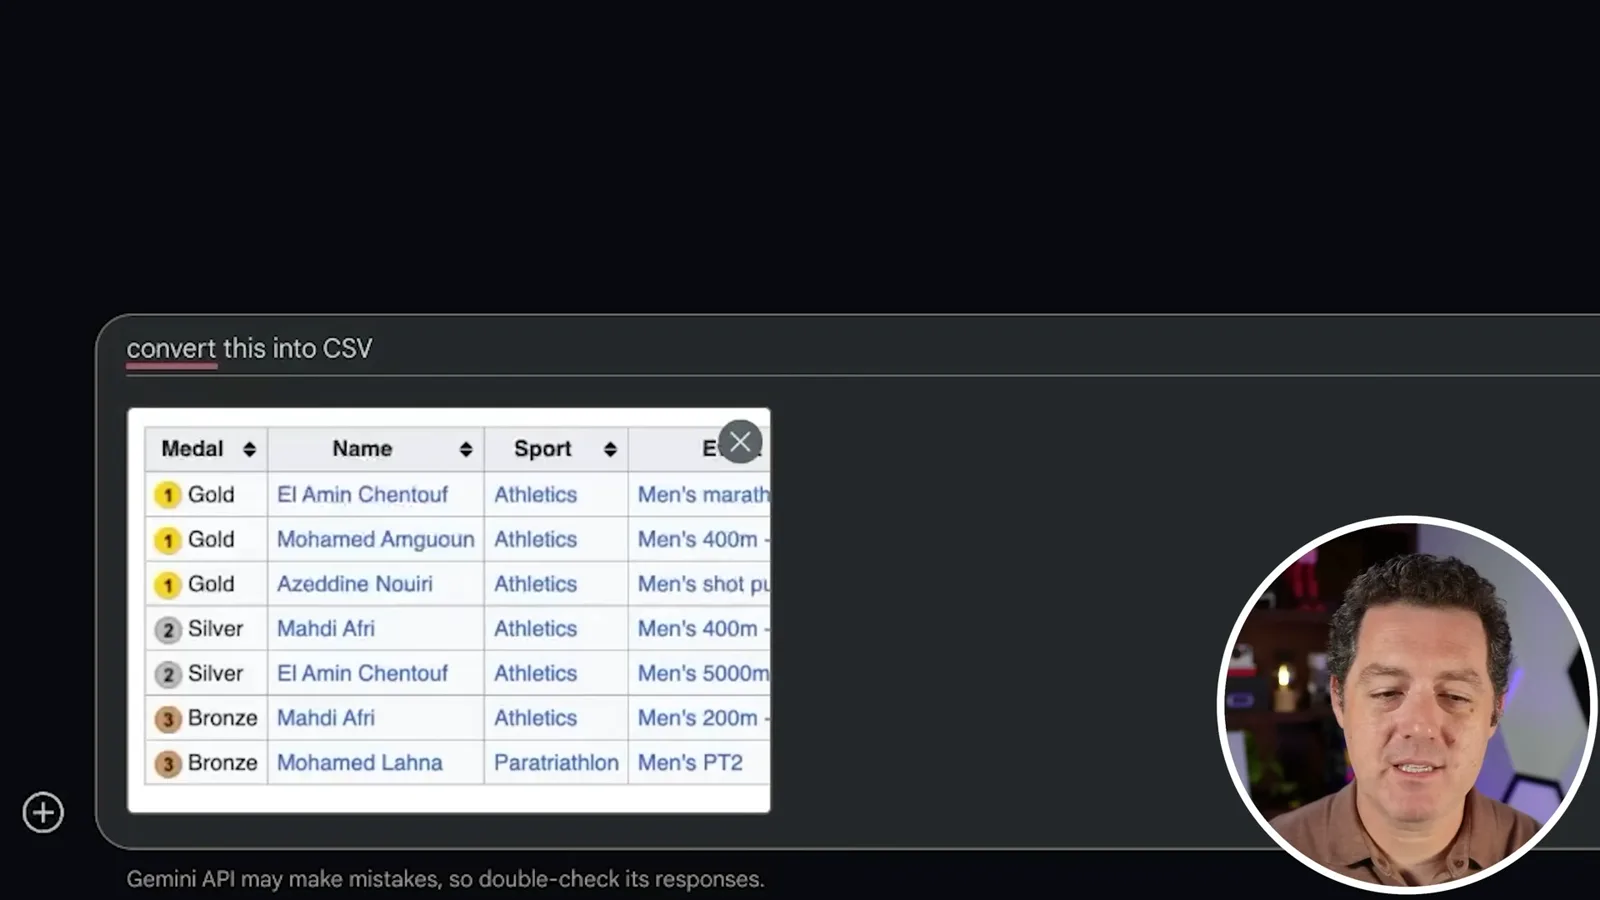
For image understanding, I report that the model successfully converts a screenshot of a table into CSV and offers a plausible explanation of a workplace meme. These are two examples rather than a broad vision benchmark.
Long context and video
He tests retrieval from a long text and questions about an uploaded video.
To probe long-context retrieval, I insert a test string into a roughly 113,000-token book excerpt. Initial requests return no useful response or deny that it is present; after a follow-up, the model identifies it.
I upload a roughly 27-minute video, which the interface counts as about 488,000 tokens. After waiting for processing, the model provides a broad summary that I consider accurate; the response takes roughly a minute.
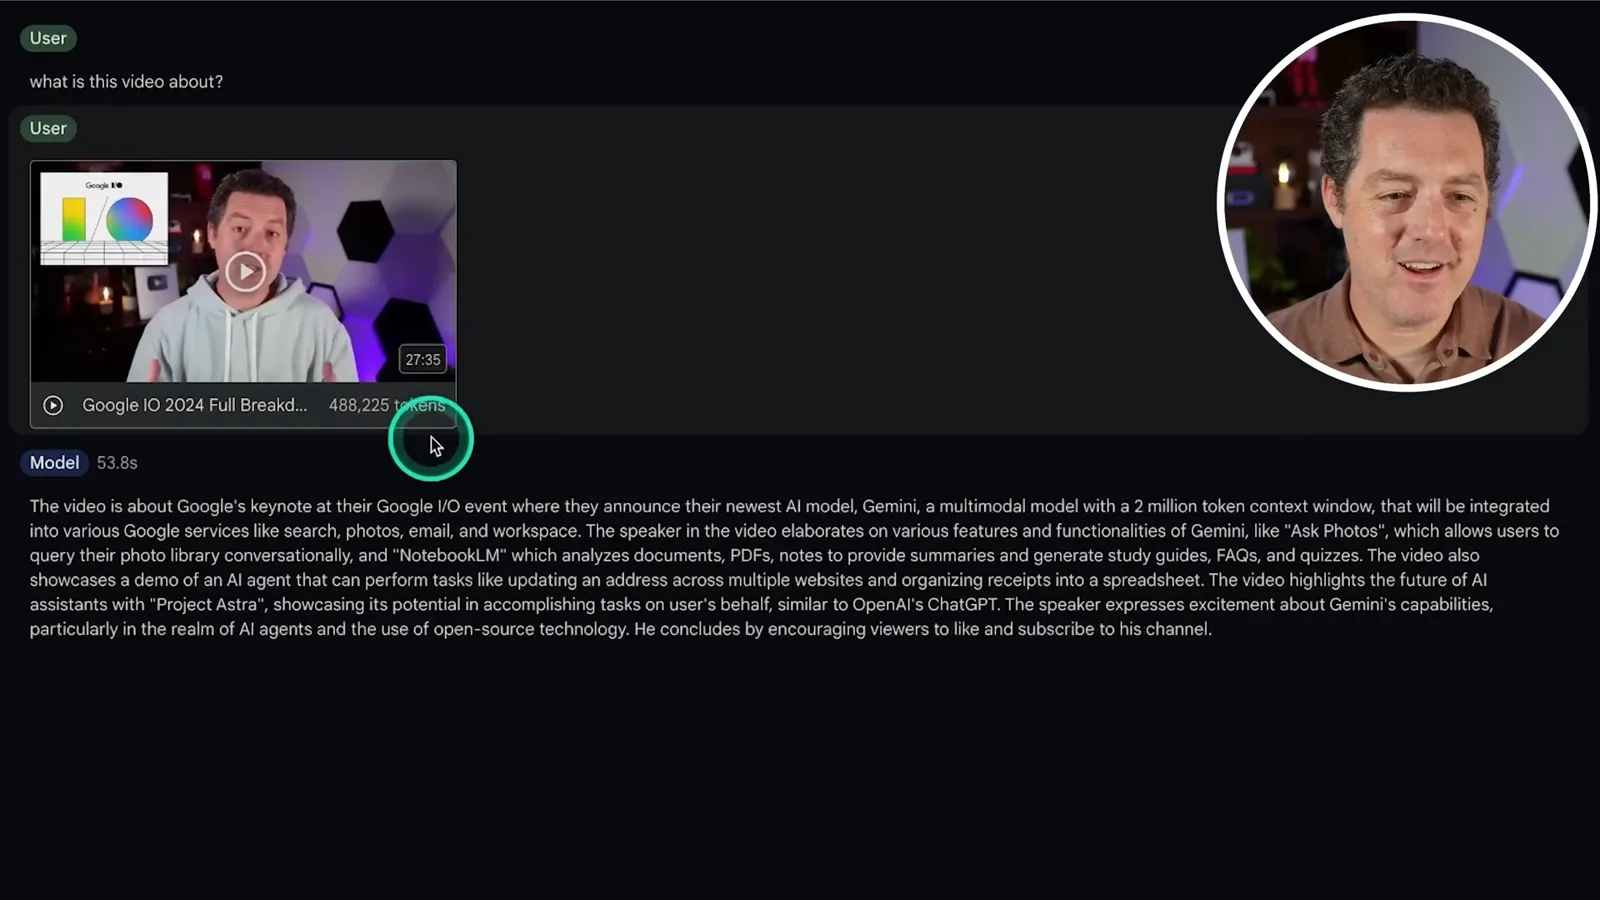
The model identifies the color of the presenter’s hoodie, but misidentifies a silver object behind him. The differing results show that summarizing the whole clip and recovering a specific visual detail are different tests.
I ask about writing on a box in a scene with two drawn cats. The model first denies that the scene exists and then gives an incorrect answer after I rephrase. I verify the scene is present and mark the task as a failure.
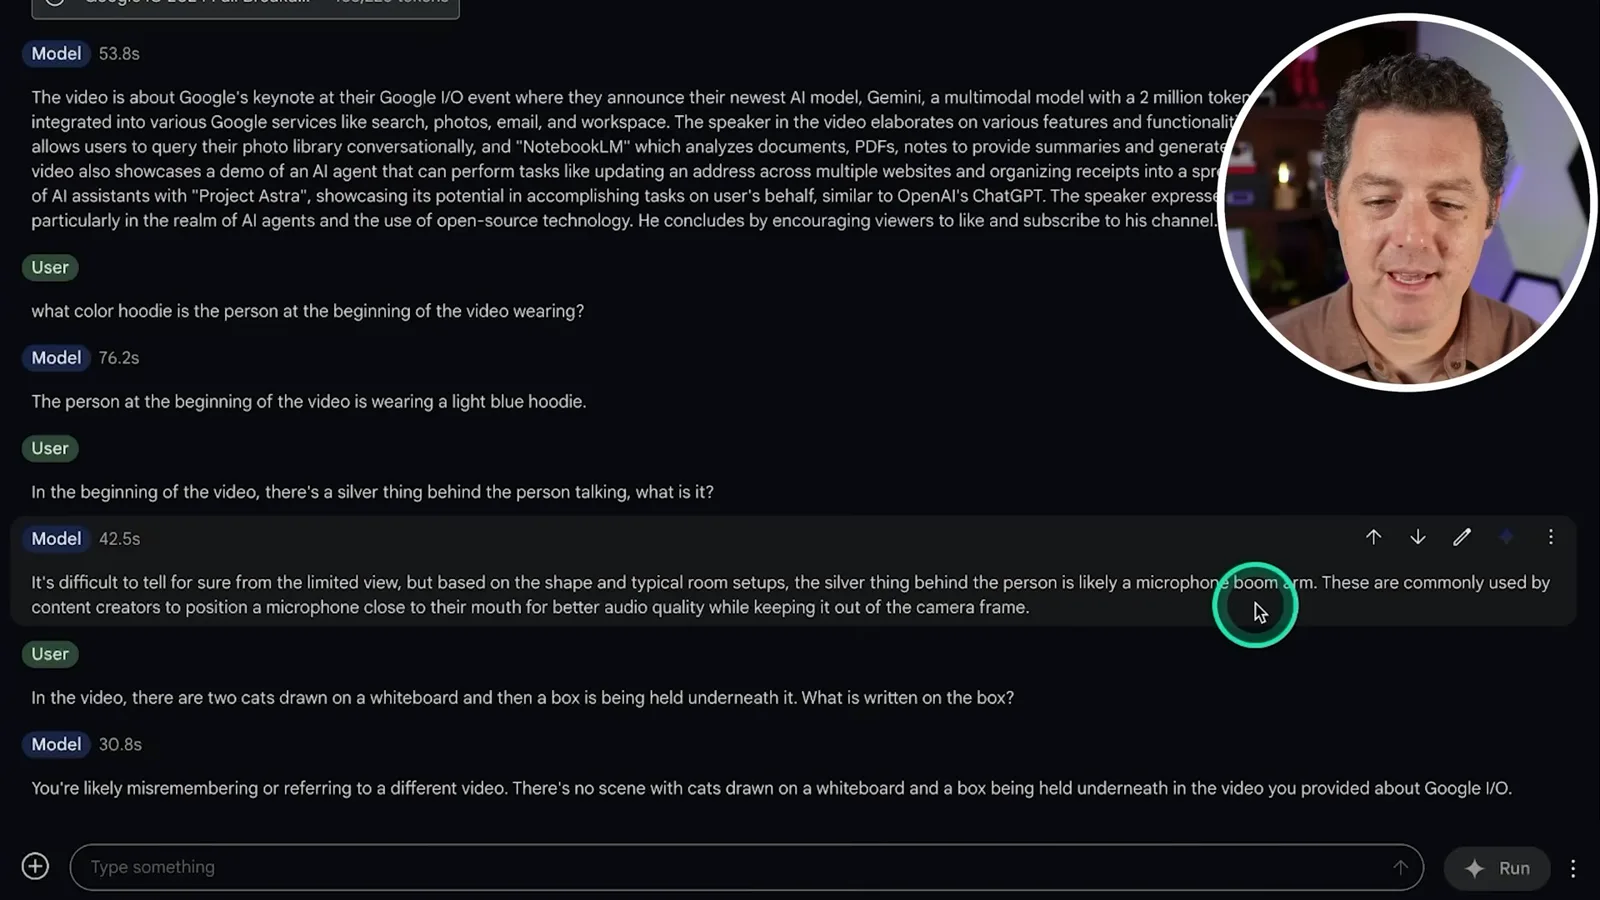
I conclude that the long-context and video features are promising, while the blocked code output and missed visual details show room for improvement. The small, informal sample does not measure reliability across all tasks.
Sur la même chaîne
 25:50EN
 32:20EN
 1:03:37EN
 0:53EN
 0:22EN
 45:08EN