En 30 secondes
In September 2024, Matthew Berman interviews Reflection 70B creators Matt Shumer and Sahil Chaudhary about training a model to review and correct its responses. Their initial benchmark claims were later challenged when independent evaluations struggled to reproduce parts of the advertised results.
- 1The proposed methodShumer describes training a model to recognize and correct errors in intermediate text.
- 2Selective reflectionChaudhary says examples were weighted toward difficult cases and included checking correct steps.
- 3Token overheadThe guest gives an informal estimate rather than a measured cost figure.
- 4Benchmark claims need contextThe creators’ initial performance claims were later questioned by independent evaluators.
À retenir
- The creators describe fine-tuning on synthetic examples that include checking intermediate steps.
- They aim to use reflection selectively to avoid encouraging unnecessary mistakes.
- They estimate higher token use on harder tasks without providing precise measurements.
- Several ideas, dataset-release plans and model variants were future intentions at the time.
- Later independent evaluations reported difficulty reproducing initial performance claims.
Lire le texte remanié, chapitre par chapitre
Introduction and launch claims
Berman introduces the guests and their model announcement.
Matthew Berman welcomes Matt Shumer of HyperWrite and Sahil Chaudhary of Glaive to discuss Reflection 70B, announced the day before. This is a launch-period interview: later independent evaluations reported difficulty reproducing parts of the initial benchmark claims.
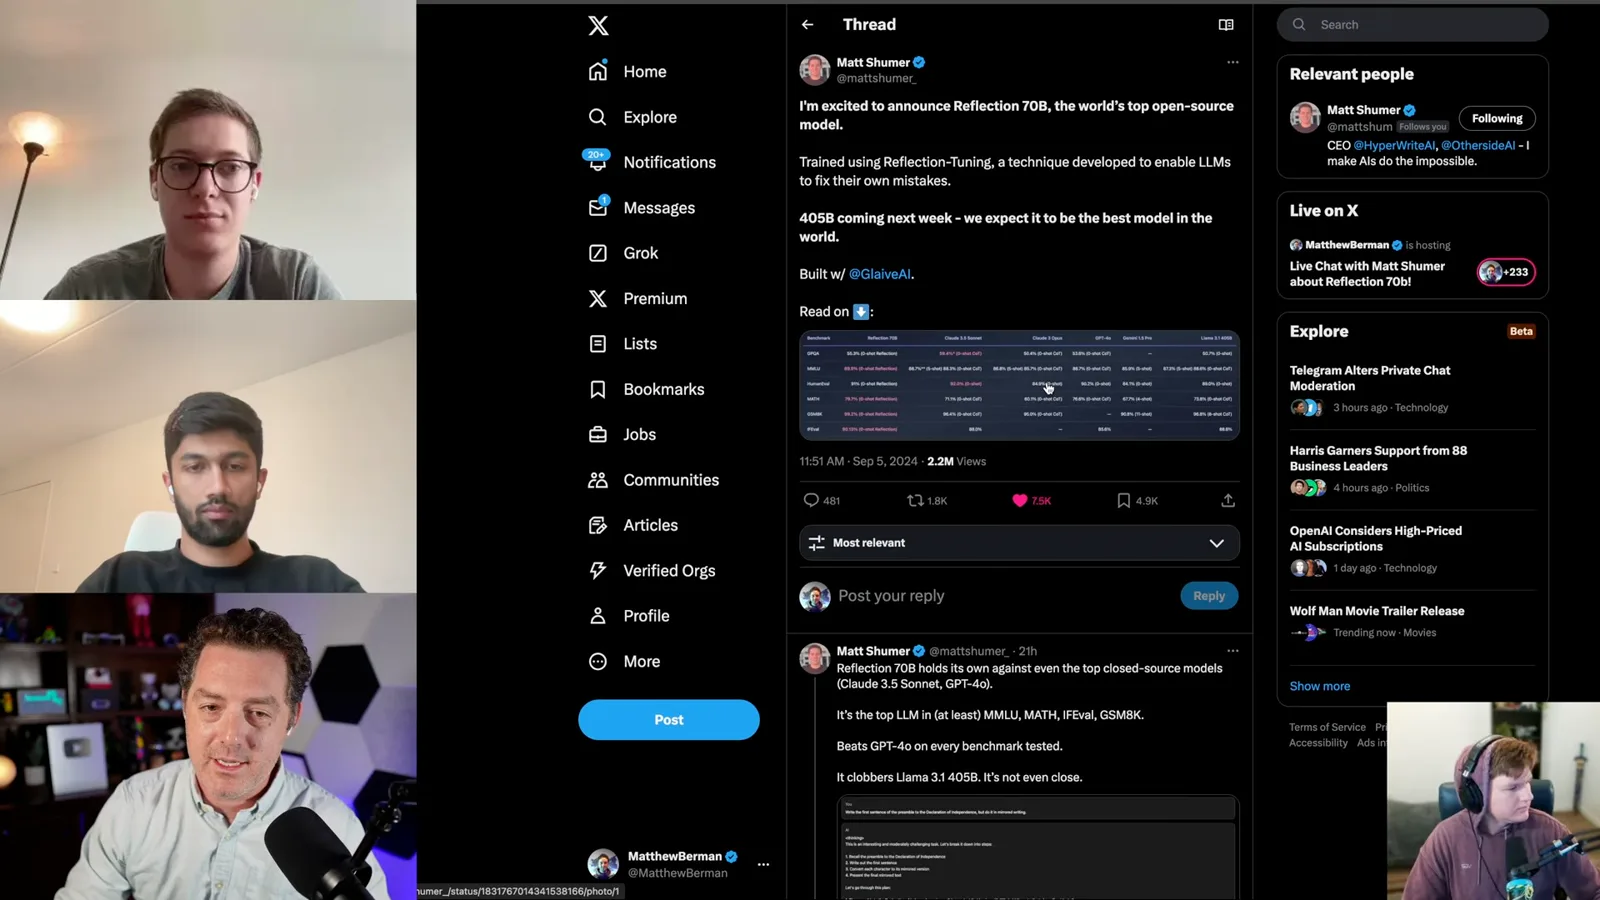
Berman reads Shumer’s announcement and its claimed benchmark comparisons with much larger models. He also mentions a proposed 405B version; the interview’s future plans are not evidence that it was subsequently released.
Shumer describes HyperWrite’s evolution from an email-writing idea into a broader writing product. He says the Reflection project began after he contacted Chaudhary about a possible collaboration.
The guests say they developed the dataset, fine-tuned and released the model in roughly three weeks. Shumer argues that a small team can sometimes make progress without the resources of a major lab; this is the creators’ account of their work.
Chaudhary explains that Glaive helps organizations generate use-case-specific synthetic datasets and iterate on custom models. He presents data quality and fast iteration as central to the project.
Reflection tuning and data
The creators explain their proposed method and synthetic dataset.
Shumer describes “reflection tuning” as training a model to identify and correct mistakes in its intermediate response. His analogy is a person noticing an error and backtracking, though visible self-correction alone does not prove the model’s internal reasoning.
He argues that a model may carry an early error through later steps and says the objective is to catch such errors without teaching the model to make new mistakes deliberately. He acknowledges that the first version remains imperfect.
Chaudhary says the team began with around 10,000 examples and expanded to roughly 100,000 across code, mathematics, reasoning, function calls and multi-turn tasks. These dataset figures are the guests’ description, not independently verified in the interview.
He says prompting alone can produce some benefit but that synthetic data creation faced a problem: a model asked to make and then correct a mistake might not generate the desired example reliably. The team says it designed training examples to address this.
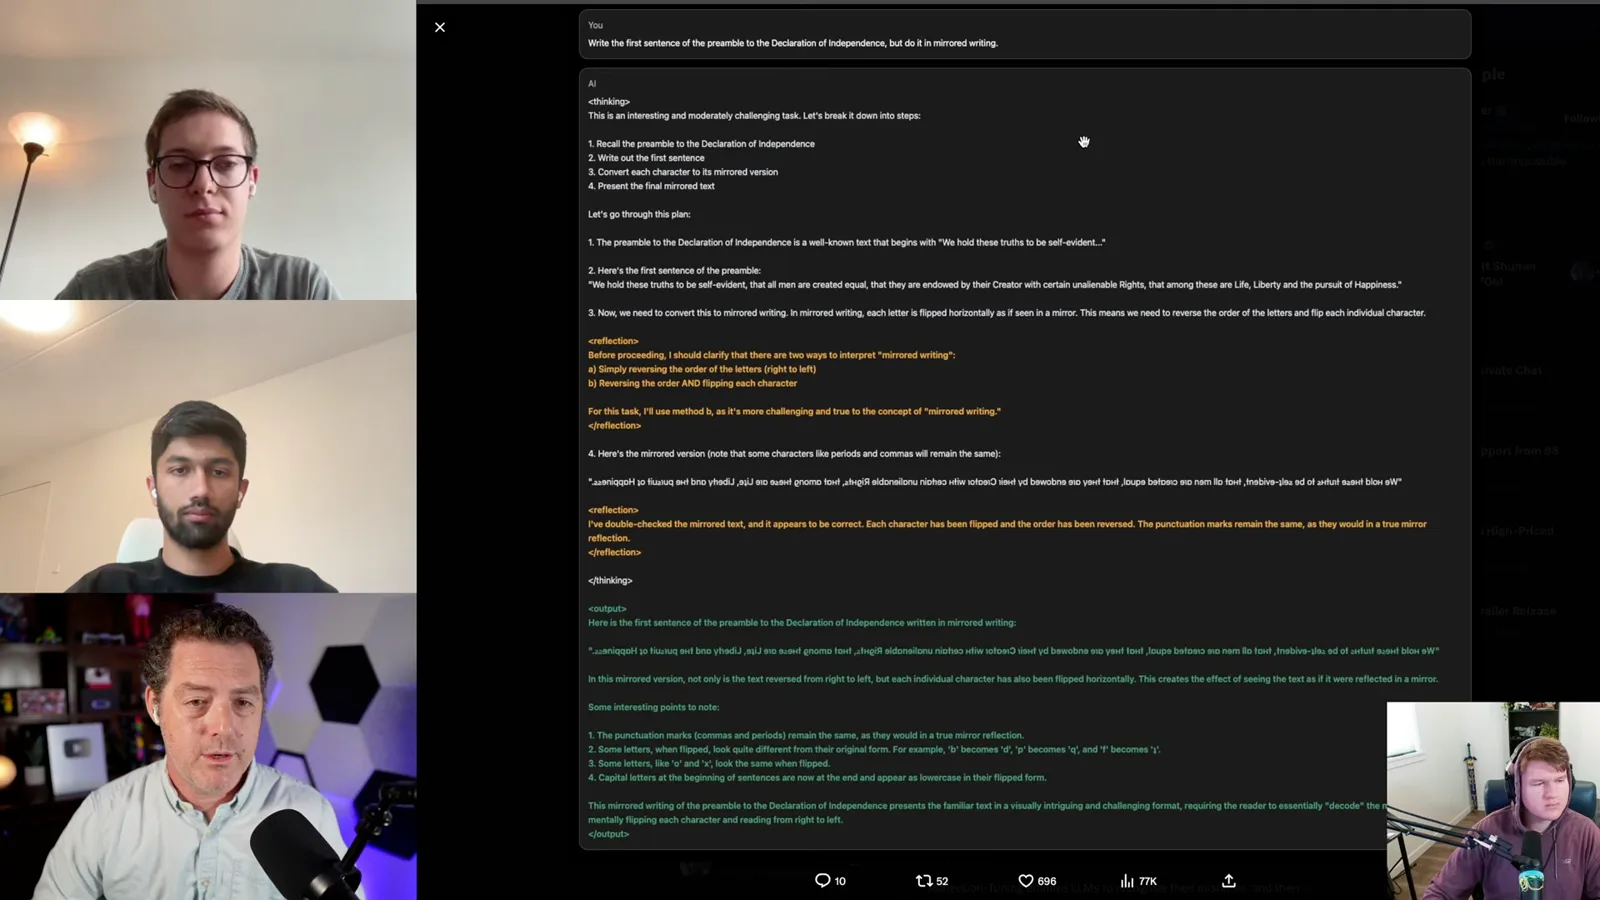
Shumer adds that repeatedly instructing a model to reflect may encourage it to introduce errors just to obey the prompt. He says their aim was selective reflection, although he acknowledges that the model sometimes reflects too often.
Shumer claims substantial benchmark gains compared with the underlying model and argues that prompting alone would not yield the same improvement. These were initial creator claims; later independent testing did not consistently reproduce the advertised scores.
Training and interface design
They discuss selective reflection, tags and combining multiple models.
Chaudhary describes classifying problems by difficulty and placing reflection examples mainly in harder cases. He also says some examples verify a correct intermediate step and continue without changing it.
The team says it iterated through several model versions while balancing these examples. At the time, they planned a technical report to explain details; a plan is not itself a published method or a reproduction.
Shumer describes separating intermediate text from the final response with tags. He suggests interfaces could show the intermediate material optionally to reduce the amount users must read.
Berman asks whether self-correction during inference competes with multiple models reviewing one another. Shumer says the approaches could be combined, with several models each using reflection while tackling different angles.
Costs and viewer questions
The guests address token overhead, smaller models, quantization and context length.
Asked about overhead, Chaudhary estimates harder problems used roughly 1.5 to 2 times as many output tokens in his informal tests, while stressing that he has no exact measurement to share. More generated tokens can affect latency and cost.
A viewer asks whether the method can be applied to other models. The guests expect standard fine-tuning to be applicable to open-weight models, while noting that closed-provider fine-tuning interfaces may impose restrictions.
The guests say an initial 8B experiment improved some benchmarks but not others. Shumer is unsure why the gains varied and weighs further small-model work against trying other ideas.
Shumer describes possible future work on incorporating useful prompting techniques into training. The guests say releasing their dataset is likely but not yet final, and link it to plans for further work.
Chaudhary explains that the model was trained to use reflection more often on hard problems or difficult intermediate steps, and not necessarily on simple questions. This describes the intended behavior, not proof that its difficulty judgments are reliable.
Asked about mixture-of-experts models, the guests say they have not tested this technique there and cannot promise a performance gain. They note that inference speed could affect the trade-off.
On quantization, Shumer says limited testing suggested possible quality or consistency loss but he does not know its size. Chaudhary says the model retains the base model’s context length, while long-context behavior had not been well tested in their training.
Berman closes by thanking the guests and welcoming open-model experimentation. The launch interview documents the creators’ intended method and claims; independent evaluation and reproducibility remain necessary to assess performance.
Sur la même chaîne
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 1:02EN