En 30 secondes
In a May 2026 livestream, Matthew Berman discusses reported cyber incidents, vulnerability research and the economics of AI-enabled attacks. He also offers speculative predictions about model strength and security; the discussion distinguishes those views from the reports he cites.
- 1A reported exploitGoogle described an exploit it believed was developed with AI and said counter-discovery may have prevented wider use.
- 2Vercel incidentBerman reads the CEO’s suspicion that AI accelerated the attackers; the tools used are not established in the stream.
- 3The stronger-model hypothesisBerman argues stronger defensive models should outperform weaker attackers, while viewers dispute the premise.
- 4A long tail of smaller targetsHe predicts that lower costs could make more low-value attacks profitable.
À retenir
- The livestream discusses Google’s assessment of a suspected AI-developed exploit and possible defensive counter-discovery.
- Supply-chain attacks and credential theft can create paths into wider environments.
- Berman’s stronger-model defense argument rests on assumptions that viewers challenge.
- He predicts lower attack costs could expose smaller targets to more attempts.
- Open-model availability has both legitimate defensive benefits and potential misuse risks.
Lire le texte remanié, chapitre par chapitre
Reported threats
Berman introduces the reported AI-assisted exploit and software supply-chain incidents.
I am concerned about reports of more frequent and severe cyberattacks, including the use of AI to speed operations or discover vulnerabilities. This May 2026 livestream combines reports with my own predictions, which should not be mistaken for established outcomes.
Google’s threat-intelligence team says it identified a threat actor using a zero-day exploit it believes was developed with AI. Google also says its own counter-discovery may have prevented a planned wider attack; the company’s assessment contains uncertainty.
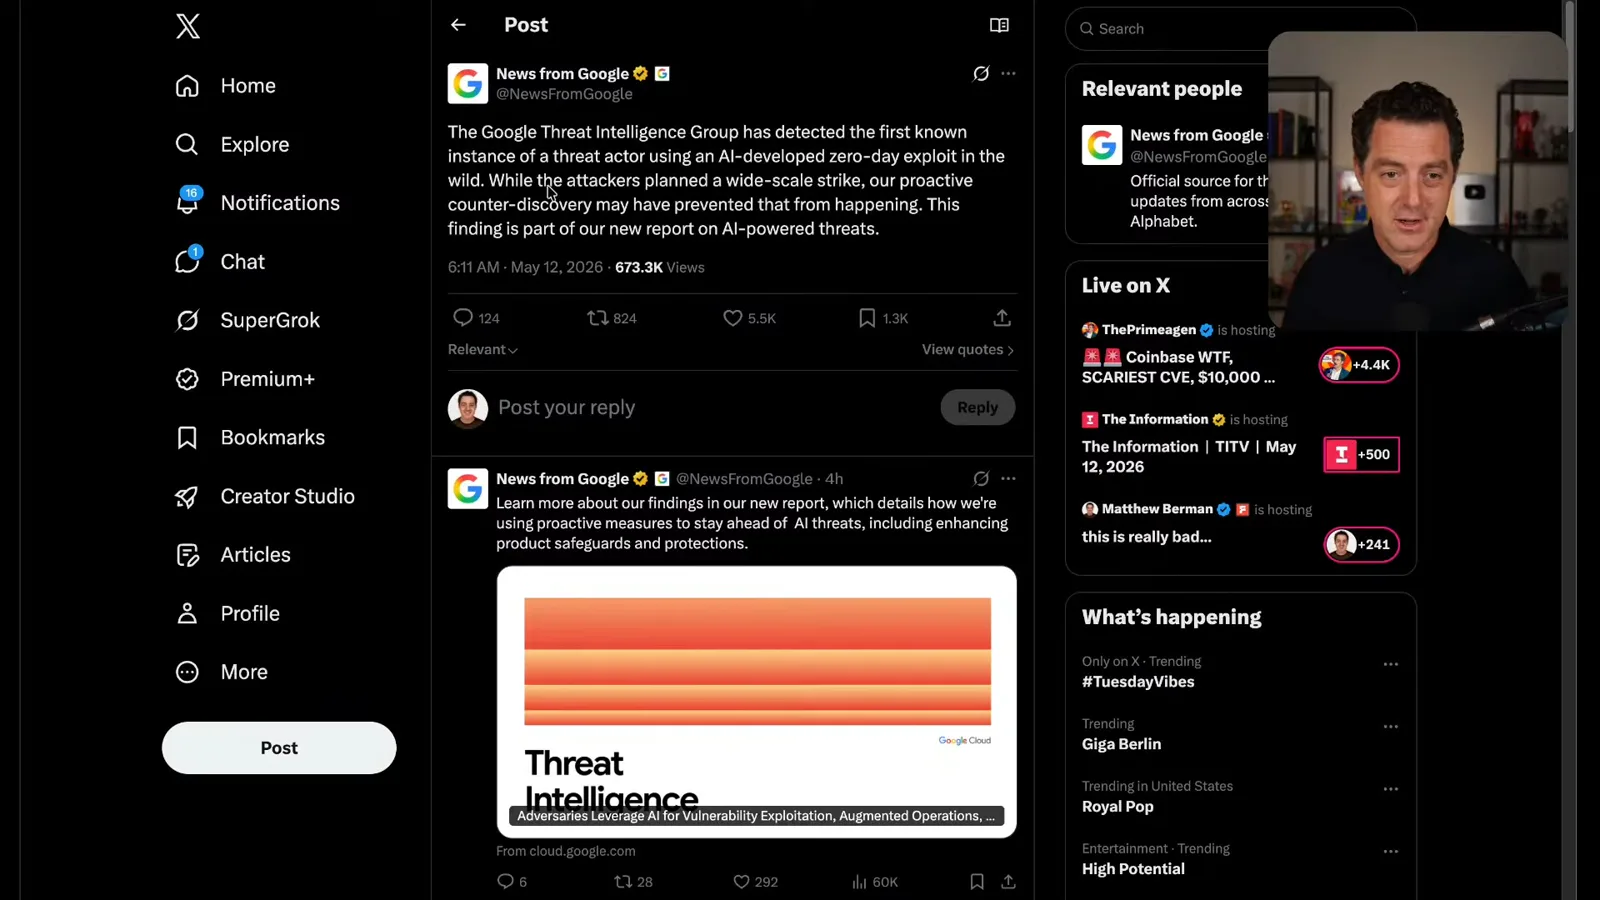
I explain that zero-day vulnerabilities can be valuable before a fix becomes available and that attackers may hold them for later use. Discovery, exploit development and actual exploitation are distinct events.
I then discuss reports about Shai-Hulud, a package supply-chain worm, and a separate report of a destructive response after a stolen token is revoked. I cite changing counts of affected packages from reports available during the stream rather than independently verifying every case.
I argue that more AI-generated code and less review of installed dependencies can expand exposure. I acknowledge that I often do not review much of my own generated code, while noting that my projects are comparatively small.
I discuss reported credential theft and worry that automation could increase the number and speed of attempts. The fact that an incident involved stolen credentials does not, on its own, establish exactly how much AI contributed.
I speculate that attackers may not be using the newest hosted models for all of their work because providers impose safeguards. I do not have evidence in the stream establishing which models are used in every attack.
Vercel and Google’s report
He reads incident updates and discusses AI in offensive and defensive workflows.
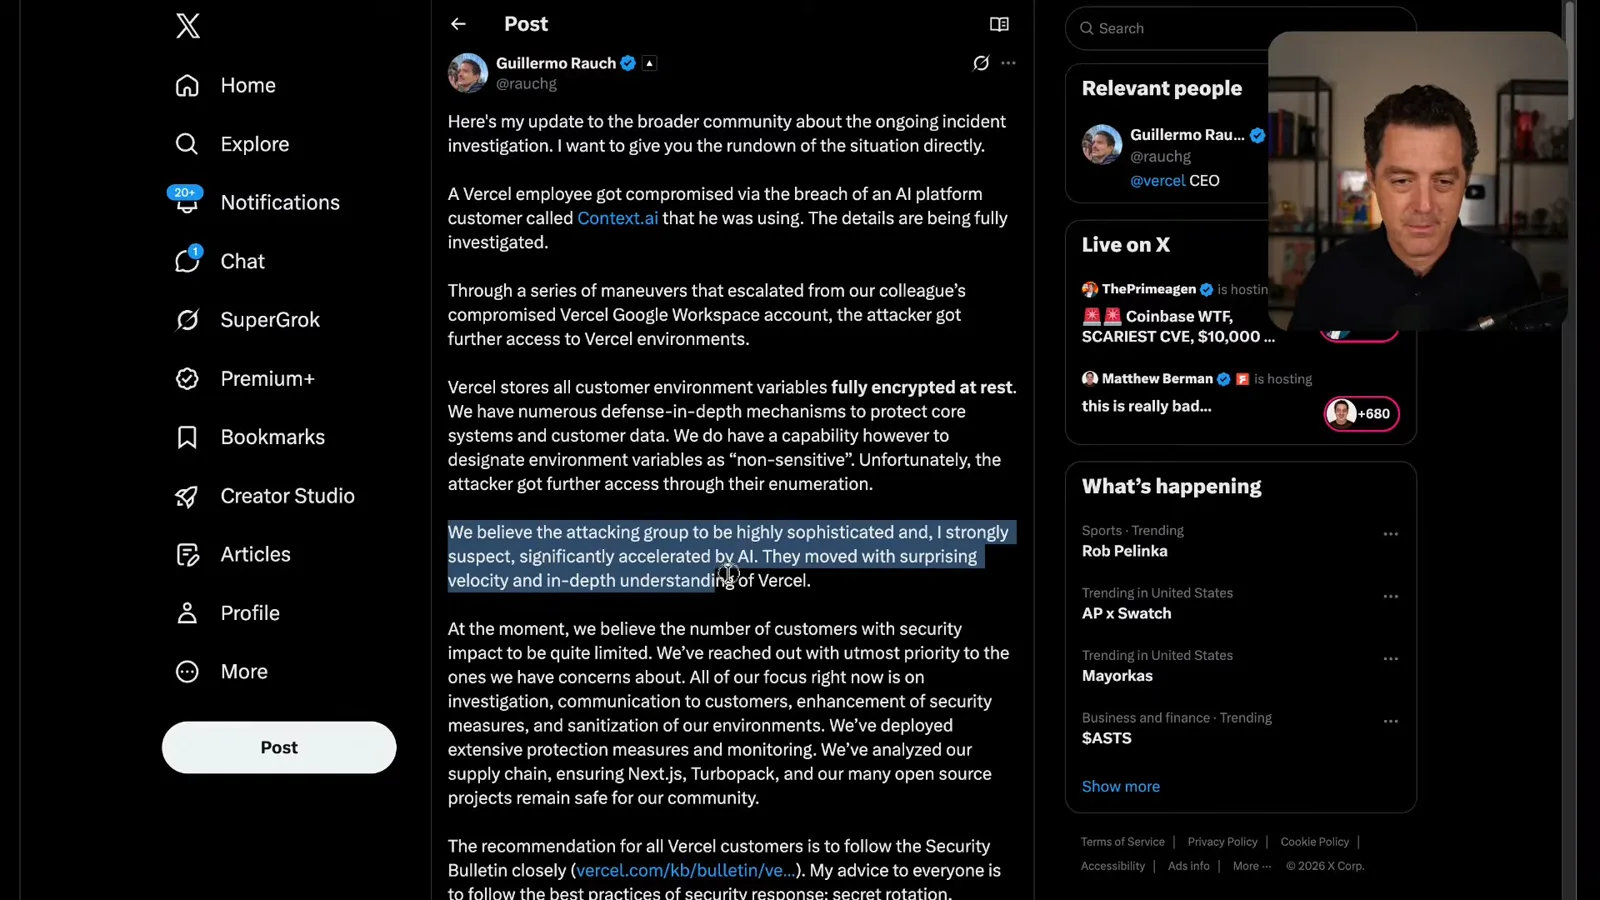
I turn to Vercel’s April 2026 incident and read the company’s public update. Its CEO said he strongly suspected AI accelerated the attackers; that is a stated suspicion, not proof of the exact tools used.
The update describes an employee compromise connected to a third-party service and subsequent access to Vercel environments. I praise the company’s communication while using the incident to discuss the possible speed of AI-assisted attacks.
Returning to Google’s report, I read its description of AI as both a tool for adversaries and a target. The report discusses vulnerability work, development of malware and threats to AI environments.
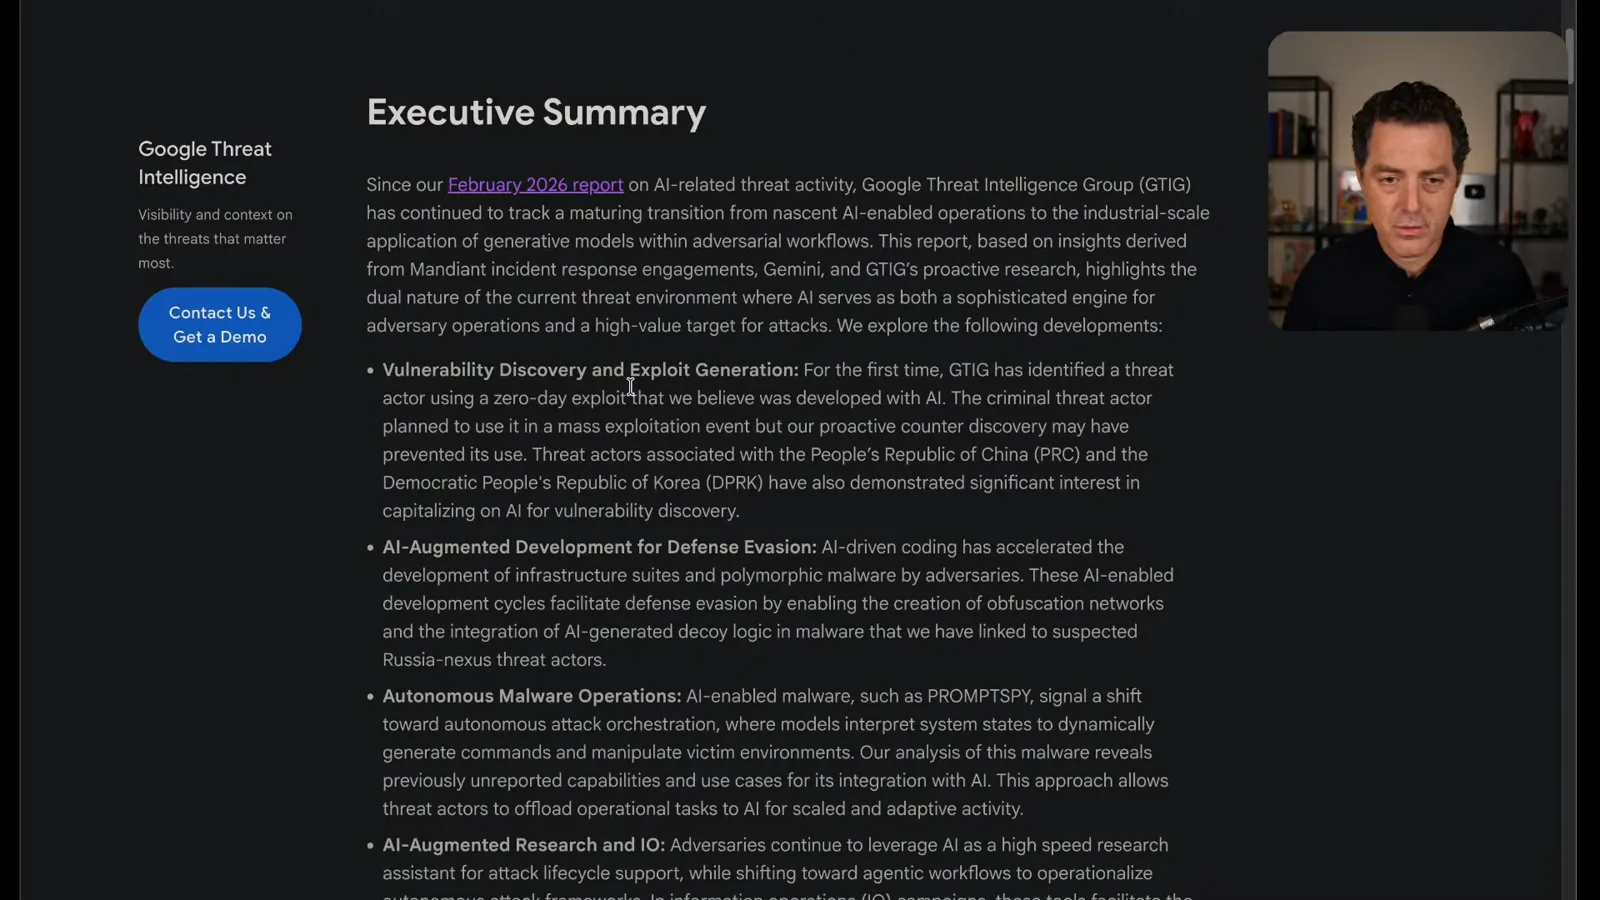
The report attributes an exploit-development case to AI with a stated degree of belief and says proactive discovery may have prevented mass use. I interpret it as a warning about the pace of vulnerability discovery, not a complete account of the incident.
I stress that many vulnerabilities already exist in code and can be found by either attackers or defenders. My broader statement that AI does not create vulnerabilities is too categorical: newly generated or modified code can also introduce flaws.
The report also describes AI-assisted development and defense evasion. I worry that faster software production can lower the effort needed to build malicious tools, while the reported cases and my general forecast should be kept separate.
I consider autonomous operation and locally run models. Running a model locally still requires hardware, electricity and maintenance; my point is that access may make some tasks cheaper or easier to repeat, not literally free.
Google’s report also discusses obscured access to hosted models and misuse of trial or account systems. I say I do not know how prevalent successful misuse is, particularly given provider detection and safeguards.
Supply-chain attacks can target dependencies and AI-related software as routes into a wider environment. I worry about their potential to spread, but the incidents I discuss differ and should not be treated as one identical attack.
This raises a difficult debate about open and closed models. I remain a supporter of open models but acknowledge that inexpensive, modifiable models can also be used by malicious actors.
Phishing and the future of vulnerabilities
He considers deepfakes and offers a speculative forecast for software security.
Beyond software intrusions, I discuss phishing and deepfakes. I recall a conversation with a Pindrop Security representative about detection and suggest that families agree on a way to verify unexpected urgent requests.
I share a prediction that AI will expose and help patch a very large number of vulnerabilities, eventually producing much safer software. I suggest a two-to-three-year horizon, but this is my speculative forecast, not an established result.
A viewer challenges the possibility that attackers will introduce new vulnerabilities. I respond by proposing that stronger defensive AI could find them, an argument that depends on assumptions about access, deployment and detection rather than a proven guarantee.
I question whether vulnerabilities will persist indefinitely and acknowledge that my ideas about perfect software are speculative. Later I clarify that I do not literally expect perfect software with zero vulnerabilities.
The stronger-model argument
Berman and viewers debate compute, human judgment and whether stronger models guarantee defense.
I summarize Jensen Huang’s “my AI versus your AI” framing and ask why a defender might have the stronger system. My proposed answer is economic: the most resource-intensive models may be easier for well-funded organizations or states to develop.
I argue that smaller criminal groups may have less access to compute and talent than large states. This is an economic argument, not proof that every defender will have a stronger model or that a weaker model cannot find a missed flaw.
I propose that if a stronger defensive model misses a vulnerability, a weaker attacker model would also miss it. Viewers challenge this with the possibility of better scaffolding, human judgment or creative combinations; the livestream does not resolve that disagreement.
A viewer suggests that a small model plus a person can still discover exploits. I disagree and emphasize model context and speed, though the relationship between model size, search strategy and results remains an open question here.
I reject a pure cold-war analogy because cyberattacks are already occurring. A conflict can be active in digital systems without being a conventional kinetic war.
Cyber models and defense products
He discusses Anthropic’s preview and OpenAI’s announced tools.
I turn to Anthropic’s Mythos preview and its limited-access approach. I criticize the company’s presentation, while also considering the argument that restricting a powerful cyber model could reduce misuse.
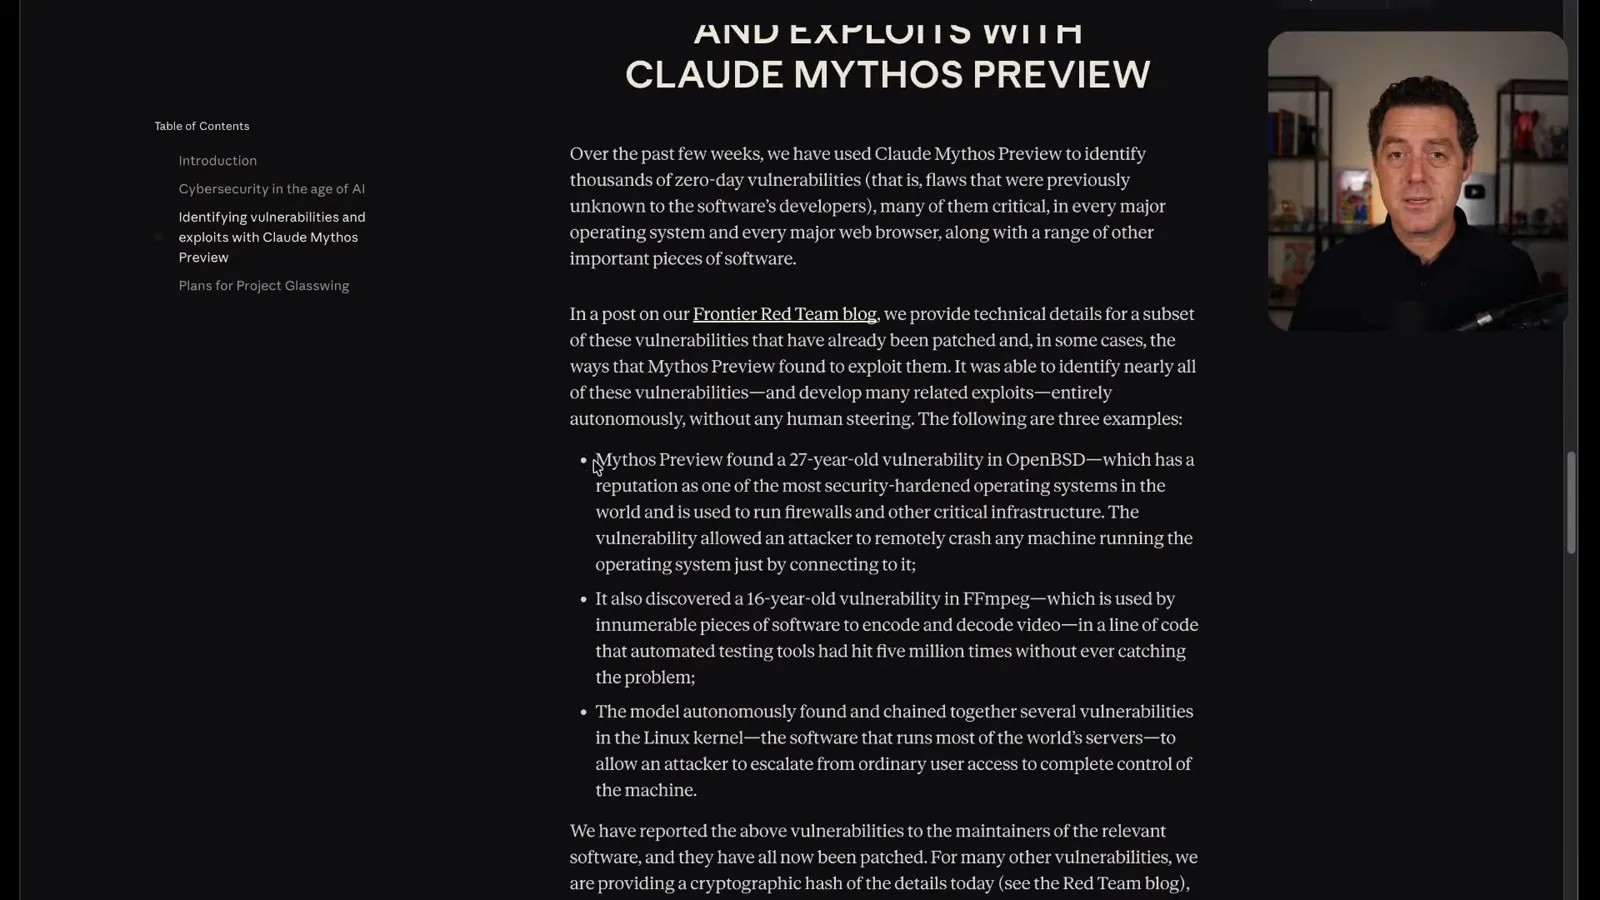
I read Anthropic’s examples of reported vulnerabilities in OpenBSD and FFmpeg and a chain involving the Linux kernel. These are company-reported research results from that period; the video does not independently reproduce them.
I compare the displayed CyberGym scores for Mythos preview and GPT-5.5 Cyber. The reported scores are close, but benchmark conditions and limited examples do not establish that the systems are equivalent in all real security work.
I discuss OpenAI’s Daybreak announcement, described as bringing together models, Codex and security partners for defense. I also recount an early Aardvark test in which a vulnerability report took longer than I expected.
I describe different levels of access and safeguards for general-purpose and authorized cyber work as presented at the time. Product access and policy can change, and my characterization of company approaches is an opinion.
Attack economics and open models
A hand-drawn sketch illustrates his concern about attacks on smaller targets.
A viewer challenges my assumption that the best models will always require enormous hardware. I do not agree with their forecast about highly capable models on a small device, but admit that my own answer about parallelism is speculative.
I argue that lower attack costs could make smaller targets profitable at scale, even if each target yields less money. I sketch an economic curve and note on air that my axes are confusing and may need to be swapped.
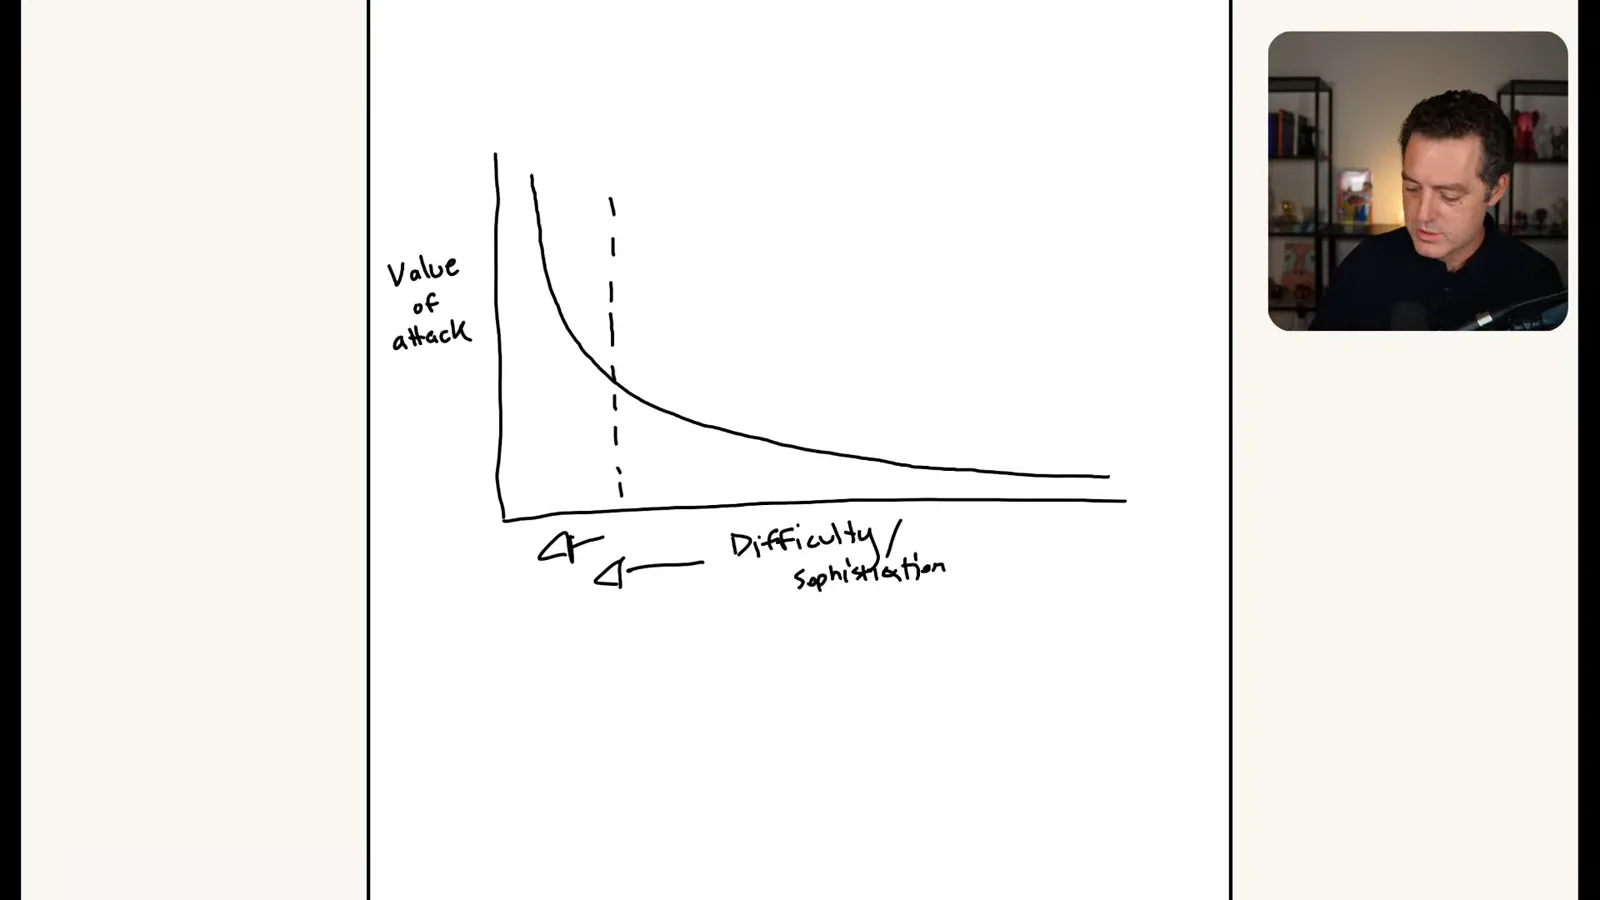
The long-tail argument is separate from my claim that better-funded defenders can use stronger models: many individuals and small organizations may not deploy those defenses at all. I worry this gap could leave them exposed.
I revisit the open-model trade-off: broad availability can support legitimate users and defenders, but also give malicious actors inexpensive tools. I remain in favor of open models while acknowledging this concern.
State competition and conclusions
He discusses geopolitical concerns and his preference for supporting open-model development.
I play part of a conversation involving Jensen Huang and summarize its competing-AI argument. The clip is illustrative of that viewpoint, not proof that an AI defender will always win.
I discuss competition between states and worry that well-resourced governments could develop strong offensive as well as defensive capabilities. I distinguish my preference for US leadership from hostility toward ordinary people in China.
I identify two concerns: lower-cost attacks against many smaller targets and competition between states with comparable resources. These are scenarios I consider plausible, not measured forecasts of their frequency.
Asked whether Chinese models should be banned, I say no and argue instead for supporting open-model development in the United States. That is my policy preference, and the stream closes without resolving the broader security debate.
Sur la même chaîne
 25:50EN
 32:20EN
 1:03:37EN
 0:22EN
 45:08EN
 0:32EN