En 30 secondes
Matthew Berman introduces AI21’s Jamba 1.5 and tests its Large model in AI21 Studio on coding, arithmetic, logic and language tasks. His experience is largely negative, although the small, informal sample and subjective or ambiguous questions limit what it can establish.
- 1AI21’s announcementThe company claimed long-context and speed advantages for its Mini and Large models; those claims depend on test conditions.
- 2A slow coding attemptBerman reports a long wait for a Tetris program, which did not run successfully in his test.
- 3Mixed puzzle resultsSeveral reasoning answers fail his checks, while the model correctly handles the strawberry and decimal questions.
- 4Limits of the evaluationThe North Pole prompt is ambiguous and the moral question reflects a value judgment, so neither is a clean objective benchmark.
À retenir
- AI21 described Jamba 1.5 as a hybrid state-space and Transformer model with a long context window.
- Berman observed a long wait and a nonworking Tetris attempt in one hosted session.
- The model missed several of his puzzles but correctly answered the strawberry letter count and decimal comparison.
- The moral question is subjective and the North Pole puzzle needs more precise assumptions.
- A single informal test cannot establish general model or architecture performance.
Lire le texte remanié, chapitre par chapitre
Jamba 1.5 and its architecture
Berman introduces AI21’s model family and its announced features. The discussion reflects a 2024 release.
I test AI21’s Jamba 1.5 Large after introducing the Jamba family and its hybrid state-space model and Transformer architecture. The video records one playground session in 2024, not a controlled benchmark of the architecture or later versions.
AI21 announced Mini and Large models with a claimed 256,000-token context window, long-context speed advantages and benchmark scores. It also described multilingual use, structured JSON, function calling and citations. These are the company’s claims and depend on the specified testing conditions.
The models were offered for download under the Jamba Open Model License and through several cloud services. I use AI21 Studio for this test. Availability, terms and model capabilities can change, so the announcement should be read in its historical context.
Tetris and reasoning tests
He tests code generation, an envelope problem and several logic puzzles. He reports long latency in his session.
I select Jamba 1.5 Large and ask it to write Tetris in Python. The output takes roughly 20 to 30 seconds to begin, and I say it continues for about seven minutes. A single session cannot establish general throughput or identify whether the delay came from the model, service or interface.
The generated code uses Pygame, but when I copy it into my editor and run it, nothing happens. I mark the attempt as a failure and do not iterate because of the wait. That is a useful observation about this particular attempt, not proof that every coding prompt will fail.
The next prompt asks whether a 200 by 275 millimeter envelope meets given postal size limits. The model says it does not; I believe rotating the envelope allows it to fit. The conclusion depends on the exact dimensional rules and how the sides are assigned.
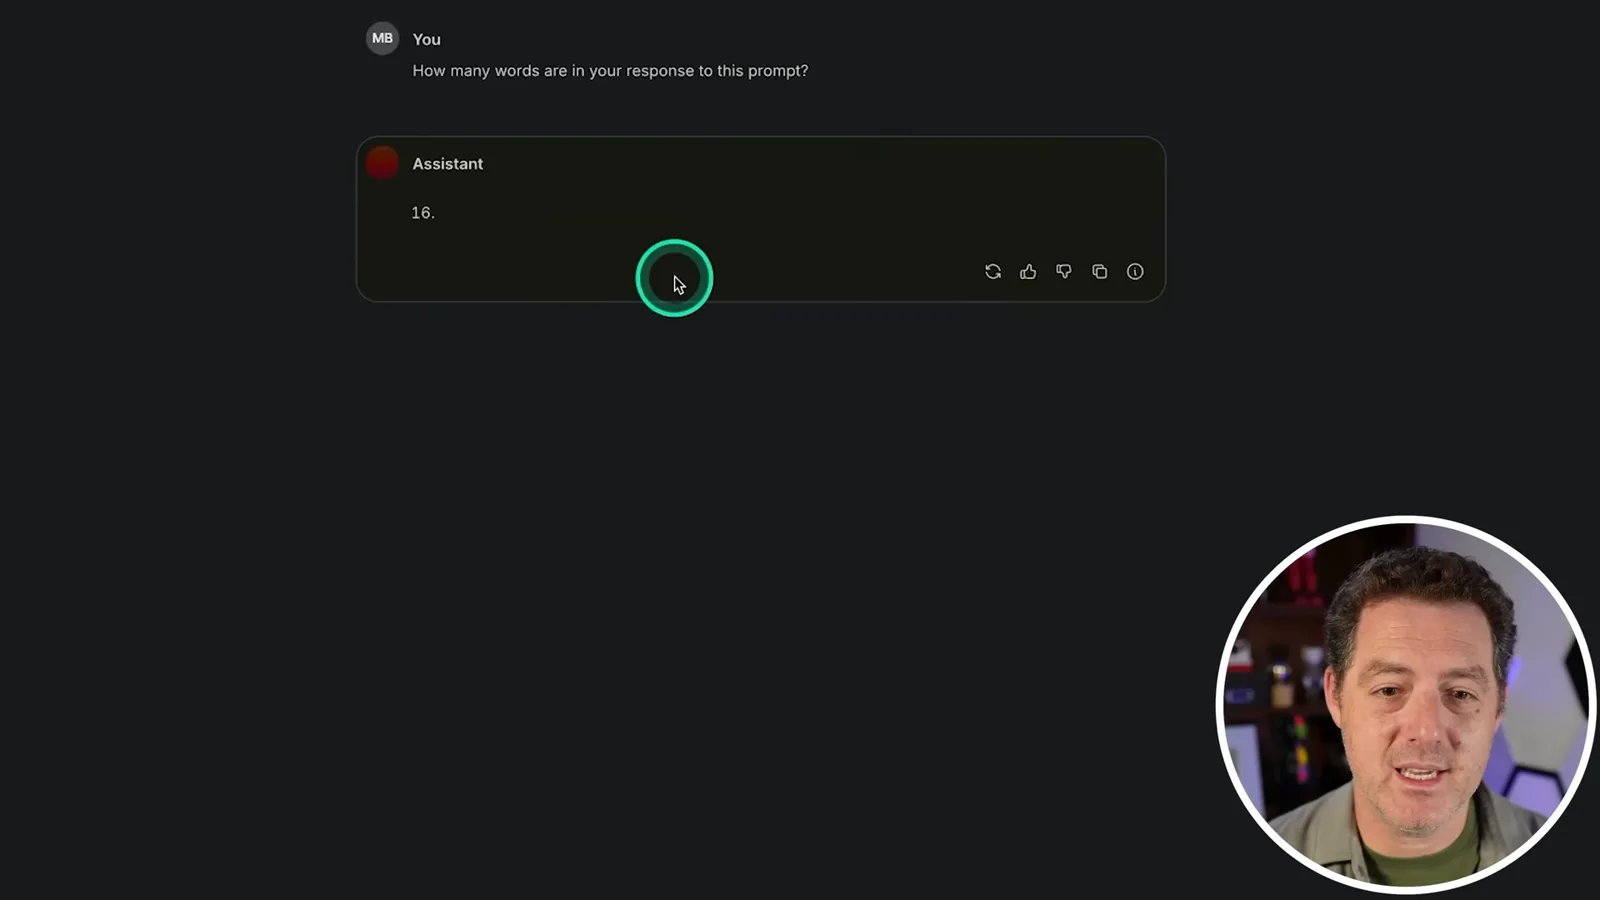
The model answers “16” when asked to count the words in its own response, and says two killers remain after a newcomer kills one of three. I mark both wrong: in the latter puzzle, the newcomer has also become a killer under the usual interpretation.
In the marble puzzle, the model reasons that a marble stays at the top of an inverted glass after the glass is lifted. I reject that answer: under the ordinary setup the marble falls onto the table and remains there when the glass is picked up.
I also ask a North Pole walking puzzle and disagree with the answer. The wording leaves the meaning of a straight path and passing the starting point open to interpretation, so the exchange is not a clean objective score without specifying those assumptions.
Language, arithmetic and judgment
The model gets some short tasks right and others wrong. Berman closes with a negative assessment of this informal session.
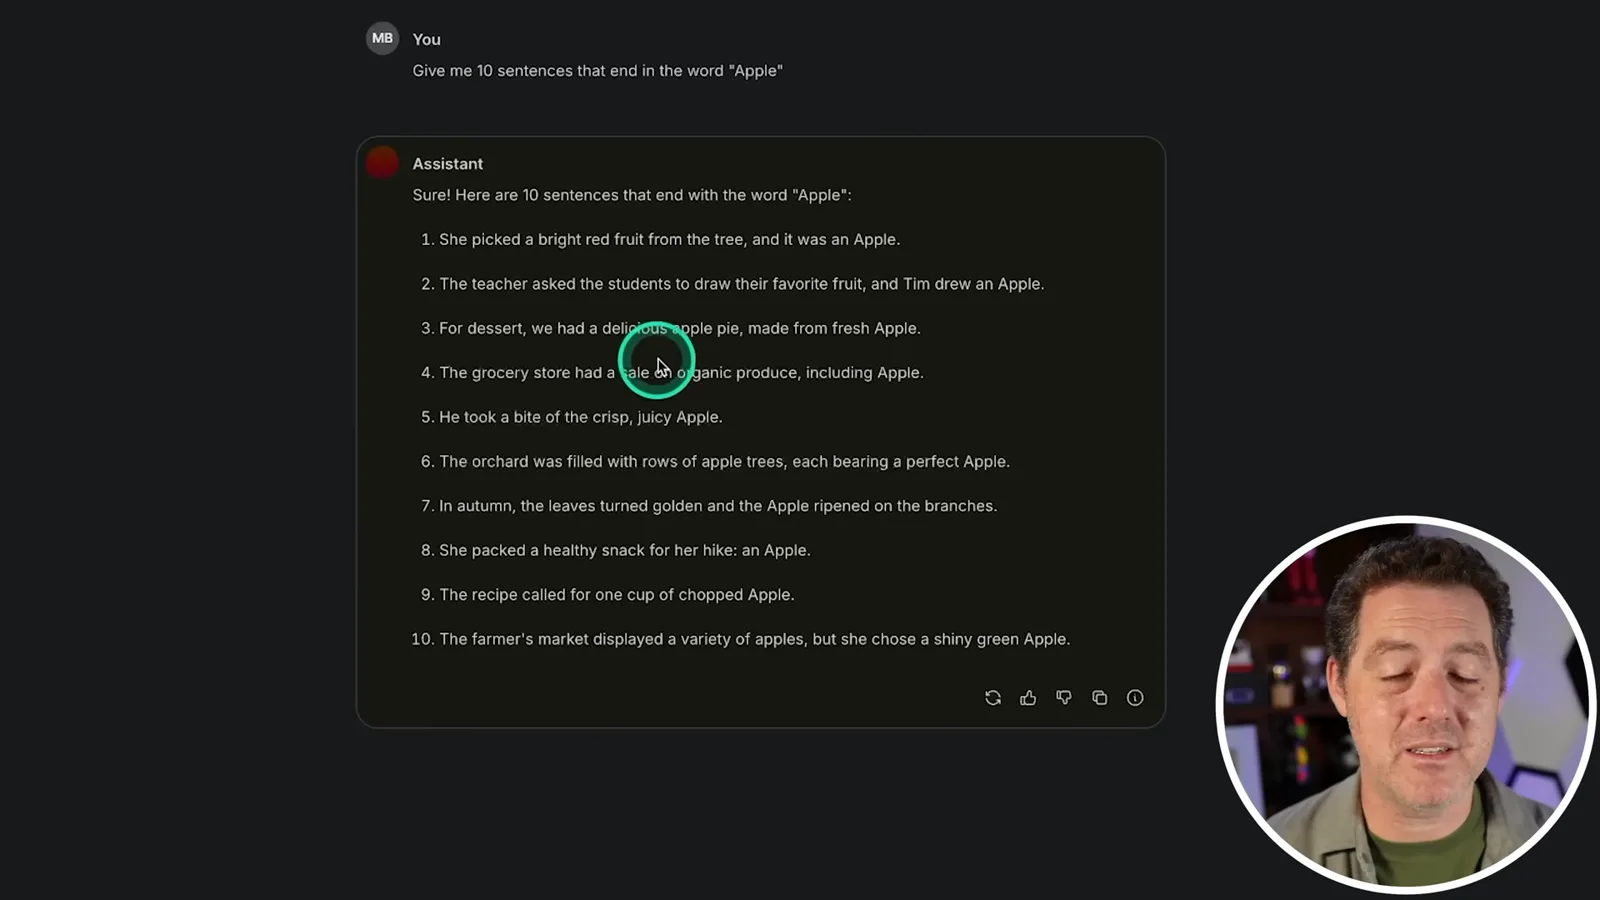
Asked for ten sentences ending in “Apple,” the model produces nine that meet the instruction and one that does not. It correctly counts three occurrences of “r” in “strawberry” and says 9.9 is greater than 9.11.
For a moral hypothetical about gently pushing someone to save humanity, the model eventually answers no. I disagree but acknowledge that the grade reflects my own ethical judgment; this is not an objective pass-or-fail measurement.
I conclude that this test session was disappointing, while welcoming competition among model architectures. The small set of prompts and one hosted session support a limited observation, not a general verdict on Mamba or all Jamba deployments.
Sur la même chaîne
 25:50EN
 32:20EN
 45:08EN
 0:32EN
 12:14EN
 10:36EN