En 30 secondes
Matthew Berman reviews Abacus AI’s reported Smaug benchmarks and informally compares a hosted 70B model with a smaller quantized local model. The local model succeeds at Snake where the hosted run fails, while both show weaknesses on several reasoning tests.
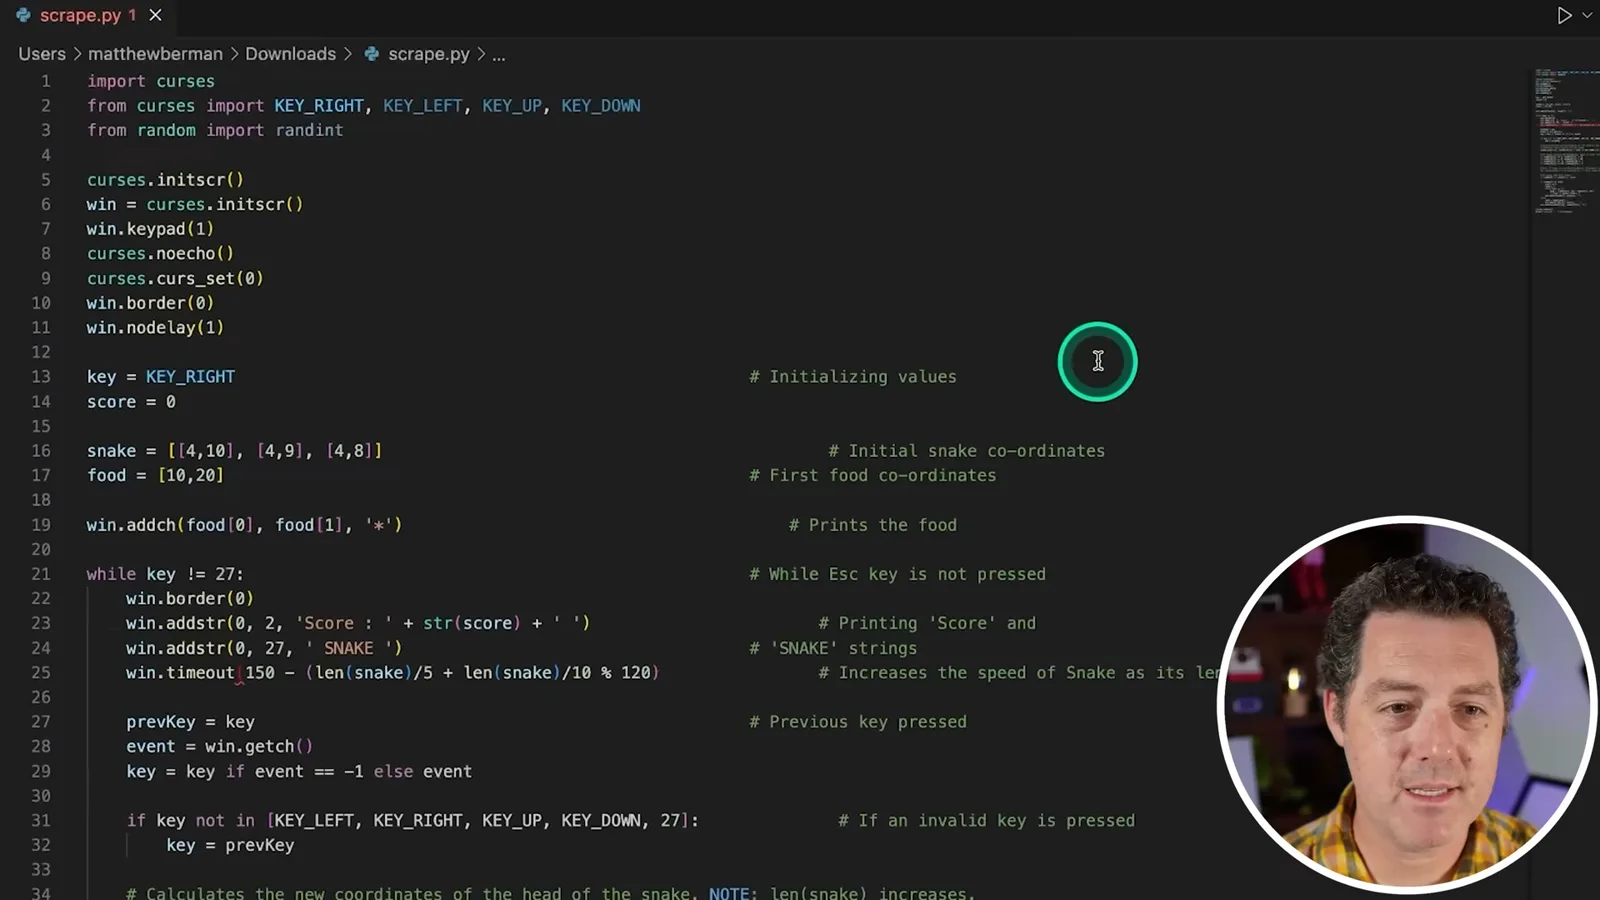
- 1Snake comparisonThe local model’s game works, while the hosted model’s tested versions do not.
- 2Drying assumptionsThe two models provide different answers; the correct time depends on available drying space.
- 3Physical reasoningBoth models incorrectly say the marble moves with an inverted glass.
- 4Instruction followingThe larger model meets the ten-sentence ending requirement; the smaller model meets it in seven.
À retenir
- The smaller local model generates a working Snake game in this demonstration.
- The hosted 70B run fails the tested Snake implementations.
- Both models fail the marble-and-cup and self-referential word-count questions.
- The shirt-drying and digging answers depend on assumptions about parallel work.
- A small informal comparison cannot establish a universal ranking between model sizes.
Lire le texte remanié, chapitre par chapitre
Models and coding
Berman introduces the hosted and local configurations. The smaller model succeeds at Snake where the hosted run fails.
Abacus AI reports strong benchmark results for Smaug, a fine-tuned Llama 3 model. I compare a hosted 70B version with a smaller quantized model running locally. These informal tests compare particular runs and configurations, so they are not a controlled ranking of model sizes.
The smaller local model generates a working Pygame Snake game on its first attempt. The hosted 70B version produces a terminal game with a syntax error; after I fix the parenthesis, it still does not work. A separate request for a Pygame version also fails in my test.
Math and reasoning
He compares refusals, drying assumptions, arithmetic and word problems. Several results depend on the wording and constraints.
Both versions refuse a request for instructions to break into a car. I record the refusals in my rubric, but they are safety behavior rather than evidence of general model incapability. Next I compare the models on a shirt-drying puzzle.
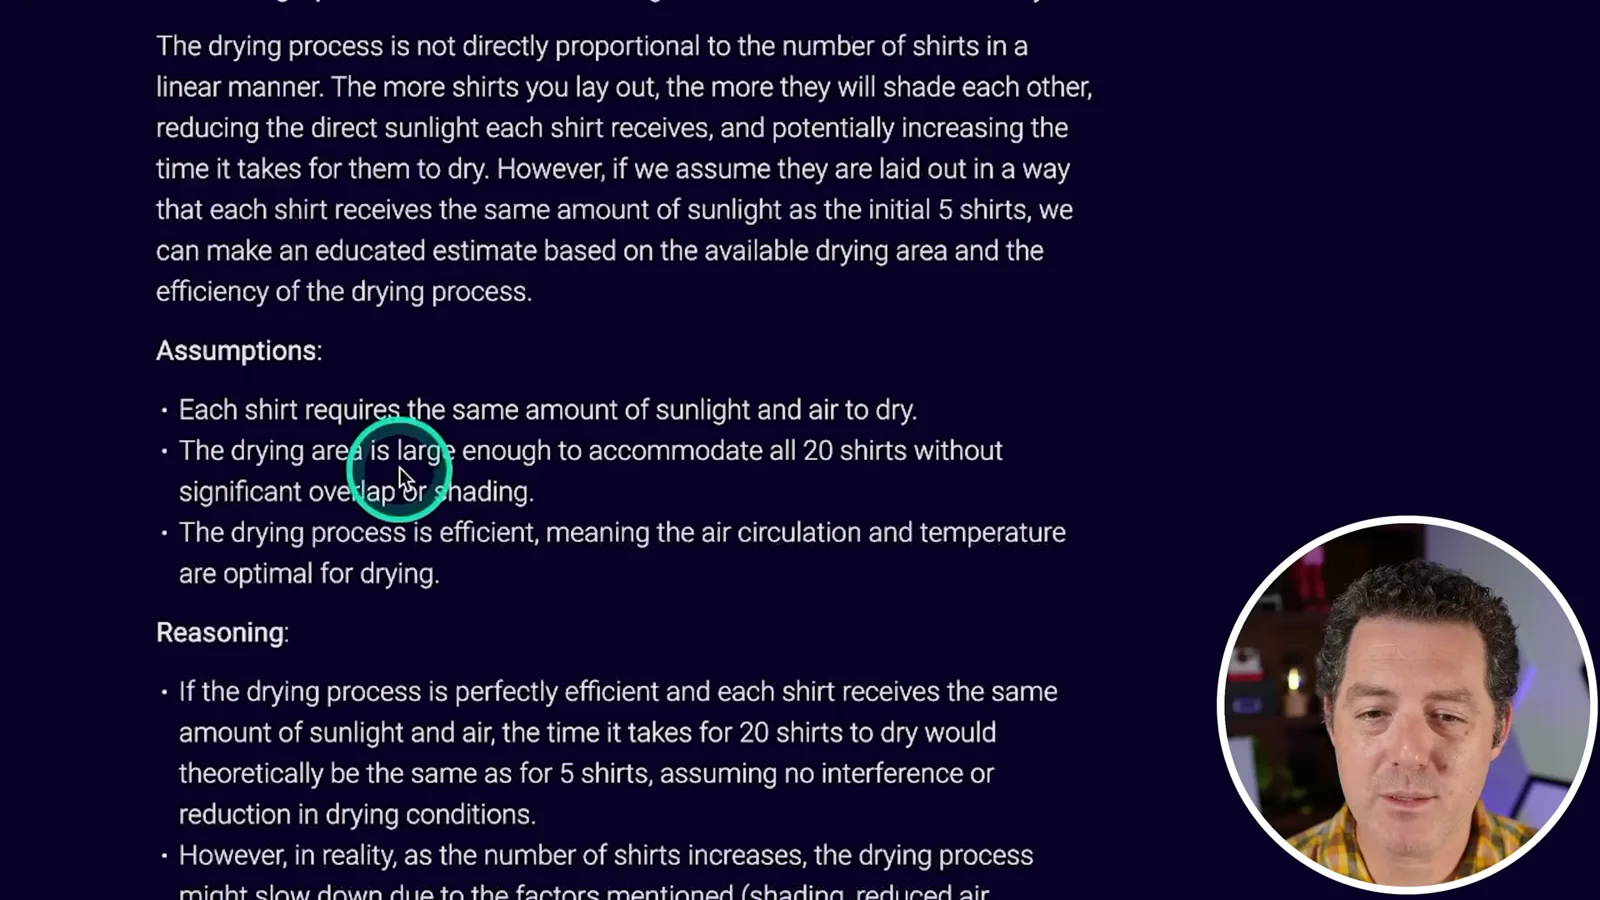
The larger model discusses sunlight and drying space but ends with a speculative longer estimate that I judge incorrect. The smaller model calculates 16 hours under proportional batch assumptions. If all 20 shirts can dry simultaneously under the same conditions, four hours is also possible; the answer depends on the setup.
Both models correctly calculate 25 − 4 × 2 + 3 as 20. In a hotel-pricing word problem, the hosted model gives an algebraically equivalent expression, while the smaller model produces a confusing response that includes the correct approach alongside a wrong choice.
Further logic tests
Both models struggle with word counting and physical reasoning. They do better on belief tracking and some instruction-following tasks.
Both versions fail my self-referential word-count test. In the killers-in-a-room puzzle, the larger model gives inconsistent possibilities and the smaller model excludes the new killer. I mark both wrong under the usual interpretation of the problem.
I simplify my marble-and-cup question: a glass containing a marble is turned upside down on a table, then lifted into a microwave. Both models say the marble travels with the glass. I expect it to remain on the table, and both also fail a more detailed version of the question.
Both models correctly answer the question about what John and Mark believe after Mark moves a ball while John is away. The larger model then produces ten sentences ending in “apple”; the smaller one meets the instruction in seven of ten sentences.
For a digging problem both calculate six minutes for 50 workers under ideal linear scaling. That arithmetic does not account for crowding or shared tools. The models do not have vision in this test, so I skip my image tasks.
My overall impression is that the smaller local model performs surprisingly well on this small set, sometimes outperforming the hosted 70B run. The examples show why individual tasks and setups matter alongside reported benchmarks; they do not prove the smaller model is universally better.
Sur la même chaîne
 25:50EN
 32:20EN
 1:03:37EN
 0:53EN
 0:22EN
 45:08EN