En 30 secondes
3Blue1Brown explains how Claude Shannon moved from counting short letter sequences to human prediction experiments. The resulting estimate connects English’s compressibility with the ability to predict what comes next.
- 1Prediction and compressionShannon linked the compressibility of English to the probabilities of its next characters.
- 2A human language modelBetty Shannon guessed letters from a passage, allowing correct guesses to be replaced by dashes.
- 3Counting guessesShannon expanded the experiment by recording how many guesses people needed and used the results to estimate probabilities.
- 4An estimate of one bitWith at least 100 characters of context, he estimated English might in principle be compressed to around one bit per character.
À retenir
- A predictable next character carries less new information and can be compressed more efficiently.
- Counting short sequences cannot reliably measure the predictive value of long contexts that rarely recur in a sample.
- Shannon used human guesses to estimate probabilities and suggested English could approach one bit per character given substantial context.
- Modern compression can use engineered predictive models rather than only measuring human prediction.
Lire le texte remanié, chapitre par chapitre
From letter counts to human prediction
Short-sequence statistics become sparse as context grows. Shannon turned to a human predictor to explore the information in longer contexts.
Claude Shannon connected the compressibility of English to how predictable its text is. His early experiments counted which characters followed short sequences: for instance, scanning books for every occurrence of “TH” and tabulating what came next.
That approach breaks down for long sequences, especially ones that never appear in the sample. Yet longer sequences provide more context, making the next character more predictable and the text more compressible. Shannon therefore needed another way to investigate those probabilities.
He turned to a language model available to him in the 1940s: his wife, Betty. As the story goes, he asked her to predict each new letter in a passage. When she guessed wrong he wrote down the correct letter; when she guessed right, he put a dash. The resulting string had fewer letters but, given a duplicate of the same predictor, could still be used to reconstruct the text.
This was a start, but Shannon’s formal definition of information required the probabilities assigned to the next letter. In his paper “Prediction and Entropy of Printed English,” he described experiments with more people that recorded how many guesses each needed to find the correct letter. He combined the number of guesses with short-sequence statistics to estimate the probabilities implicit in their predictions.
Estimating entropy from guesses
Shannon recorded the number of guesses needed and combined that information with short-sequence statistics. The estimate suggests a connection between compression and intelligent prediction.
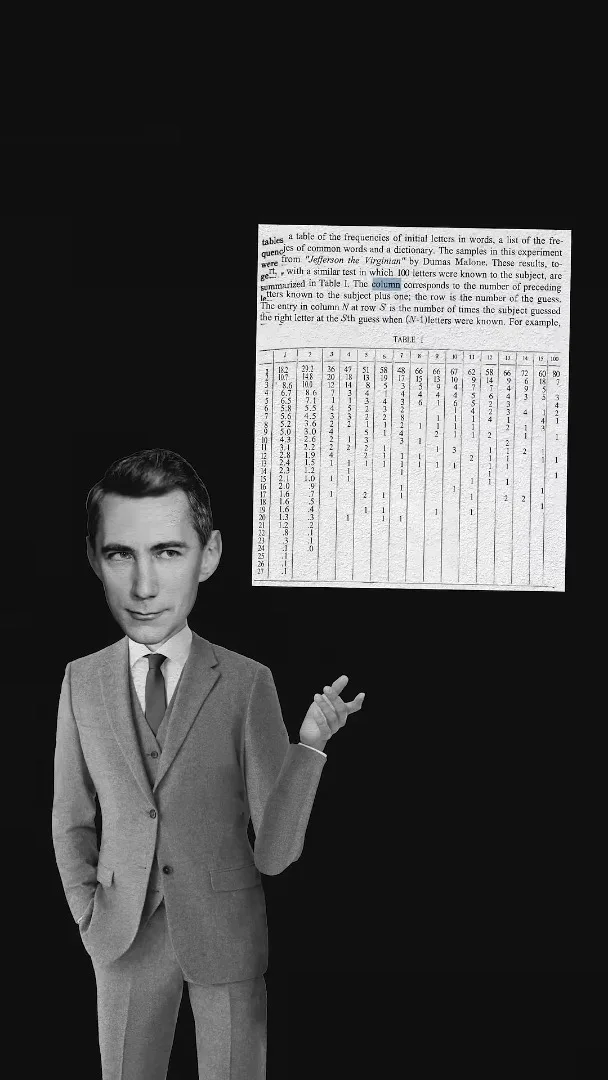
Given at least 100 characters of context, Shannon estimated that English might in principle be compressed to around one bit per character. To make that estimate he had to go beyond simple data analysis and probe something intelligent. Today, the speaker argues, compression near this limit involves trying to engineer predictive intelligence; this clip comes from a longer series exploring that connection.
Sur la même chaîne
 40:44EN
 3Blue1Brown· 16 oct. 2026Grant Sanderson: There's never been a better time to go into mathGrant Sanderson, Constantin Kogler · 3Blue1BrownStudents fear AI has solved mathematics. Grant Sanderson argues the opposite: even if machines prove theorems better than we do, the institution of math stays valuable—and this is a rare moment when newcomers can reshape it.
 51:55EN3Blue1Brown· 18 sept. 2026The last IMO problem AI could not solveGrant Sanderson · 3Blue1BrownGrant Sanderson walks through IMO 2025 Problem 6 — a tiling puzzle that frontier models missed — and the visual patience it takes to prove a construction is optimal.
 0:55EN3Blue1Brown· 24 juil. 2026The 64 Sugar Cubes Puzzle: Six Equal DistancesA 4×4×4 block has three colors; prove that six same-colored pairs share a distance.
 1:02EN3Blue1Brown· 10 juin 2026A Robot Walk and the Puzzle of Optimal Binary EncodingHow few bits does it take to send directions that occur with unequal frequencies?
 32:19EN3Blue1Brown· 7 juin 2026Reinventing Entropy: Why Prediction Helps Compress LanguageA robot’s movement code leads from prefix-free encoding to Shannon information and the entropy of language.
 0:48EN3Blue1Brown· 25 mars 2026The Subset Sum Puzzle: Who Has a Winning Strategy?Choose ten integers from 1 to 100, then look for two different subsets with the same sum.