








Résultats
64 articlesTrier
 2:00:51EN
 Cognitive Revolution "How AI Changes Everything"· 10 oct. 2026PodcastResample Every Token and You Can Watch the Model DecideAnime : Nathan LabenzGoodfire's Eric Bigelow on forking paths, in-context learning, and why chain-of-thought monitoring is getting harder to trust.
 51:55EN
 3Blue1Brown· 18 sept. 2026The last IMO problem AI could not solveGrant Sanderson · 3Blue1BrownGrant Sanderson walks through IMO 2025 Problem 6 — a tiling puzzle that frontier models missed — and the visual patience it takes to prove a construction is optimal.
 1:53EN
 Matthew Berman· 8 juil. 2026What Anthropic’s J-Space Research Suggests About AI ReasoningMatthew Berman · Forward FutureMatthew Berman discusses internal model representations, interventions and the question of consciousness, while the research itself describes important limits.
 36:19EN
 No Priors: AI, Machine Learning, Tech, & Startups· 26 juin 2026Podcast · 2 voixThe Benchmark Grid Is Broken: Why Test-Time Compute Has Outrun How We Score ModelsAnime : Sarah Guo, Elad GilOpenAI researcher Noam Brown argues that static leaderboards hide how long a model is allowed to think — and that safety evals, research taste, and the release cycle have not caught up.
 1:34:29ENCognitive Revolution "How AI Changes Everything"· 18 févr. 2026PodcastThree IMO Golds Missed the Same Problem. Harmonic Wants Math to CompileAnime : Nathan LabenzVlad Tenev and Tudor Achim built Aristotle to emit Lean proofs a kernel can check—and they argue that is how mathematical superintelligence stays trustworthy.
 1:16:21ENNo Priors: AI, Machine Learning, Tech, & Startups· 8 janv. 2026Podcast · 2 voixJensen Huang’s Year-End Case That Token Costs Can Fall a Billion-Fold Without Killing JobsAnime : Sarah Guo, Elad GilOn No Priors, NVIDIA’s CEO uses radiology, open source, and a $2 trillion R&D budget to argue that 2025’s extremes missed the stack.
 7:49ENMatthew Berman· 2 déc. 2025DeepSeek V3.2: Reasoning, Sparse Attention and Agent TrainingMatthew Berman · Forward FutureMatthew Berman examines DeepSeek’s December 2025 model release, its benchmark results and the techniques used to improve long-context efficiency and tool use.
 18:59ENNo Priors: AI, Machine Learning, Tech, & Startups· 31 oct. 2025Podcast · 2 voix86 Out of 100: The Clips No Priors Could Not Leave on the Cutting-Room FloorAnime : Sarah Guo, Elad GilSarah Guo and Elad Gil stitch nine 2025 conversations into one short tour of legal AI, spatial intelligence, jobs, deterrence, and a doctor who made it home for dinner.
 1:39:05ENCognitive Revolution "How AI Changes Everything"· 29 oct. 2025PodcastThe Summer GPT-5 Disappointed Does Not Mean AI Progress Has StalledAnime : Nathan LabenzNathan Labenz tells Erik Torenberg why the GPT-5 backlash mixed up product mishaps, naming chaos, and a real jump in capabilities.
 13:53ENMatthew Berman· 10 oct. 2025Tiny Recursive Models and the Limits of Puzzle Benchmark ComparisonsMatthew Berman · Forward FutureMatthew Berman examines a small recursive network that reports strong ARC and Sudoku results, and what its experimental setup means.
 36:58ENNo Priors: AI, Machine Learning, Tech, & Startups· 9 oct. 2025Podcast · 2 voixSTaR's Author Wants Models With EQ, Not Just More IQAnime : Sarah Guo, Elad GilEric Zelikman, the Stanford and xAI researcher behind STaR and Quiet-STaR, launches humans& on the bet that three years of IQ scaling left models emotionally unintelligent.
 13:30EN3Blue1Brown· 17 août 2025How AlphaGeometry Combines Logical Proof with Creative ConstructionAleph0Aleph0 explains how a symbolic geometry solver gets surprisingly far without AI, and how a language model supplies the auxiliary constructions that take it to Olympiad level.
 30:11EN
 Sequoia Capital· 30 juil. 2025PodcastFrom 12 Percent on AIME to IMO Gold in Two MonthsAlex Wei, Sheryl Hsu, and Noam Brown tell Sequoia's Sonya Huang how a three-person OpenAI sprint used general-purpose reinforcement learning, not Lean, to reach gold-level on the 2025 International Mathematical Olympiad.
 48:51ENSequoia Capital· 17 juin 2025PodcastThe Breakthroughs for AGI Are Already Done, Says OpenAI’s Former Research HeadBob McGrew tells Sequoia’s Training Data that 2025 is the year of reasoning, agents will be priced at the cost of compute, and nothing fundamental will be added to the stack by 2035.
 11:38ENMatthew Berman· 12 juin 2025AI News in June 2025: Magistral, Voice Models and Image GenerationMatthew Berman · Forward FutureMatthew Berman reviews Mistral’s reasoning models, voice and browser updates, reports on Meta and Scale AI, and FLUX.1 Kontext.
 22:05ENMatthew Berman· 9 juin 2025Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 10:09ENMatthew Berman· 30 mai 2025DeepSeek R1 0528: Benchmark Gains and Two Coding TestsMatthew Berman · Forward FutureMatthew Berman examines the May 2025 DeepSeek reasoning-model update, comparing reported benchmark gains with his own Rubik’s Cube and Snake programming tests.
 15:13ENMatthew Berman· 10 mai 2025Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 38:10ENNo Priors: AI, Machine Learning, Tech, & Startups· 1 mai 2025Podcast · 2 voixo3 should wait exactly as long as the answer takesAnime : Sarah Guo, Elad GilOpenAI researchers Eric Mitchell and Brandon McKinzie tell No Priors why o3's leap is a chain of tools during reasoning — and why you should send the same prompt a hundred times.
 14:04ENMatthew Berman· 29 avr. 2025Qwen3: Open Weights, Adjustable Reasoning and Tool UseMatthew Berman · Forward FutureMatthew Berman reviews the April 2025 Qwen3 family, its benchmark claims, training pipeline and local demonstration.
 19:06ENMatthew Berman· 25 avr. 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 15:15ENMatthew Berman· 19 avr. 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
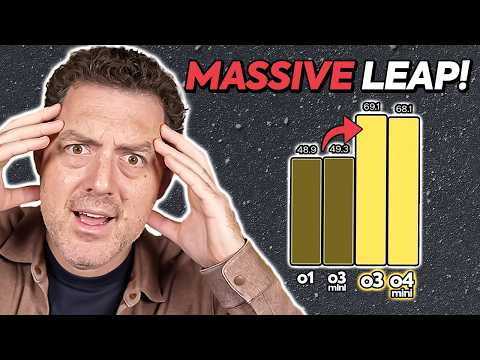 15:46ENMatthew Berman· 16 avr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 1:14:11ENCognitive Revolution "How AI Changes Everything"· 5 avr. 2025PodcastThe Reasoning Curve Was Smooth All Along: Gemini 2.5's Jack Rae on Thinking, Memory, and AGIAnime : Nathan LabenzDeepMind's thinking-and-inference lead explains why RL-for-reasoning felt sudden, why Gemini shows raw chain of thought, and why a million-token window still is not memory.
Charger plus24 sur 64 affichés