








Résultats
16 articlesTrier
 11:38EN
 Matthew Berman· 12 juin 2025AI News in June 2025: Magistral, Voice Models and Image GenerationMatthew Berman · Forward FutureMatthew Berman reviews Mistral’s reasoning models, voice and browser updates, reports on Meta and Scale AI, and FLUX.1 Kontext.
 22:05ENMatthew Berman· 9 juin 2025Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 10:09ENMatthew Berman· 30 mai 2025DeepSeek R1 0528: Benchmark Gains and Two Coding TestsMatthew Berman · Forward FutureMatthew Berman examines the May 2025 DeepSeek reasoning-model update, comparing reported benchmark gains with his own Rubik’s Cube and Snake programming tests.
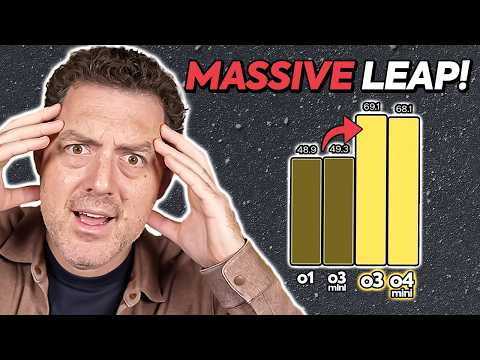 15:46ENMatthew Berman· 16 avr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 9:35ENMatthew Berman· 25 févr. 2025Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 13:24ENMatthew Berman· 18 févr. 2025Grok 3’s 2025 Launch: Benchmarks, Reasoning and DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman reviews xAI’s launch charts, a historical user-preference leaderboard and an early product demonstration.
 18:05ENMatthew Berman· 16 févr. 2025OpenAI’s Coding-Competition Study: o1-ioi, o3 and the Limits of the ResultsMatthew Berman, Sam Altman · Forward FutureMatthew Berman interprets OpenAI’s 2025 paper on reinforcement learning and programming contests. The results are strong on the studied benchmarks, but do not establish AGI or remove humans from model development.
 9:58ENMatthew Berman· 31 janv. 2025OpenAI o3-mini Launch: Reasoning Effort, Benchmarks and a Snake TestMatthew Berman · Forward FutureIn January 2025, Matthew Berman reviews OpenAI’s reported results and tries two coding examples with different reasoning settings.
 15:10ENMatthew Berman· 22 janv. 2025DeepSeek R1 Tested on Coding, Reasoning and Sensitive QuestionsMatthew Berman · Forward FutureMatthew Berman runs the full R1 model on cloud GPUs and tries game programming, reasoning puzzles and politically sensitive prompts.
 26:23ENMatthew Berman· 20 déc. 2024OpenAI’s o3 Announcement: Benchmark Gains and the Question of AGIMatthew Berman, Sam Altman, Mark Chen, Greg Kamradt, Hongyu Ren · Forward FutureMatthew Berman reviews the December 2024 o3 and o3-mini announcement, including coding, math and ARC-AGI results. He calls the results evidence of AGI, a conclusion the benchmarks alone cannot establish.
 17:12ENMatthew Berman· 30 avr. 2024Testing the Mystery 'gpt2-chatbot' Model in April 2024Matthew Berman · Forward FutureMatthew Berman tries an anonymous model on coding, arithmetic and reasoning tasks while its identity remains uncertain.
 22:17ENMatthew Berman· 21 mars 2024Q* Rumors, Energy-Based Models, and Research on ReasoningMatthew Berman, Yann Lecun · Forward FutureMatthew Berman examines an anonymous, unverified account of Q* and compares its ideas with published research on teaching language models to reason.
 35:16ENMatthew Berman· 28 nov. 2023What Was Known About Q* in 2023—and What Was SpeculationMatthew Berman, Sam Altman, Andrej Karpathy · Forward FutureMatthew Berman surveys rumors, reasoning papers and self-play analogies after OpenAI’s leadership crisis, with important limits on what was verified.
 11:05ENMatthew Berman· 7 nov. 2023Testing Dolphin 2.2, a Mistral 7B Fine-TuneMatthew Berman · Forward FutureMatthew Berman tries a small open-weight model on coding, formatting and reasoning prompts, with mixed results.
 4:59ENMatthew Berman· 25 juil. 2023Testing Airoboros L2 70B on Coding, Writing and ReasoningMatthew Berman · Forward FutureMatthew Berman runs a small set of prompts against a Llama 2 fine-tune, finding useful structured output alongside failures on code and logic.
 8:04ENMatthew Berman· 11 juil. 2023WizardLM 13B v1.1 Tested on Coding, Writing and LogicMatthew Berman · Forward FutureMatthew Berman tries an instruction-tuned model on a small set of prompts, with mixed results and several subjective scoring choices.