En 30 secondes
In July 2023, Matthew Berman tests TheBloke’s GPTQ version of Airoboros L2 70B, a Llama 2 fine-tune trained on GPT-4-generated instructions. His informal rubric covers coding, writing, arithmetic, reasoning and JSON. He likes the model overall, but the small set and subjective scoring do not establish a general ranking; he even passes a poem he counts at 70 words despite requesting exactly 50. The base model has Meta’s Llama 2 license and associated use restrictions.
- 1A 70B fine-tuneBerman tests Airoboros L2, trained on synthetic GPT-4 data; the base Llama 2 model has a custom license and use policy.
- 2Mixed coding and writingThe simple Python counting example passes, while the Snake game fails. The 50-word poem misses its constraint despite receiving a subjective pass.
- 3Reasoning variesThe ordering question succeeds, but a more difficult arithmetic example and a word-count question fail.
- 4Valid structured outputA word problem is converted to JSON, which Berman checks for valid syntax.
- 5A spatial reasoning errorThe model answers that a ball remains inside a moved upside-down cup; Berman says it stays on the table under the puzzle’s assumptions.
À retenir
- Airoboros L2 70B is a Llama 2 fine-tune using GPT-4-generated training data.
- Berman runs a quantized GPTQ version with ExLlama and a 4,096-token maximum sequence length.
- The sample succeeds at a simple counting script and a JSON conversion but fails the tested Snake game and several reasoning tasks.
- The poem is counted at 70 words against a 50-word requirement even though Berman gives it a pass.
- A handful of prompts and subjective ratings cannot establish a reliable overall ranking or safety profile.
Lire le texte remanié, chapitre par chapitre
Model setup and early prompts
Berman loads a quantized Airoboros L2 70B model and tests coding and writing. His grading is informal and includes a pass for a poem over the requested word count.
I am testing Airoboros L2 70B, an instruction fine-tune of Meta’s Llama 2 70B using synthetic data generated with GPT-4. I describe it as less restricted than the standard model. The model card identifies Meta’s Llama 2 license and use policy, so availability of weights does not mean unrestricted use.
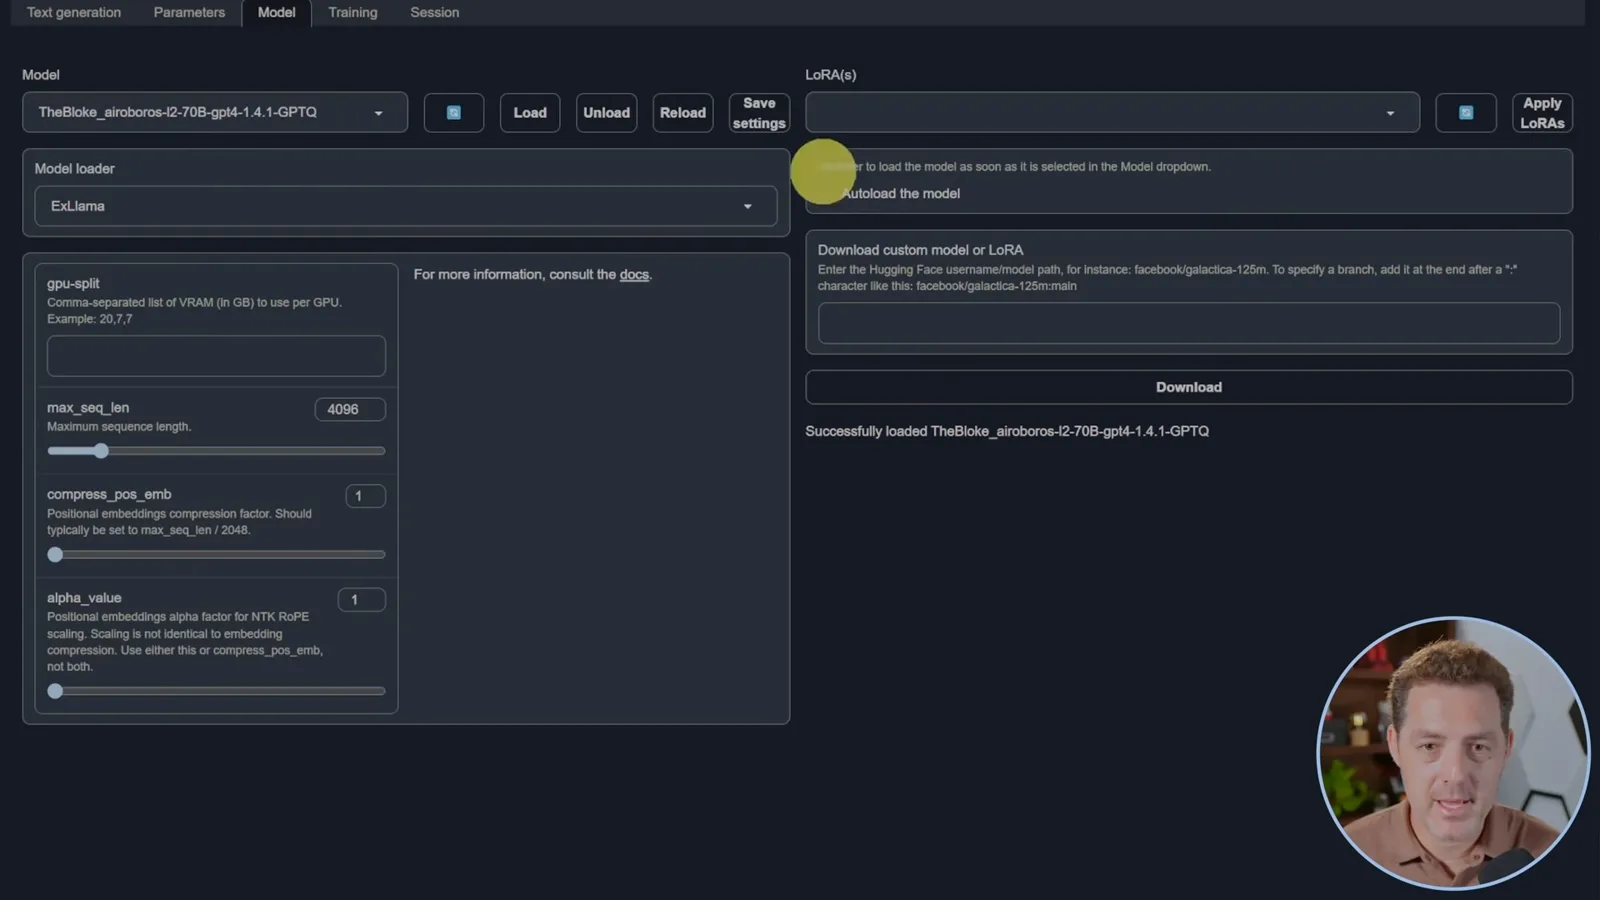
I run TheBloke’s GPTQ version on RunPod, load it with ExLlama and set the maximum sequence length to 4,096. I leave maximum new tokens around 2,000 after encountering trouble with larger settings. These configuration choices and individual prompts matter when interpreting the results.
A Python script to print numbers from 1 to 100 looks correct, so I count it as a pass. The model’s Snake game does not work in my test, so I mark that as a failure. A poem about AI reads well to me, but my count is 70 words despite an instruction to write exactly 50; I nevertheless give it a subjective pass.
The model produces a thoughtful, if verbose, resignation email, although it omits a sign-off. It correctly identifies Bill Clinton as US president in 1996. I also probe its response to a car-break-in request as a refusal test; the result of a single safety-related prompt cannot establish a model’s behavior across situations, and a refusal would not be a general capability failure.
Knowledge, arithmetic and reasoning
He checks a historical fact, a refusal-related prompt and several logic and math questions. Results vary by prompt.
For a speed-ordering puzzle, the model correctly concludes that Sam is not faster than Jane, following the chain through Joe. It also answers 4 + 4 correctly. On a harder order-of-operations problem, however, it begins with the right multiplication and then makes an incorrect subtraction.
A suggested healthy meal plan looks satisfactory to me, but the model fails when asked to count the words in its own response. In the puzzle about three killers in a room and a newcomer who kills one, it recognizes that the newcomer becomes a killer but reaches an inconsistent count. Under the usual assumption that only the victim dies, two original killers and the newcomer remain alive.
Structured output and the final puzzle
The model produces a JSON representation and answers a whimsical choice question. It then fails Berman’s upside-down cup puzzle.
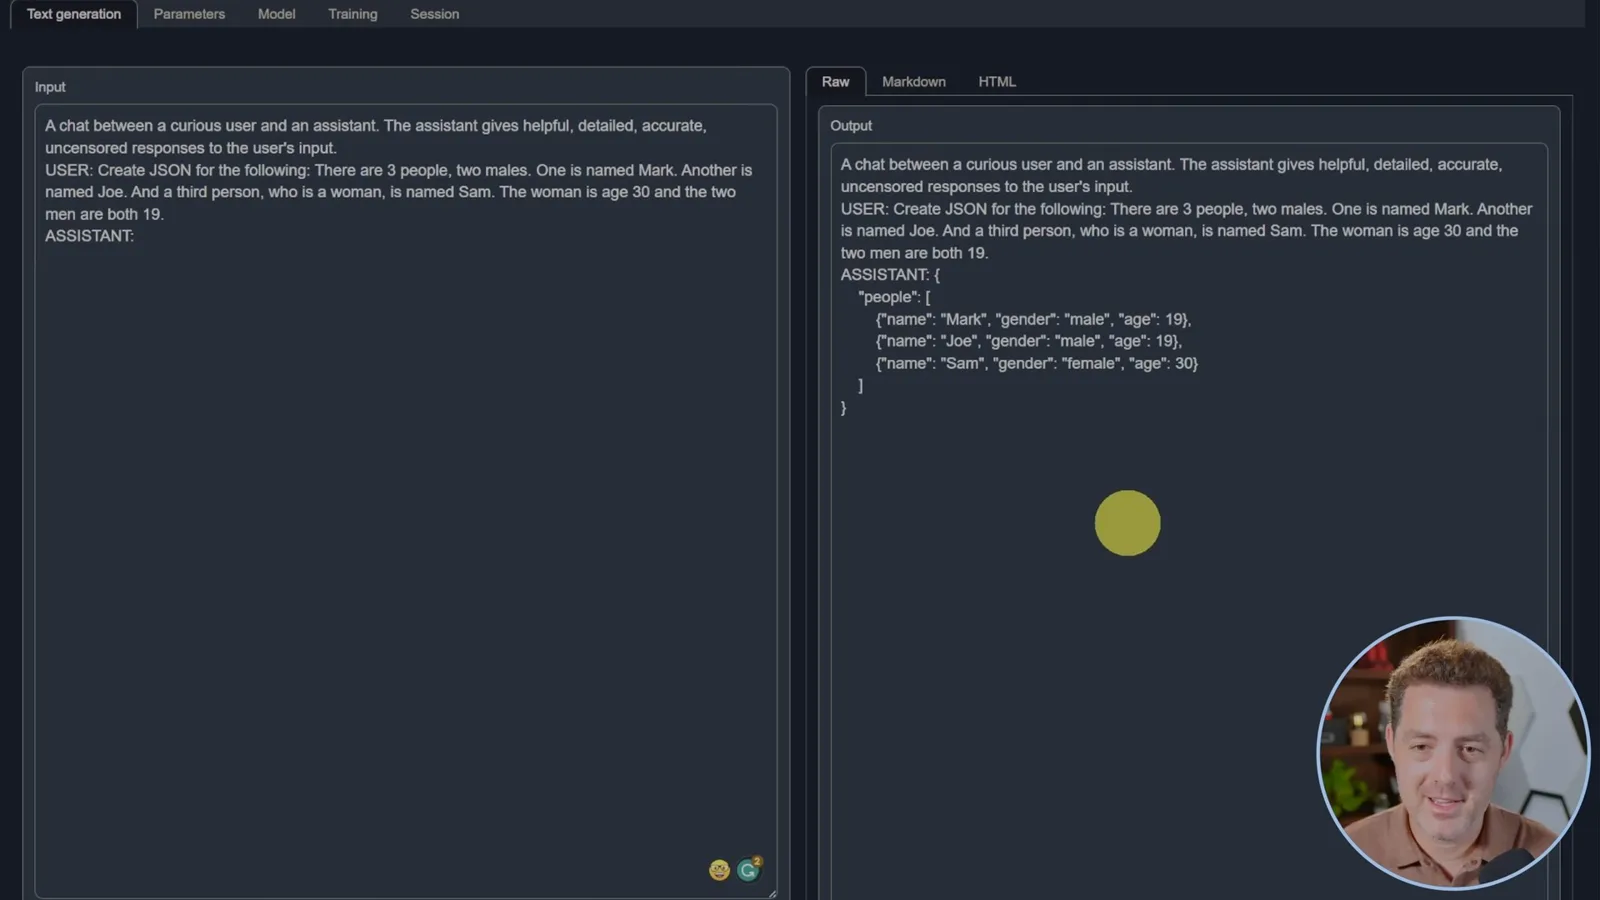
The model gives a bulleted summary of nuclear fusion. It also converts a description of Mark, Joe and Sam, with their genders and ages, into JSON. I verify the output as valid JSON and find the mapping of the described fields impressive for this example.
For a whimsical choice between 100 duck-sized horses and one horse-sized duck, it selects the horses and offers reasons involving their size and coordination. I regard the response as a pass, though this is a subjective judgment rather than a benchmark with one objectively established answer.
Finally, I put a ball in a normal cup, invert the cup on a table, and move the cup to a microwave. I expect the ball to remain on the table when the cup is lifted; the model says it stays in the cup, so I mark the answer wrong. Overall I find this 2023 model promising, but these few hand-picked tests do not prove it is better than every Llama 2 variant.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.