En 30 segundos
At Bug Bash EU 2026, Cate Huston explains how lessons from engineering management help a small team coordinate AI agents and deliver reliable software. She presents guardrail allocation and throughput figures as examples from her own team.
- 1Adapt the management playbookRelease gates, queues and priorities can coordinate agents as well as people.
- 2Four layers of workMission, strategy, process and execution must remain aligned.
- 3Turn rules into checksWritten instructions alone did not ensure tests until coverage was enforced.
- 4Protect load-bearing componentsInvest in architecture, tests and guardrails where change is most consequential.
- 5Measure CI cost as well as tokensVelocity creates costs that should be compared with delivered value.
- 6Fix classes of bugsTreat incidents as signals to prevent recurrence, not only to patch one instance.
Conclusiones
- Good management practices can be adapted to coordinate people and AI agents.
- Mission and strategy remain necessary when execution accelerates.
- Automated checks and targeted architecture help prevent recurring classes of failures.
- Huston uses 30% of output for guardrails as a team-specific starting point, not a universal rule.
- Human review, prioritization and CI costs remain essential to turning output into value.
Lee el texto editado por capítulos
A new perspective on velocity
Huston describes the move from large teams to AI-assisted development.
What percentage of a team’s output should be guardrails? And which old ways of working still help when AI changes the industry? I came to this talk with those two questions, which I think are closely related.
I spent more than a decade scaling remote teams, including at Automattic and DuckDuckGo. This year I left DuckDuckGo to experiment, worked with a friend on a platform built with Claude, and became fractional CTO at Twill. With one other engineer, I helped move its platform off Bubble.
The migration took four months. These systems are smaller than the teams I used to lead, but they are real, in production and earning money. My perspective combines experience making large teams effective with recent experience making AI-assisted development effective.
My impact used to show up through other people; now much of it shows up on GitHub. My calendar has given way to the terminal, but the goal is unchanged: consistently shipping reliable, useful software.
Replatforming and the playbook
The team stabilizes and migrates its product, then builds release and agent workflows.
At Twill, the data model had become a constraint. I did not begin replatforming on day one: first I stabilized the existing system, including stopping two-way writes, and spent months creating the conditions for a move to a proper database.
The team found its rhythm in June, reached feature completion in July, and prepared infrastructure and data migration. The August launch brought reactive work; in September we returned to larger roadmap features. Two engineers and a six-week intern produced the work, with most fixes caught before release.
When I adapted the setup to another platform, I realized the management playbook was still useful, just applied differently. I introduced a release branch, an orchestrator and a merge queue that validates work, sends it back or files follow-ups. Sequencing merges also reduced wasted CI minutes.
I aligned the board’s priorities with the orchestrator and marked features for the next release. I also added temporary database targets, authenticated end-to-end tests, environment requirements, a design system and nightly backups before leaving AI unattended. Without a release focus, we could ship 50 pull requests and no headline feature.
Small teams now need practices that larger teams previously accumulated over time. I think of process as depending not only on the number of people, but also on the agents each person manages and on how effectively those agents are managed. That formula is a simplification, not a measurement.
Management and its four layers
Mission, strategy, process and execution still matter when agents accelerate work.
A good manager multiplies the team’s effectiveness: finds and removes bottlenecks, helps individuals improve, and keeps the team’s needs in view. Process scales judgment into execution; relationships move judgment between people. Turning token spending into business value has a management dimension.
Agents can be more consistent within a narrower range, but they may not ask why or admit uncertainty. Not everyone asked to manage agents has management experience. I realized that I had brought management practices into my own work without explaining them to the engineer working alongside me, so coaching became necessary.
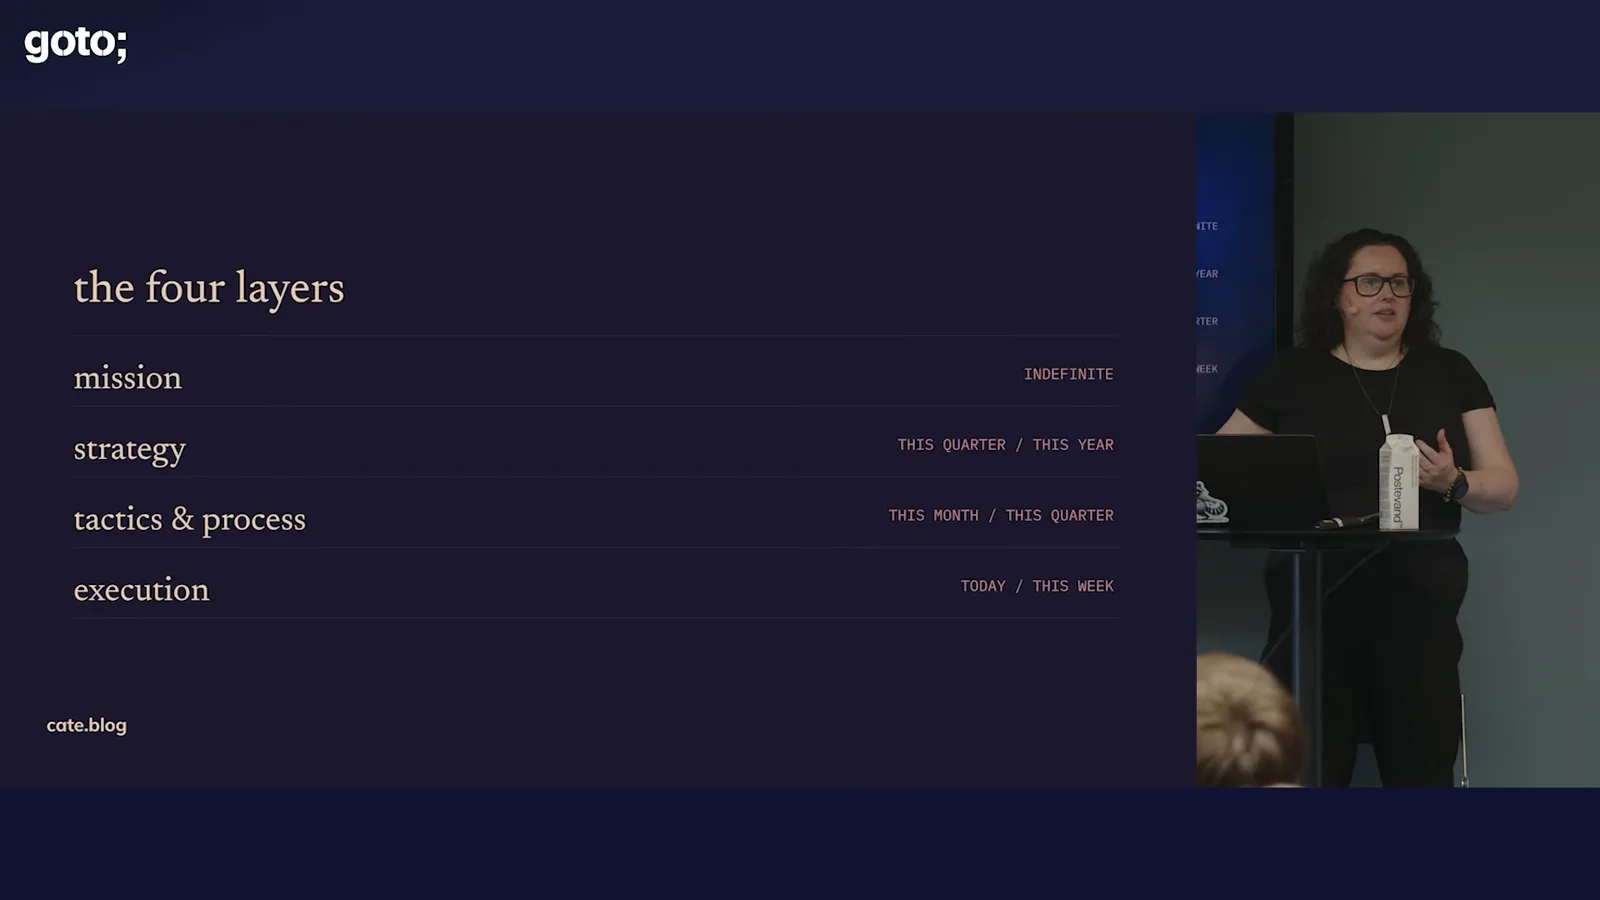
I use four layers: mission defines the value a team exists to deliver; strategy sets priorities; tactics and process make work observable and actionable; execution gets it done. Fast execution alone is insufficient if the team has not decided what to do and why.
The layers remain, but their pace changes. Mission is relatively stable; strategy may need to evolve in weeks rather than quarters. Agent-facing process can be written and enforced quickly, and execution can continue overnight, but only if the other layers are aligned.
Good human process asks what helps a capable person on a bad day. For agents, I also ask what a persistent agent could do in the worst case. Instead of waiting weeks for a postmortem, we should build a guard against the class of problem while the incident is fresh.
Guardrails and reliability
Written rules evolve into checks, tests and architecture that prevent classes of failures.
I define a guardrail as a way to prevent problems. Large companies traditionally built layers that let people work safely with partial understanding; small teams often relied on shared tacit knowledge or senior hires. Incidents and maintenance form a second, often unwritten roadmap competing with planned features.
I cite reports suggesting that higher AI-assisted change volume can coincide with more incidents and less proportional user impact, alongside research on developer speed. These findings have different settings and should not be treated as a universal productivity estimate. The engineering question is how to convert output into business value without losing control of incidents.
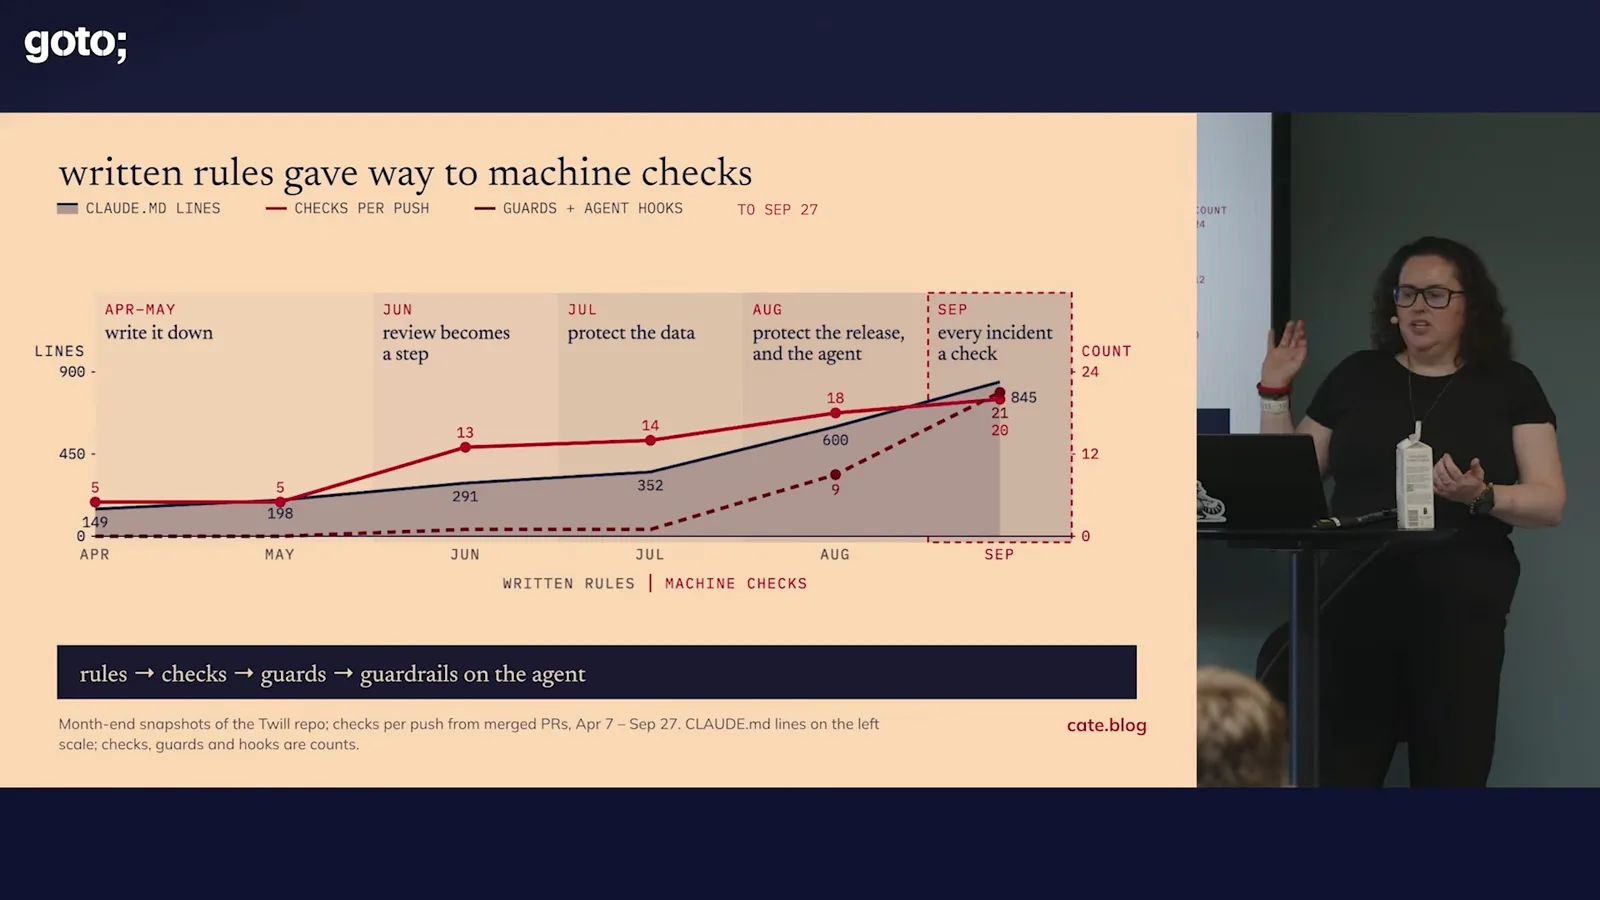
We began with written rules, then increasingly turned them into machine checks because agents do not always follow instructions. A rule requiring tests did not consistently work until coverage was instrumented and checked. In my team, guardrails have averaged around 30% of output; that is a starting point from our experience, not a universal target.
Preventing a bug from shipping is better than merely observing or healing it afterward. We introduced a design system with visual snapshots, and generated database queries from the schema after repeated classes of server errors. These investments make consistency easier and can also support accessibility.
Architecture matters earlier when high output causes more churn. We invested early in role-based access control: it seemed expensive in the first month, but later permission changes vindicated the decision. Identify the load-bearing pieces and give them stronger tests, guardrails and resilient architecture rather than trying to perfect everything.
Review, cost and priorities
Human review, CI spending and product strategy keep output tied to value.
For a small team, separating releases from main creates a deliberate human review gate. UI changes should be viewed before production. Think about what can be rolled back, use feature flags where useful, and monitor the system so humans can see the bigger picture.
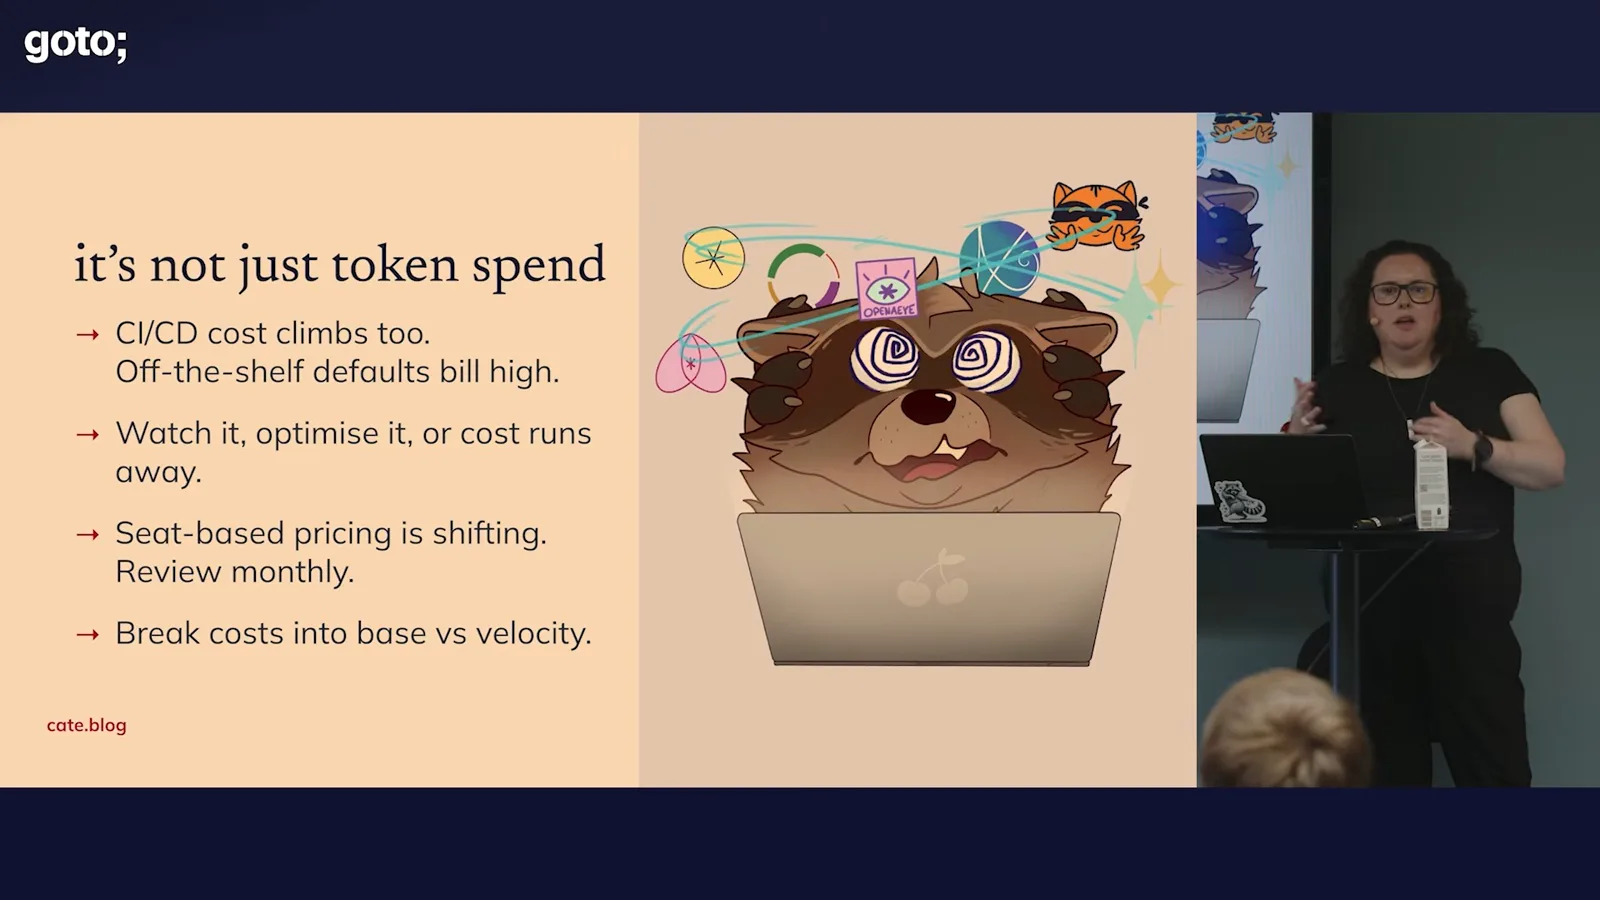
AI output consumes CI minutes as well as tokens, and stronger checks can increase those costs. I divide operating costs into base costs and velocity costs that scale with output, then compare the latter with delivered value. In one month our CI spend exceeded our AI subscription spend, though metered AI pricing could change that comparison.
Cheap execution makes doing everything tempting, but doing everything is not a strategy. Product work still requires deciding what matters to users and in what order. Asking an AI to draft a specification does not remove the human responsibility to think it through, especially when other people must read and act on it.
I think teams underuse shared default guidance for agents. Inconsistent workflows can multiply their differences when agents are added, and people need support learning to manage those agents. I cite CircleCI’s report as evidence that strong CI is associated with better results; this is a reported association, not proof that one pipeline causes every gain.
Make room for prevention
The team reserves output for guardrails and prioritizes work requiring human attention.
Since launch, our two-person team has averaged five releases a week with roughly 25 pull requests per release; later we moved toward fewer, larger releases. The volume depends on guardrails. I suggest 30% of output as a starting point for discussion, not as a substitute for measuring reliable software and user value.
The roadmap must include guardrails. An incident is a signal to automate protection against its whole class, not just patch the immediate bug. Much of this work is mechanical, so 30% of output does not mean 30% of human time. Individual contributors need coaching to look one level up at recurring problems and their implications.
My nontechnical CEO asks for features; my job is to build the guardrails that make those features possible. During migration I declined requests to protect scope. Later, a feature she expected to wait for had already shipped. Leaders need to show how foundational work advances the shared goal of velocity.
Large features still need scarce human attention and prioritization. The other engineer focuses on a large feature and data work; I handle a medium feature, releases and CTO duties, while an orchestrator works through the backlog. You can have many things, but not all at once: decide what comes first.
I am not claiming this exact workflow is correct for everyone. Each of us sees only part of a rapidly changing picture. In our case, leaving the no-code platform would not have been possible without Claude, and Claude could not have done it without us. The failure mode is surrendering judgment; rigor helps people and agents make progress together.
Más de este canal
 22:33EN
 GOTO Conferences· 26 oct 2026William Schor: From Unit Tests to Synthetic Canaries at NetflixWilliam Schor · NetflixHow generated workloads and production-like infrastructure help test a distributed key-value service.
 34:11ENGOTO Conferences· 23 oct 2026Anatoliy Bilenko and Alberto Carretero: Making Database Protocols Reliable with Formal Methods and AIAnatoliy Bilenko, Alberto Carretero · CanonicalCanonical’s database engineers connect executable specifications, model-based tests, failure exploration, and reconstructed execution histories—and explain why none of these techniques proves a real system correct on its own.
 28:15ENGOTO Conferences· 22 oct 2026Steve Poole on Open-Source Security and AI’s Maintenance ChallengeOlimpiu Pop, Steve PooleWhy faster vulnerability discovery increases pressure on maintainers, dependency users and upgrade processes.
 46:36ENGOTO Conferences· 21 oct 2026Don Syme: Building Agentic Automation Around Human CollaborationDon Syme · GitHubContinuous AI, repository workflows and the guardrails needed for unattended software maintenance.
 28:23ENGOTO Conferences· 19 oct 2026Learning Ash: Declarative Elixir Apps, Testing and ExtensibilityChristian Alexander, Rebecca Le, Zach DanielRebecca Le and Zach Daniel explain how their book and the framework evolved together.
 38:07ENGOTO Conferences· 9 oct 2026Garrison Hinson-Hasty on Systems Programming with ZigTrevor Berrange Sanchez, Garrison Hinson-HastyA conversation about simplicity, memory, strings, graphics APIs and working with C.