En 30 segundos
GPT-6.2 Astra needed repeated direction to build a convincing Tokyo scene, yet diagnosed a recording problem that had frustrated Matthew Berman’s team for 18 months. The early-access tester says he generally prefers Anthropic’s models, but calls Astra strong at computer use and video editing. He also reports that OpenAI made late changes which some testers had not retested, and points to public demonstrations where GPT models produced appealing results at lower reported costs.
- 1Berman rates Astra capable but prefers competing models overallHe says computer use is the principal exception and weighs model quality alongside subscription allowances.
- 2Astra needed repeated prompts to fix its Tokyo buildingsThe model initially mapped satellite images onto facades, producing misplaced windows and doors before constructing buildings directly.
- 3Computer control helped diagnose an 18-month recording problemBerman says Astra inspected OBS logs and fixed dropped frames by forcing on a buffer setting.
- 4Late model changes may explain some differences in reviewsAn OpenAI employee suggested early testers had not retested recent changes; Berman says he received no notice of an update.
- 5Astra has edited dialogue in Berman’s early open-source appHe says it powers editing in Scarlet and has come close to handling a full video in one pass.
- 6Public demos show different quality and reported cost tradeoffsBerman compares scenes and games generated by several models, including examples where GPT models cost much less.
Conclusiones
- Berman says Astra fixed dropped frames by inspecting live OBS logs and forcing a buffer setting on.
- Expect to inspect visual output closely and give further direction: an initially plausible building facade hid errors.
- Individual demonstrations show substantial reported cost differences; compare quality against the price and task.
- Berman says some early-access opinions may not reflect late model changes, and plans to retest.
- In Berman’s experience Astra performs well at dialogue editing in his early Scarlet application.
Lee el texto editado por capítulos
Why early reviews and public impressions diverged
Berman calls Astra competent and particularly strong at computer use. He compares it with Anthropic’s models and weighs subscription limits.
OpenAI has released GPT-6.2 Astra and Sol, and the early reception has been contentious. I was among the early testers, many of whom reported poor experiences, while some people using the public release have posted much more positive demonstrations. I want to explain what I tested and where those differences may come from.
After extensive testing, I consider Astra a competent model rather than a standout, with one major exception: computer use. It can build games, applications and 3D city simulations, but in my comparisons I prefer Anthropic’s Opus and Fable for many of those tasks.
The choice also depends on budget and usage limits. I previously preferred an OpenAI subscription because of its larger allowance, but I believe Anthropic now provides enough usage that I would choose it instead. This reflects my current experience, not a fixed rule for every user.
Before showing the demos, I should explain that the computer on which I ran many tests failed. I recovered some examples, but lost the one I most wanted to show: a Gears of War-style game clone.
Building a Tokyo scene required several corrections
Astra created buildings and used downloaded assets. Its initial facade shortcut needed repeated prompting to correct.
I asked Astra to build a 3D replica of Tokyo in Unreal Engine. Its computer and browser control suited the task. It built the buildings itself while downloading assets such as logos, but the final version came after several iterations.
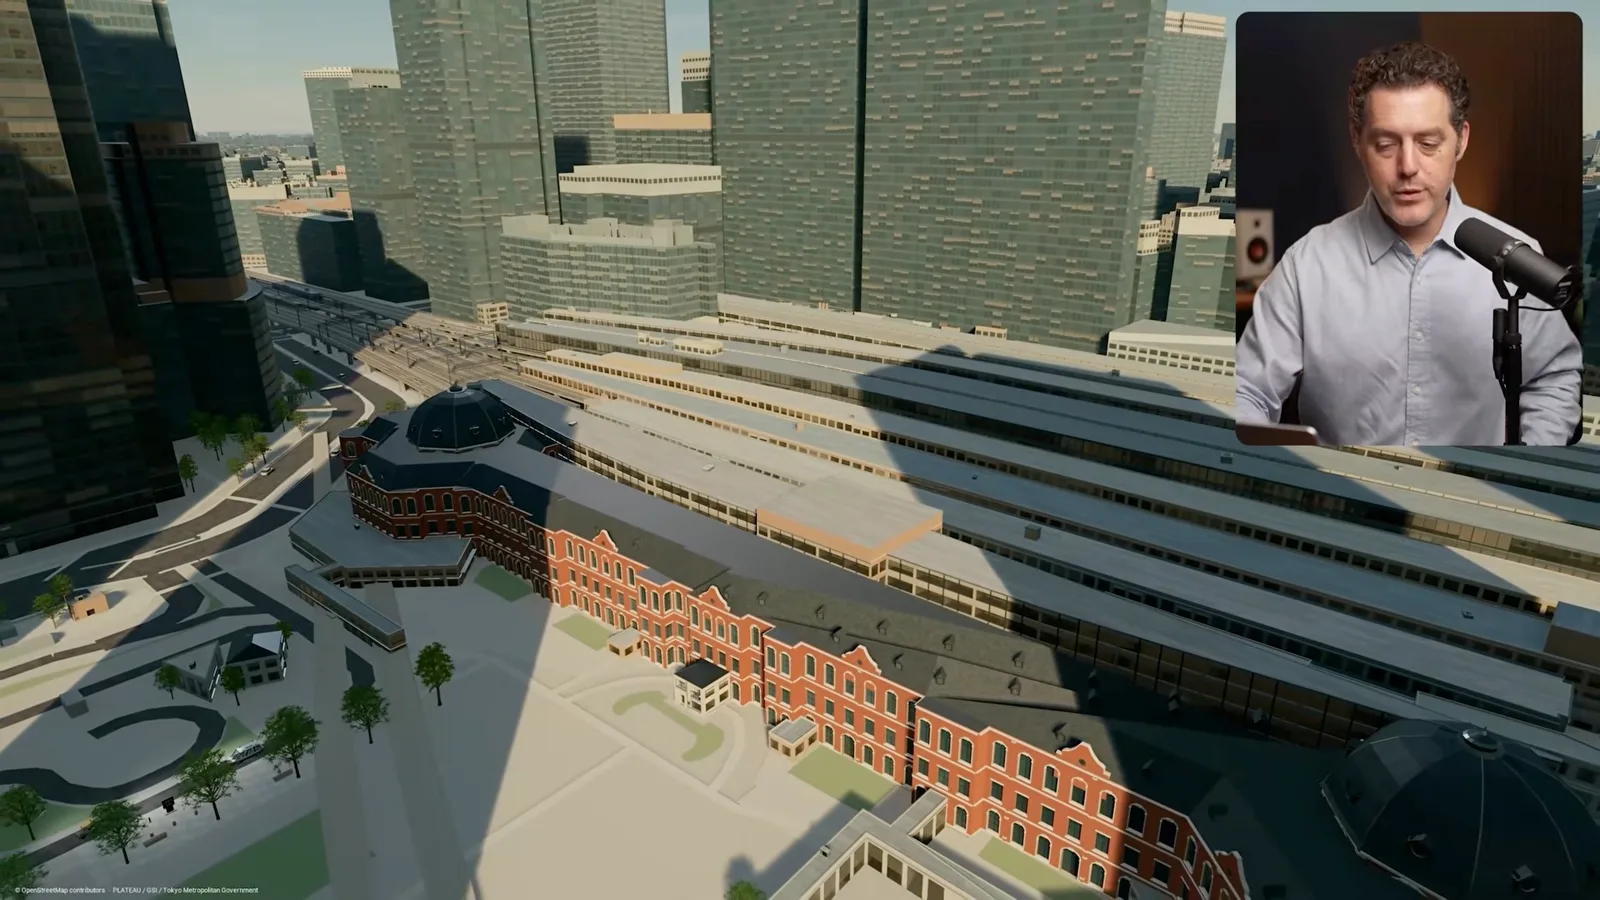
Initially the model mapped satellite imagery onto building facades. It looked plausible from a distance, but closer inspection revealed misplaced windows and doors. I had to prompt it repeatedly to build structures directly; that difficulty following an apparently obvious direction was one reason early testers became frustrated.
Finding the cause of dropped recording frames
Berman says Astra inspected OBS logs and identified a buffer setting. Previous equipment replacements and outside help had not solved the problem.
A different task showed why I still find the model impressive. My team had spent around 18 months trying to diagnose occasional dropped video frames. Replacing the camera, HDMI cable and computer, asking other models and consulting human experts had not solved it.
Astra inspected the camera, incoming feed and OBS recording logs while I recorded. It found a buffer setting that had remained off despite being set to automatic; forcing it on resolved the issue for us. The ability to operate the computer and examine the evidence made this a useful result.
Early-access feedback and the last-minute update
Several testers reported negative experiences. Berman discusses a claimed late model update and says he was not informed of it before release.
I am part of OpenAI’s early-access testing program. The company provides models for us to test and accepts critical feedback, but does not pay us for participating. After release, many members shared negative experiences; I did not have as much trouble as some, although I still rate the models below Anthropic’s competing offerings.
Matt Shumer initially said his experience was so poor that he would not write a full review, then published a negative one after readers asked. Theo also described hating Astra and explained his reasons. My own building tests surfaced similar issues, although further prompting often got the job done.
Another tester, Paul Solt, reported unclear summaries, premature stopping, fixation on the wrong issues and weak iOS interface work. He also noted stronger video editing and lower costs. Dan Shipper likewise described the release as disappointing relative to Fable.
An OpenAI employee, Thibault Sottiaux, suggested one reason for the split: early testers had access for some time, but the team made changes in the final three or four days and he believed some reviews had not retested those changes. He also acknowledged remaining problems with taste and ease of use.
For my part, that account is mostly right: apart from video editing I had not recently tested many other tasks, and I often checked the model’s work with Opus after losing some trust. But I say testers normally hear when the model changes; this time I did not receive that notice or the usual advance warning of launch.
Video editing and public model comparisons
Berman says Astra performs well in his editing application. He reviews individual visual demos and the reported time and cost of competing models.
Video editing has been a strong area in my use. Astra has powered editing in Scarlet, the open-source application I am building, for weeks. It cuts dialogue well in my tests and is getting close to editing a whole video in one pass, although the app is early and rough.
Other users have posted visual demonstrations that make me want to give Astra and Sol another chance. In one four-model scene-generation comparison, a tester reported Astra taking about 45 minutes and $9, Sol 30 minutes and $2, Fable roughly three hours and $200, and Opus nearly three hours and $31.
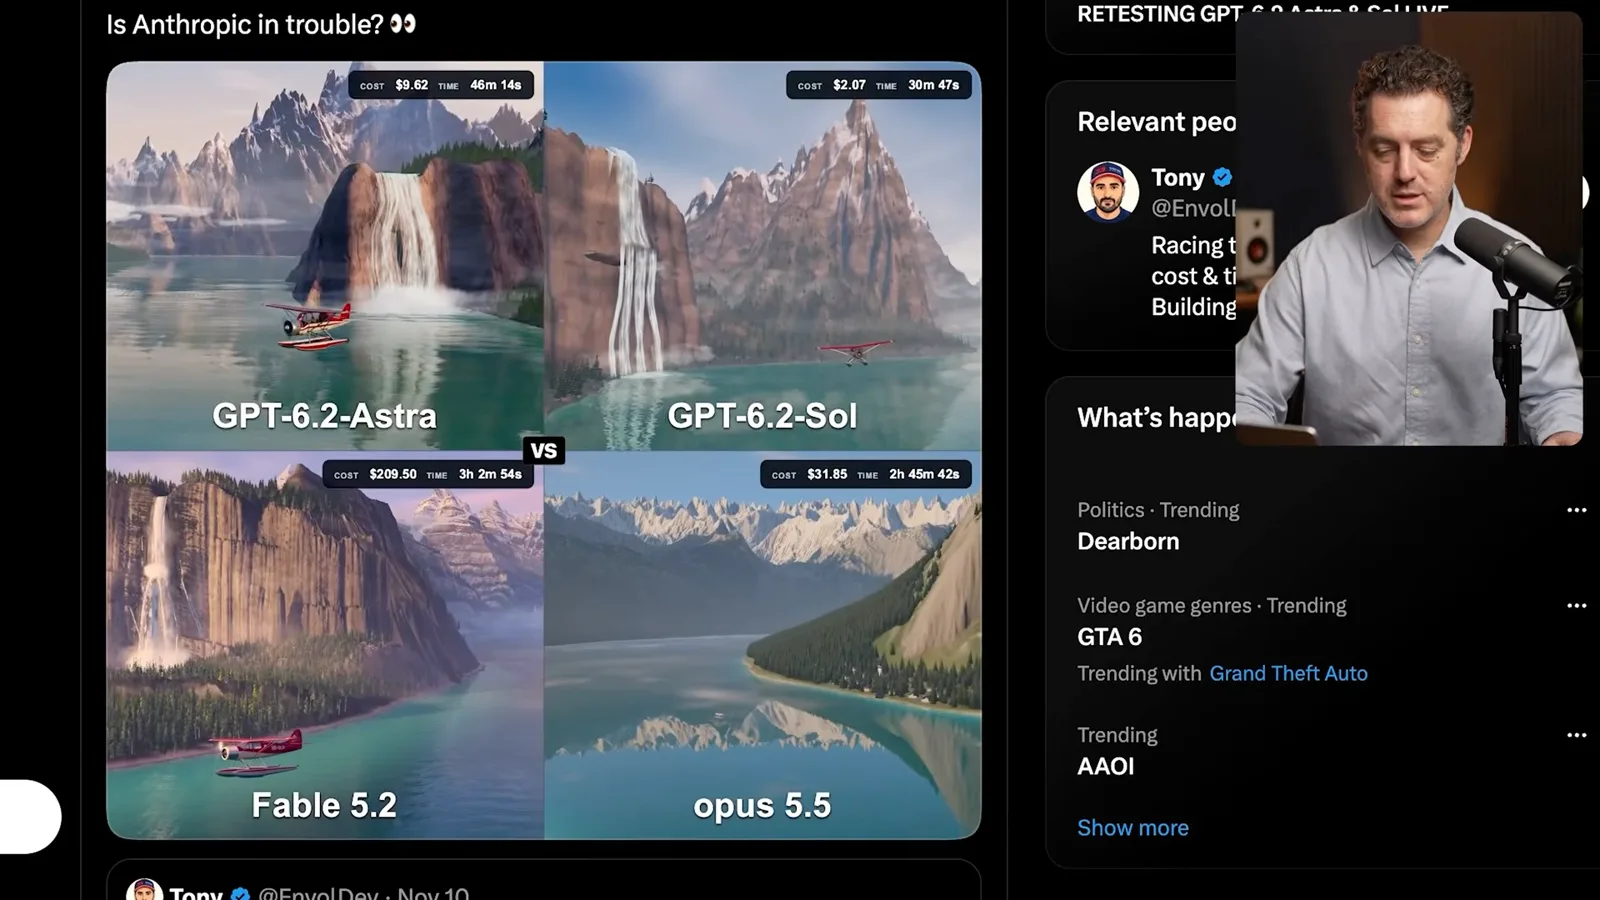
Judging the resulting scenery by appearance, I prefer Fable in that example, with Astra also competitive. None of the four looks bad to me. Another example shows a horror game with reflections in standing water, and a Japanese temple scene with convincing lighting.
The contrast between these public demos and early reviews makes me think the rollout could have been handled better, especially if the last update materially changed behavior. In another comparison, Astra’s scene looks more cartoon-like while Fable’s looks more realistic, but both look good to me.
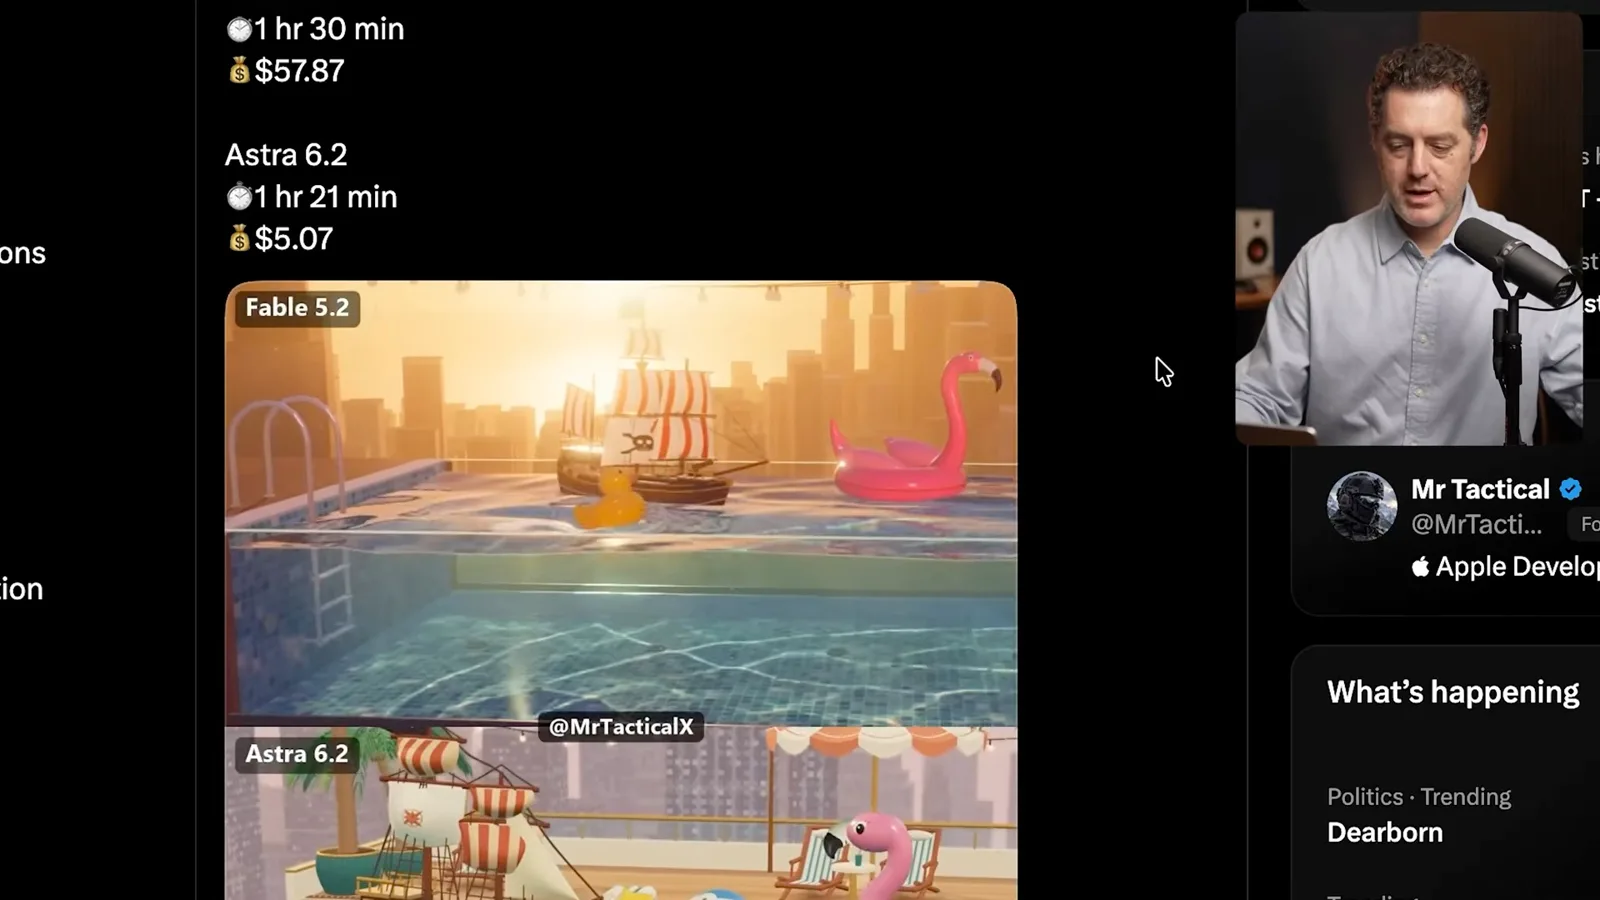
That creator reported an Astra run costing about $5 in 81 minutes versus nearly $60 and 90 minutes for Fable. Whether a quality difference is worth a multiple of the cost depends on the task and the user’s priorities.
I also like a one-shot Doom-style game and another side-by-side scene where Astra costs about $8 and takes 40 minutes while Fable costs $81 and takes nearly two hours. These examples suggest a recurring cost difference, although they are individual demonstrations.
I think Astra is a good model and intend to retest it. I also speculate that Anthropic’s recent model progress reflects the start of recursive self-improvement, referring viewers to outside research discussed in another video.
Más de este canal
 56:20EN
 Matthew Berman· 12 nov 2026How language models learn from text and improve by trial and errorMatthew Berman, Jeremy Berman · Forward FutureAnthropic researcher Jeremy Berman uses apartment prices to explain neural networks, then builds up to language models and reinforcement learning.
 18:18ENMatthew Berman· 11 nov 2026Fable 5.2 leads a week of model releases, but cost changes the choiceMatthew Berman · Forward FutureMatthew Berman compares Fable and Gemini Carbon, reviews smaller models and discusses Nvidia’s investigation.
 24:18ENMatthew Berman· 9 nov 2026Fable 5.2 built playable demos—but several cost thousandsMatthew Berman · Forward FutureMatthew Berman shows games, creative software and simulations, with estimated API costs from $25 to $15,000.
 20:08ENMatthew Berman· 7 nov 2026METR Finds Faster AI Research at Anthropic, With Major UncertaintyMatthew Berman · Forward FutureMatthew Berman examines an independent assessment of AI-assisted R&D and the limits on its access to evidence.
 19:53ENMatthew Berman· 5 nov 2026AI News: Kimi K3.1 Weights, Computer Use and Specialized Open ModelsMatthew Berman · Forward FutureMatthew Berman reviews a week of model releases, from desktop agents and scientific workflows to image, video and speech tools.
 26:47ENMatthew Berman· 4 nov 2026What Weight-Space Programming Experiments Show—and Their LimitsMatthew Berman · Forward FutureMatthew Berman reviews experiments in which a frontier model reads, repairs and writes other networks’ weights, from small game policies to a targeted language-model edit.