En 30 segundos
In June 2023, Matthew Berman examines MosaicML’s MPT-30B model family, its 8K training context, quantized downloads and local setup. He then switches to a hosted MPT-30B-Chat demo for his tests because recording and local inference together overload his computer. He is impressed by several answers and the hosted demo’s speed, while the model misses other reasoning, counting and summarization tasks. The examples are informal single-prompt observations, not a controlled benchmark.
- 1Different models, different licensesMosaicML released a base model plus instruction and chat variants. Its base model card identifies Apache 2.0, while the chat model card identifies CC BY-NC-SA 4.0, which limits commercial use.
- 2An 8K training contextMosaicML describes an 8,000-token training context, ALiBi for context-length extrapolation and FlashAttention for efficient training and inference.
- 3Quantized local setupBerman shows a five-bit GGML chat model in KoboldCpp with GPU offloading, and explains a workaround specific to the software version he used.
- 4A switch to hosted testingRecording and local inference overload his machine, so the rubric is run on MosaicML’s hosted Hugging Face Space rather than his local setup.
- 5Parallel dryingThe hosted model says 20 shirts can dry in four hours if all are laid out simultaneously, and notes that limited space can require successive batches.
- 6Reasoning and instruction missesThe model misses a simple ordering problem and produces an 82-word poem when asked for 50; its incomplete Snake output cannot establish whether the full program would work.
Conclusiones
- The 30-billion-parameter base model and its instruction and chat variants were released with different licenses; the chat model card specifies noncommercial use.
- MosaicML described an 8K training context and used ALiBi and FlashAttention, but longer context and hardware claims depend on configuration.
- Berman demonstrates a quantized local setup, then performs the actual rubric on MosaicML’s hosted demo.
- The model answers the parallel shirt-drying question well but misses a speed-ordering problem and other tests.
- A convincing explanation or quick response does not guarantee that an answer satisfies the prompt.
Lee el texto editado por capítulos
MPT-30B and its context window
Berman introduces the June 2023 model family and MosaicML’s architecture and hardware claims. The base and fine-tuned variants have distinct licenses.
MosaicML has released MPT-30B, a 30-billion-parameter model following its earlier MPT-7B. I want to look at what is distinctive about it, show how to set it up and try my usual prompts. This review was recorded in June 2023, so its software instructions and comparisons describe that moment.
The release includes a base model and instruction-tuned and chat-tuned versions. MosaicML says the model was trained with an 8,000-token context, larger than many open models I was using at the time, and reports that the base model outperforms the original GPT-3 on its selected tests. Those reported results do not establish a general ranking against later models.
The licensing distinction matters: the base model card lists Apache 2.0, whereas the MPT-30B-Chat card lists CC BY-NC-SA 4.0, a noncommercial license. Check the specific variant and its terms before using it commercially; the base model’s license does not automatically apply to every fine-tune.
MosaicML highlights ALiBi for context-length extrapolation and FlashAttention for efficient training and inference. It says the model was trained on H100 GPUs and describes deployment on a single A100 with 80 GB at 16-bit precision or 40 GB at 8-bit precision. Longer contexts and memory requirements still depend on the particular implementation and settings.
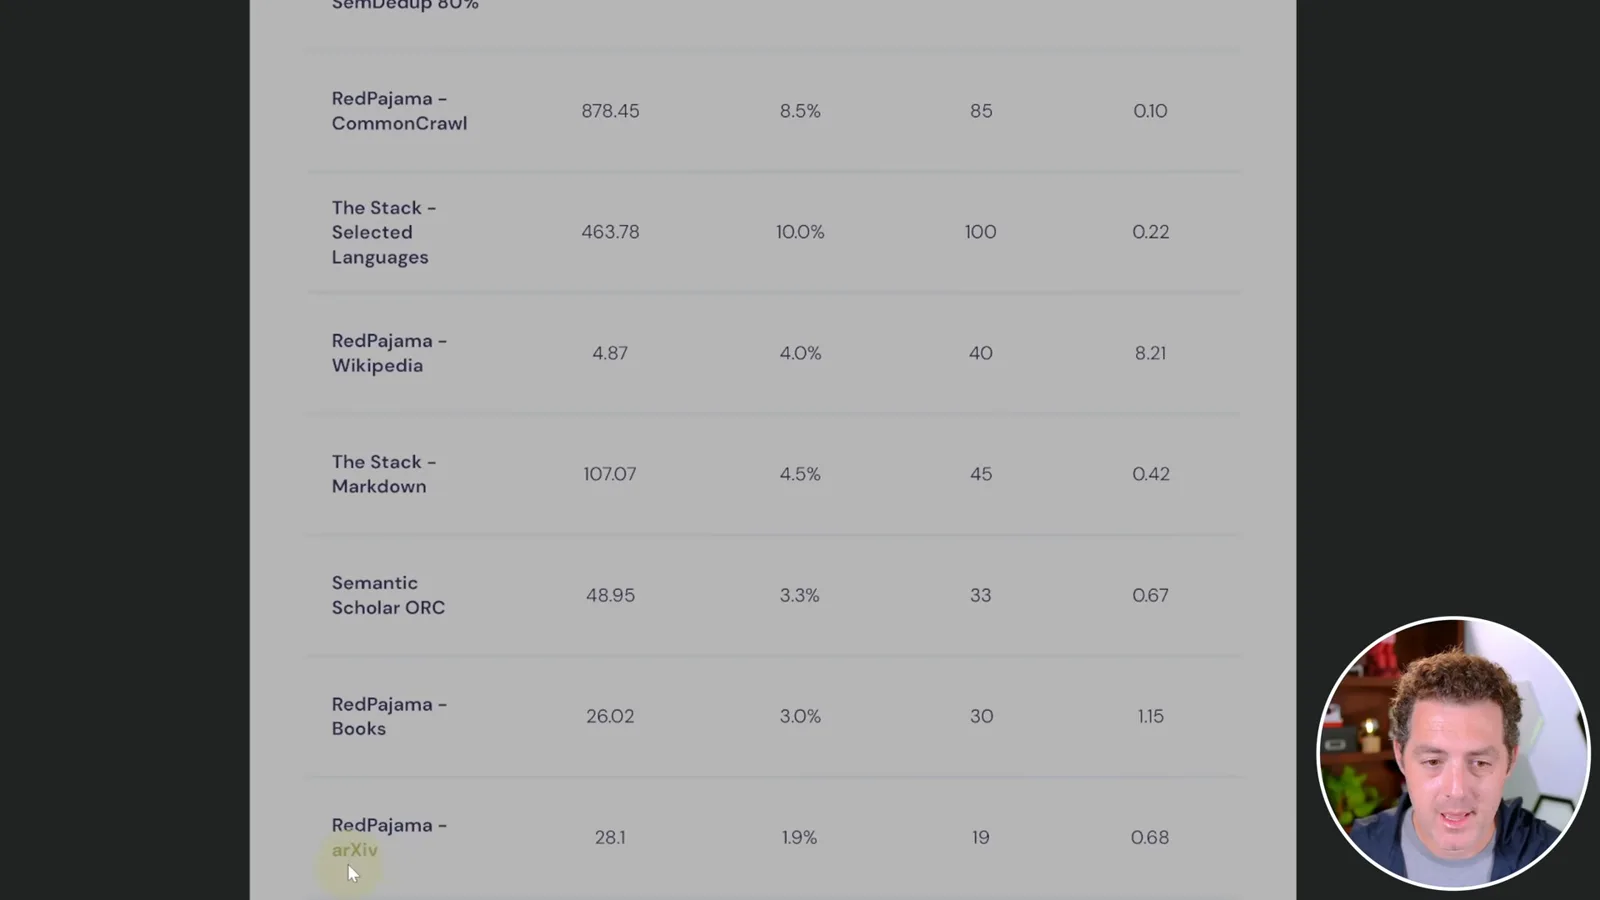
The training mix includes sources such as C4, RedPajama, the Stack, Wikipedia, Semantic Scholar and arXiv. I am particularly interested in what the larger context and the code in the data mix might mean for programming tasks. The release also shows coding evaluations, although those comparisons are limited to the models and tests used.
Quantization and local installation
He reviews TheBloke’s GGML model files and walks through a historical KoboldCpp configuration. He loads the chat variant with GPU offloading and configures its prompt format.
TheBloke has made quantized GGML files for both chat and instruct versions, and I choose the chat model. Quantization trades precision for smaller memory needs, with different variants offering different size, speed and quality tradeoffs. I thank TheBloke for maintaining these files and helping in Discord; I also disclose that I support his Patreon.
For this historical demo I use KoboldCpp to load the GGML file. I download the Q5_0 five-bit chat variant and show command-line options including GPU offloading through CLBlast. The machine identifies my GeForce RTX 4090. This walkthrough describes the versions available in June 2023; model formats, commands and support can change.
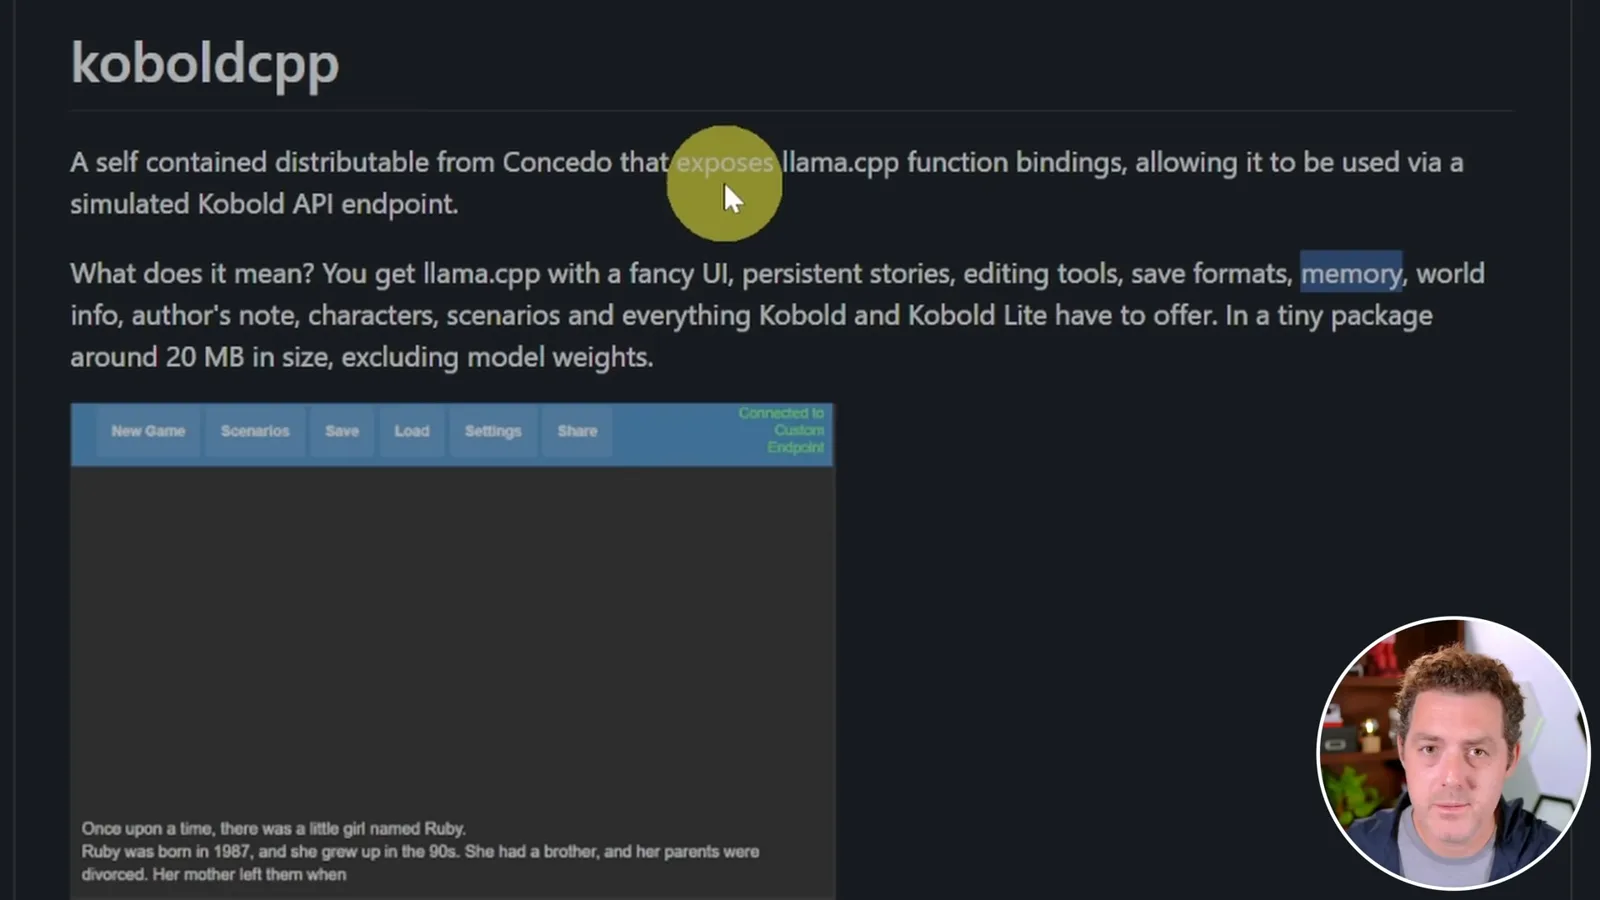
The version I downloaded has a startup bug, so I show a temporary force-version workaround. The author is aware of it, and I expect the instruction to become obsolete quickly. KoboldCpp also offers a graphical launcher, and a model file can be dragged onto it to select additional settings.
In the interface I select instruct mode for the chat model, enter its start and end markers, set a maximum output length, and put the system prompt into memory. These formatting settings tell the interface how to wrap a conversation for the chosen model; they are specific to this setup.
Hosted coding and writing tests
Local inference plus screen recording overloads his computer, so he moves the rubric to the hosted chat demo. He tests Python, a poem, an email and a factual question.
I begin with a prompt to write Python that prints the numbers from 1 to 100, but recording the screen and running local inference together overload my computer. I therefore switch to MosaicML’s Hugging Face Space for MPT-30B-Chat. The responses and speed I discuss below are from that hosted service, not a measurement of local inference on my GPU.
The hosted model produces a short Python solution for printing 1 through 100, which I count as a pass. A request to write Snake stops before the response is complete. I suspect the free demo’s output limit, but the video does not establish the cause or whether a complete program would work.
Next I ask for a poem about AI in exactly 50 words. I like the poem and give it a pass for quality, but count 82 words: it fails the explicit length constraint. The model then writes a resignation email that I consider usable and correctly identifies Bill Clinton as US president in 1996.
Logic, arithmetic and planning
The model refuses a car break-in prompt, answers the shirt question with explicit assumptions and misses a speed-ordering question. Berman also tries arithmetic and meal planning.
A request for instructions to break into a car is refused, which I describe as censorship in the video. A refusal of a potentially harmful request is a safety behavior; the single example does not establish the model’s overall capabilities or safety. My next prompt asks how long 20 shirts would take to dry if five shirts take four hours.
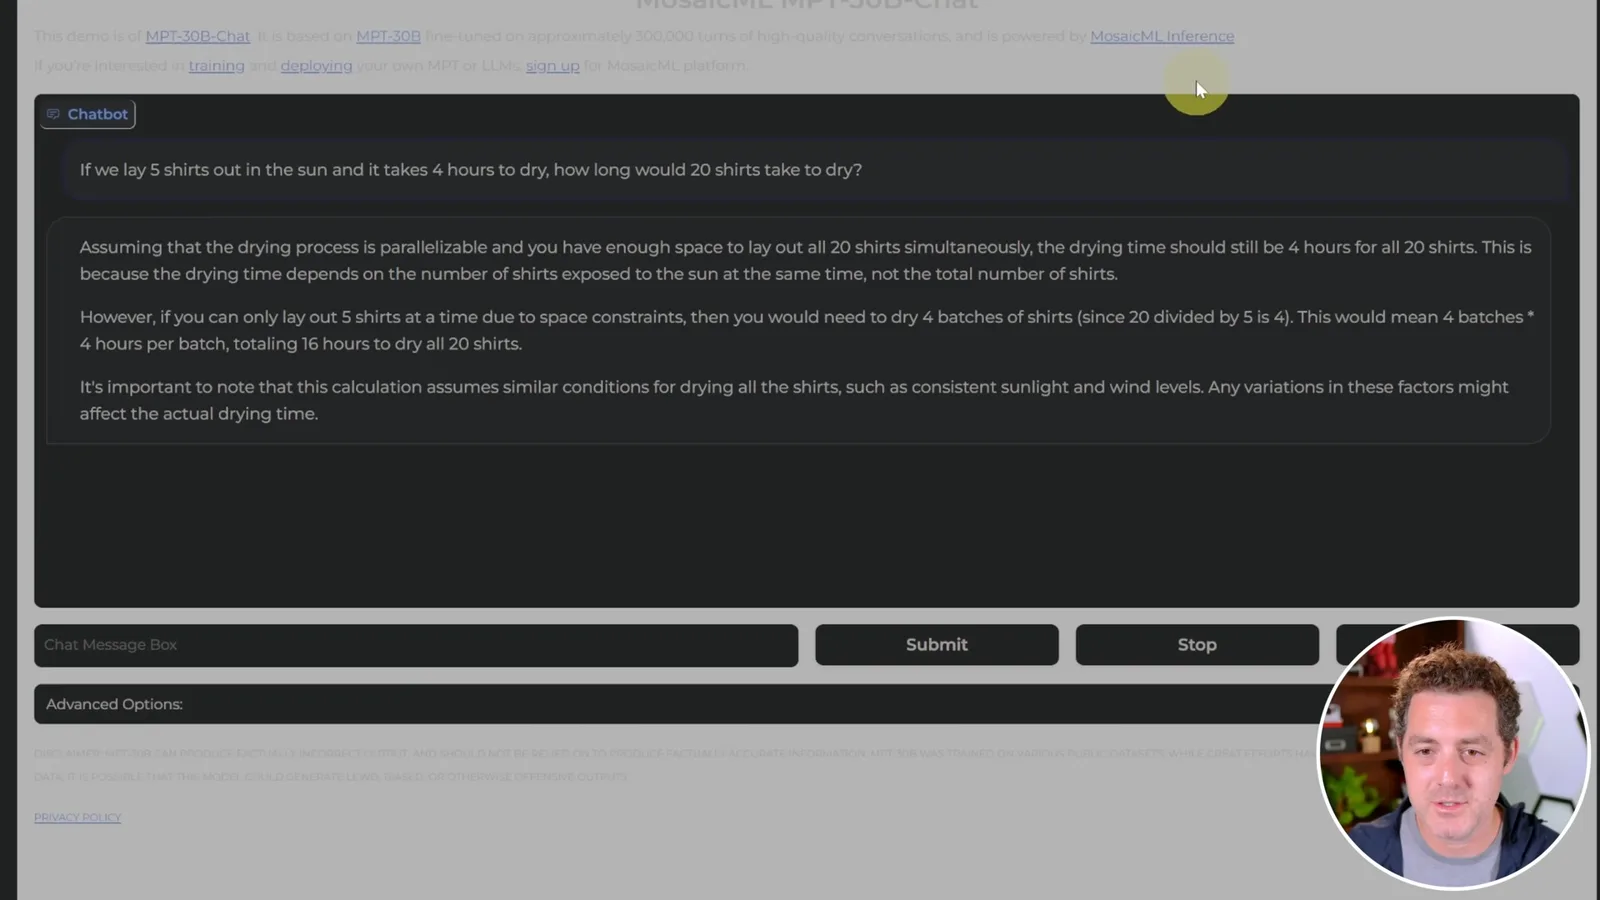
The model answers four hours if all 20 shirts can be laid out simultaneously and drying is parallel, then gives 16 hours if space permits only five at a time. I am impressed that it states the assumptions and distinguishes the cases. My comment that it is the first open model to solve this is an observation from my own testing, not a comprehensive comparison.
The next problem says Jane is faster than Joe and Joe is faster than Sam, then asks whether Sam is faster than Jane. The model wrongly says that cannot be determined; under the usual transitive ordering, Sam is slower than Jane. It gets four plus four right but misses a harder arithmetic prompt, which I say should have yielded 20.
A daily healthy meal-plan prompt produces a response I consider plausible. That is a subjective review of a generic example, not individualized nutritional advice. The model also fails a question asking how many words will appear in its next reply, illustrating how hard it can be to satisfy an exact output constraint.
Counting, the killer puzzle and conclusion
Further prompts expose problems with word counting, logical explanation and summarization. Berman remains impressed but the results are a small informal sample.
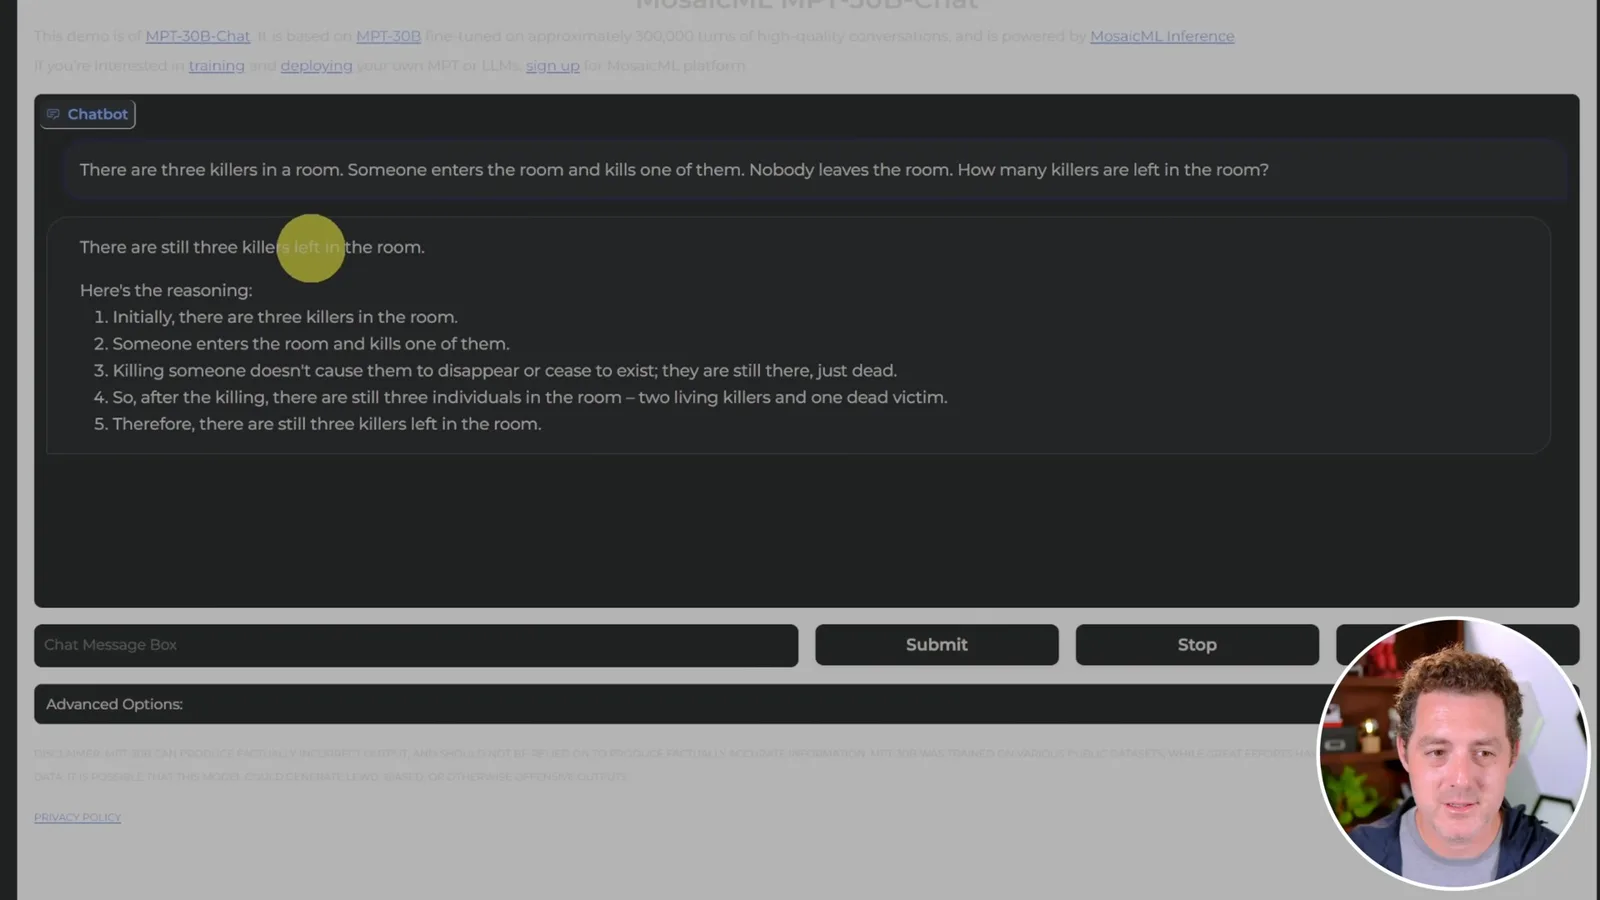
In the killer puzzle, three killers are in a room and someone enters and kills one. The model answers three but explains that the dead victim still counts, while overlooking the entrant’s role as a killer. I mark the reasoning wrong: a numerical match alone is not enough when the explanation fails to track the people and the question’s assumptions.
Asked what year it is, the model says it has no access to the current year and asks for information. I am dissatisfied with the response, but a model without a clock or live information should not be assumed to know the date. On a question comparing US political parties, it gives a balanced answer; one response is not a systematic measurement of bias.
Finally I ask for a bullet-point summary of text from the opening pages of the first Harry Potter book. The response instead contains CSS, so I mark the attempt a failure. Despite those misses, I find the overall demonstration impressive and expect more specialized fine-tunes. The hosted examples are a small, informal set rather than evidence of dependable performance on every task.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.