En 30 segundos
Matthew Berman explains a 2025 paper on recursive language models, which keep long inputs in a programming environment and use model calls to inspect relevant pieces. He reviews the benchmarks, model comparisons and costs, and argues for building better tools around language models. The video is sponsored by Zapier.
- 1Scaffolding beyond a model windowRLMs keep the prompt in an external environment and let a model inspect and query parts of it.
- 2How the REPL worksA root model uses code to examine a stored prompt and can send pieces to sub-calls, then combine results.
- 3Different tasks test different skillsBrowseComp-Plus, OOLONG, OOLONG-Pairs and CodeQA test retrieval, aggregation and reasoning in different settings.
- 4The cost comparison needs contextOn BrowseComp-Plus, the RLM scored higher than the summary agent but cost more on average; a separate full-ingestion estimate was hypothetical.
- 5Variable costs and model behaviorRecursive trajectories can be expensive outliers, and the tested models differ in quality and decision making.
Conclusiones
- RLMs process external text through code and sub-calls; they do not make a single model call’s context window infinite.
- The paper reports strong results on specific long-context tasks, including a collection of 6–11 million tokens.
- Recursive calls can help information-dense tasks but do not win every tested comparison.
- API costs vary by task and trajectory, and some RLM runs cost more than their baselines.
- Theoretical full-ingestion cost estimates are not direct measurements of a model processing an unlimited context.
Lee el texto editado por capítulos
Context limits and the research question
Berman introduces context rot and the idea of handling long inputs without retraining the underlying model. Summarization is useful but may discard information.
A paper from MIT researchers presents recursive language models, or RLMs, as a way to handle prompts much longer than a model's own context window. I find it an exciting example of scaffolding: software around a language model can let it use its existing capabilities in new ways. The technique does not remove the underlying model's context limit or guarantee unlimited, accurate processing.
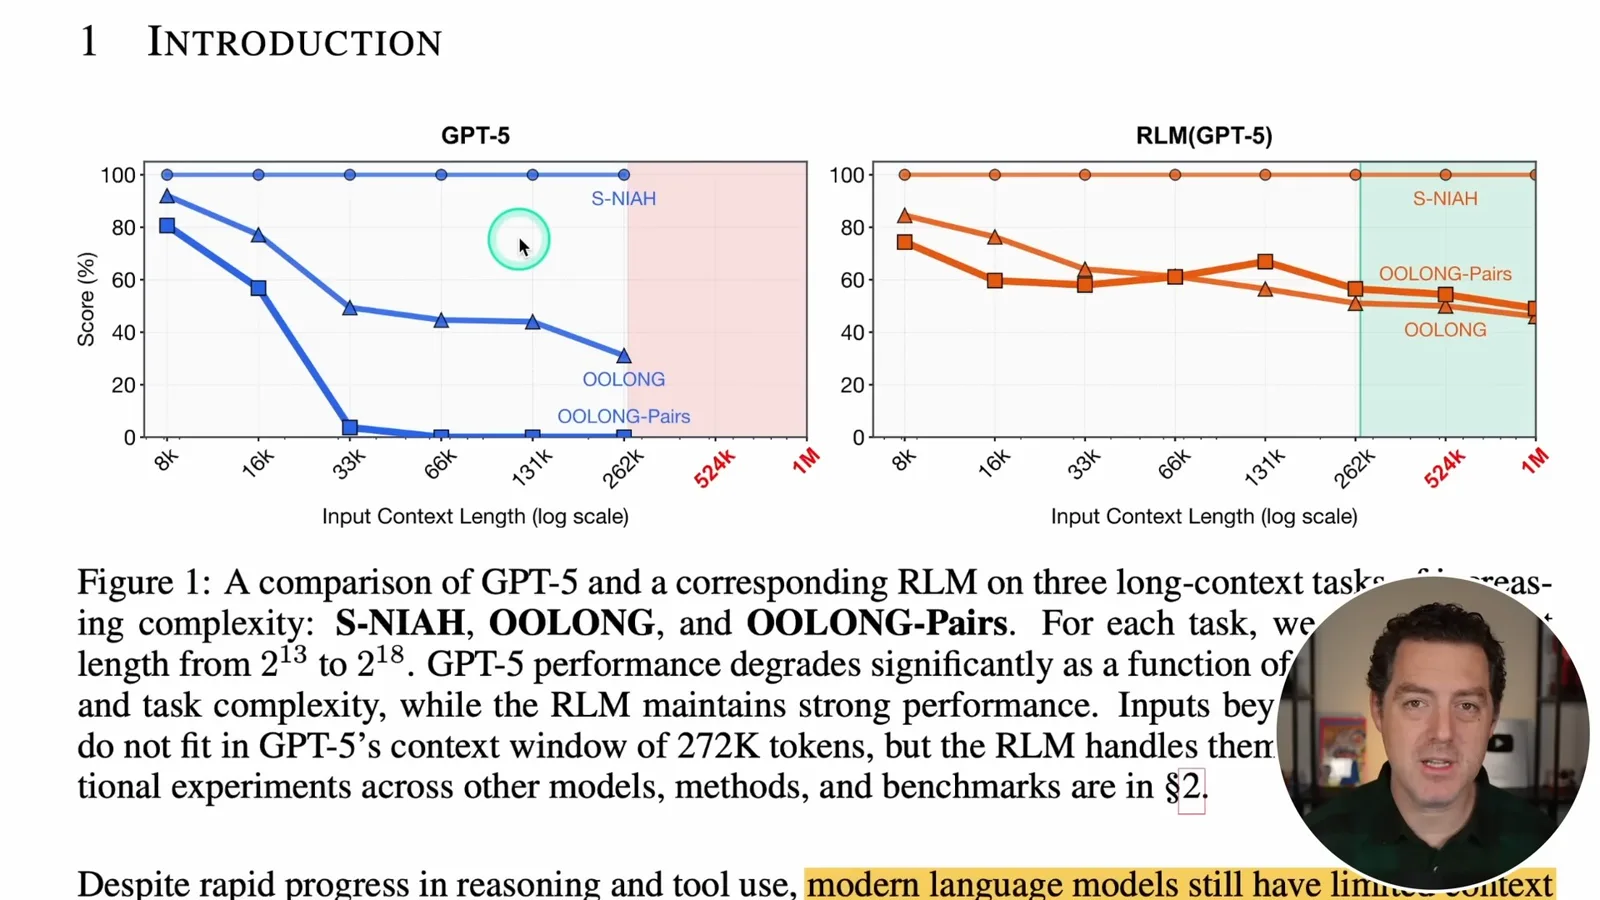
The researchers compare ordinary GPT-5 and an RLM on tasks that become harder as context grows. The video highlights strong single-needle retrieval but much weaker ordinary-model performance on OOLONG and OOLONG-Pairs. The RLM holds up better in the displayed experiments, though its scores on the harder tasks are far from perfect.
A context window limits how much information a model can take in for a single call. Even within that limit, finding details and connecting information across a long input can get harder. This performance degradation is often called context rot, although its magnitude depends on the model and task.
The question is whether we can work over a much larger body of material without modifying the model itself. This matters for long-running work, document collections and large codebases. The [paper](https://arxiv.org/html/2512.24601v1) tests particular benchmarks and inputs, including a 6–11 million-token document collection; it does not establish an infinite practical limit.
A common alternative is compaction: summarize prior context when it becomes too long. It can be useful, but it is lossy. Summarizing a story, then summarizing that summary repeatedly, can discard details that a later question turns out to need.
External prompts and recursive calls
The model writes code in a REPL to inspect a long prompt and can delegate portions to model sub-calls. The video discloses a Zapier sponsorship.
The proposed approach instead places the long prompt in an external programming environment. The model writes code to inspect and manipulate the stored text and selectively bring pieces into a call. It resembles retrieval in its selective access, but the model can also programmatically decompose the work and call language models on snippets.
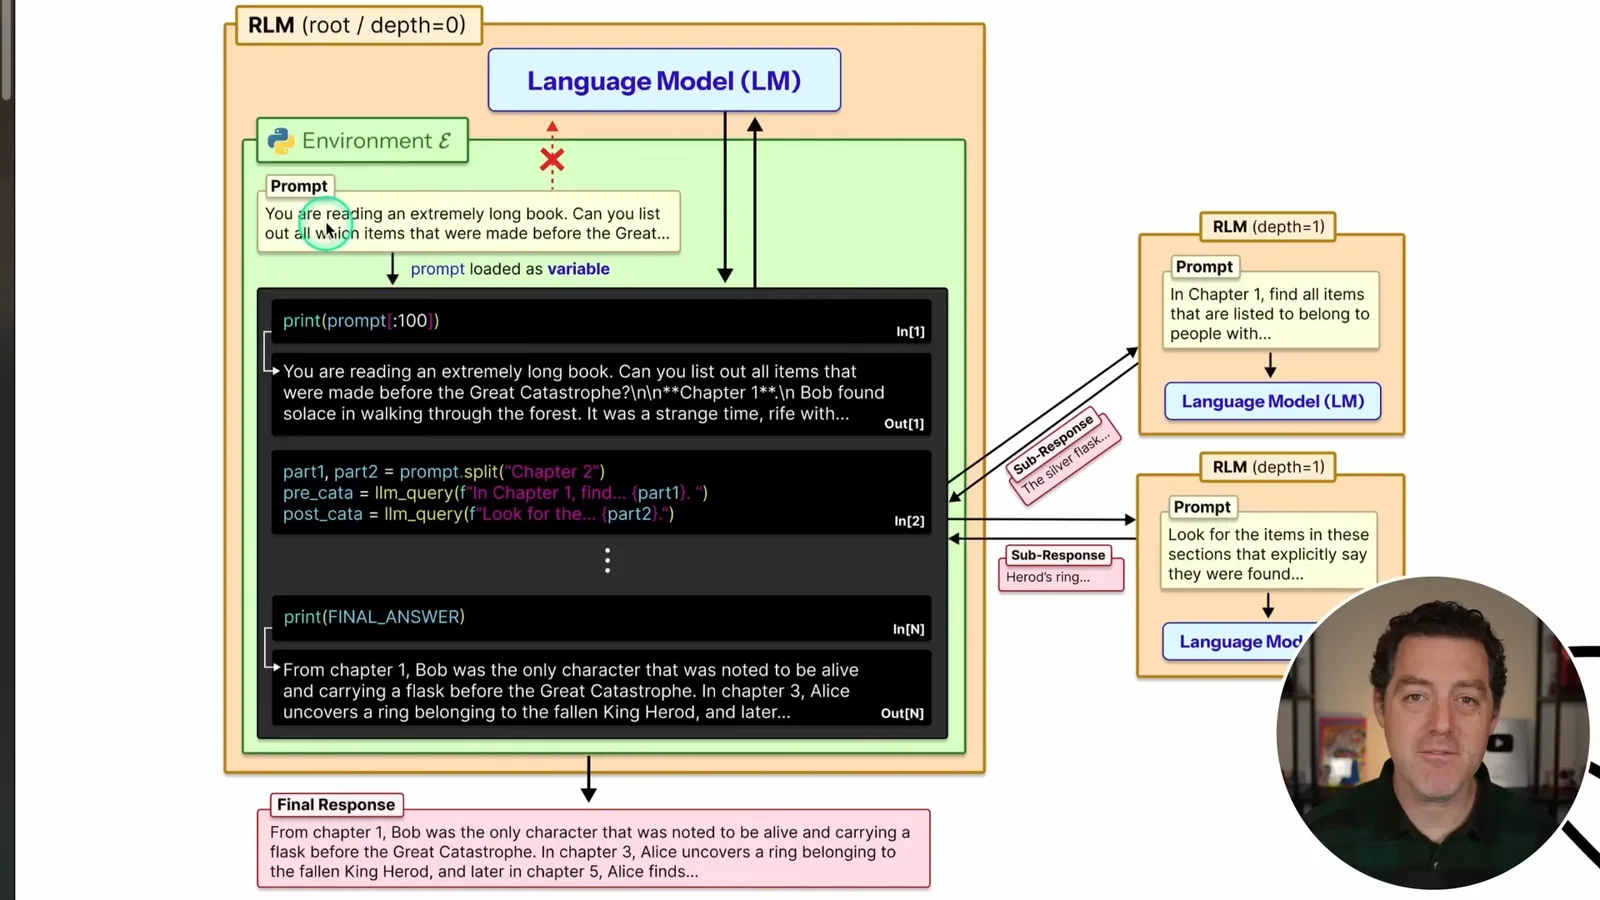
In the paper's example, a Python REPL holds the long input as a variable. A root model can split it into sections, query a model about selected pieces and combine the returned results. These are bounded model calls over parts of the material, not the entire input being attended to in one enlarged window.
Imagine a long book and a question about objects made before a catastrophe. The system can inspect chapters and send relevant sections to sub-calls, then assemble an answer. This avoids requiring a single summary of the whole book, but the method can still miss evidence, make errors or produce incomplete results.
This illustrates the distinction between the model's learned capabilities and the tools built around it. I am enthusiastic about adding memory, code execution and other scaffolding. My suggestion that today's models are sufficient for almost all use cases is an opinion, not a result established by this study.
This video is sponsored by Zapier. Berman describes Zapier Agents, workflow integrations and a Claude integration through MCP, drawing on his own experience using the platform. These are his and the sponsor's product claims, rather than findings from the RLM research.
Benchmarks and experiment design
The researchers compare retrieval, aggregation and code-understanding tasks. They test GPT-5 and Qwen3-Coder with several baselines and an RLM ablation.
The authors use several long-context tests. A simple needle-in-a-haystack test asks a model to retrieve a planted fact from a large body of text. Strong results on one such retrieval test do not prove that a model can reliably handle every needle test or perform complex reasoning across a long input.
The harder evaluations include BrowseComp-Plus for multi-document questions, OOLONG for semantic processing and aggregation, OOLONG-Pairs for pairwise aggregation, and code question answering drawn from LongBench v2. They test different combinations of retrieval, reasoning and synthesis rather than just locating one fact.
A model's advertised maximum input length is not always the same as its effective context for a particular task. A comparison across documents near opposite ends of an input can be much harder than retrieving a single explicit value. The researchers evaluate how task complexity and length affect performance.
In a simple needle test, for example, a password is embedded in unrelated text and the model is asked to retrieve it. Berman says frontier models do very well on this kind of task; that observation should not be read as a guarantee of perfect retrieval in all settings.
BrowseComp-Plus requires a question to be answered using information from multiple documents. OOLONG asks the model to interpret and aggregate pieces of a long input, and OOLONG-Pairs raises the difficulty by requiring combinations of pairs. These distinguish retrieval from the more demanding work of processing and combining evidence.
For code understanding, the researchers use a CodeQA subset of LongBench v2. A question about a repository can require tracing relationships between functions in different files, so looking at one snippet may not be enough. Performance is assessed on the selected benchmark, not every real-world codebase.
The main comparison uses GPT-5 and Qwen3-Coder-480B-A35B and several approaches: the base model, CodeAct with retrieval, a summarization agent, an RLM and an ablation without recursive sub-calls. The setup matters: an RLM without sub-calls can still use the REPL to inspect external input.
Results, costs and limitations
Berman discusses reported scores, the role of recursion, cost variability and model differences. The results are bounded by the tested settings.
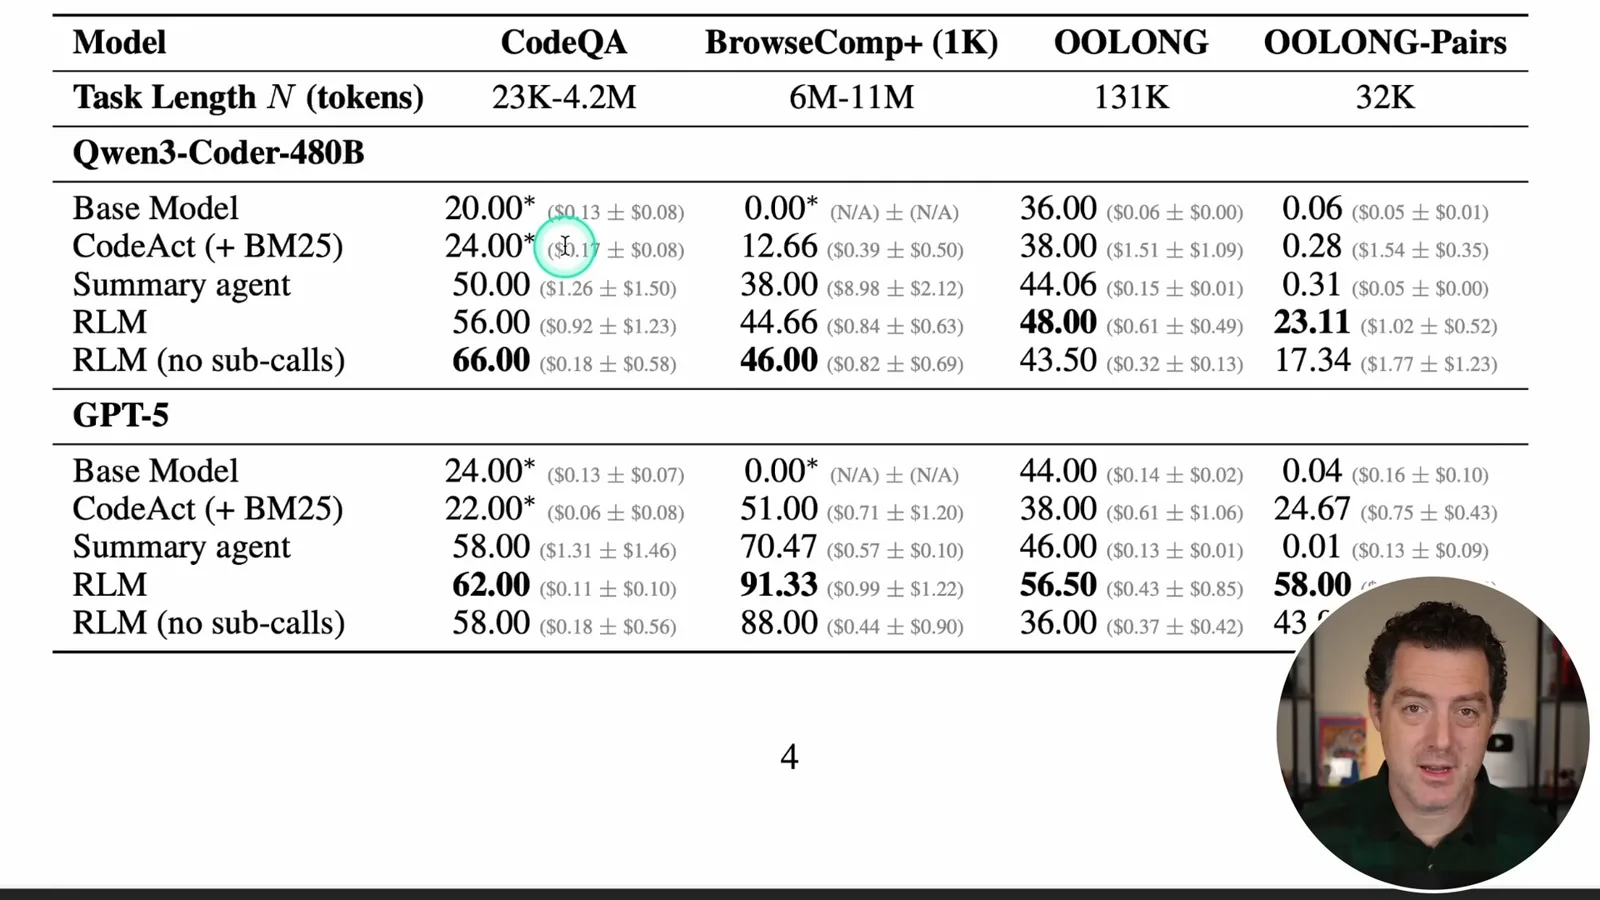
In the paper's table, GPT-5 with an RLM performs better than the listed GPT-5 baselines on all four reported tasks. Results vary with the underlying model: for Qwen, the no-sub-call version outperforms the recursive version on CodeQA and BrowseComp-Plus. Recursion is therefore not uniformly the best option in every comparison.
The paper reports 91.33 for RLM GPT-5 on BrowseComp-Plus versus 70.47 for the summary agent, and an average API cost of $0.99 versus $0.57 for that summary baseline. The RLM's cost is not lower in that particular comparison, despite its higher score. These are research measurements under specific prices and settings.
The authors also compare the $0.99 average with a $1.50–$2.75 estimate for GPT-5-mini hypothetically ingesting 6–11 million tokens. That is a theoretical, linearly extrapolated full-ingestion cost, not an actual run of a model with that context capacity. It should not be mistaken for a universal cost saving.
Their ablation suggests that putting input in the REPL helps handle text beyond the base window, while recursive model calls can help on information-dense tasks such as OOLONG-Pairs. It does not mean all useful context is always found: the approach still depends on the model's choices and the execution environment.
The study also reports that performance changes with both input length and problem complexity. In its experiments, ordinary GPT-5 degraded faster on harder tasks, while the RLM degraded more slowly. The paper notes that the base model could perform better for smaller inputs, so extra scaffolding has a tradeoff.
Cost is another tradeoff. The number and length of sub-calls vary by task, and some long trajectories produce expensive outliers. For example, the reported average GPT-5 RLM cost on OOLONG-Pairs was $0.33 versus $0.16 for the base model; latency and implementation also matter.
The framework is designed to be model-agnostic, but that is a design property rather than proof it works equally well with every model. GPT-5 and Qwen3-Coder made different choices and achieved different results. On BrowseComp-Plus, the GPT-5 RLM scored 91.33, while the Qwen RLM scored 44.66.
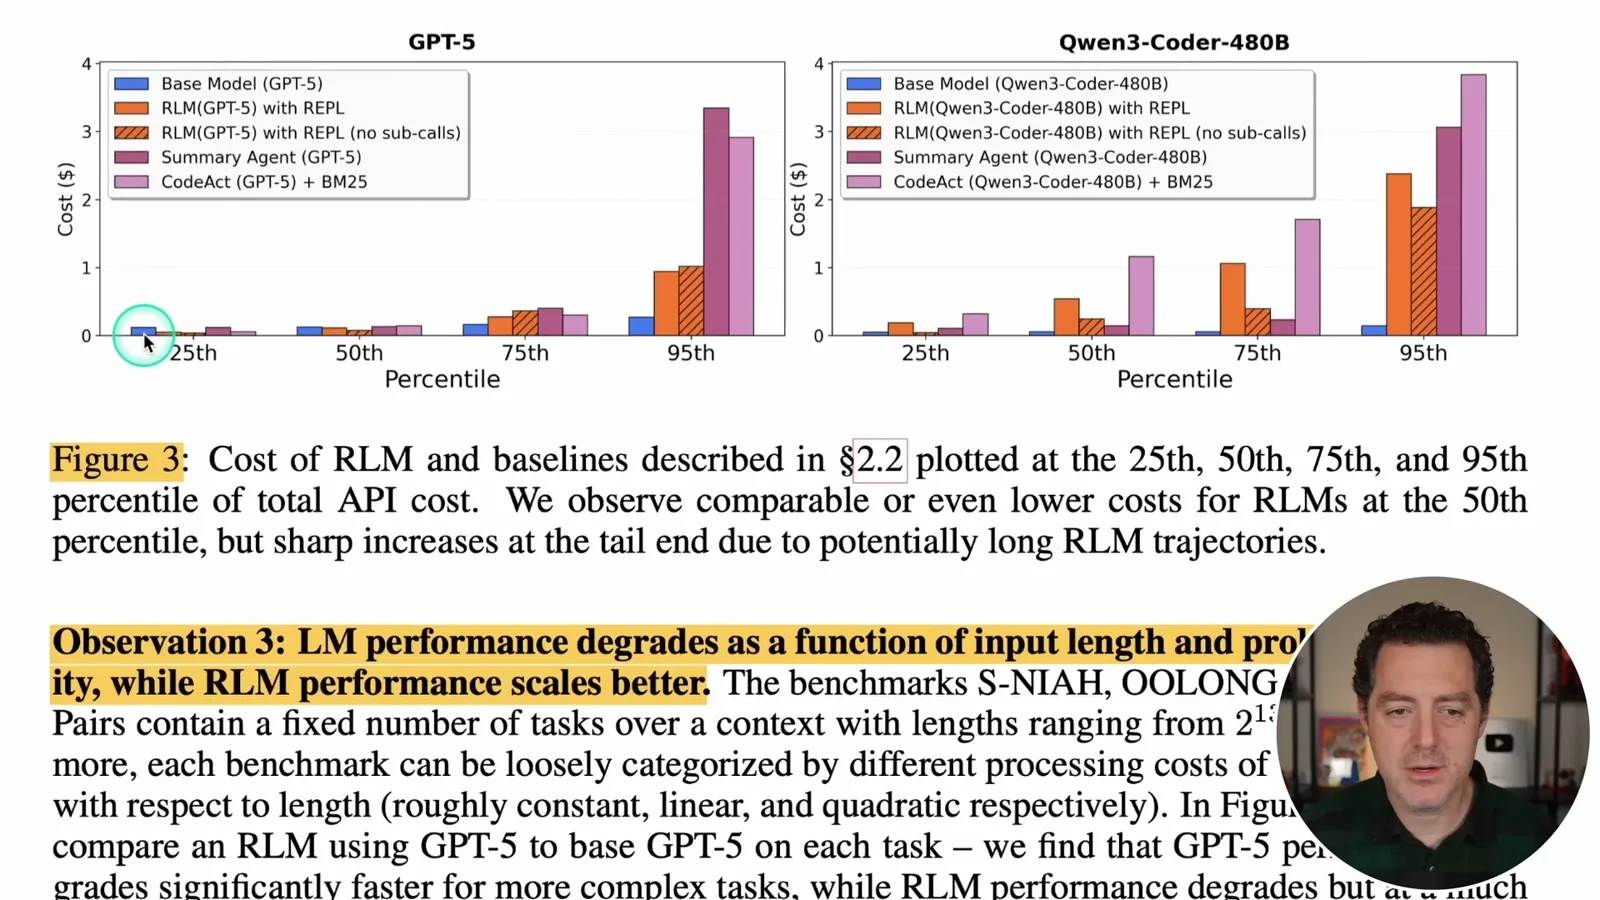
The cost chart compares the 25th, 50th, 75th and 95th percentiles for different approaches. Some RLM runs stay inexpensive, while the tail rises sharply. Looking only at cost would also miss the quality differences between approaches.
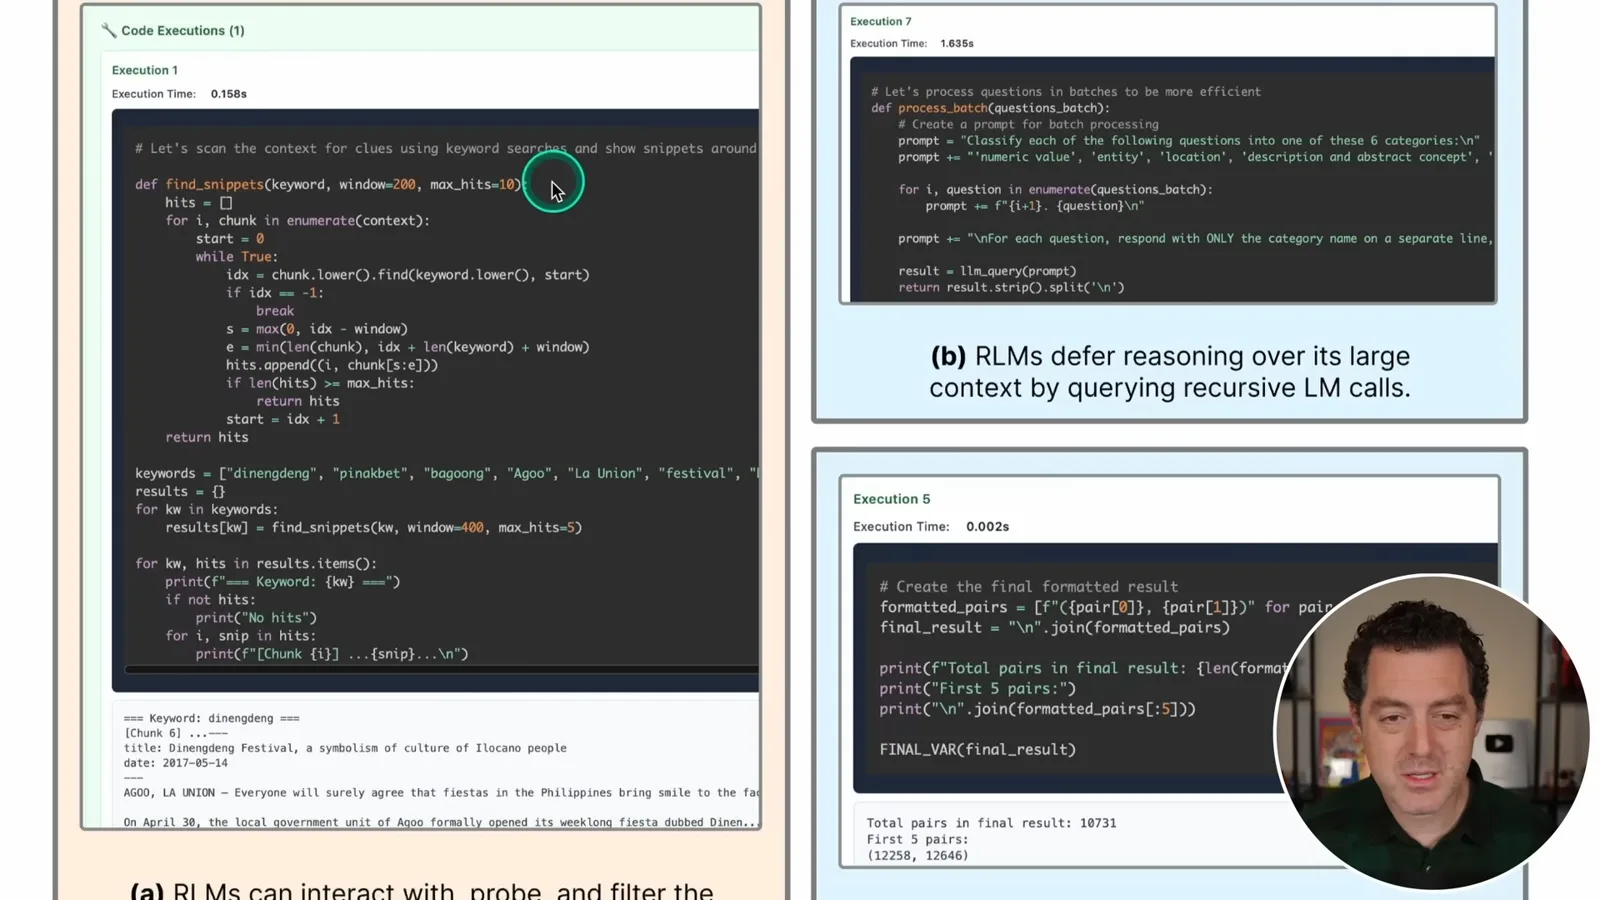
The paper shows the kind of code an RLM can write to search and filter context, then query a model over useful chunks and combine the results. Keyword search and regular expressions are examples, not a guarantee that every relevant passage will be identified.
I find the paper compelling because it shows room for improved tooling around models as the models themselves also improve. The result is a promising research approach, with finite tested workloads, variable costs and remaining reliability questions—not a proof of unlimited context.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.