En 30 segundos
In an AWS-sponsored video published in December 2025, Matthew Berman discusses Amazon Bedrock AgentCore features announced at re:Invent: policy controls, agent evaluations and episodic memory. He argues that governance and measurement should be integrated into agent development. AWS initially listed Policy and Evaluations as previews. Their safeguards, measurements and memory behavior depend on configuration and testing; the episode does not independently establish the platform’s comparative superiority or solve enterprise deployment risk.
- 1A preliminary report, not a universal failure rateProject NANDA studied limited enterprise returns and deployments using interviews, surveys and public initiatives; it did not measure failure across all pilots.
- 2Policies for tool accessDevelopers can generate Cedar rules from natural language and test them before enforcing them through the gateway.
- 3Controls in the request pathAgentCore Gateway checks tool requests against policies before allowing access to protected resources.
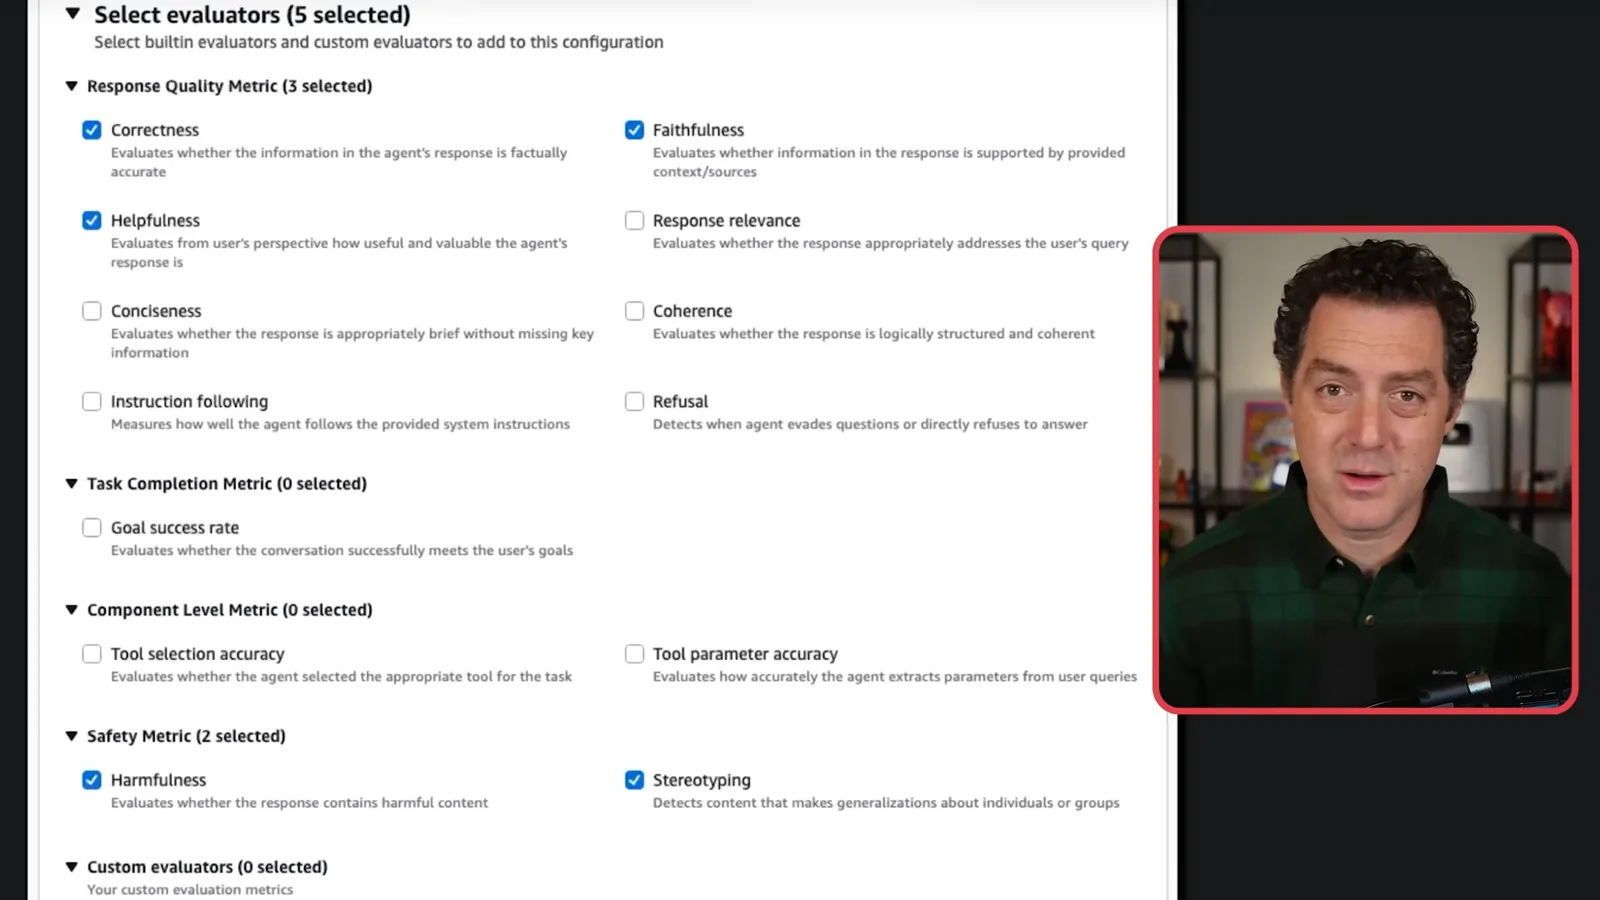
- 4Agent evaluationsBuilt-in and custom evaluators support on-demand or ongoing assessment across selected quality measures.
- 5Experience-based memoryEpisodic memory stores experiences and derives reflections, with sharing controlled by the chosen scope.
Conclusiones
- AgentCore Policy evaluates requests passing through its gateway against configured access rules.
- Natural-language policy generation still requires review and testing of the resulting Cedar rules.
- AgentCore Evaluations offers built-in and custom measures, initially in preview.
- Episodic memory can make previous experience available to later tasks, with scope determined by configuration.
- The preliminary Project NANDA report does not establish that 95% of all enterprise AI pilots fail.
Lee el texto editado por capítulos
Enterprise deployment and AgentCore
Berman introduces the production challenge and discloses AWS sponsorship. The cited preliminary report has a narrower scope than a universal pilot failure rate.
I start with a viral 2025 Project NANDA report often summarized as finding that 95% of enterprise AI pilots fail. That is broader than the preliminary report's evidence: it discusses limited measurable returns and deployment among organizations studied, not a representative count establishing the failure rate of every pilot. Its methods included interviews with 52 organizations, 153 senior-leader survey responses and review of over 300 public initiatives.
At AWS re:Invent in December 2025, AWS announced additions to Amazon Bedrock AgentCore aimed at enterprise agent deployment. I focus on controlling agent actions, evaluating performance and retaining useful experience. AWS sponsored this video; its product claims and my assessment should be read in that context.
AgentCore is AWS's managed platform for building and running agents with different models and frameworks. I am particularly interested in having policy, evaluations and episodic memory integrated into the platform rather than treated as separate afterthoughts. AWS initially announced Policy and Evaluations as previews, so availability and capabilities should be checked for the relevant environment.
Policy controls
A natural-language example generates policy code. The gateway evaluates tool requests against configured rules before execution.
Policy management lets a team describe restrictions on agent actions. My examples include allowing Slack messages only for users with the appropriate scope or group and restricting internal websites to administrators. The interface can translate a natural-language instruction into Cedar policy code; the team should inspect and test the generated rules to confirm that they match the intended access controls.
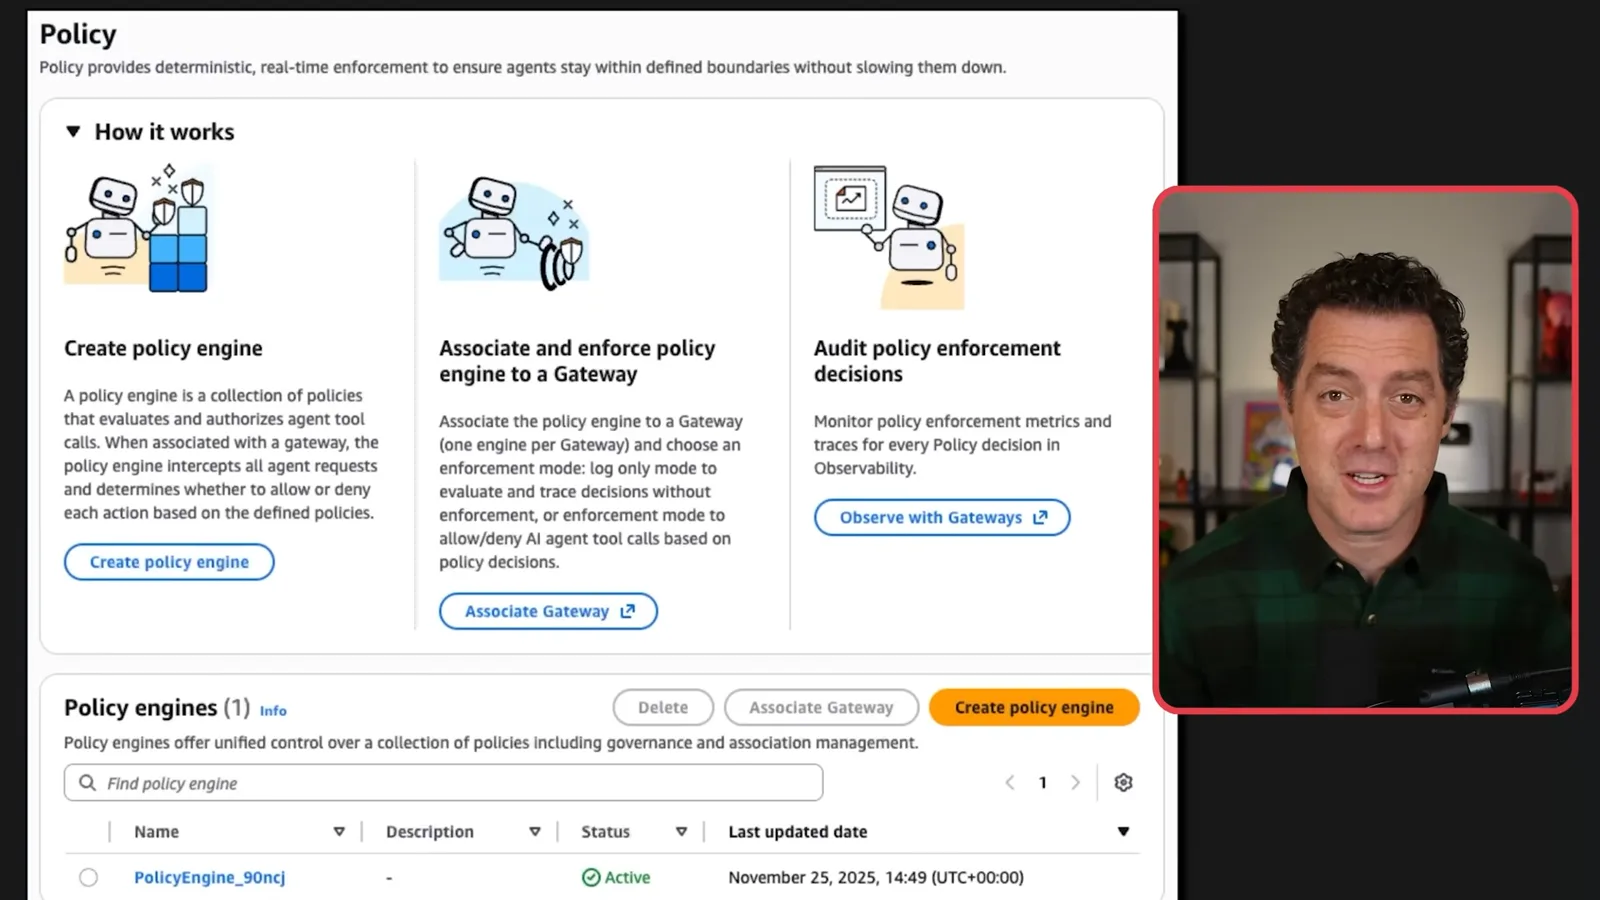
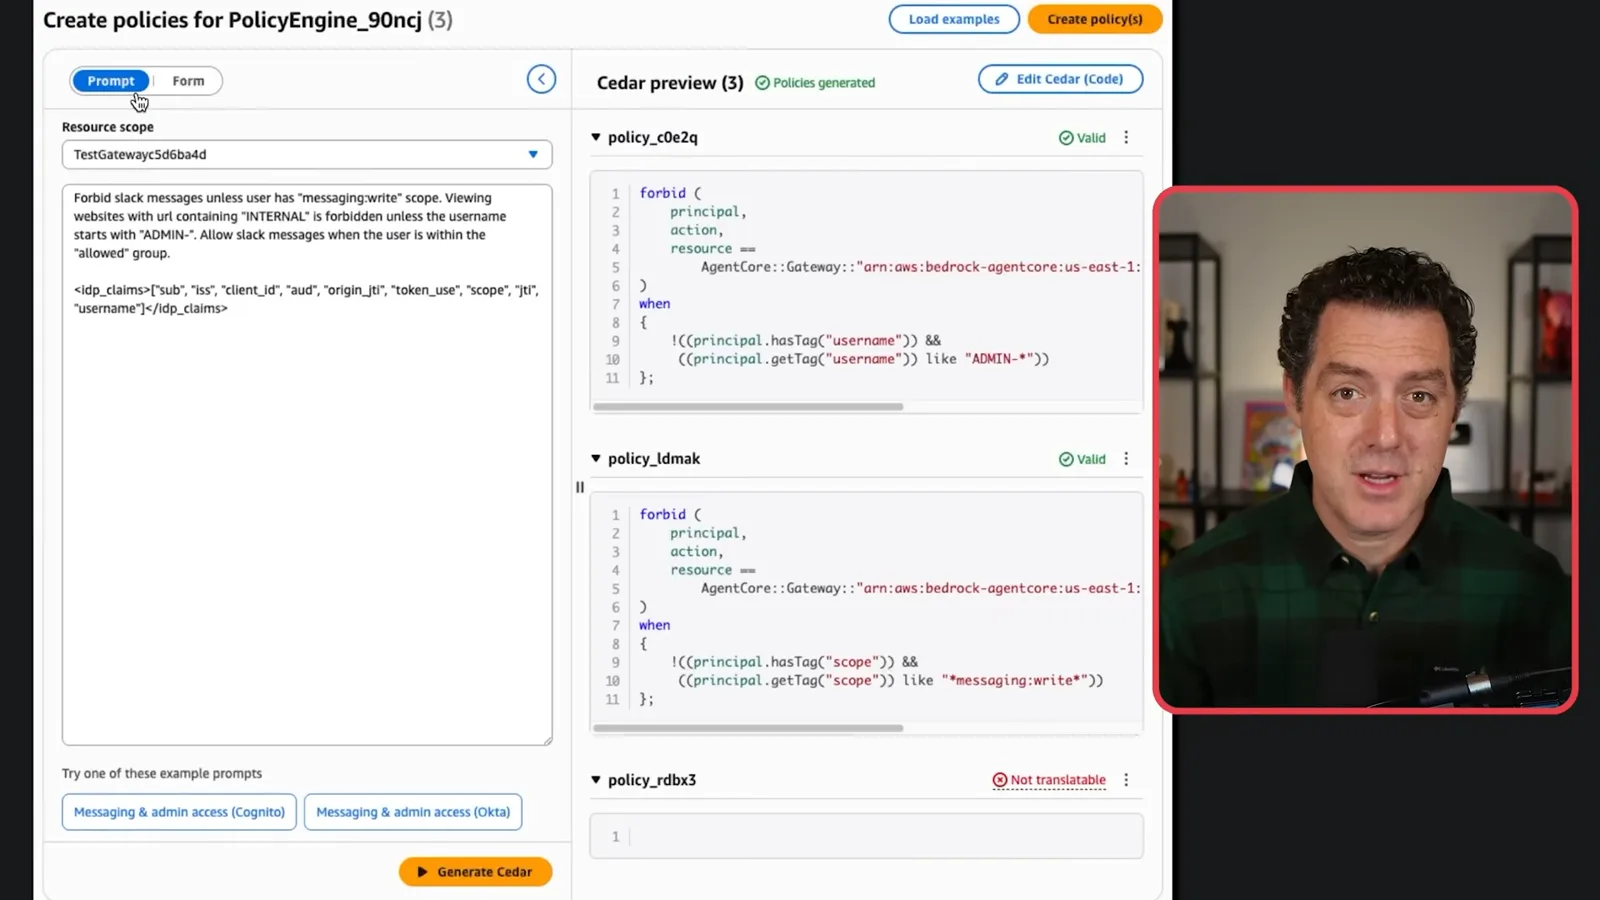
In the architecture shown, an agent or MCP client sends tool requests through AgentCore Gateway. A policy engine evaluates a request before the gateway permits it to reach a protected tool, API or system. AWS describes fine-grained controls for gateway tool calls; this does not automatically govern every possible action taken outside that enforcement path.
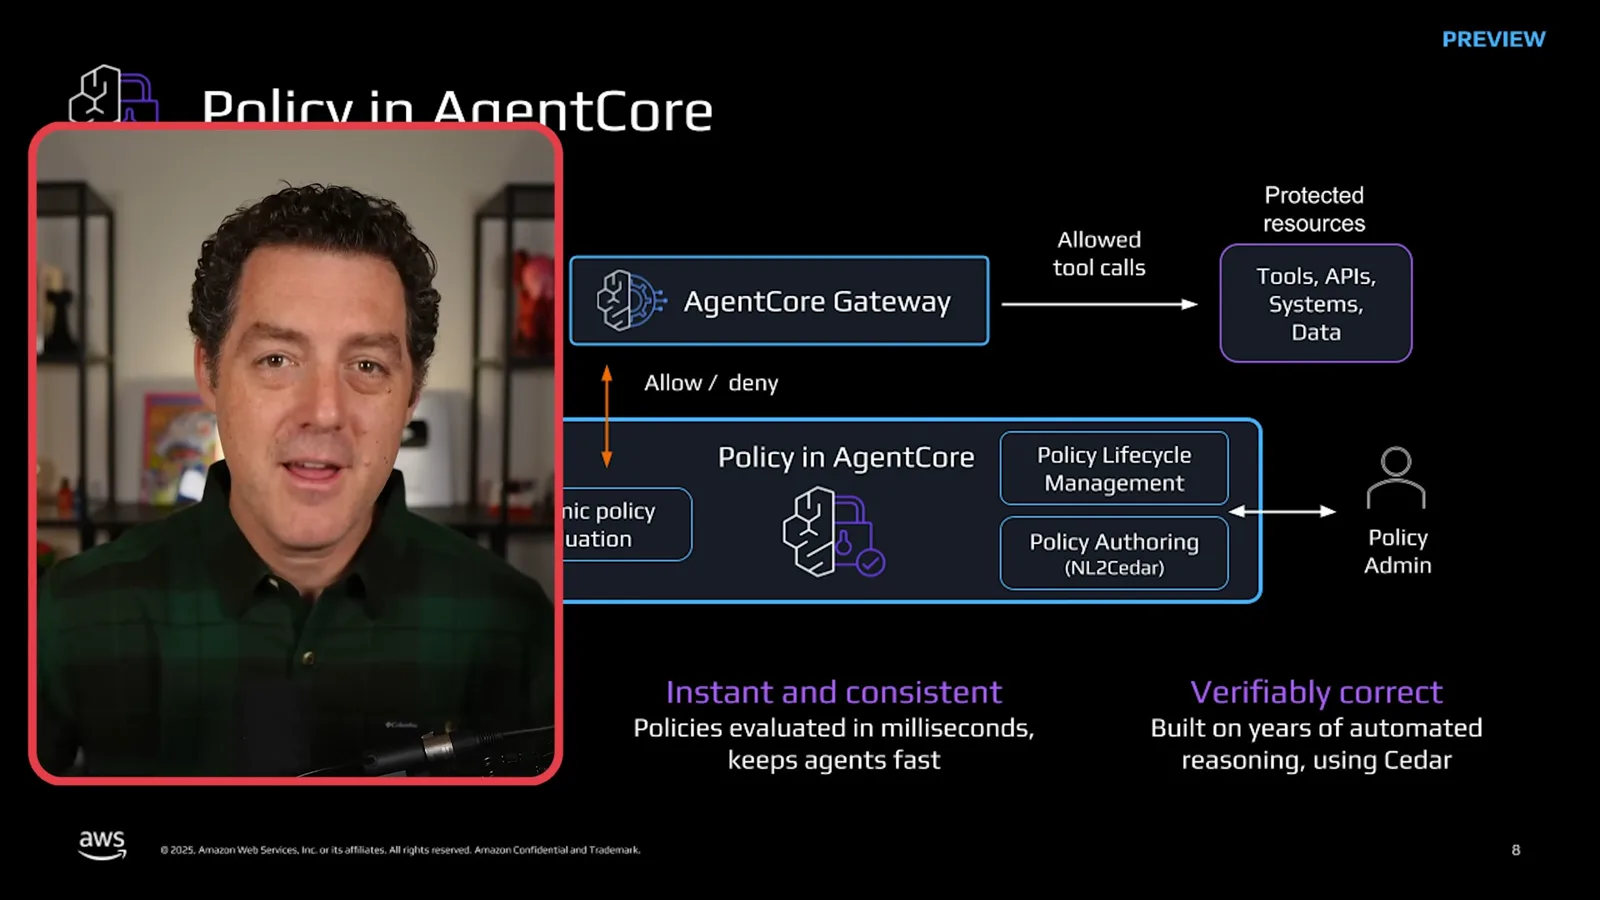
AWS says its policy controls use automated reasoning and evaluate requests in milliseconds, with support for high request volumes. Mathematical analysis can help check specified policy properties, but it is not a universal proof that an AI model's answers are truthful or free of hallucinations. Actual protection still depends on correct policies, integration and testing.
I consider these controls important because research has explored behaviors such as deception and data exfiltration under particular conditions. Those studies do not show that every deployed model behaves that way, but they illustrate why access boundaries and governance deserve attention when agents can call tools.
Evaluations and observability
Built-in and custom evaluators measure selected agent behaviors. Traces help investigate results but need interpretation.
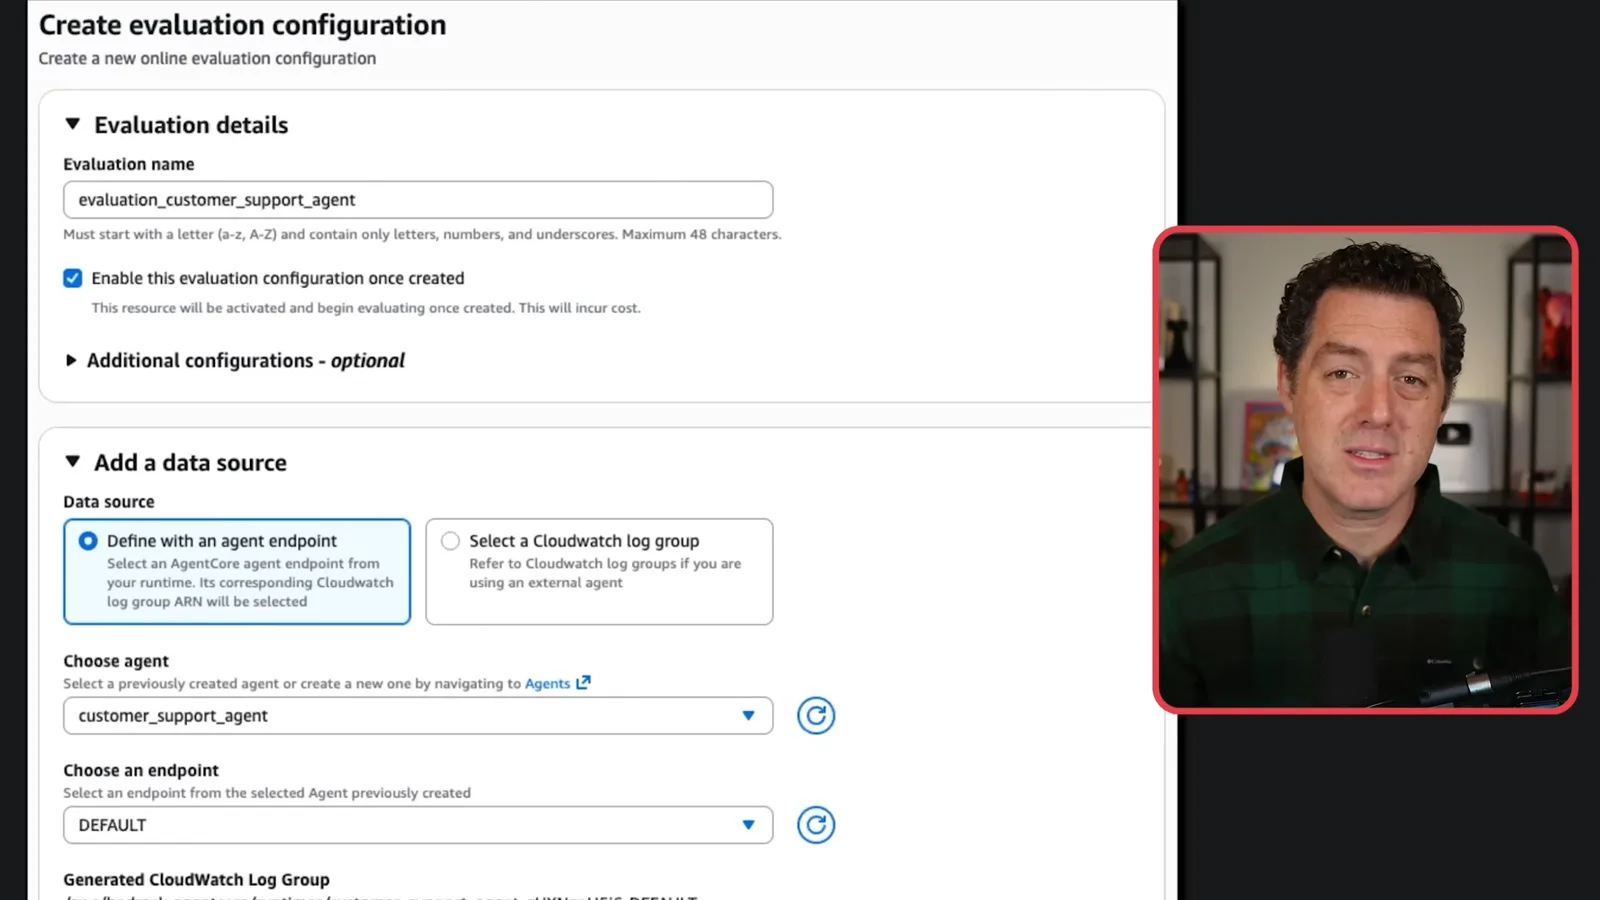
The second announcement is AgentCore Evaluations. I encourage teams to establish a baseline early so they can tell whether changes improve an agent. AWS offers built-in and custom evaluators, with on-demand or ongoing evaluation; its initial announcement described the feature as a preview.
Evaluation criteria can include correctness, helpfulness, instruction following, faithfulness, relevance, coherence and refusal. A team can also define a custom criterion—for example, whether responses consistently use a pirate voice. Observability and traces can help investigate an error, although they do not guarantee a complete explanation of every model decision or perfectly measure quality.
Episodic memory and integration
The memory strategy makes experience and reflections available for later tasks. Berman closes by explaining why he values integrated controls.
The third feature is episodic memory: AWS describes a long-term memory strategy that records experiences and can derive reflections for use in similar later tasks. I am interested in using past successes and failures to inform future interactions and in evaluating whether those memories actually help. Retrieval and memory use do not guarantee that an agent will learn correctly or improve in every case.
I suggest that these memories can extend beyond a single conversation. Their sharing is configurable, however, rather than necessarily spreading across an entire deployment: AWS documents namespaces that can scope memories by user, session or broader application boundaries. Teams need to choose that scope deliberately.
Taken together, policy controls, evaluations and episodic memory address different parts of the production problem: restricting tool calls, measuring behavior and retaining experience. I see their integration as a promising direction for building agents. The announcements themselves do not establish exclusive market firsts or prove that enterprise deployment challenges are solved.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.